
Top 10 Sales KPIs for AI Document Intelligence in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
Quality
Certified
The 10 best sales kpis for ai document intelligence are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. AI Document Intelligence Net New ARR
Net new ARR ranks first because it is the headline growth line every board and investor asks about, and in this category it is unusually hard to verify externally. Hyperscaler document intelligence revenue is bundled inside broader cloud AI reporting and never disclosed standalone, so independent vendor ARR visible through funding disclosures is the only clean comparable. It captures new logos plus expansion in one figure.
It is for founders, revenue leaders, and finance teams reporting to a board that wants one growth number. The trade-off is that net new ARR alone hides whether growth came from new logos or from volume expansion inside existing accounts, which are very different engines. Pair it with net revenue retention directly below, which decomposes the expansion half of this number.
2. AI Document Intelligence Net Revenue Retention
Net revenue retention ranks second because it is the single best summary of whether the installed base is expanding or quietly eroding, and in document intelligence strong performers sit in the 120 to 140 percent band. The reason it runs higher than generic B2B software is the volume component: retrieval pipelines scale document ingestion fast once in production, and usage-based pricing captures that automatically. Below 110 percent something specific is broken.
It is for revenue operations and customer success leaders who need to separate three mechanically distinct expansion engines: raw volume growth, new document type addition, and movement up the stack into validation and human review. The trade-off is that a single blended figure cannot tell you which engine is running. Compare against net new ARR above, which shows the absolute growth the retention rate is compounding.
3. AI Document Intelligence Documents Processed Monthly
Documents processed per month ranks third because it is the volume metric that drives usage-based revenue and the leading indicator of whether a deployment is actually in production. It spans orders of magnitude by customer: a mid-market finance team runs tens of thousands of invoices monthly, while a large shared services center or national insurer runs into the millions or tens of millions. Report it per customer with a growth rate.
It is for product and revenue teams tracking adoption depth inside each account. The trade-off is that an aggregate total across all customers is dominated by your two largest accounts and tells you nothing about the base, so it must be segmented. Compare against cost per document below, which converts this volume into unit economics.
4. AI Document Intelligence Cost Per Document
Cost per document ranks fourth because it is the metric with the widest legitimate range in the category and the one most often quoted as a single misleading number. Plain OCR on standard forms at hyperscaler volume pricing sits at fractions of a cent per page, full schema extraction with validation lands at a few cents to tens of cents, and enterprise workflows including human review of the exception queue run to a dollar or more per document.
It is for pricing teams and finance leaders who must always state which of those three things is being priced. The trade-off is that vendor-side cost governs gross margin while buyer-side blended cost including their review labor wins renewals, and conflating the two loses deals. Compare against documents processed monthly above, which supplies the denominator.
5. AI Document Intelligence OCR Accuracy
OCR accuracy ranks fifth because it is the floor of the pipeline and the entry ticket to every technical bake-off, even though it is not the moat. Above 99 percent character accuracy on clean printed text is table stakes that every serious vendor clears, roughly 95 percent on handwriting is genuinely differentiating, and around 90 percent on degraded scans is where most real-world corpora actually live. That last figure decides pilots.
It is for solutions engineers and evaluation teams who know buyers assemble a few hundred of their own worst documents rather than running vendor benchmark sets. The trade-off is that tuning for clean-text accuracy produces beautiful charts and lost evaluations. Compare against schema extraction F1 below, which measures the actual work product rather than the input reading.
6. AI Document Intelligence Schema Extraction F1
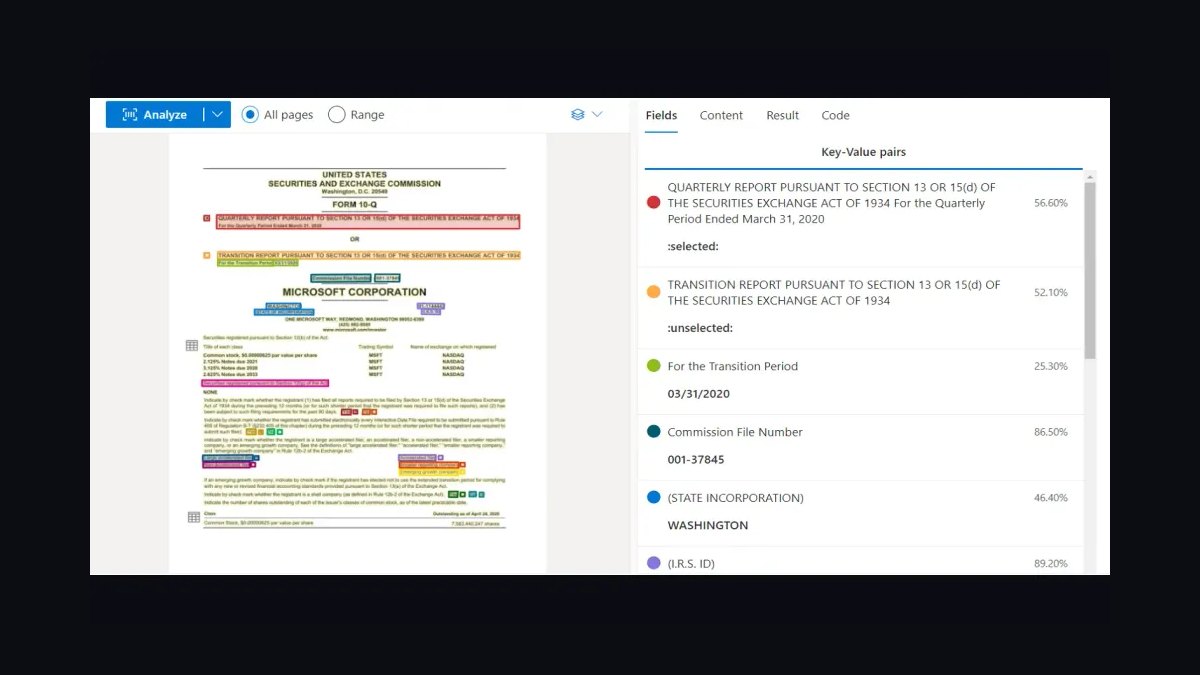
Schema extraction F1 ranks sixth because it is the work product itself, turning laid-out documents into named fields like invoice number, vendor tax ID, and contract effective date. The thresholds are well understood in the market: at or above 0.95 the buyer's straight-through processing rate is high enough that economics work, between 0.90 and 0.95 the deal is winnable but the buyer negotiates hard on price, and below 0.90 the manual review burden consumes the savings.
It is for technical sellers running accuracy proofs on customer sample corpora. The trade-off is that it must be reported per document type, never blended, because a blended 0.94 hiding one type at 0.84 is worse than useless. Compare against OCR accuracy above, which is the upstream stage this metric depends on.
7. AI Document Intelligence Document Type Coverage
Document type coverage ranks seventh because it determines the expansion ceiling in every account: a customer stops growing spend at exactly the point where their next document type is unsupported. Roughly 50 or more pretrained types is a credible breadth claim for a general platform covering invoices, receipts, purchase orders, contracts, passports, tax forms, medical claims, and bills of lading. Specialist vendors deliberately cover far fewer with much higher fidelity.
It is for product and sales leaders setting the type roadmap from actual installed-base blockers rather than competitive feature lists. The trade-off is that broad coverage claimed but shallowly delivered damages trust when a buyer uploads their own version during a demo. Compare against schema extraction F1 above, which measures depth within each covered type.
8. AI Document Intelligence API Plus UI Revenue Mix
API plus UI revenue mix ranks eighth because it reveals whether a vendor actually serves both buyers inside an account or just claims to. Developers building retrieval pipelines want an API, clean documentation, predictable latency, and a client library; operations users running invoice review want a document on the left, extracted fields on the right, and a correction workflow. A split roughly in the 40 to 60 percent range on either side indicates genuine dual service.
It is for product strategists deciding where to invest engineering next. The trade-off is that a 90-10 split in either direction means you have one product and an afterthought, structurally capped at roughly half the addressable spend in each account. Compare against document type coverage above, since breadth without a surface to consume it limits expansion.
9. AI Document Intelligence 12-Month Renewal Rate
Twelve-month renewal rate ranks ninth because it is the lagging confirmation that everything upstream worked, and the benchmarks are clear: 88 percent and up is healthy for this industry, 92 percent and up is strong, and newer entrants and narrow point solutions run materially lower. The leading indicator arrives 90 to 120 days before renewal, when realized cost per document rises and the manual review queue grows on a newly onboarded document type.
It is for customer success and finance leaders forecasting revenue durability. The trade-off is that it is a backward-looking number, so acting on it alone means reacting after the damage. Compare against net revenue retention above, which captures expansion that logo retention ignores entirely.
10. AI Document Intelligence Time To First Production Value
Time to first production value ranks tenth because it behaves as a strong renewal predictor even though it sits outside the core nine. Median days from first API call to a customer running production volume is short for standard document types, often the first week or two, and stretches to several weeks for complex or heavily regulated schemas. When onboarding passes a month and a half, renewal risk rises sharply because the customer has paid without seeing return.
It is for onboarding and solutions engineering teams who can compress it with prebuilt connectors to common retrieval frameworks and data warehouses. The trade-off is that chasing speed on complex regulated schemas sacrifices extraction fidelity that the customer will measure later. Compare against renewal rate above, which this metric predicts months in advance.
How we ranked these
We ranked nine metrics by commercial impact on renewals and expansion: net new ARR, net revenue retention, monthly documents processed, cost per document, OCR accuracy, schema extraction F1, document type coverage, API-plus-UI revenue mix, and 12-month renewal rate. Weighting favored extraction quality and per-document economics, since these directly determine the buyer's labor savings and therefore whether they renew.
We deliberately ignored feature-count comparisons, generic SaaS engagement metrics like logins and seat counts, and vendor-published benchmark accuracy on clean documents. Those numbers do not survive a buyer's own corpus test. We also excluded blended F1 figures that hide a weak document type, and any market-sizing totals that bundle hyperscaler revenue nobody discloses separately.
What to look for
What matters is field-level F1 on the buyer's own worst documents, not published accuracy on clean text. Ask for per-type F1 on a sample corpus you supply, plus the straight-through processing rate that results. Then compute blended cost per document including your remaining review labor, because that is the number your CFO compares against the status quo.
The mistake most buyers make is evaluating on the vendor's benchmark set and a demo UI. The second mistake is accepting a blended accuracy figure that conceals one document type extracting at 0.84. The third is ignoring confidence calibration, which lets wrong values sail past the threshold into your ERP. Test calibration explicitly before signing.
Related questions
What is schema extraction F1 and why does it decide renewals?
F1 combines precision and recall into one score for named field extraction. Above 0.95, straight-through processing is high enough that buyer economics work. Between 0.90 and 0.95 the deal is winnable but price gets negotiated hard. Below 0.90, manual review labor consumes the savings and the value proposition inverts, so renewal becomes unlikely regardless of price.
Why is cost per document so hard to benchmark across vendors?
The range is enormous because vendors price different scopes. Plain OCR on standard forms runs fractions of a cent per page. Full schema extraction with validation runs a few cents to tens of cents. Workflows including human review of exceptions run to a dollar or more. Always state which scope you are pricing and compute the buyer-side blended figure including review labor.
What net revenue retention should a document intelligence vendor target?
Strong performers land in the 120 to 140 percent band, higher than generic B2B software because retrieval pipelines scale ingestion fast once in production and usage pricing captures that automatically. Below 110 percent usually signals a narrow initial use case or an underperforming document type the customer stopped feeding. Segment by motion before drawing conclusions.
How does straight-through processing rate connect quality to labor cost?
Every document either clears the confidence threshold into structured output or drops into a review queue. The percentage that clears is straight-through processing rate, and it converts extraction quality directly into the buyer's labor cost. A vendor reporting 0.94 F1 but a 60 percent clear rate is delivering far less savings than the accuracy number suggests.
Why does document type coverage matter more than accuracy in expansion?
Breadth determines whether you expand past the initial use case or stay a point product forever. Roughly 50 or more pretrained types is a credible general-platform claim. Specialist vendors cover fewer types with higher fidelity in one vertical, and for them coverage count is the wrong metric entirely. Measure depth on hardest fields instead.
What is confidence miscalibration and why is it dangerous?
A model reporting high confidence on wrong extractions defeats the confidence-gate architecture. Bad values sail past the threshold into the customer's ERP or claims system, and humans find the errors downstream. Measure calibration by bucketing predictions by reported confidence and checking observed accuracy per bucket. If your 0.95 bucket is 85 percent correct, your straight-through rate is fiction.
How should API and UI revenue mix inform product strategy?
A split roughly 40 to 60 percent on either side indicates you genuinely serve both engineering and operations buyers. A 90-10 split in either direction means you have one product and an afterthought. Selling only an API caps you at the engineering budget; selling only a UI makes you invisible to retrieval-pipeline builders driving new volume.
What is time to first production value and why track it?
It is median days from first API call to a customer running production volume, and it behaves as a strong renewal predictor. Standard document types reach production in a week or two; complex or regulated schemas take several weeks. Onboarding stretching past six weeks sharply raises renewal risk because the customer has paid without seeing return.
FAQ
What are the top sales KPIs for AI document intelligence in 2027?
Track nine: net new ARR, net revenue retention, monthly documents processed, cost per document, OCR accuracy, schema extraction F1, document type coverage, API-plus-UI revenue mix, and 12-month renewal rate. Extraction quality and per-document economics decide renewals, because a vendor whose F1 drops below 0.90 hands manual-review cost straight back to the buyer.
Why is OCR accuracy not the moat in this category?
Character-level accuracy above 99 percent on clean printed text is table stakes; every serious vendor clears it. Differentiation appears on handwriting, degraded scans, skewed phone captures, multi-column layouts, and non-Latin scripts. Buyers know this, which is why evaluations run on their own worst documents rather than vendor benchmark sets. Published accuracy gets you into the bake-off but does not decide it.
What F1 threshold makes a document intelligence deal commercially viable?
At or above 0.95, the buyer's straight-through processing rate is high enough that economics work. Between 0.90 and 0.95 the deal is winnable but the buyer negotiates hard on price. Below 0.90, manual review burden consumes the savings and the value proposition inverts. Report F1 per document type, never blended, because one weak type defines the customer experience.
How does layout analysis cause silent quality loss?
Errors at the layout stage do not look like errors. A table with misread column boundaries produces perfectly legible text in the wrong cells, and downstream extraction confidently reports high confidence on wrong values. This is the most common cause of a pilot that passes character-accuracy checks and then fails business validation during the customer's own testing.
What drives net revenue retention above 120 percent?
Three mechanically distinct sources: raw volume growth on existing document types, addition of new document types, and movement up the stack into validation and human-in-the-loop review. Each is a different sales motion with different lead times. A single blended retention figure cannot tell you which engine is running, so segment before staffing against it.
Why does usage-based pricing create commercial risk?
Revenue becomes a function of the customer's document volume, which you do not control. A customer whose business contracts reduces your revenue with no failure on your part, and one that improves upstream capture reduces it too. Some floor commitment in the contract keeps a volume-driven model from behaving like a bet on the customer's growth.
What is document drift and how do you guard against it?
Customers change templates, vendors redesign invoices, regulators revise forms, and new scanners introduce different compression artifacts. Quality degrades gradually until a review queue backs up. Guard with per-type accuracy monitoring on a rolling window and alert on relative degradation, not absolute thresholds. A type dropping from 0.96 to 0.92 still clears the floor but signals something changed.
How should customer acquisition cost be managed in this category?
Developer-led acquisition through documentation and open source is cheap per account but lands low initial contract values. Outbound enterprise sales with solutions engineering is expensive and only pencils against large multi-year contracts. Keep blended acquisition cost under roughly a third of first-year contract value and target payback inside twelve months on gross margin.
What edge cases break document intelligence pipelines?
Multi-page records where the page split is ambiguous; mixed languages within one page; fields legitimately empty versus extraction failures, which are semantically different but often collapsed; scanned duplicates inflating volume and billing; and regulated personal or health data that cannot legally transit certain processing paths. That last one kills deals late during security review rather than early.
What should a vendor instrument first when rolling out these KPIs?
Get all nine metrics captured end to end and reconciled against billing in month one. Reconciliation is the step teams skip and the one that surfaces the most problems: telemetry and invoiced volume should agree, and discrepancies usually mean retries, duplicates, or failed documents counted inconsistently. Baseline your worst customer cohorts first, since they define churn exposure.
Sources
- https://aws.amazon.com/textract/
- https://cloud.google.com/document-ai
- https://learn.microsoft.com/en-us/azure/ai-services/document-intelligence/
- https://www.gartner.com/en/newsroom/press-releases
- https://www.mckinsey.com/capabilities/quantumblack/our-insights
- https://arxiv.org/list/cs.CV/recent
- https://www.nist.gov/itl/iad/image-group
- https://www.accenture.com/us-en/insights/technology
Related on PULSE
- [More sales kpis for ai document intelligence rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 pulse-industry-kpisTop 10 Sales KPIs for Zero Trust Network Access (ZTNA) Vendors in 2027
 pulse-industry-kpisTop 10 KPIs for Dental Practices in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Fine-Tuning Platform in 2027
 pulse-industry-kpisTop 10 KPIs for Physical Therapy Clinics in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Text-to-Speech (TTS) Voice AI in 2027
 pulse-industry-kpisTop 10 KPIs for Auto Repair Shops in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Recruiting in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Vector Database in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Medical Device OEM in 2027
 pulse-industry-kpisTop 10 KPIs for Moving Companies in 2027