


How do you prove Palantir Foundry improved win rate without creating a new shadow data mart for enterprise outbound teams on Dynamics 365 when consumption pricing with minimum commits in 2027?
Quality
Certified
Prove the lift inside Dynamics 365 itself: add one boolean field ("Foundry-Influenced") to the Opportunity entity, have enterprise outbound reps flag deals where Palantir Foundry insights shaped the play, then compare win rate between flagged and unflagged cohorts over 4-6 weeks. No shadow data mart, no new warehouse — just a native report proving improved win rate against consumption spend.
What it is and why it matters
The question hides two separate problems that most RevOps teams collapse into one. The first is attribution: did Foundry actually move win rate, or did the deals that used it simply belong to your best reps working your best accounts? The second is infrastructure discipline: proving that attribution without spinning up a parallel system that IT never approved, security never reviewed, and nobody maintains six months later. Shadow data marts happen for a boring reason — someone needed a join that Dynamics 365 couldn't produce natively, so they exported to a spreadsheet or a personal database, and that export became permanent infrastructure. Once that happens with a Palantir Foundry integration, you've created exactly the risk consumption pricing is supposed to prevent: paying for compute against data nobody governs.
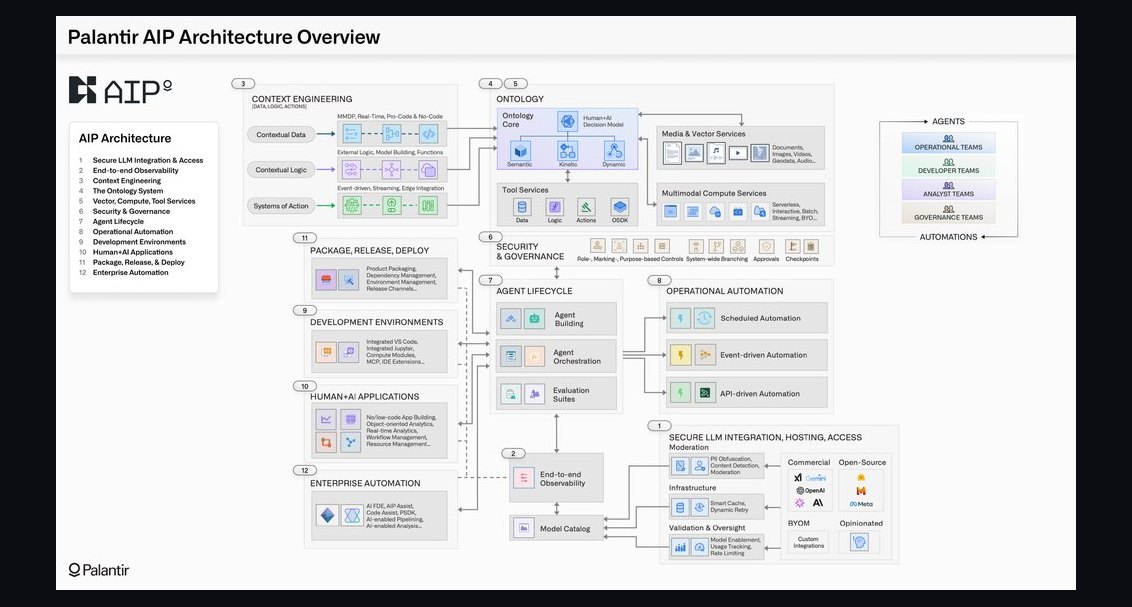
This matters more with Foundry specifically than with a typical point solution because Foundry's value proposition is data integration itself — it wants to be the layer that unifies CRM, product usage, and finance data. That's powerful, but it means the natural failure mode is "Foundry becomes its own shadow mart" even when the intent was to feed insights back into Dynamics 365. The fix is architectural discipline: Foundry can read and enrich, but the system of record for the metric you're using to justify the spend stays in Dynamics. Enterprise outbound teams are the right proving ground because deal cycles are long enough to see stage movement inside a single quarter, and the deal count per rep is low enough that a boolean flag doesn't get abused as a vanity metric.
There's also a governance angle that's easy to underweight. Finance is watching consumption pricing with minimum commits because that model punishes idle spend — you're paying for the platform whether or not reps use it well. A clean, native-in-Dynamics measurement approach gives finance something they can audit without learning Foundry's query layer. That single fact — auditability by a non-technical stakeholder — is often what separates a renewed contract from a canceled one at the 12-month mark.
The step-by-step process (mermaid)
Run this as a five-week sequence, not a single "let's measure it" ask.
- Week 0 — Instrument the object. Work with your Dynamics 365 admin to add a single custom field on Opportunity:
Foundry_Influenced__c(or your naming convention), boolean, required-to-set before stage advancement past qualification. Do not make it optional — optional flags get skipped under quarter pressure and you'll have no clean signal. - Week 0 — Define the trigger. Write a one-sentence rule for when a rep checks the box: "Check this when a Foundry insight (account signal, ICP score, or expansion trigger) changed which account, contact, or message you pursued." Publish it in the same wiki page as your other Dynamics 365 field definitions.
- Weeks 1-4 — Run the pilot on enterprise outbound only. Restrict the flag and the reporting view to one pod. This keeps the sample clean and keeps the blast radius small if the flag gets misused.
- Weeks 1-4 — Track a control cohort. Pull the same pod's opportunities from the prior comparable period (previous quarter, same stage mix) as your baseline. You need both a within-period control (flagged vs. unflagged, same weeks) and a historical control (this pod, before Foundry existed) to rule out seasonality.
- Week 5 — Run the comparison report natively in Dynamics. Win rate for flagged vs. unflagged, stage-to-stage conversion, and average sales cycle length. No export required — a standard Dynamics view or Power BI report against the same data source does this.
- Week 5 — Translate to a dollar figure. Multiply the win rate delta by pipeline volume and average deal size to get incremental revenue, then divide by actual Foundry consumption cost for the period (not the minimum commit) to get a true cost-per-incremental-win number.
The mermaid above is the whole method in one picture: everything upstream of the comparison report lives inside Dynamics 365, and Foundry never becomes the system holding the metric you report to leadership.
Costs, timelines, and typical ranges
Budget the pilot at roughly five to six weeks end-to-end, and expect the admin work — the custom field, the report, the pilot-segment security role adjustments — to take a single Dynamics admin two to four hours total. That's the cheap part. The expensive part is behavioral: getting reps to consistently flag the field takes active manager enforcement, not a Slack announcement. Plan on two short (10-15 minute) rep office-hours sessions during the pilot to walk through edge cases — what counts as "Foundry influenced" when a rep half-remembers an insight from three weeks ago, for instance.
On the consumption pricing side, minimum commits typically get negotiated in the low five figures to low six figures monthly depending on data volume and number of connected sources, with true-up periods running quarterly. If your contract has a minimum commit that exceeds what a single-pod pilot will consume, ask your Palantir account team for a reduced-tier trial SKU or a carve-out that lets you run the four-to-six-week test at a fraction of full committed spend — many enterprise software vendors, Palantir included, have some flexibility here for a bounded proof-of-value window, especially if you're transparent that a positive result leads to expansion.
Win rate deltas worth reporting to a CRO are rarely dramatic in a single pilot — a 3-8 percentage point improvement in stage-1-to-stage-2 conversion, or a 5-15% reduction in average sales cycle days, is a realistic range for a well-run pilot on enterprise outbound. Anything larger should make you suspicious of selection bias: check whether the reps who bothered to flag deals are simply your strongest performers, and control for that by segmenting the comparison by rep tenure or historical win rate if your sample is large enough.
The total cost of ownership conversation also needs to include what you're NOT paying for: a shadow mart avoided is not just an infrastructure cost saved, it's a security review, a data governance sign-off, and an ongoing maintenance burden you never had to create. When you present the ROI to finance, put a rough dollar value on that avoided cost — even a conservative one — because it's real and it's part of why the native-Dynamics approach beats the "just build a lakehouse and join everything" instinct that consumption-priced platforms tend to provoke.
Where teams get it wrong
The single most common failure is optional instrumentation. Teams add the Foundry-influenced flag but don't require it before stage advancement, so fill rate on the field comes in under 30% and the resulting sample is too small and too self-selected to mean anything. Require the field at a specific stage gate, the same way you'd require any other qualification evidence.
The second failure is scope creep during the pilot. Someone on the team decides that since Foundry is already connected, why not also pull in product usage data, or support ticket volume, to build a "complete picture." That impulse is exactly how the shadow mart gets born — a well-intentioned analyst builds a side table to join Foundry output with data Dynamics doesn't natively hold, and six months later that side table is a dependency nobody documented. Hold the line: the pilot measures one thing, using fields that already exist or can be added natively to the CRM object.
The third failure is comparing apples to oranges on deal size. Enterprise outbound deals vary enormously in size and complexity; a pilot that shows "win rate improved" without normalizing for average deal value or segment can mask a scenario where Foundry helped close smaller, easier deals while larger strategic deals saw no change. Always segment the comparison by deal size band, not just an aggregate win rate number.
The fourth failure is treating a flat or negative pilot result as a referendum on Palantir Foundry as a platform, rather than as a signal about how the insights were operationalized. If the pilot shows no lift, the far more common root cause is that reps weren't actually changing behavior based on Foundry signals — the insights existed but nothing in the workflow forced a rep to act on them differently. That's a process problem, not a data problem, and the fix is tightening the trigger definition and re-running rather than abandoning the tool.
The fifth failure, specific to consumption pricing, is running the pilot against full production data volume when a sampled or scoped connector would have proven the same point for a fraction of the spend. Ask your implementation team to scope the Foundry connector to exactly the fields and record volume the pilot needs — this is the practical way an enterprise team keeps consumption costs proportional to a proof-of-value exercise instead of accidentally consuming against the full committed volume in month one.
Decision framework: when to choose what (mermaid)
Not every team should run this exact playbook identically — the right variant depends on how mature your Dynamics 365 instance already is and how much trust exists between RevOps and the Palantir account team.
Use this to decide your entry point: teams with a cooperative Dynamics admin start at the top-left path; teams fighting change-control processes can still get a directional read using an existing field, though the data will be noisier and the conclusion should be held more loosely before it's used to justify expanded Palantir spend.
Related questions
Can I use Power BI instead of a native Dynamics report to run the comparison?
Yes — Power BI reading directly from Dynamics 365 via its native connector is still "no shadow mart," since it queries the system of record rather than replicating it. Avoid exporting to a separate database as an intermediate step.
What if enterprise outbound doesn't have enough deal volume for a clean signal?
Extend the pilot window to 8-10 weeks instead of 4-6, or widen the pilot to two comparable pods simultaneously. Small enterprise segments need longer observation periods to reach a reliable sample.
Does this approach work for inbound or SMB segments too?
Yes, the mechanism is segment-agnostic, but higher-velocity segments (SMB, inbound) can run shorter 2-3 week pilots since deal cycles are faster and sample size accumulates quicker.
How do I keep Foundry from becoming a shadow mart after the pilot succeeds?
Keep the rule permanent: Foundry enriches and scores, Dynamics 365 remains the system of record for any metric reported externally. Any new Foundry output that needs to inform decisions gets written back to a Dynamics field, not queried from a separate store.
Should legal or security review the Foundry connector before the pilot?
Yes, even a scoped, read-only connector touching CRM data should get a lightweight security sign-off before go-live — this is cheap insurance against the exact governance risk consumption pricing and shadow infrastructure both raise.
FAQ
Do I need executive sponsorship before running this pilot? Not strictly, but a two-line email to your CRO explaining scope and duration prevents surprise questions mid-pilot. Executive sponsorship becomes essential only when you move to scale the flag beyond the pilot pod.
What happens if reps game the flag to make their numbers look better? Add a manager-review step where flagged deals get spot-checked for a one-sentence justification in the deal notes. Reps who can't articulate the specific insight lose credibility on future flags, which self-corrects most gaming quickly.
Is a boolean field enough, or should I capture which specific Foundry insight was used? A boolean is enough to prove aggregate lift, but adding a picklist for insight type (account signal, expansion trigger, ICP fit) lets you see which Foundry capability is actually driving improved outcomes, which strengthens your renewal conversation.
How does this interact with existing Dynamics 365 forecast categories? It doesn't need to — keep the Foundry flag separate from forecast category logic to avoid conflating "the deal is more likely to close" with "Foundry influenced this deal." Mixing the two muddies both signals.
Can this method also apply to renewal or expansion motions, not just new-logo enterprise outbound? Yes, the same flag-and-compare structure works for expansion opportunities; just make sure your control cohort also excludes seasonal renewal timing effects, since renewal win rates often swing on contract-anniversary clustering rather than sales motion quality.
What's the minimum sample size before I trust the win rate delta? As a rule of thumb, don't present a lift number to leadership with fewer than 25-30 opportunities in each cohort (flagged and unflagged) — below that, normal deal-to-deal variance can produce a misleading delta in either direction.
Sources
- https://www.palantir.com/platforms/foundry/
- https://learn.microsoft.com/en-us/dynamics365/sales/
- https://hbr.org/topic/subject/sales
- https://www.gartner.com/en/sales
- https://www.forrester.com/blogs/category/sales-technology/
- https://sloanreview.mit.edu/topic/data-analytics/
- https://learn.microsoft.com/en-us/power-bi/connect-data/desktop-connect-dynamics-365
- https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights
Related on PULSE
- How do you prove Palantir pipeline digital twins improved win rate without creating a new shadow data mart for inbound SDR teams on Dynamics 365 when consumption pricing with minimum commits?
- How do you use Palantir Ontology to automate ramp quotas on new hires in Dynamics 365 during usage-based pricing when consumption pricing with minimum commits?
- How do you use Palantir-driven forecast simulations to dedupe ramp quotas on new hires in Dynamics 365 during BDR-to-AE split when consumption pricing with minimum commits?
- How do you design a RevOps control tower in Palantir AIP that catches UTM loss across subdomains before weekly commit calls for services-led sales with consumption pricing with minimum commits?
- How do you design a RevOps control tower in Palantir Signals for GTM alerts that catches UTM loss across subdomains before weekly commit calls for multi-year ramp contracts with consumption pricing with minimum commits?
- How do you prove you fixed Gong calls not tied to opportunities with CRM fields after migrating to Salesforce for multi-year ramp contracts when consumption pricing with minimum commits?
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for multi-year ramp contracts teams on Dynamics 365 when marketing ops on Marketo in 2027?
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for BDR-to-AE split teams on HubSpot when AEs refuse new required fields in 2027?
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for inbound SDR teams on Salesforce when SDRs on Outreach in 2027?
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for usage-based pricing teams on Pipedrive when data warehouse in Snowflake in 2027?
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for services-led sales teams on Zoho CRM when post-merger CRM merge in 2027?
 revopsHow do you prove Palantir AIP improved win rate without creating a new shadow data mart for AE-led pods teams on Dynamics 365 when founder still owns largest accounts in 2027?
 revopsHow do you use Palantir Ontology to automate ramp quotas on new hires in Dynamics 365 during usage-based pricing when consumption pricing with minimum commits in 2027?
 revopsHow do you use Palantir AIP to measure stage inflation without buyer evidence in Dynamics 365 during channel co-sell when marketing ops on Marketo in 2027?
 revopsHow do you use Palantir-driven forecast simulations to dedupe ramp quotas on new hires in Dynamics 365 during BDR-to-AE split when consumption pricing with minimum commits in 2027?
 revopsHow do you use Palantir pipeline digital twins to document ramp quotas on new hires in Dynamics 365 during PLG-to-sales handoff when BI in Looker in 2027?