


Top 10 Best Tech Stack Tools for Bioinformatics Labs in 2027
Quality
Certified
The 10 best tech stack tools for bioinformatics labs are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Nextflow
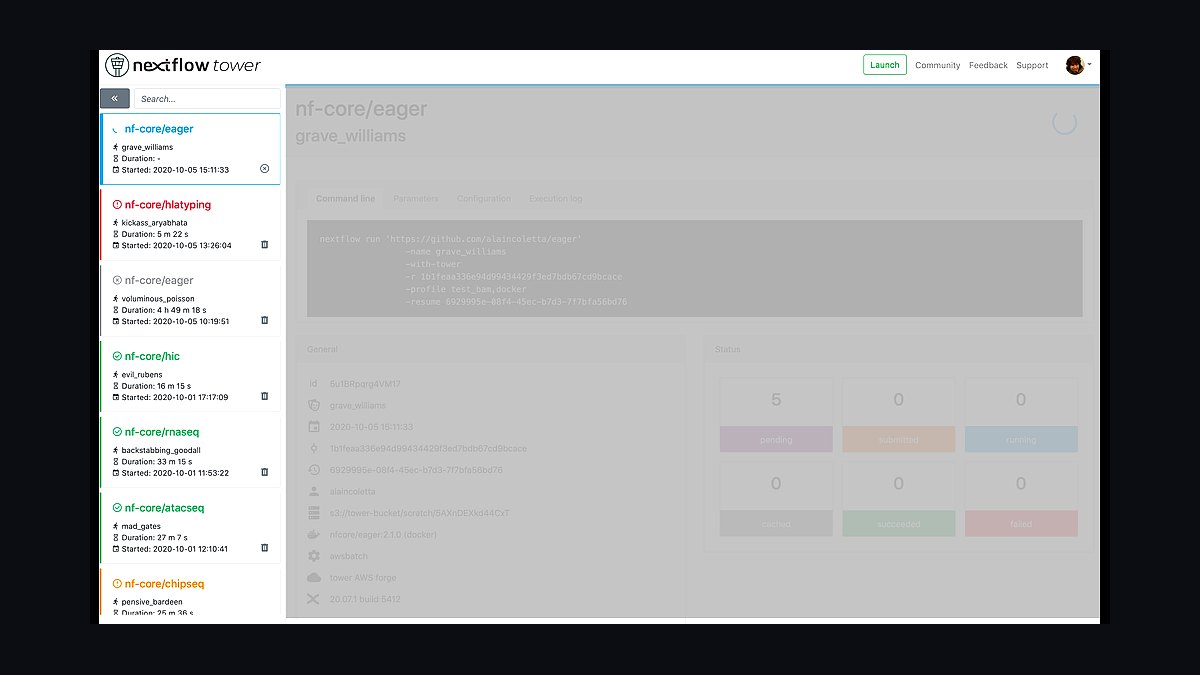
Nextflow ranks first because its hashed work directory makes -resume genuinely reliable: every process execution gets its own subdirectory holding the exact command, stdout, stderr, and exit code, so a failed step 6 of 9 restarts only from step 6. It supports Conda, Docker, and Singularity directives natively, and executors for AWS Batch, Slurm, and Kubernetes via one config switch. On a 200-sample cohort this saves hours of recompute.
It suits labs running multi-step pipelines across more than a handful of samples. It trades away simplicity: the DSL2 channel model has a real learning curve, and small one-off scripts are faster in bash. Compared with Conda directly below, Nextflow handles dataflow and retries while Conda only handles dependency isolation, so the two are complementary rather than competing.
2Conda
Conda ranks second because it solves genomics dependency hell: bioconda packages several thousand tools with resolved dependencies, and pinning bwa=0.7.17, samtools=1.19, gatk4=4.5.0.0, and fastp=0.23.4 in an environment.yml makes installs reproducible. Nextflow consumes it directly through a conda process directive, creating and caching the environment automatically. Without pinned versions, the same pipeline resolves differently six months later.
It is for any lab installing command-line genomics tools, from a single laptop to a shared cluster. It trades away full-filesystem reproducibility: Conda pins the packages you named, not the entire image, so production work should ship as pinned container digests instead. Compared with Nextflow above, Conda isolates dependencies but provides no orchestration, retries, or dataflow.
3AWS Batch
AWS Batch ranks third because genome workloads are embarrassingly heterogeneous: trimming needs 2 vCPUs, alignment scales to 16-32 cores, and de novo assembly can demand 256 GB to 1 TB of RAM for hours. Batch matches each job to an instance type, runs the container, and terminates it, so you never own hardware sized for the worst step. Spot pricing cuts compute 60-90%, landing a 30x human genome near $1-3.
It is for labs with bursty workloads or no existing cluster. It trades away control: IAM roles, subnet routing, and VPC endpoints for S3 and ECR are the most common cause of failed runs, and default maxvCpus ceilings silently serialize large cohorts. Compared with Nextflow above, Batch supplies compute but no dataflow model, so it is a layer beneath it rather than a substitute.
4nf-core/sarek
nf-core/sarek ranks fourth because it ships a tested germline and somatic variant calling pipeline with standardized modules, AWS Batch profiles, and a -profile test configuration that runs in minutes on downsampled data. Starting from a maintained pipeline inherits community bug fixes, container pins, and MultiQC wiring rather than rebuilding orchestration by hand. For most labs it reaches a green run faster than any custom main.nf.
It is for teams wanting production variant calling without writing the pipeline themselves. It trades away flexibility: genuinely unusual workflows fight the standardized structure, and customizing modules means learning nf-core conventions. Compared with AWS Batch above, sarek is the pipeline layer that runs on top of it; compared with GATK below, sarek orchestrates the caller rather than replacing it.
5GATK HaplotypeCaller
GATK HaplotypeCaller ranks fifth because it performs local de novo reassembly around active regions instead of naive pileup counting, which is why it handles indels well and remains the best-documented germline short-read caller. Running in GVCF mode with -ERC GVCF lets samples be joint-genotyped later without recalling. It does not scale past roughly 4 threads, so interval sharding across 20-50 jobs cuts a 12-hour serial call to about an hour.
It is for germline short-read calling on human and model-organism data. It trades away speed and simplicity: base quality score recalibration adds 30-60 minutes per sample, and hard filters are needed below 30 WGS samples for VQSR training. Compared with nf-core/sarek above, HaplotypeCaller is the engine sarek invokes; compared with DeepVariant below, it is cheaper but often slightly behind on indel accuracy.
6DeepVariant
DeepVariant ranks sixth because its deep-learning pileup model often edges out GATK HaplotypeCaller on indel accuracy, particularly for PacBio HiFi and Oxford Nanopore long reads where the local-reassembly assumptions of older callers weaken. It converts aligned reads into image-like tensors and classifies genotypes directly, which generalizes well across sequencing platforms and coverage depths without retraining.
It is for labs with long-read or mixed-platform data, or where indel accuracy justifies extra compute. It trades away cost and ecosystem maturity: GPU or large-CPU instances raise per-sample spend meaningfully, and downstream tooling still assumes GATK-style outputs. Compared with GATK HaplotypeCaller above, DeepVariant is the accuracy-first choice; compared with MultiQC below, it produces calls while MultiQC only reports on them.
7MultiQC
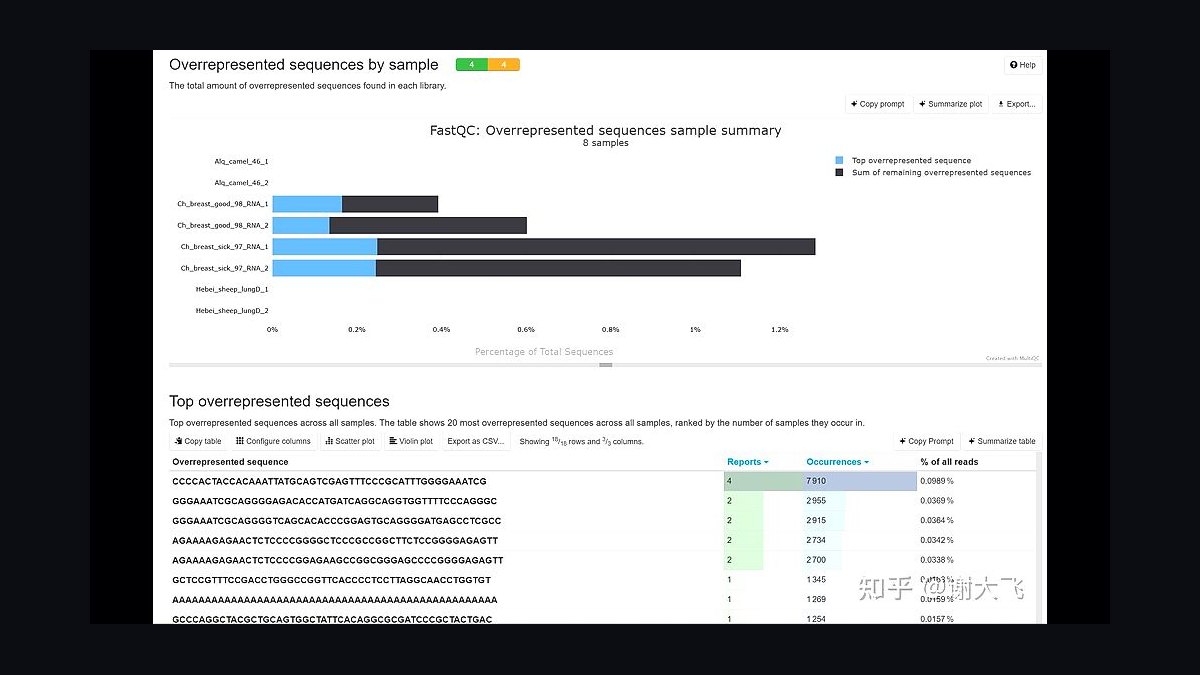
MultiQC ranks seventh because it aggregates every tool's log in a run into a single HTML report, which is the artifact humans actually read. A pipeline exiting zero means the tools ran, not that the data is usable, so gating on MultiQC metrics such as alignment rate, mean coverage, duplicate rate, and Ti/Tv ratio catches scientifically worthless samples. Expected Ti/Tv is roughly 2.0-2.1 for WGS and 3.0-3.3 for exomes.
It is for anyone who needs a QC gate before trusting a VCF. It trades away depth: MultiQC summarizes existing logs rather than computing new metrics, so a tool that never ran leaves no trace in the report. Compared with DeepVariant above, MultiQC reports on results rather than producing them; compared with SnpEff below, it describes run quality while SnpEff describes variant consequence.
8SnpEff
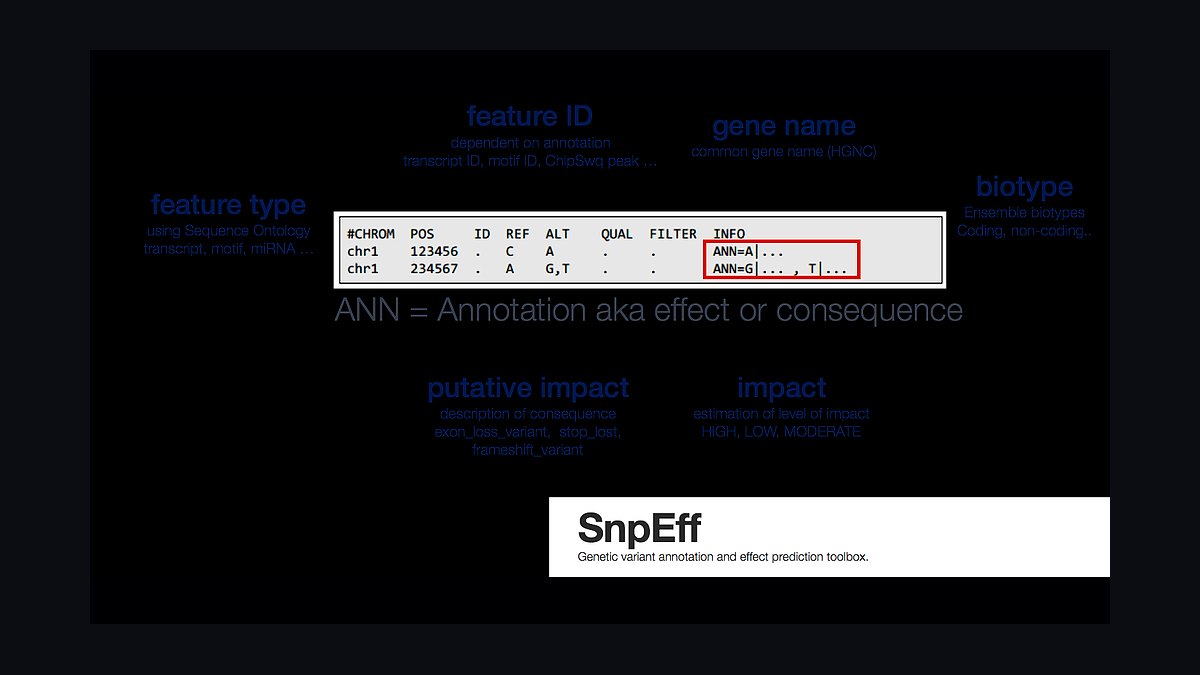
SnpEff ranks eighth because it adds functional consequence predictions to a VCF, labeling variants as missense, nonsense, splice-site, or synonymous and annotating them against a chosen transcript set. It runs offline against bundled databases, so no network call is needed mid-pipeline, and it emits a summary HTML alongside the annotated VCF. That annotation is what turns millions of raw calls into something a biologist can triage.
It is for labs needing functional interpretation of variants without a full clinical annotation stack. It trades away currency: bundled databases lag recent releases, and transcript selection can change predicted consequences, so the annotation build must be recorded. Compared with MultiQC above, SnpEff interprets variants rather than reporting run quality; compared with VEP below, it is faster to set up but less configurable.
9VEP
VEP ranks ninth because it is the most configurable variant effect predictor, supporting custom plugins, multiple transcript sets, regulatory annotation, and frequency lookups against gnomAD and 1000 Genomes in one pass. For clinical and translational work where consequence calls must be defensible, its plugin ecosystem and explicit cache versioning make results easier to audit than a bundled-database annotator.
It is for teams needing regulatory or custom annotation beyond basic consequence labels. It trades away setup speed: cache downloads are large, plugin dependencies must be installed, and misconfigured transcript sets silently change output. Compared with SnpEff above, VEP is the more powerful but heavier option; compared with SPAdes below, it annotates existing variants rather than assembling sequence.
10SPAdes
SPAdes ranks tenth because it assembles bacterial genomes in 30-90 minutes on 16 cores and 64 GB RAM, landing under 100 contigs with N50 above 100 kb on a typical 5 Mb isolate at 100x coverage. Spot cost per isolate is well under a dollar, which is why microbial labs run hundreds of isolates without a budget conversation. It handles both short and hybrid read sets.
It is for bacterial and small-genome de novo assembly where no good reference exists. It trades away scalability: large eukaryotic genomes need 500 GB to 1 TB of RAM for 12-48 hours, and SPAdes is not the tool for those. Compared with VEP above, SPAdes reconstructs sequence rather than annotating variation; compared with Flye and hifiasm, it is the short-read-first assembler while those target long reads.
How we ranked these
We ranked tools by four weighted criteria: reproducibility guarantees (30%), measured cost-per-sample on real workloads (25%), scalability ceiling for cohort-scale runs (25%), and onboarding friction for a lab with mixed computational skill (20%). Evidence came from published benchmarks, vendor documentation, and reported runtimes for 30x human WGS and bacterial assembly workloads.
We deliberately ignored marketing feature lists, UI polish, and enterprise contract minimums, because none of those change whether a pipeline reproduces six months later. We also excluded vendor-published speed claims without methodology, and pricing pages that quote list rates rather than realized Spot or committed-use costs. Both distort the comparison buyers actually face.
What to look for
What matters most is whether the tool pins every dependency at the filesystem level, not just named packages. A pipeline that resolves differently in March than in September produces different variant calls, and that is a scientific liability, not an inconvenience. Check whether container digests and reference checksums are recorded as part of the run output.
The mistake most buyers make is sizing for the median task instead of the worst one. De novo assembly can demand a terabyte of RAM for two days while trimming needs two cores for twenty minutes. Buyers who provision for the average either overpay constantly or watch their largest job fail. Match compute to each step, and verify the executor's concurrency ceiling before committing.
Related questions
Can I run this pipeline without AWS?
Yes. Nextflow's executor is a configuration switch. The same pipeline runs on Slurm, SGE, LSF, Kubernetes, Google Cloud Batch, Azure Batch, or a single machine's local executor by changing nextflow.config. Process definitions and Conda environments stay identical.
Should I use Conda or Docker containers?
Conda is faster to iterate on and easier to modify. Containers are more reproducible because they pin the entire filesystem, not just named packages. Common practice: develop with Conda, ship production with pinned container digests. Nextflow supports both via process directives.
How much coverage do I actually need?
For human germline SNP calling, 30x is the accepted standard. Exomes need 100x because capture efficiency is uneven. Somatic calling in tumors typically wants 80-100x or higher due to subclonal variants and normal contamination. Bacterial assembly is comfortable at 50-100x.
What does -resume actually cache on?
Nextflow hashes the process script text, the input file contents, and the process directives. Any change to any of these invalidates that task and everything downstream of it. The cache lives in the work/ directory and the .nextflow/ cache database.
Is de novo assembly ever needed for human samples?
Rarely for clinical resequencing, but yes for population-specific reference building, for resolving complex structural variation and highly polymorphic regions like HLA, and for pangenome work. Long-read assembly of human genomes is increasingly practical but still costs substantially more than reference-based calling.
How do I stop Spot interruptions from killing long runs?
Set errorStrategy to retry only on exit codes 143, 137, 104, 134, and 139, which indicate reclamation rather than genuine failure. Set maxRetries to 3 and use SPOT_CAPACITY_OPTIMIZED rather than price-optimized. A reclaimed task restarts; a failed run wastes hours.
When does an HPC cluster beat cloud Spot?
When you already own the hardware and it sits idle. Sunk capital is cheaper than Spot if utilization is high. Cloud wins when workload is bursty, when you occasionally need 100-plus concurrent jobs, or when you have no cluster and no staff to run one.
What belongs in the reproducibility artifact bundle?
Pin the pipeline to a git tag, pin container digests, archive the environment.yml and solved lock file, store the Nextflow trace and HTML report alongside the VCF, and record the reference genome checksum. A run you cannot reproduce is a run you cannot defend to a client or regulator.
FAQ
How long does a full 30x human genome take end to end?
Roughly 4-8 hours of wall clock on AWS Batch with interval-parallelized variant calling, against 20-40 hours if run serially on one machine. The variable is how aggressively you shard HaplotypeCaller and how much Batch capacity is available. Trimming and alignment are typically the longest single steps.
What is the most common cause of a failed Nextflow run on AWS Batch?
A compute environment maxvCpus ceiling set too low. Nextflow submits hundreds of jobs, Batch queues them behind a small cap, and the run stalls for hours. Check maxvCpus, check your EC2 service quotas for the instance families requested, and confirm your Spot capacity strategy before scaling.
Why do my variant calls differ between runs of the same pipeline?
Almost always unpinned dependencies. Writing bioconda::gatk4 without a version resolves differently depending on build date. Pin every package to an exact version, commit the environment.yml, and export a fully-solved lock file. Containers pin the whole filesystem and eliminate this class of drift entirely.
How much does a human genome actually cost to process?
On-Demand instances land around $4-10 per sample; Spot at a 60-80% discount brings it to roughly $1-3. Storage adds separately: 90 GB FASTQ plus a 60 GB CRAM plus intermediates. Teams often spend more on forgotten S3 intermediates than on compute itself.
Should I write my own pipeline or start from nf-core?
Start from nf-core. It is a curated collection of community Nextflow pipelines with standardized structure, testing, and documentation. nf-core/sarek covers germline and somatic calling; nf-core/mag covers metagenome assembly. Customizing a maintained pipeline is nearly always faster, and you inherit community bug fixes.
What QC metrics should gate a run before downstream analysis?
Alignment rate above 95% for human WGS, duplicate rate under 15%, mean coverage at target, and Ti/Tv ratio near 2.0-2.1 for WGS or 3.0-3.3 for exomes. A low Ti/Tv signals false-positive-heavy calls. A zero exit code means tools ran, not that the data is usable.
When should I choose DeepVariant over GATK HaplotypeCaller?
DeepVariant often edges out GATK on indel accuracy, especially for PacBio HiFi and Oxford Nanopore data, but at meaningfully higher compute cost. GATK remains the default for germline short reads and has the best documentation. For somatic calling, use Mutect2 or Strelka2 instead of either.
How do I right-size resources per process?
Run one real sample with -with-trace and -with-report, then inspect per-task CPU and memory utilization. A process requesting 64 GB and peaking at 9 GB is money on fire. Give BWA-MEM 8-16 vCPUs, MarkDuplicates 8-16 GB heap, and HaplotypeCaller 4 vCPUs per interval shard.
What breaks reproducibility when cleaning the work directory?
-resume only works if work/ still exists and input files still hash the same. Teams delete work/ to save storage, then need to resume after a downstream failure and must rerun everything. Keep work/ until the run is validated, then delete it in one deliberate step.
Does the reference genome choice really matter that much?
Yes. Aligning to hg19 and annotating with a GRCh38 database silently produces garbage coordinates. GRCh38 also ships in analysis-set and full-assembly variants, with and without ALT contigs, and BWA behaves differently unless postalt is run. Fix the bundle once, store it immutably, record its checksum.
Sources
- https://www.nextflow.io/docs/latest/index.html
- https://nf-co.re/pipelines
- https://gatk.broadinstitute.org/hc/en-us
- https://bioconda.github.io/
- https://docs.aws.amazon.com/batch/latest/userguide/what-is-batch.html
- https://www.htslib.org/doc/samtools.html
- https://multiqc.info/
- https://docs.seqera.io/platform/
- https://www.genome.gov/about-genomics/fact-sheets/Genome-Reference-Sequences
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Automated Testing Frameworks for QA Engineers in E-commerce in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Smart Manufacturing Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Serverless E-Commerce Developers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Multi-Location Healthcare Clinics in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for AI-Native Revenue Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for IoT Sensor Network Engineers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Medical Device Software Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Clinical Trial Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Fitness App Developers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Solopreneur SaaS Founders in 2027