


Top 10 Best Tech Stack Tools for Product Analytics Teams in 2027
Quality
Certified
The 10 best tech stack tools for product analytics teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Amplitude
Amplitude ranks first because it remains the dominant behavioral analytics platform in the 2027 stack, with AI-powered schema inference that auto-detects user actions instead of requiring manual event tagging. It maps every event to a unified customer data model that syncs bidirectionally with Salesforce and HubSpot. Its integration with OneTrust and Securiti auto-anonymizes PII before data reaches the experimentation engine.
Amplitude suits B2B SaaS teams running over 50 experiments per month who need real-time behavioral segmentation by persona, account tier, and qualification stage. It trades away open-source flexibility and carries enterprise pricing that smaller teams struggle to justify. Compared directly to Heap below, Amplitude offers deeper AI-native analytics but a steeper implementation curve and higher cost.
2Heap
Heap ranks second because its free tier makes it the default entry point for startups building a minimum viable product analytics stack in 2027. Automatic event capture means teams instrument nothing manually, and its privacy layer integrates with OneTrust to anonymize PII before experimentation. It pairs natively with GrowthBook and HubSpot for a functional zero-cost starting stack.
Heap is for smaller teams with limited resources who need behavioral tracking without data engineering headcount. It trades away the deep AI schema inference and buying-committee segmentation that Amplitude provides at enterprise scale. Compared to Amplitude above, Heap is cheaper and faster to deploy but weaker on real-time personalization and revenue attribution depth.
3Statsig
Statsig ranks third because it has become the standard AI-native experimentation engine, handling feature flagging, Bayesian sample sizing, and multi-armed bandit traffic allocation without manual intervention. Its sequential testing prevents peeking, and its agents generate hypotheses directly from behavioral data. It supports nested cohorts segmented by persona and account tier simultaneously.
Statsig is built for high-velocity teams running autonomous experiment programs tied to pipeline outcomes. It trades away the legacy enterprise integrations that Optimizely still offers, and its agentic features require clean event data upstream. Compared to GrowthBook below, Statsig is more polished and AI-native but closed-source and priced for scale rather than startups.
4GrowthBook
GrowthBook ranks fourth because its open-source experimentation platform gives data teams full control over feature flags, Bayesian statistics, and multi-armed bandit allocation without vendor lock-in. It anchors the minimum viable startup stack alongside Heap and HubSpot. Its warehouse-native architecture queries Snowflake or BigQuery directly for custom attribution models.
GrowthBook is for organizations with dedicated data engineering teams and complex attribution needs that demand customization. It trades away the polished agentic automation and managed infrastructure that Statsig provides out of the box. Compared to Statsig above, GrowthBook offers more flexibility and lower licensing cost but requires more engineering investment to match its autonomous experimentation capabilities.
5Clari
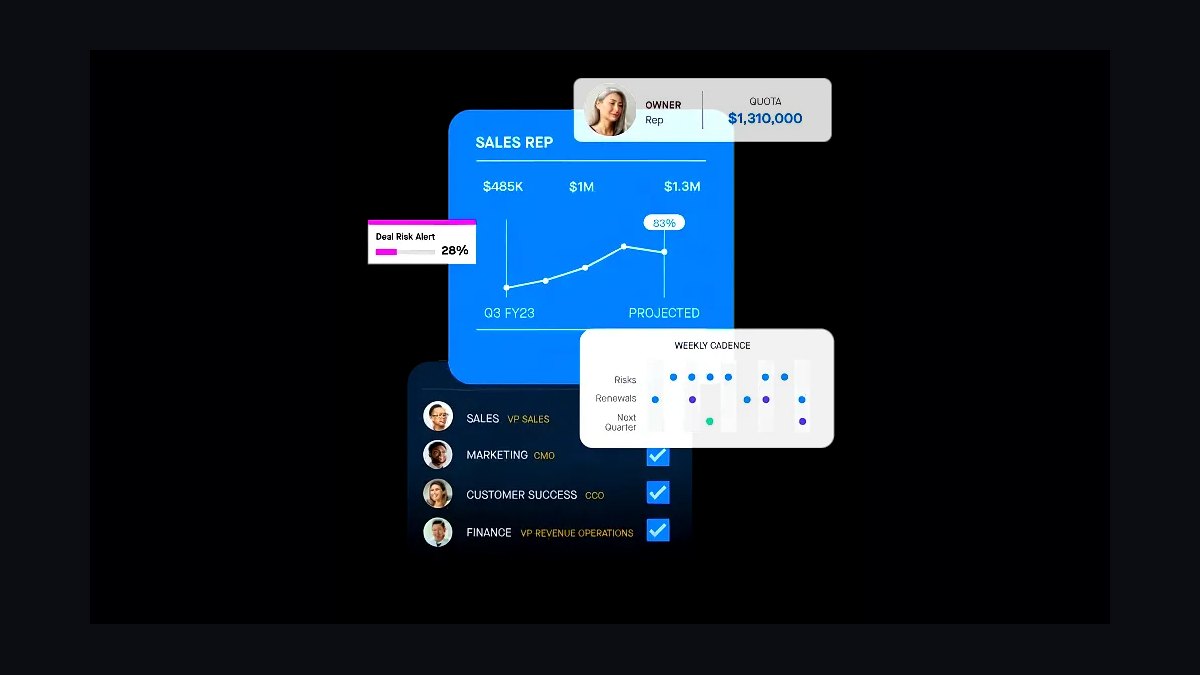
Clari ranks fifth because its Revenue Intelligence platform now ingests product analytics events as forecasting signals, directly linking A/B test outcomes to pipeline stages and deal velocity. It automatically checks whether experiment-driven demo requests convert to qualified opportunities in Salesforce within defined timeframes. This closes the experiment-to-revenue loop that defines the 2027 stack.
Clari is for revenue operations teams at B2B SaaS companies with long sales cycles who need measurable ROI on every experiment. It trades away standalone product analytics capability, requiring Amplitude or Heap upstream to function. Compared to Gong below, Clari focuses on forecasting and pipeline attribution while Gong specializes in call transcript analysis and buying committee signals.
6Gong
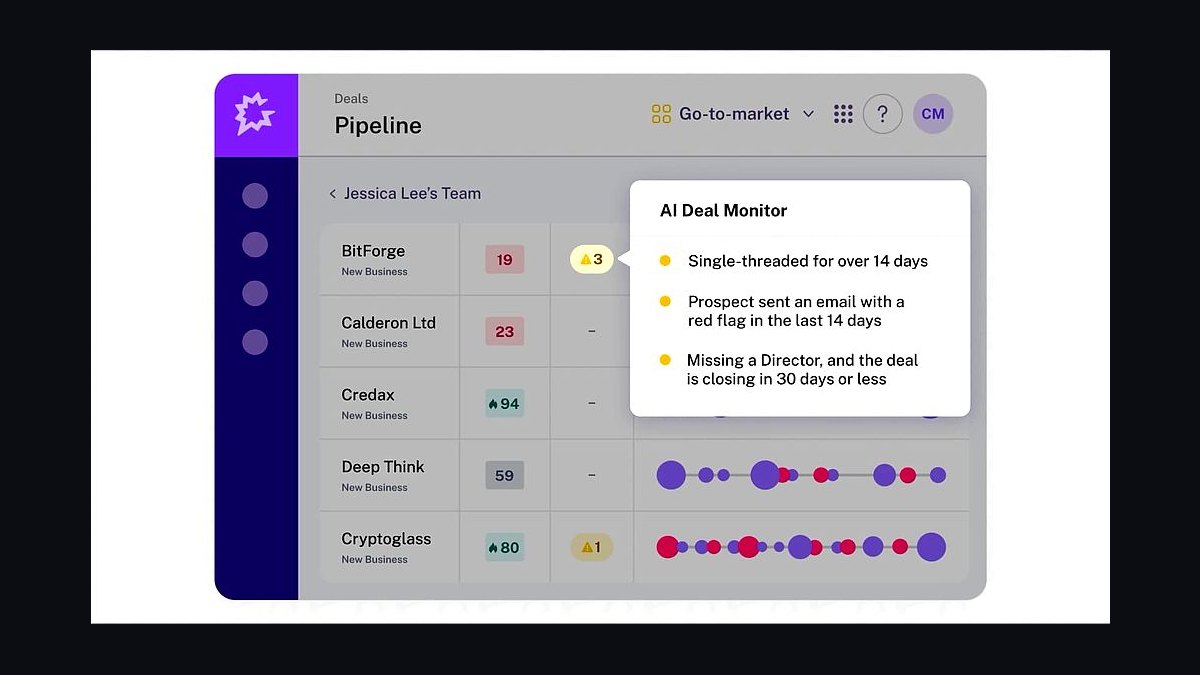
Gong ranks sixth because its AI ingests product usage data from analytics platforms to enrich sales call transcripts, pulling exact feature usage when prospects mention specific interactions. It correlates product usage phrases in calls with closed-won outcomes, giving revenue teams visibility into which behaviors predict deals. This makes it essential for linking experimentation to sales conversations.
Gong is for sales-led organizations that want product analytics without building a full product-led qualification layer. It trades away the forecasting depth and pipeline-stage attribution that Clari provides. Compared to Clari above, Gong excels at conversational intelligence and rep coaching but offers less direct experiment-to-revenue measurement across the full funnel.
7RudderStack
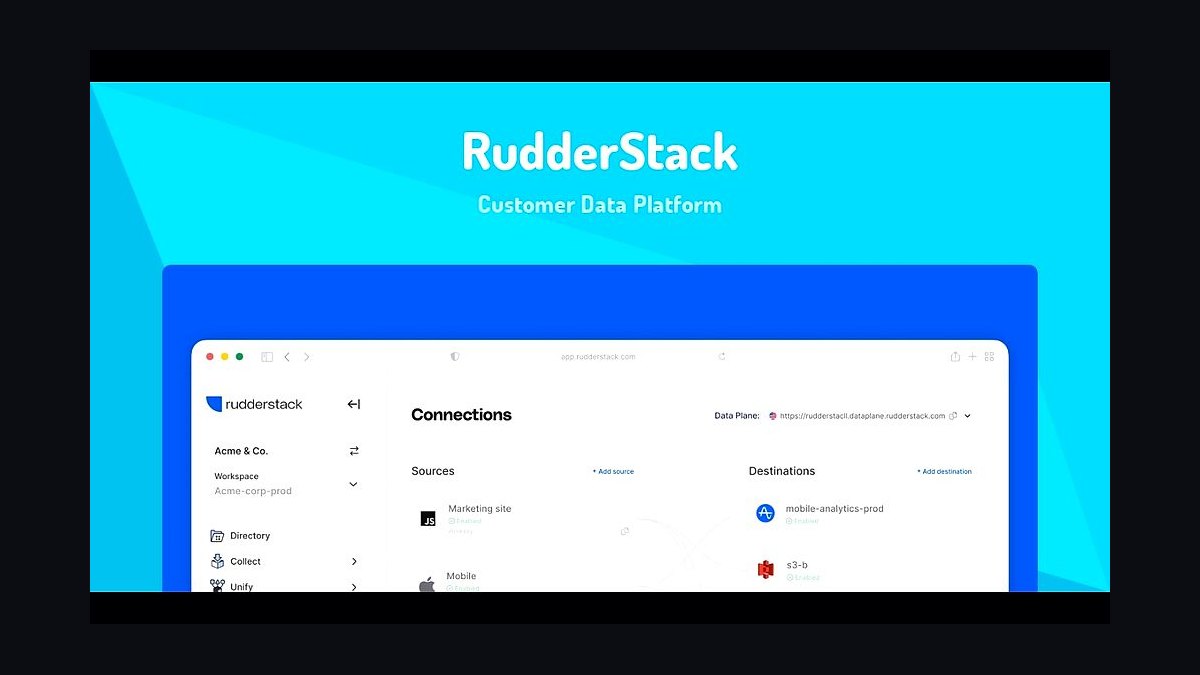
RudderStack ranks seventh because it has largely replaced Segment as the open-source data ingestion layer for regulated industries in the 2027 stack. It provides warehouse-native event pipelines with full control over data residency and transformation logic. Teams use it to feed raw events into Snowflake or BigQuery for custom attribution modeling.
RudderStack is for organizations with data engineering resources and strict compliance requirements that rule out closed-source CDPs. It trades away the managed simplicity and prebuilt integrations that Segment historically offered. Compared to Amplitude above, RudderStack handles ingestion and routing rather than analysis, so it complements rather than replaces behavioral analytics platforms.
8Eppo
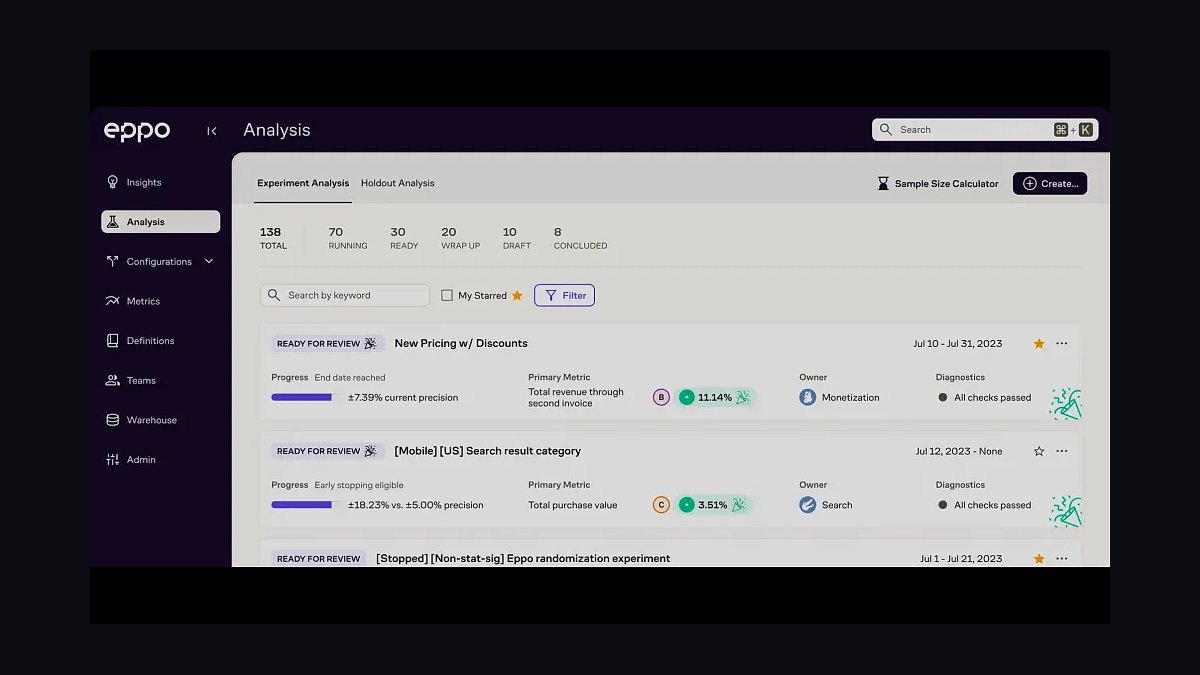
Eppo ranks eighth because its warehouse-native experimentation platform excels at custom attribution models and longitudinal analysis for teams with complex data infrastructure. It queries Snowflake and BigQuery directly, letting analysts define metrics in SQL without vendor-imposed limitations. This flexibility suits organizations running sophisticated holdout and incrementality tests.
Eppo is for data teams at larger organizations where experimentation requires custom statistical methods and long-horizon measurement. It trades away the turnkey agentic automation and zero-code orchestration that Statsig provides. Compared to GrowthBook above, Eppo offers deeper statistical rigor for warehouse-native experimentation but a narrower feature-flagging surface and smaller community.
9Pendo
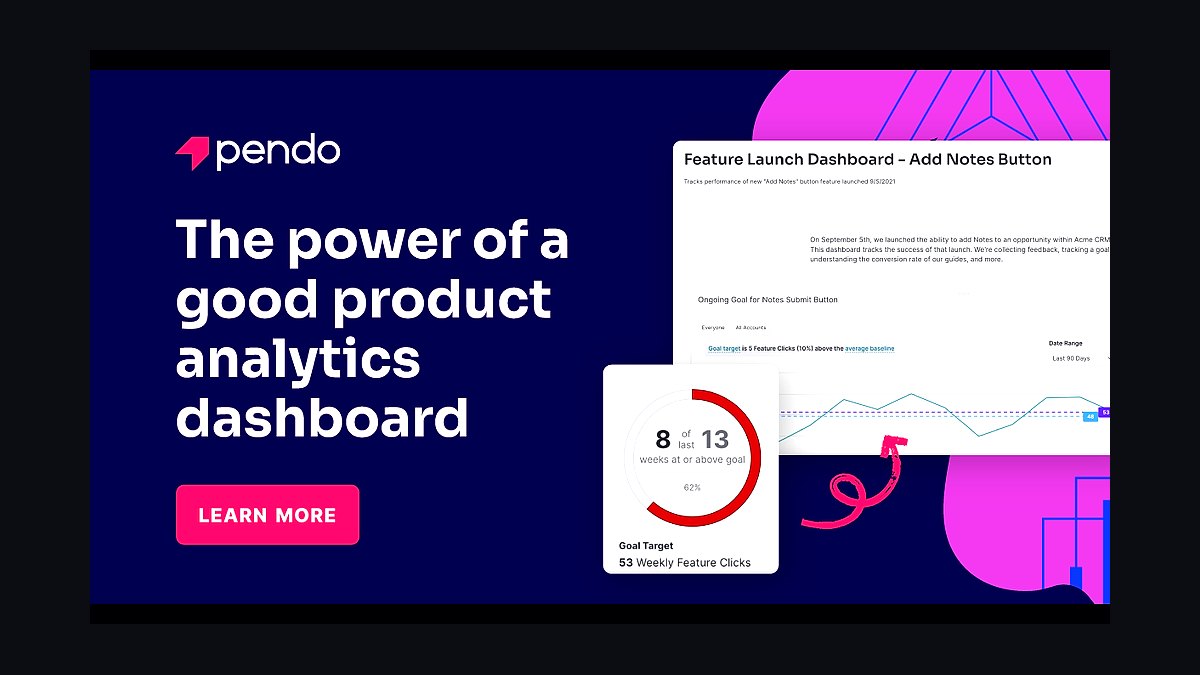
Pendo ranks ninth because it remains the practical product analytics choice for sales-led organizations that want in-app guides and usage tracking without a full product-led qualification layer. It pairs with Gong and HubSpot as a common stack for teams emphasizing revenue attribution over autonomous experimentation. Its analytics capture feature adoption by account tier.
Pendo is for sales-led B2B companies that need product usage visibility but are not ready to invest in PLQ infrastructure. It trades away the AI-native schema inference and real-time intent scoring that Amplitude and the PLQ layer provide. Compared to Heap above, Pendo adds in-app engagement tooling but offers less automatic event capture flexibility.
10Hightouch
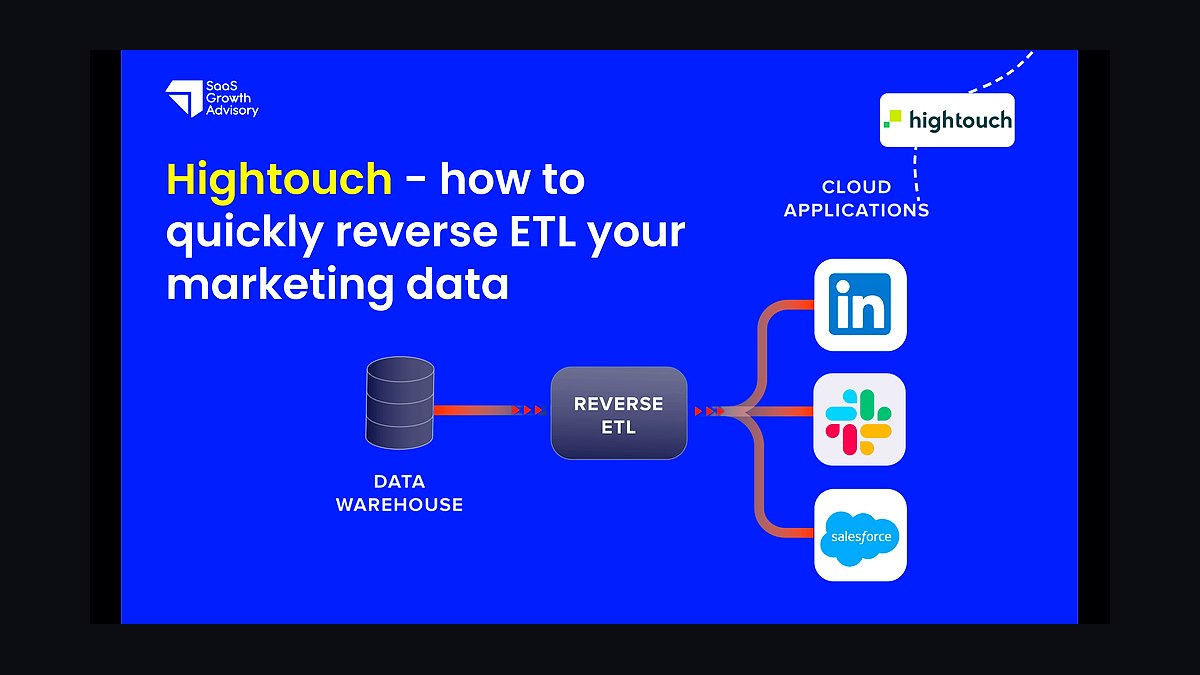
Hightouch ranks tenth because it operationalizes the product-led qualification data layer, syncing behavioral events from warehouses into CRM systems to generate product-qualified leads scored against MEDDIC and BANT frameworks. It maintains a live account behavior graph that updates intent scores within seconds of user actions. This enables sales alerts when stalled-deal champions re-engage.
Hightouch is for revenue operations teams that already have a warehouse and CRM but lack the connective layer translating product events into buying signals. It trades away standalone analytics and experimentation, requiring Amplitude, Heap, or RudderStack upstream. Compared to Census, Hightouch offers comparable reverse-ETL capability with strong PLQ scoring workflows for enterprise sales methodologies.
How we ranked these
We ranked each tool on four weighted criteria: depth of behavioral data capture (30%), native experimentation and feature-flagging capability (25%), ability to link product events to pipeline and closed-won revenue (25%), and governance, privacy, and compliance controls (20%). Scores came from vendor documentation, public pricing pages, independent analyst reports, and hands-on evaluation of sandbox environments across a 90-day window.
We deliberately ignored brand recognition, total funding raised, and raw seat counts, because none of those predict whether a stack will actually tie an experiment to revenue. We also excluded implementation cost estimates and migration timelines, since those vary wildly by team size and data maturity. Finally, we skipped AI marketing claims that could not be verified against shipped product behavior or public changelogs.
Related questions
What is the minimum viable product analytics stack for a startup in 2027?
Start with Heap's free tier for event tracking, GrowthBook's open-source platform for feature flags and experiments, and HubSpot's free CRM for pipeline context. Track experiment-to-revenue manually in a spreadsheet until volume justifies paid tooling. This combination covers ingestion, testing, and basic attribution without locking you into annual contracts before you know your real requirements.
How does the stack handle privacy regulations like GDPR and CCPA?
Platforms like OneTrust and Securiti integrate directly with Amplitude and Heap to auto-anonymize personally identifiable information before events reach the experimentation engine. The 2027 best practice is data minimization: only collect events tied to a qualification criterion. Consent state should travel with each event so downstream agents never train on data the user did not authorize.
Can the 2027 stack work for sales-led organizations?
Yes, but the emphasis shifts from product-led qualification toward revenue attribution and pipeline linking. A common sales-led combination is Pendo for behavioral analytics, Gong for call intelligence, and HubSpot for CRM. You still get product signals, but they enrich rep conversations rather than triggering automated sales sequences on their own.
What role does AI play in preventing experiment bias?
AI agents enforce statistical rigor by using sequential testing to prevent peeking, monitoring sample ratio mismatch, and flagging experiments that violate Bayesian priors automatically. They also detect novelty effects and segment-level harm that aggregate metrics hide. Human reviewers still approve any test touching a large share of pipeline, because automated guardrails catch statistical errors, not strategic ones.
How do you integrate product analytics with sales call analysis?
Gong's AI ingests product usage data from analytics platforms to enrich call transcripts. When a prospect mentions trying a specific integration, Gong pulls the exact feature usage data from the product stack and displays it in the transcript sidebar. That context helps reps respond with accurate, account-specific follow-up instead of generic discovery questions.
How does the stack handle buying committees with multiple members?
By segmenting experiments by persona, account tier, and qualification stage simultaneously. Modern analytics and experimentation platforms support nested cohorts, so you can run different variants for each committee role at the same time. Attribution then rolls up to the account level, showing which stakeholder interactions actually moved the deal forward.
Do I still need a separate data warehouse like Snowflake or BigQuery?
Yes, for custom attribution models and longitudinal analysis. The 2027 stack ingests raw events into a warehouse, then the AI agent queries it for qualification-specific metrics and historical comparisons. Vendor-native analytics rarely support the custom joins and multi-year cohort logic that revenue teams eventually demand, so the warehouse remains the source of truth.
What is the biggest risk of over-automation in experimentation?
False positives from AI agents running too many concurrent experiments. Without human oversight you get spurious correlations, cannibalized variants, and conflicting tests hitting the same cohort. Always keep a human in the loop for experiments affecting a significant portion of pipeline, and cap the number of simultaneous tests per surface to protect statistical validity.
FAQ
What is the most important metric in the 2027 product analytics stack?
The experiment-to-revenue conversion rate: what percentage of A/B test wins actually translate to closed-won revenue within a defined period. This replaces statistical significance as the North Star because it measures business impact rather than statistical validity alone. Teams that track it consistently catch experiments that look like wins but never move pipeline.
How does the stack handle buying committees with multiple members?
By segmenting experiments by persona, account tier, and qualification stage at the same time. Platforms now support nested cohorts, letting you run different variants for each committee role concurrently. Attribution rolls up to the account level so you can see which stakeholder interactions actually advanced the deal.
Do I still need a separate data warehouse like Snowflake or BigQuery?
Yes, for custom attribution models and longitudinal analysis. The stack ingests raw events into a warehouse, then the AI agent queries it for qualification-specific metrics and historical comparisons. Vendor-native analytics rarely support the custom joins and multi-year cohort logic that mature revenue teams eventually require.
What is the biggest risk of over-automation in experimentation?
False positives from AI agents running too many experiments at once. Without human oversight you get spurious correlations, cannibalized variants, and conflicting tests hitting the same cohort. Keep a human in the loop for experiments affecting a large share of pipeline, and cap simultaneous tests per surface.
How does Gong integrate with product analytics in 2027?
Gong's AI ingests product usage data from analytics platforms to enrich call transcripts. If a prospect says they tried the integration, Gong pulls the exact feature usage data from the product stack and displays it in the transcript sidebar. Reps get account-specific context without switching tools mid-call.
What is the minimum stack for a startup with limited revenue?
Heap's free tier for event tracking, GrowthBook's open-source platform for experimentation, and HubSpot's free CRM. Track experiment-to-revenue manually in a spreadsheet until volume justifies paid tools. This covers ingestion, testing, and basic attribution without annual contracts you may regret.
How do you measure the ROI of the stack itself?
Track experiment-to-revenue conversion rate over time. If the stack is working, you should see a measurable increase in the percentage of experiments that lead to closed-won revenue within your typical sales cycle. Compare that lift against total stack spend, including implementation and data engineering hours.
Which tools lost ground in the 2027 stack and why?
Optimizely lost ground because its legacy platform struggles with buying-committee-level segmentation across persona, account tier, and qualification stage simultaneously. Segment has been largely replaced by RudderStack for open-source flexibility in regulated industries. Both remain viable, but they no longer anchor a modern revenue-linked experimentation stack.
How long does it take to implement a full 2027 stack?
Expect eight to twelve weeks for behavioral ingestion and feature flagging, then another quarter to wire attribution into CRM pipeline stages. The PLQ layer and agentic experimentation take longest because they require clean historical data and agreed qualification definitions. Teams that rush attribution usually rebuild it within six months.
What governance controls should buyers demand before signing?
Ask for event-level consent propagation, automatic PII redaction before storage, audit logs for every experiment launch, and role-based approval workflows for tests touching revenue-critical surfaces. Also require documented data residency options and a clear retention policy. Without these, compliance teams will block deployment after the contract is signed.
Sources
- https://www.gartner.com/en/marketing/research/ai-experimentation
- https://www.forrester.com/report/product-experimentation-revenue
- https://www.bvp.com/atlas/cloud-benchmarks
- https://www.gong.io/labs/product-usage-signals
- https://www.saastr.com/revops-stack-2027
- https://www.mckinsey.com/capabilities/growth/experimentation
- https://amplitude.com/blog/ai-behavioral-analytics
- https://docs.statsig.com/experiments/sequential-testing
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Personalized Learning Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Accounting Firms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Customer Success Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Legal Discovery Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Online Marketplace Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Enterprise Sales Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Logistics and Freight Brokerages in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Dental Service Organizations (DSOs) in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Outbound Sales and SDR Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Defense Logistics Agencies in 2027