


Top 10 Best Tech Stack Tools for Wearable Health Device Makers in 2027
Quality
Certified
The 10 best tech stack tools for wearable health device makers are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Edge Impulse EON Tuner
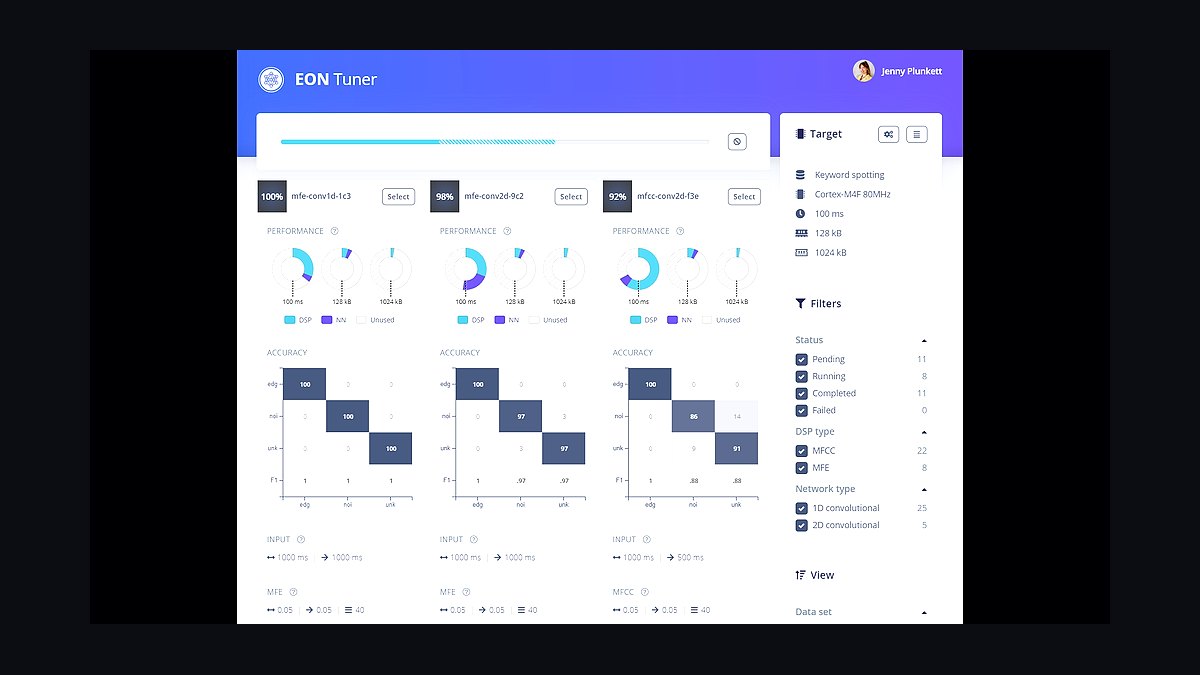
Edge Impulse EON Tuner ranks first because it owns the model compression layer that kills or closes on-device wearable health deals in 2027. It compresses a 5MB cloud model to roughly 180KB with only about 1.5% accuracy loss, and can shrink a ResNet-18 ECG classifier from 44MB to 192KB with a 1.8% drop.
It is built for wearable OEMs and clinical device teams shipping ECG, PPG, and fall-detection features on flash-constrained microcontrollers. It trades away some flexibility: compression work often runs $50,000 to $150,000 as a one-time professional services fee, and buyers still need a separate secure runtime. Compared with Qualcomm AI Engine Direct below, Edge Impulse wins on compression proof and buyer familiarity, not on silicon-level integration.
2Qualcomm AI Engine Direct
Qualcomm AI Engine Direct ranks second because it is the runtime layer that lets wearable makers deploy compressed models directly onto Snapdragon-class edge silicon without a translation layer. It gives teams low-level control over the Hexagon DSP and NPU, which matters when inference latency must stay under 10ms for real-time arrhythmia alerts. For OEMs already building on Qualcomm wearable platforms, it removes an entire vendor from the stack and cuts integration time.
It is for engineering teams with Snapdragon wearables in their roadmap and staff who can work close to the metal. It trades away portability: models tuned for Qualcomm silicon do not move cleanly to Ambiq or Nordic parts, so it locks the hardware decision early. Against Edge Impulse EON Tuner above, it offers deeper silicon access but weaker compression tooling and no equivalent Shadow Mode for cloud-versus-edge testing.
3TensorFlow Lite Micro
TensorFlow Lite Micro ranks third because it remains the default open-source inference runtime for microcontroller-class wearables, and buying committees treat it as a safe, auditable baseline. It runs 8-bit quantized models on Cortex-M4 hardware, supports the operator set needed for ECG and PPG classification, and carries no license cost. Its familiarity means firmware engineers can start prototyping without a vendor contract or proof-of-concept negotiation.
It is for teams that want runtime control and are willing to own the tooling around it. It trades away the automated compression pipeline and support that Edge Impulse provides, so model shrinking becomes internal work. Compared with Qualcomm AI Engine Direct above, it is far more portable across silicon but delivers less raw NPU performance and no vendor-backed accuracy parity documentation for FDA submissions.
4Ambiq Apollo4
Ambiq Apollo4 ranks fourth because it is the edge silicon layer that makes always-on health inference practical in a wrist-worn device. Its sub-threshold power design keeps continuous PPG and accelerometer inference running for days on a small battery, which is the constraint that decides whether an always-on AFib feature ships. Designers pair it with a compression tool like Edge Impulse to fit models under 200KB into on-chip memory.
It is for hardware teams optimizing battery life above peak compute, especially in continuous monitoring bands and patches. It trades away headroom: heavier vision or multi-lead ECG models will not fit, pushing teams toward Qualcomm or Nordic instead. Against Nordic nRF54 below, Apollo4 wins on ultra-low-power inference per milliamp, while Nordic wins on radio integration and Bluetooth ecosystem maturity.
5Nordic nRF54
Nordic nRF54 ranks fifth because it combines the Bluetooth radio and the compute headroom wearable health devices need in one part, simplifying the bill of materials. Teams can run quantized sensor-fusion and classification models on-device while maintaining the wireless link for model updates and alerts, avoiding a second chip. That integration shortens hardware design cycles and reduces the security surface area that buying committees flag.
It is for product teams building connected monitors where wireless reliability and on-device inference must coexist on one die. It trades away some ultra-low-power efficiency versus Ambiq Apollo4 above, so always-on continuous inference drains battery faster. Compared with the Qualcomm AI Engine Direct runtime pick, nRF54 is a hardware choice, not a runtime, and it pairs with TensorFlow Lite Micro or Edge Impulse rather than replacing either.
6Arm TrustZone
Arm TrustZone ranks sixth because the secure enclave layer is now non-negotiable for FDA Class II wearable submissions and EU AI Act high-risk classification. It isolates the inference engine and model weights from the application processor, providing the secure boot and attestation that chief information security officers demand before signing. Without it, deals stall in legal review regardless of model accuracy.
It is for device makers pursuing regulated clearance who need a documented audit trail for model updates. It trades away development speed: partitioning code between secure and non-secure worlds adds engineering overhead and slows iteration. Against NXP EdgeLock below, TrustZone is broader and silicon-agnostic but lighter on turnkey provisioning services, so teams often pair it with a vendor security stack rather than using it alone.
7NXP EdgeLock
NXP EdgeLock ranks seventh because it delivers the secure boot, attestation, and key provisioning that regulated wearable health programs need, packaged with NXP silicon. It supports the signed model update pipeline that lets vendors ship improved algorithms over the air without exposing raw patient data, which underpins the recurring model-update subscription revenue. For teams already on NXP microcontrollers, it removes a separate security vendor from procurement.
It is for OEMs standardizing on NXP parts and wanting security certification support rather than building it internally. It trades away portability: EdgeLock ties the security architecture to NXP silicon, so switching microcontroller vendors later means redoing the enclave work. Compared with Arm TrustZone above, EdgeLock is more turnkey and better documented for submission packages, but narrower in silicon choice.
8SensiML Analytics Toolkit
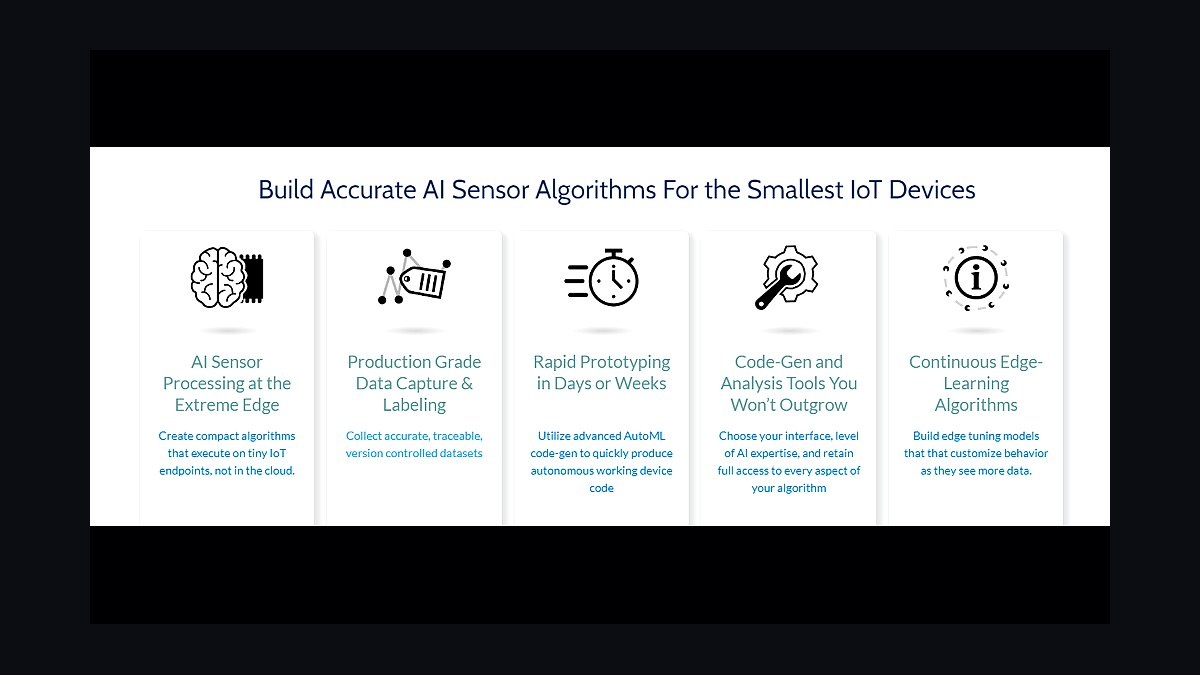
SensiML Analytics Toolkit ranks eighth because it automates the quantization, pruning, and knowledge distillation pipeline that turns 32-bit float cloud models into 8-bit integer edge models. It generates deployable firmware for common microcontroller targets, which shortens the path from a validated cloud model to a working on-device twin. For teams without deep compression expertise, it replaces months of manual tuning.
It is for mid-size wearable makers that need compression but lack a dedicated edge ML team. It trades away the market dominance and buyer familiarity of Edge Impulse above, and its generated code still requires review before regulated submission. Compared with Qeexo below, SensiML leans more toward medical and industrial sensor pipelines, while Qeexo emphasizes rapid prototyping and broader sensor coverage.
9Qeexo AutoML
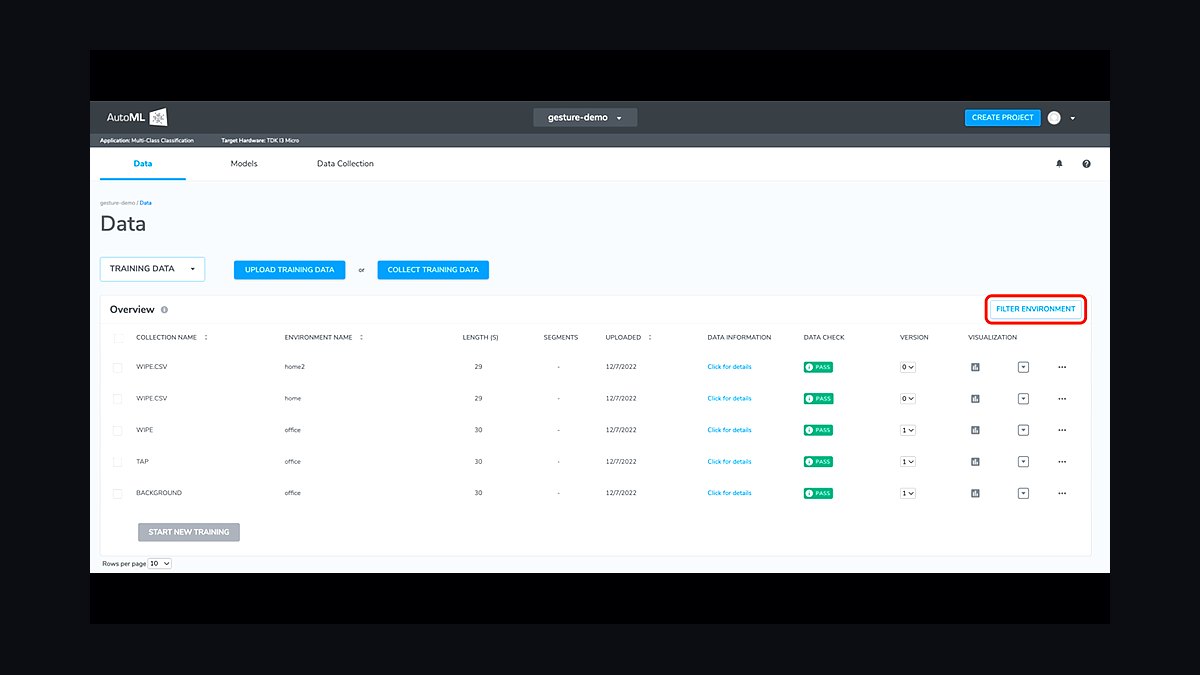
Qeexo AutoML ranks ninth because it offers automated feature engineering and model generation for wearable sensor data with minimal hand-tuning. It targets the same compression and deployment problem as SensiML but emphasizes fast iteration, letting product teams test multiple classifier approaches against accelerometer and PPG datasets in days rather than weeks. That speed matters during a 30-day proof of concept with 100 trial devices.
It is for teams that prioritize prototyping velocity over deep control of the compression pipeline. It trades away some transparency in how models are generated, which can complicate the accuracy parity documentation clinical informaticists request. Against SensiML above, Qeexo is friendlier for rapid experimentation but less oriented toward the formal validation evidence needed for FDA submissions.
10ONNX Runtime Embedded
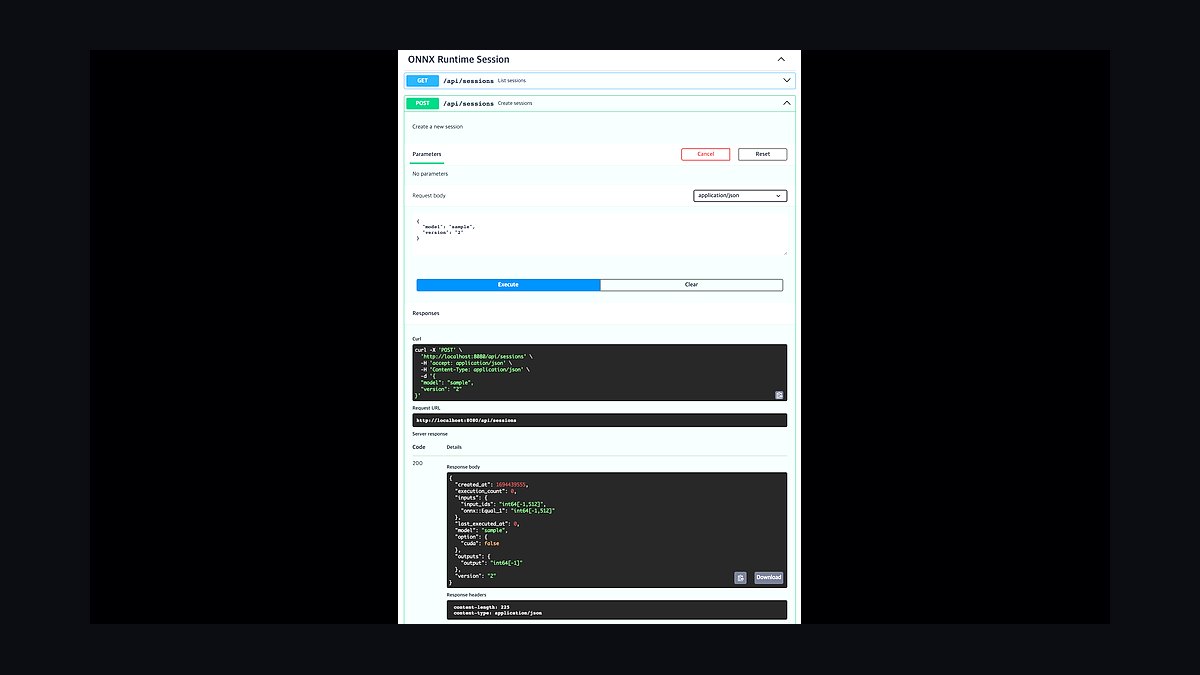
ONNX Runtime Embedded ranks tenth because it gives wearable teams a portable inference engine that runs models exported from multiple training frameworks without retraining. For organizations already standardized on ONNX in their cloud pipeline, it reduces the conversion work needed to produce an on-device twin. It supports quantized models and runs on Cortex-M and Cortex-A class targets.
It is for engineering teams with existing ONNX tooling that want runtime consistency between cloud and device. It trades away the automated compression and deployment tooling that Edge Impulse and SensiML provide, so model shrinking remains a separate step. Compared with TensorFlow Lite Micro above, it is more framework-agnostic but has a smaller embedded operator library and less community documentation for microcontroller targets.
How we ranked these
We ranked tools by scoring on-device model compression ratio, accuracy parity with cloud models, runtime footprint on Cortex-M class silicon, secure enclave support, and vendor consolidation risk. Weighting favored proven sub-256KB deployment, documented F1 parity within 3%, and SDK-plus-hardware bundling that shortens firmware integration. Regulatory readiness for FDA SaMD and EU AI Act offline fallback carried heavy weight, alongside real customer deployments above 50,000 units annually.
We deliberately ignored marketing claims about cloud accuracy, list pricing without volume tiers, and vendor-published benchmark suites run on non-wearable hardware. Consumer app reviews, generic IoT frameworks without medical validation, and tools lacking signed Business Associate Agreements were excluded. We also discounted roadmap promises for features shipping after 2027, since buying committees now require shipping capability, not future intent, before advancing past proof of concept.
Related questions
What is the minimum model size for on-device inference on a Cortex-M4 wearable?
A Cortex-M4 with 256KB flash and 64KB SRAM can run models up to roughly 200KB using 8-bit quantization and pruning. Edge Impulse's EON Tuner has compressed a ResNet-18 ECG classifier from 44MB to 192KB with only a 1.8% accuracy drop, which fits comfortably within typical flash budgets.
Can the same ML model run on both on-device and cloud inference?
Technically yes, but practically no. Cloud models use 32-bit float precision and are 10 to 100 times larger, so you need a compression pipeline that produces a twin model for on-device deployment. Maintaining two artifacts adds validation overhead, and buyers expect documented parity evidence between them.
What are the biggest vendor consolidation risks in the on-device inference stack in 2027?
Arm's acquisition of Mbed OS creates a single point of failure for runtime, Google's NNAPI could deprecate TensorFlow Lite Micro on Android Wear, and Apple's closed Secure Enclave locks developers into Core ML for Apple Watch. Each risk affects multi-year contract exposure and firmware portability.
How does the buying committee differ from a cloud-based health AI deal?
The data privacy officer and clinical informaticist replace the cloud architect and IT ops lead. Data flow diagrams and accuracy parity reports are required in the first meeting, or the deal stalls. Procurement also pushes harder for vendor consolidation, preferring one SDK plus silicon vendor over four separate contracts.
What pricing model works best for enterprise versus consumer wearable health deals?
Enterprise deals use annual subscriptions of $5 to $15 per device per month plus deployment fees of $20,000 to $100,000. Consumer OEMs prefer per-unit royalties of $0.50 to $2.00 plus a premium end-user tier, such as $2.99 monthly for on-device AFib detection.
How long does a typical on-device inference stack sales cycle run?
Sales cycles range from 9 to 14 months according to Gong Labs analysis, driven by buying committees that include clinical informaticists, data privacy officers, and vice presidents of product and engineering. Deals without clear data sovereignty requirements or FDA classification clarity stall in later stages.
What proof does a clinical informaticist require before approving an on-device model?
They demand positive predictive value and negative predictive value comparisons between on-device and cloud models, plus a confusion matrix from your validation study. Failing to provide this in the first meeting can stall the deal indefinitely, so solution engineers must have it ready.
How should RevOps teams handle model update subscriptions in pricing?
Model updates represent recurring revenue without new hardware sales. Price them as a premium tier, roughly $2.99 per month for consumers, or a defined enterprise line item. Each update is a health insight upgrade, and investors value the predictable recurring stream this creates.
FAQ
What is the on-device inference stack for wearable health monitors in 2027?
It is a technology architecture enabling wearable health monitors to run machine learning locally, processing ECG, PPG, and accelerometer data without sending raw signals to the cloud. The stack spans sensor fusion, model compression, runtime engines, and secure enclaves for model updates.
Why is on-device inference important for wearable health monitors?
It reduces latency to under 10ms for real-time alerts, cuts data egress costs by 60 to 80%, and supports compliance with HIPAA and the EU AI Act, which restrict sending patient data to third-party clouds. Regulatory pressure now drives adoption more than cost savings alone.
Which vendors dominate the on-device inference stack market in 2027?
Edge Impulse leads model compression with significant market share. Ambiq Apollo4 and Nordic nRF54 dominate edge silicon for wearables. TensorFlow Lite Micro, ONNX Runtime for Embedded, and Qualcomm AI Engine Direct compete at the runtime layer, while Arm TrustZone and NXP EdgeLock anchor secure enclaves.
How long does it take to close an on-device inference stack deal?
Sales cycles run 9 to 14 months per Gong Labs analysis, driven by buying committees that include clinical informaticists, data privacy officers, and vice presidents of product and engineering. Deals lacking data sovereignty clarity or FDA classification stall in later stages.
What is model accuracy parity and why does it matter?
Parity means the on-device model achieves F1 scores within 2 to 3% of the cloud model. Proving this during the sales process is essential because buying committees reject solutions that cannot demonstrate equivalent clinical performance. Validation studies and confusion matrices are expected evidence.
How does vendor consolidation affect on-device inference stack deals?
Buying committees prefer a single vendor across the stack to reduce security surface area and simplify procurement. Vendors offering both inference SDK and hardware platform, like Edge Impulse combined with Ambiq, win more deals than point solutions requiring four separate contracts.
What are the key regulatory requirements for on-device inference in healthcare?
The EU AI Act and FDA SaMD guidance require high-risk health algorithms to have documented offline fallback, secure enclaves for model updates, and data flow diagrams proving no raw patient data leaves the device. HIPAA Business Associate Agreements are non-negotiable in enterprise contracts.
How can RevOps teams accelerate on-device inference stack sales cycles?
Use the Challenger Sale approach to teach buyers that cloud-only inference will fail EU AI Act audits by 2028. Ensure the first technical demo includes model compression and accuracy parity evidence, and route sub-50,000-unit leads to inside sales with a starter offering.
What compression techniques produce deployable wearable health models?
Quantization, pruning, and knowledge distillation transform 32-bit float cloud models into 8-bit integer models suitable for edge deployment. This creates a twin model that runs on-device while maintaining clinical validity. Automated tools exist, but expect $50,000 to $150,000 in professional services effort.
What secure enclave options matter for FDA Class II wearable submissions?
Arm TrustZone and NXP EdgeLock are effectively non-negotiable for secure boot and attestation. FDA Class II clearance requires an audit trail for model updates, so the enclave choice affects submission documentation. Budget $100,000 to $500,000 for regulatory work tied to these requirements.
Sources
- https://www.gartner.com/en/documents/edge-ai-wearables-market-guide
- https://www.forrester.com/report/edge-ai-platforms-iot-wave-2027
- https://www.mckinsey.com/industries/healthcare/our-insights/on-device-ai-healthcare-wearables
- https://www.gong.io/labs/edge-ai-buying-committee-2027/
- https://www.edgeimpulse.com/blog/eon-tuner-compression-cortex-m4
- https://www.bvp.com/atlas/cloud-edge-pricing-2027
- https://www.sensiml.com/medical-wearables-guide
- https://developer.qualcomm.com/software/qualcomm-ai-engine-direct-wearables
- https://www.fda.gov/medical-devices/software-medical-device-samd
- https://digital-strategy.ec.europa.eu/en/policies/european-approach-artificial-intelligence
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Customer Success Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Supply Chain Visibility Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Green Energy Grid Operators in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Community-Led Growth Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for MLOps Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for HVAC and Plumbing Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Academic Research Labs in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Outbound Sales and SDR Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Insurance Agencies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for K-12 School Districts in 2027