


Top 10 Best Tech Stack Tools for Revenue Data Teams in 2027
Quality
Certified
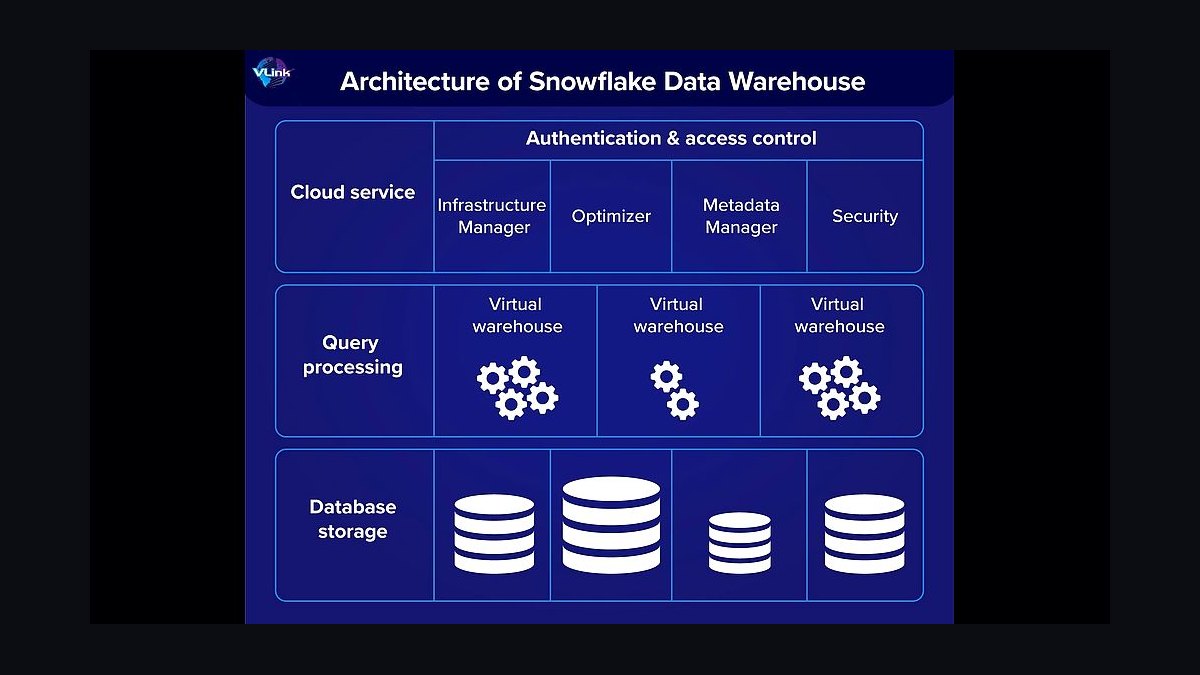
The 10 best tech stack tools for revenue data teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Snowflake Data Warehouse
Snowflake tops the stack because its separation of storage and compute makes it the default landing zone for revenue data at mid-market scale. A 210-person SaaS team running scheduled transformations a few times daily on tens of millions of rows typically lands in the low tens of thousands per year. Time travel and zero-copy cloning let analysts snapshot opportunity tables daily without duplicating storage cost.
It suits teams that want managed infrastructure without capacity planning, vacuum maintenance, or an on-call pager rotation. The trade-off is consumption billing: continuous refreshes can multiply compute several times over, so freshness must be a budget decision. Compared with Databricks below, Snowflake trades lakehouse flexibility for simpler SQL-first operations and faster onboarding.
2Databricks Lakehouse Platform
Databricks ranks second because it handles the extreme product-telemetry volumes that break per-row ingestion pricing, unifying Delta Lake storage with Spark and SQL compute in one governed lakehouse. Teams with billions of product usage events can keep raw data in open table formats on their own object storage, avoiding vendor-proprietary formats. Unity Catalog centralizes governance across those tables.
It is built for organizations with engineering depth already comfortable with notebooks, Spark, and cluster tuning. The trade-off versus Snowflake is operational complexity: cluster configuration and job orchestration demand more expertise. Choose Databricks when volume economics and open formats matter more than the simplest possible SQL experience.
3Fivetran Managed Connectors
Fivetran ranks third because it absorbs the schema drift that sinks hand-built extract jobs, automatically adding new source columns to target tables and handling pagination, rate limits, and incremental cursors. It captures hard deletes and CRM record merges through periodic full re-syncs, closing the incremental-correctness gap that makes warehouse counts quietly diverge from the CRM by two percent.
It is for teams with eight to fifteen SaaS sources who would otherwise track twenty API changelogs forever. The trade-off is monthly-active-row pricing, which scales with event volume: product usage and email-activity tables dwarf CRM tables by orders of magnitude, and ingestion can cost as much as the warehouse itself. Compare with Airbyte below when volume costs dominate.
4dbt Transformation Framework
dbt ranks fourth because the transformation layer is exactly where revenue teams should own their definitions rather than outsource them. It turns opportunity, activity, and billing rows into dim_account, fct_opportunity_stage_change, and fct_pipeline_snapshot in version-controlled SQL that is portable across engines. Tests enforce uniqueness, non-null keys, and referential integrity between facts and dimensions.
The open-source core is free, and the hosted orchestration tier is a modest per-developer-seat cost for a small team. It trades away nothing important for revenue modeling, though very large teams may hit orchestration limits and run it on their own scheduler. Compared with Fivetran above, dbt owns meaning while Fivetran owns plumbing.
5Airbyte Data Integration
Airbyte ranks fifth because its open-source connectors and self-managed deployment options resolve a large share of data-residency objections that otherwise force a build. Teams can run the data plane inside their own network while keeping the control plane managed, satisfying sovereignty requirements without hand-writing extract jobs against every vendor API. The connector catalog covers hundreds of sources.
It suits teams with compliance constraints or unusually high ingestion volume where per-row pricing hurts. The trade-off versus Fivetran is maintenance: self-hosted deployments require upgrading, monitoring, and occasional connector debugging, effectively a fraction of an engineering FTE. Pick Airbyte when control and cost matter more than fully managed reliability.
6Salesforce Revenue Cloud
Salesforce Revenue Cloud ranks sixth because it keeps the system of record for opportunities, quotes, and billing contracts inside the CRM where reps already work, reducing the reconciliation gap between closed-won records and invoiced revenue. Native objects mean the warehouse can pull opportunity and stage-change history without custom extraction, and CPQ data lands in the same schema as pipeline.
It is for organizations already standardized on Salesforce that want billing and revenue recognition close to the CRM rather than in a separate finance system. The trade-off is cost and lock-in: licensing is expensive and configuration is heavy. Compare with HubSpot below when the team is smaller and wants faster time to value.
7HubSpot Operations Hub
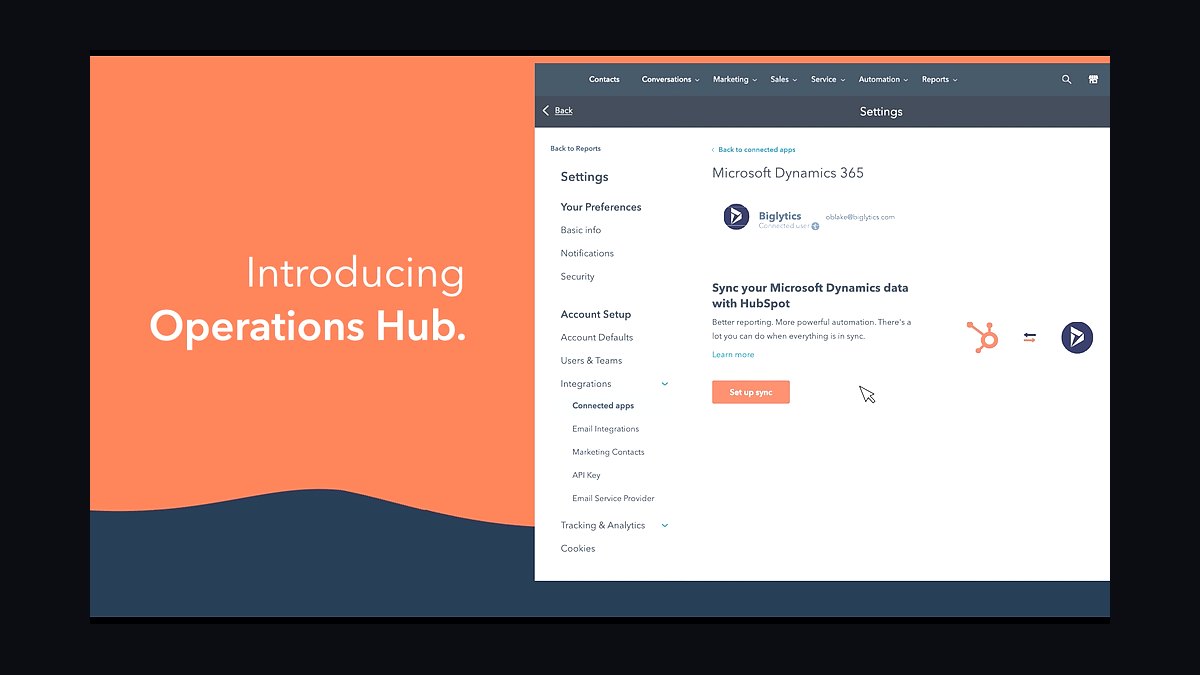
HubSpot Operations Hub ranks seventh because it gives smaller revenue teams a single platform for CRM, marketing touches, and data sync without standing up a separate ingestion vendor for the top three sources. Programmable automation and two-way syncs push modeled scores and segments back into the tools reps use, addressing the activation gap that stalls adoption at the analytics team.
It is for teams under roughly 200 people where marketing and sales data already live in HubSpot and a full warehouse stack is premature. The trade-off versus Salesforce Revenue Cloud is depth: complex multi-entity billing and partner-sourced attribution outgrow it. Choose HubSpot when speed of setup beats configurability.
8Looker BI Platform
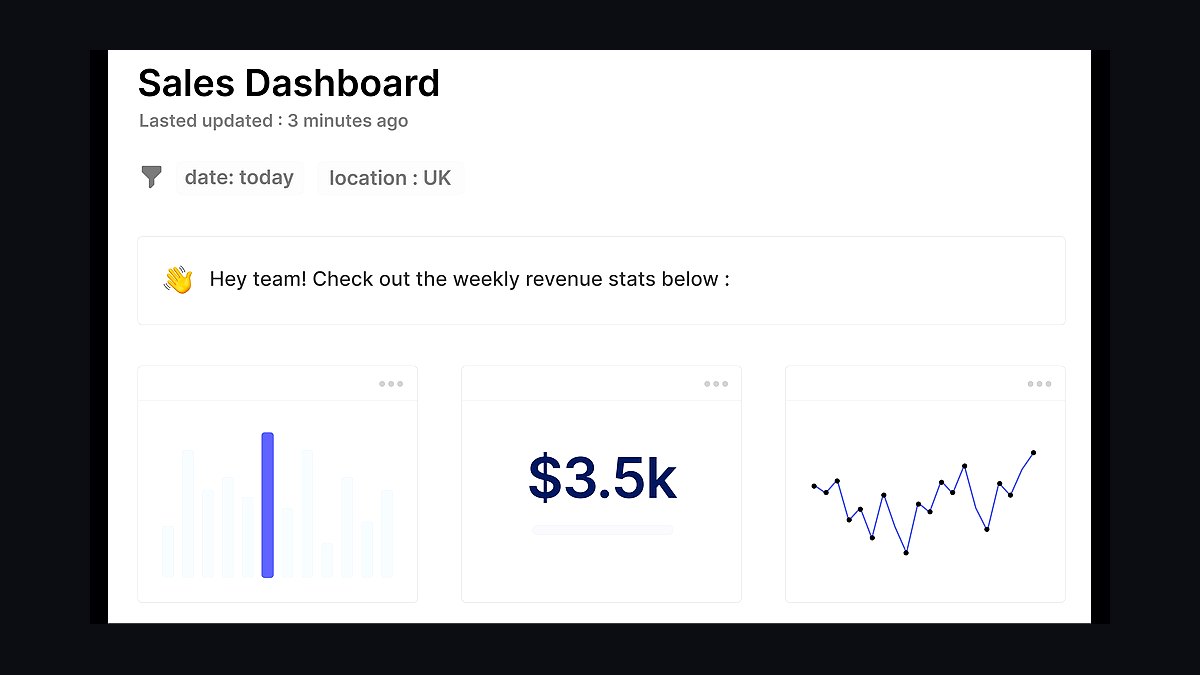
Looker ranks eighth because its semantic modeling layer keeps metric definitions in version-controlled LookML, so pipeline, qualification, and revenue definitions live next to the SQL that implements them rather than scattered across dashboards. That directly addresses the failure mode where sales, marketing, and finance build three dashboards that disagree and destroy trust in the warehouse.
It is for teams that need governed, consistent metrics distributed widely across the company. The trade-off is per-seat pricing that scales with viewer count, not analyst count, plus a real learning curve for LookML. Compared with a lightweight BI tool, Looker costs more but prevents definition drift as the organization grows.
9Hightouch Reverse ETL
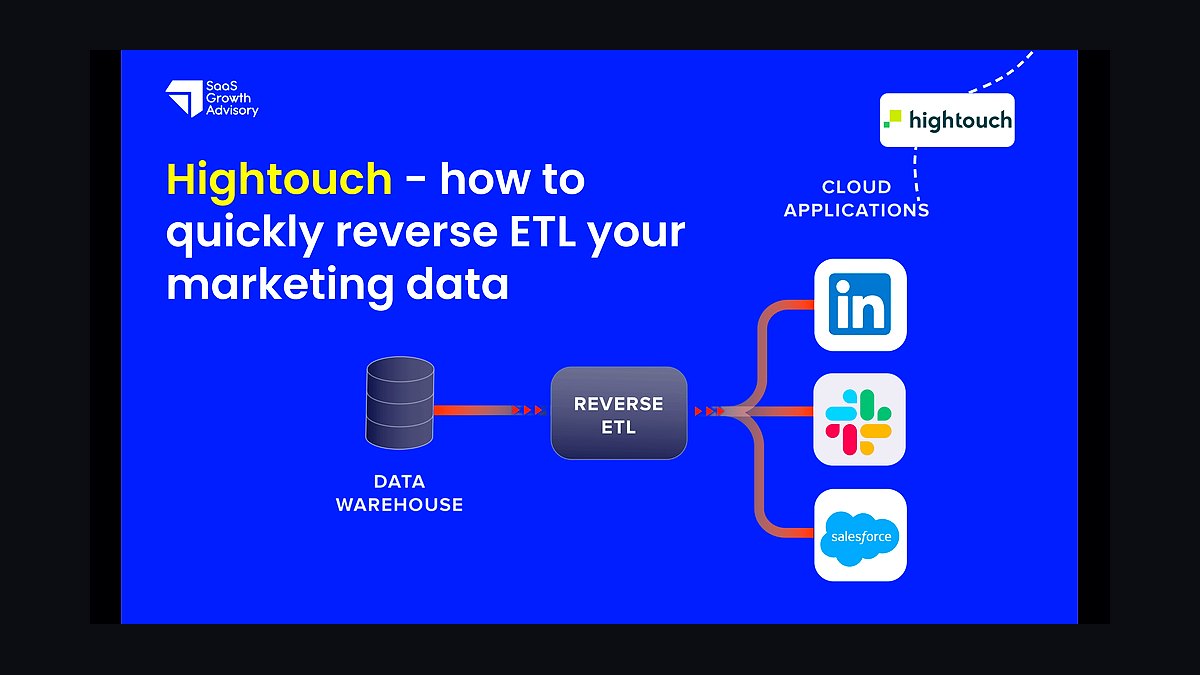
Hightouch ranks ninth because modeled data that never flows back into operational tools stalls adoption, and reverse ETL closes that loop by syncing scores, segments, and account tiers from the warehouse into the CRM and engagement platforms. Reps see deal-risk signals where they work instead of logging into a separate dashboard, which is what makes the warehouse change behavior rather than just reporting.
It is for teams that have already built trusted marts and now need activation. The trade-off is record-based pricing that grows with synced volume, plus stickiness: reverse-ETL layers are harder to migrate than storage, so metric definitions should be documented outside the tool. Pair it with dbt above, not instead of it.
10Monte Carlo Data Observability
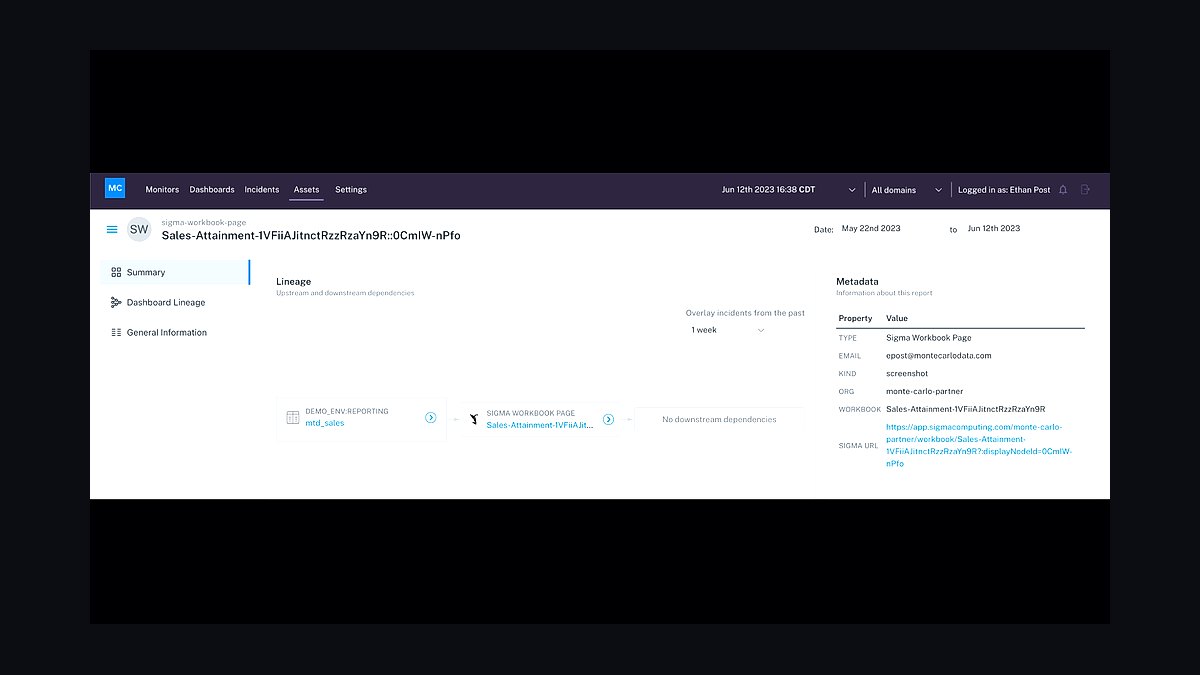
Monte Carlo ranks tenth because silent staleness is worse than a hard failure: people keep making decisions on data that stopped updating. It monitors freshness, row-count anomalies, and schema changes across warehouse tables, alerting before a broken pipeline quietly corrupts the forecast. That observability is what keeps finance trusting the numbers after the initial build.
It is for teams running production revenue reporting where a pipeline outage is a reporting outage. The trade-off is another subscription and another integration to maintain, which is hard to justify before the warehouse serves decision-making. Compared with Hightouch above, Monte Carlo protects trust in the data while Hightouch distributes it.
How we ranked these
We ranked each tool on five weighted criteria: time-to-first-trusted-dashboard (25%), total three-year cost including fully loaded engineering time (20%), connector breadth and schema-drift handling (20%), transformation and semantic flexibility (20%), and governance, lineage, and observability (15%). Scores came from vendor documentation, public pricing pages, hands-on trials, and practitioner reports on ingestion volume costs and maintenance burden.
We deliberately ignored analyst quadrant placement, brand recognition, and demo polish, because none of those predict whether a three-person RevOps team ships a reconciled forecast. We also excluded AI feature checklists, since most buyers cannot evaluate them pre-purchase, and we discounted list pricing in favor of consumption behavior at realistic row volumes, which is what actually drives renewal surprises.
What to look for
What matters most is your source inventory: how many systems, their record volumes, and whether managed connectors already exist. A team with twelve mainstream SaaS sources and modest CRM volume should almost always buy ingestion and storage, then own transformation. The decision flips only when one enormous internal source makes per-row pricing exceed a dedicated engineer's fully loaded cost.
The mistake most buyers make is pricing year one and ignoring the maintenance loop. Custom extractors look cheap until every vendor API change, credential rotation, and backfill becomes your pager. Buyers also conflate owning SQL models with building infrastructure, then over-build. Price three years, include a maintenance FTE from day one, and write down the conditions that would flip the decision.
Related questions
Should we build our own RevOps data warehouse or buy one in 2027?
Buy, for nearly every team. Managed warehouses plus off-the-shelf connectors already solved ingestion, governance, and AI-ready schemas. Build only when data residency law, proprietary sources without connectors, or a genuinely unique attribution model forces it, and only with dedicated engineers. Most real decisions are about which layers to buy, not whether to buy at all.
Which layer should we always own ourselves?
Transformation. Metric definitions, account hierarchies, attribution logic, and stage-progression models encode how your business works. Keep them in version-controlled SQL you own and can port between engines. Buy the plumbing, own the meaning. Prebuilt vendor packages are starting points, not final schemas, especially with usage-based expansion or multi-entity billing.
How long until a bought warehouse pays for itself?
Most mid-market teams see a credible decision-changing dashboard within a quarter. Payback is easiest to argue where the warehouse eliminates recurring manual reconciliation. Count analyst hours currently spent stitching monthly reports, multiply by fully loaded hourly cost, and compare against subscription spend. If pipeline reviews change three months earlier, price that in pipeline terms too.
Does buying mean we no longer need a data engineer?
No. You still need someone owning models, tests, and definitions, typically half to one full-time equivalent at mid-market scale. Buying removes infrastructure and connector maintenance, not analytics engineering. Teams that budget zero headcount for this end up with an unmaintained warehouse nobody trusts, which is worse than no warehouse at all.
When does building ingestion actually win?
When per-row connector pricing on one enormous, stable source exceeds a dedicated engineer's fully loaded cost. That is a scale problem, and it arrives with product-telemetry volume long before CRM volume. The right response is selective insourcing: keep buying connectors for low-volume, high-churn SaaS APIs where schema drift is the enemy, and hand-build only the giant stable pipelines.
What is the biggest hidden cost of a custom build?
The maintenance loop. Every source API change, credential rotation, rate-limit update, and backfill re-enters a queue that never terminates. Price it as a persistent one to two full-time engineers, not a one-time build. Add the bus-factor risk: if the primary maintainer leaves, institutional knowledge walks out and reporting becomes an outage.
How do we handle data residency requirements without building everything?
Verify the constraint first. Major warehouse vendors support many regions and private-network deployments, and several ingestion vendors offer self-hosted agents where the data plane never leaves your network while the control plane stays managed. That pattern resolves most compliance-driven build arguments. Build only where no vendor deployment genuinely matches your legal or contractual requirement.
What should we snapshot from day one?
The opportunity table, daily, on either path. CRM systems overwrite current state, so without snapshots you can never answer what the forecast looked like six weeks ago or how much pipeline was created and then pushed out. Retrofitting history is impossible because the past is gone. This is the most common regret in warehouse projects and costs almost nothing to prevent.
FAQ
What is the single most important input to the build-versus-buy decision?
Your source inventory: every system, its record volume, update frequency, and whether a managed connector exists. That one list decides most arguments. Twelve mainstream SaaS sources with modest CRM volume means buy ingestion and storage. One enormous internal source with no connector and brutal per-row pricing is the narrow case where selective building wins.
How should we compare costs honestly across three years?
Model three years, not one. Buy costs are roughly flat-to-growing with volume; build costs are heavily front-loaded in year one and then persistently staffed forever. Load engineering at 1.25 to 1.4 times base salary, include a maintenance FTE from day one, and add a risk line for the probability your primary maintainer leaves within 24 months.
Why do custom extractors quietly diverge from source systems?
Naive extractors pull records whose updated-at timestamp changed since the last run. That misses hard deletes, account merges, and backdated parent-record edits. Managed connectors handle these with periodic full re-syncs and deletion capture. Teams often discover the gap months later when warehouse closed-won counts differ from the CRM by two percent and finance stops trusting the numbers.
What is the most common reason build decisions go wrong?
Choosing build for a reason that expires. A team builds custom ingestion because a critical source had no connector in year one. Three years later the connector exists, but the custom job is load-bearing, undocumented, and owned by an engineer who left. The build compounds into a maintenance tax nobody budgeted and nobody can name.
How fresh does warehouse data actually need to be?
Fresher than monthly, almost never real-time. Continuous or near-real-time refreshes can multiply compute bills several times over, which makes freshness a budget question rather than a preference. Most RevOps decisions run fine on scheduled refreshes a few times daily. Reserve continuous pipelines for operational triggers where a delayed score genuinely costs revenue.
What breaks warehouse projects more often than technology?
Unreconciled definitions. Sales, marketing, and finance define qualified, pipeline, and closed differently. Building on those definitions produces three dashboards that disagree and a credibility problem outliving the project. Run the definition workshop first, write the definitions down, and store them in the repository next to the SQL that implements them.
How do we avoid vendor lock-in on the buy path?
Keep raw landed data in open table formats in your own object storage where possible, and keep transformation logic in version-controlled SQL portable across engines. Document metric definitions outside the semantic tool so they survive a migration. Storage is the least sticky layer; activation and semantic layers are stickier, so treat those contracts as longer commitments.
What observability is mandatory before anyone trusts the warehouse?
Freshness thresholds per source, row-count anomaly detection, schema-change alerts, uniqueness and non-null tests on primary keys, referential integrity between facts and dimensions, and a reconciliation check against source-system totals. Silent staleness is worse than a hard failure because people keep making decisions on data that stopped updating weeks ago.
Should we migrate everything at once or phase it?
Phase it. Land three sources, model one business question end to end, and get one team to genuinely trust the output. Then expand. Big-bang migrations fail on trust rather than technology, and a pipeline nobody believes has negative value. Each successful phase buys credibility for the next, which is the currency that keeps the project funded.
How often should we revisit the build-versus-buy decision?
Annually, with a named owner and written flip conditions. Connector coverage expands, so a build justified by unsupported sources may no longer be justified next year. Volume grows, so a buy decision that penciled at ten million rows may not at a billion. Writing flip conditions in advance keeps the review honest once everyone is invested in the status quo.
Sources
- https://docs.getdbt.com/docs/introduction
- https://docs.snowflake.com/en/user-guide/intro-key-concepts
- https://cloud.google.com/bigquery/docs/introduction
- https://docs.airbyte.com/understanding-airbyte/cdc
- https://docs.fivetran.com/
- https://docs.hightouch.io/
- https://docs.salesforce.com/
- https://docs.getdbt.com/docs/build/data-tests
- https://docs.snowflake.com/en/user-guide/resource-monitors
- https://docs.airbyte.com/understanding-airbyte/schema-change-management
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Tech Stacks strategies for 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Mid-Size Logistics Tech Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Early-Stage Startups in 2027
 tkTop 10 Best Tech Stack Tools for First-Time Business Owners in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Small Businesses in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Bootstrapped Startups in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Startups in 2027
 pulse-tech-stacksTop 10 Database Stacks for Large-Scale Inventory Management in 2027
 pulse-tech-stacksTop 10 Data Engineering Tools for E-commerce Analytics Teams in 2027
 pulse-tech-stacksTop 10 Data Visualization Tools for Marketing Analysts in 2027