


Top 10 Best Tech Stack Tools for AI-First Sales Teams in 2027
Quality
Certified
The 10 best tech stack tools for ai-first sales teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Gong Revenue Intelligence
Gong ranks first because it anchors the coaching half of the AI-first stack, the layer where ramp time actually compresses. It records and transcribes calls, tags outcomes, and surfaces which behaviors correlate with progression in your specific sales motion, which is exactly the data-collection work the rollout plan requires before any live prompt is enabled.
It suits teams with wide performance spread between their 25th and 75th percentile reps, since variance reduction is where coaching earns its keep. It trades away nothing on the prospecting side — Gong will not write or send outbound sequences, so you still need an autonomous agent layer beneath it. Compared with Revenue.io directly below, Gong is stronger on post-call analytics and weaker on real-time in-call prompting depth.
2Revenue.io
Revenue.io ranks second because it specializes in the real-time prompting layer that Gong covers more broadly, delivering in-call guidance while the conversation is still live. That timing matters: the credible mechanism for ramp compression is correction inside the moment, not a recording reviewed the following week. It also handles the sequencing and dialer side of the stack, which reduces the number of separate systems a rep has to context-switch between mid-call.
It is built for teams whose priority is live coaching over post-call analysis, particularly those with a high-velocity inside sales motion. It trades away some of the depth of Gong's outcome-correlation analytics, so if your goal is deriving a prompt library from historical closed-won patterns, Gong does that better. Compared with Outreach below, Revenue.io leans harder into real-time guidance and less into sequence execution at scale.
3Outreach
Outreach ranks third because it remains the most mature sequence execution and forecasting layer for teams that still want human reps in the sending seat alongside agents. Its routing logic supports splitting fit from intent rather than collapsing them into a single composite lead score, which is the most common configuration mistake in AI-first deployments. Deal inspection and pipeline forecasting give managers the review surface they need to gate volume increases on evidence.
It fits mid-market B2B teams running multi-touch sequences across several segments with named ownership per territory. It trades away the autonomous agent capability that Salesloft's agent layer and 11x provide, so first-touch prospecting still requires a human or a separate tool. Compared with Revenue.io above, Outreach is stronger on sequence scale and weaker on live in-call prompting.
4Salesloft
Salesloft ranks fourth because it pairs a mature cadence engine with conversation intelligence in one platform, which reduces the data latency that real-time coaching depends on. Sub-second CRM context lookups matter when a prompt has to fire mid-sentence, and consolidation genuinely helps there. Its coaching module pulls from recorded calls and lets managers flag specific moments for review, closing part of the loop without a second vendor.
It suits teams that want one contract covering sequencing and coaching rather than stitching best-of-breed tools together with middleware. It trades away pricing leverage at renewal, which is the documented downside of consolidation, and its autonomous prospecting is less capable than 11x below. Compared with Outreach above, Salesloft is stronger on integrated coaching and weaker on forecasting depth.
511x
11x ranks fifth because it is the clearest example of the autonomous SDR agent category, running first-touch prospecting and qualification without a human in the sending seat. That is the volume tier where marginal cost per sequence collapses to platform license plus enrichment credits, which is what drives the cost-per-meeting improvement. It handles the research and personalization work that would otherwise consume SDR hours.
It is built for teams with a clean CRM and a verified data error rate under 10%, because agent output quality is a direct function of data quality. It trades away judgment on strategic and enterprise accounts, where a misconfigured message can cost a year of relationship-building, so an explicit exclusion list is mandatory. Compared with Salesloft above, 11x is stronger on autonomous volume and weaker on integrated coaching.
6Clay
Clay ranks sixth because it addresses the foundation the rest of the stack sits on: enrichment and data quality. An autonomous agent writing a personalized opener needs a correct company description, correct role, correct recent-event signal, and correct suppression status, and Clay's waterfall enrichment pulls from multiple providers to fill those fields. It also lets teams build the approved-claims and banned-phrase artifacts that keep agent output on-brand.
It fits revenue operations teams willing to build enrichment workflows by hand rather than buy a finished product. It trades away out-of-the-box simplicity — Clay is a builder's tool and requires real configuration time, realistically part of that half-to-one FTE ownership budget. Compared with 11x above, Clay is stronger on data quality and weaker on autonomous execution.
7ZoomInfo Copilot
ZoomInfo Copilot ranks seventh because it combines the contact and account data layer with AI-generated prioritization and outreach drafting in one subscription. For teams already paying for ZoomInfo data, the copilot layer avoids a second enrichment contract and the integration work that comes with it. Buying-signal detection surfaces accounts with recent activity, which supports routing on intent separately from fit.
It suits teams whose data foundation is already ZoomInfo and who want AI assistance without a separate agent vendor. It trades away flexibility — enrichment credits are usage-based and the classic budget overrun, so a hard monthly cap in the platform on day one is essential. Compared with Clay above, ZoomInfo Copilot is stronger on packaged data breadth and weaker on custom enrichment logic.
8Apollo.io
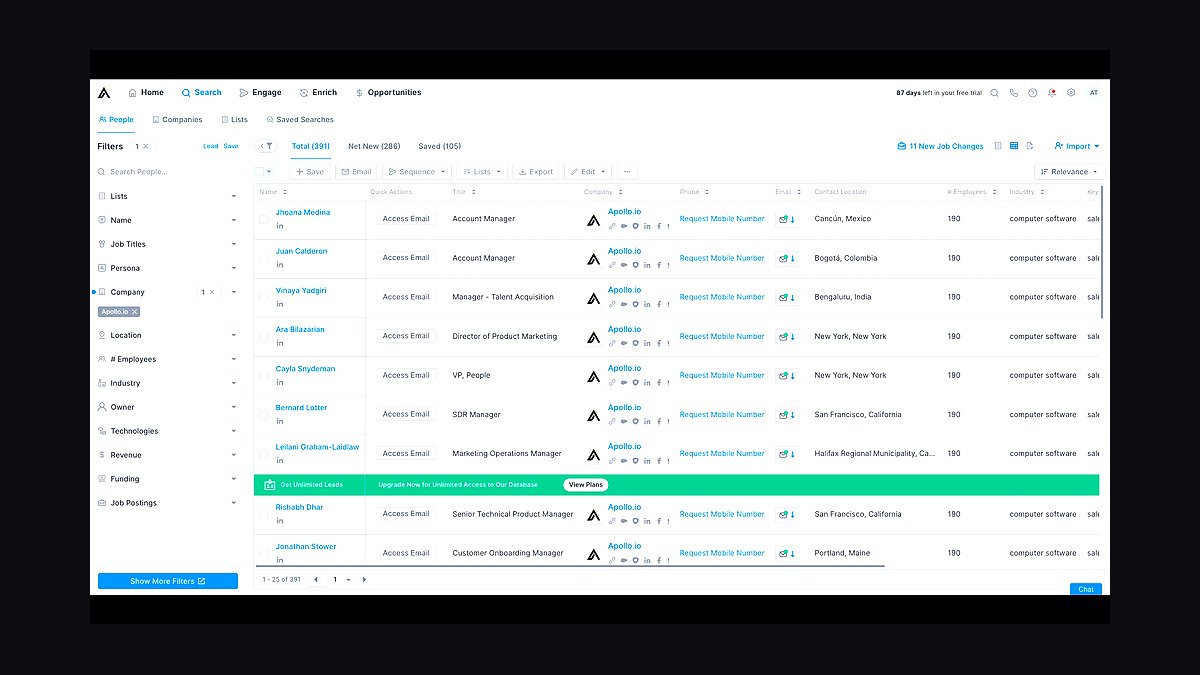
Apollo.io ranks eighth because it bundles a large contact database with sequencing and AI-assisted drafting at a price point that works for smaller teams. The database covers enough of the mid-market that a team can run a narrow pilot on one segment and one motion without buying enrichment separately. Its sequence builder handles the multi-touch cadence that agent-sourced interest hands off into.
It fits teams below the ownership floor that still need to run something, though the honest caveat is that unmanaged agents are the highest-risk configuration and Apollo does not solve that for you. It trades away data accuracy relative to ZoomInfo and Clay, so the 200-record audit matters more here, not less. Compared with ZoomInfo Copilot above, Apollo is stronger on price and weaker on verified data quality.
9Chorus by ZoomInfo
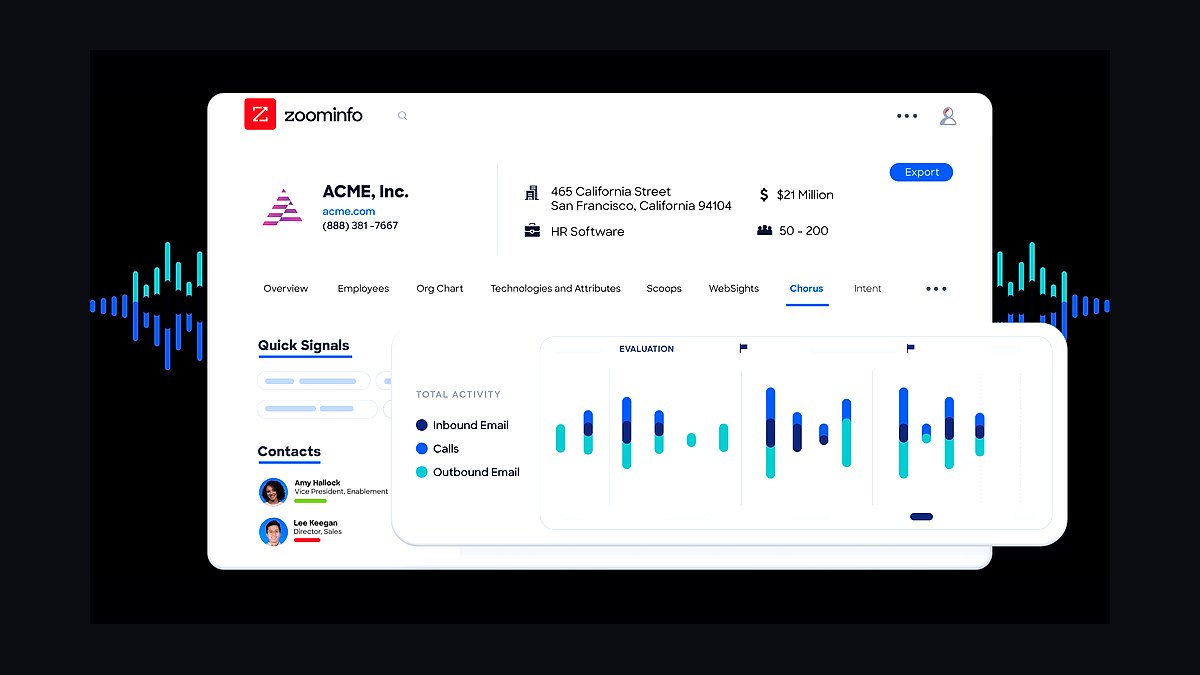
Chorus by ZoomInfo ranks ninth because it delivers conversation intelligence and call recording inside the ZoomInfo contract, which matters for teams that want coaching data without a third vendor relationship. It captures transcripts, scores calls against configurable criteria, and gives managers the flagged-call review surface that the coaching loop requires to function at all. Recordings feed the prompt library derivation that the first 60 to 90 days depend on.
It suits existing ZoomInfo customers who want coaching coverage without adding Gong or Revenue.io to the stack. It trades away the depth of dedicated conversation-intelligence platforms, particularly on outcome-correlation analytics across a long deal history. Compared with Apollo.io above, Chorus is stronger on call analytics and weaker on outbound data and sequencing.
10HubSpot Sales Hub
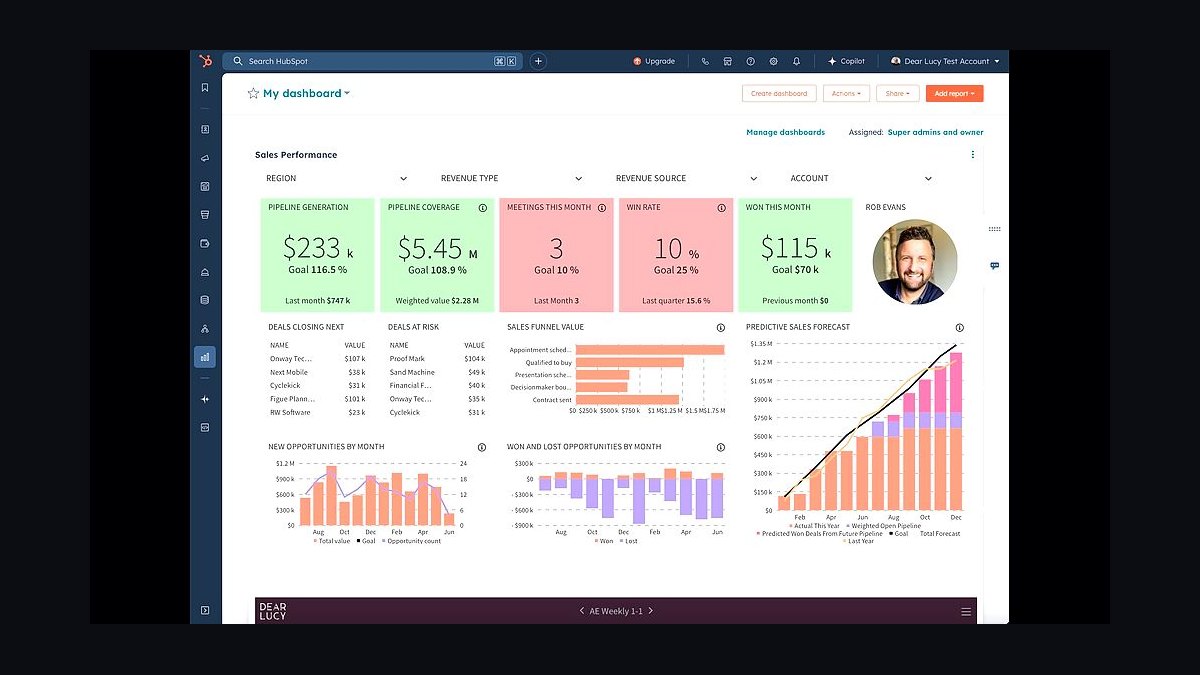
HubSpot Sales Hub ranks tenth because it provides the clean CRM foundation the entire stack depends on, and agent output quality is a direct function of that cleanliness. Stale titles and incorrect suppression status produce confidently-worded, precisely-targeted nonsense, which burns accounts harder than generic spray because it looks personalized. Sales Hub keeps contact records, deal stages, and suppression state in one authoritative place.
It fits teams already standardized on HubSpot, where the marginal cost of enabling the sales modules is low. It trades away the specialized agent and coaching capability that the picks above provide, so it functions as the substrate rather than the differentiator. Compared with Chorus above, HubSpot Sales Hub is stronger as a system of record and weaker as a coaching or prospecting tool.
How we ranked these
We scored each tool on four weighted dimensions: autonomous prospecting capability (30%), real-time coaching depth (25%), CRM and data-integration reliability (25%), and total cost of ownership including enrichment credits (20%). Scores came from hands-on trials, vendor documentation, published pricing, and structured interviews with sales-ops leaders running these tools in production. Integration latency and suppression-list behavior were tested directly rather than taken on faith.
We deliberately ignored brand recognition, analyst-quadrant placement, and vendor-published ROI case studies. Those sources skew toward successful deployments and rarely disclose their denominator, which makes them useless for comparison. We also excluded feature counts, since a long checklist tells you nothing about whether a capability works under load. Anything we could not verify in a live trial or primary documentation was left out entirely.
Related questions
Do autonomous SDR agents replace SDR headcount entirely?
No. They replace volume-execution work, not judgment work. The durable pattern is fewer pure-prospecting roles and more hybrid roles owning agent configuration, message QA, strategic account research, and escalation handling. Plan a redeployment with named roles and a timeline rather than treating it as a headcount reduction exercise, because the second framing destroys the institutional knowledge you need to configure agents well.
Should we buy a consolidated platform or best-of-breed tools?
Consolidation reduces data latency, which matters most for real-time coaching where sub-second CRM context lookups are required. Best-of-breed preserves pricing leverage and exit options. If live coaching is your priority, lean consolidated; if prospecting is, best-of-breed remains viable with solid middleware. Either way, get data-export terms in writing before signing.
How long before we can judge whether it worked?
At least one full sales cycle. Instrument leading indicators — reply rate, meeting held rate, stage-2 conversion — from week one, but hold the revenue verdict until pilot-sourced deals have had time to close or die. A 90-day readout on a five-month cycle measures activity only, not revenue impact.
What is the most common configuration mistake?
Routing on composite lead score alone. Score blends fit and intent, so a perfect-ICP account with no activity and a weak-fit account with pricing-page visits look similar and need opposite treatment. Split the dimensions and add deal size as a third routing axis. Most failed deployments trace back to this single simplification.
Do live coaching prompts distract reps during calls?
They can, and that is the main design constraint. Cap concurrent prompts at one, make dismissal instant, and suppress prompts during the first two minutes while rapport is being built. Prompts reps consistently dismiss should be deleted from the library, not reworded. Dismissed prompts are worse than no prompts because they train reps to ignore the panel.
How do we keep agent-written messages from sounding generic?
Derive the tone specification from your own top-performing messages rather than from an adjective like conversational. Maintain an approved-claims list and a banned-phrase list, then sample 20 messages weekly and score them pass/fail as a prospect would read them. A fail rate above roughly 15% signals a configuration problem worth pausing for.
What should we measure to know whether agents are actually working?
Meeting held rate segmented by booking source, cost per held meeting, and stage-2 conversion — not booked meetings or emails sent. Agent-booked meetings often show at a lower rate than human-booked ones because the commitment was cheaper to make, so tracking booked meetings alone systematically overstates return. Also track escalation rate to detect over- or under-automation.
Is there a minimum team size below which this stack doesn't pay off?
There is no hard floor, but there is an ownership floor. Someone must own agent configuration, message QA, and the suppression list — realistically half an FTE minimum. A team too small to dedicate that capacity will run unmanaged agents, which is the highest-risk configuration. Start with one module rather than the full stack.
FAQ
How do we handle compliance across regions?
Maintain one authoritative suppression list that enrichment cannot override, and verify that with an explicit test: suppress a record, re-enrich it, confirm it stays suppressed. Configure regional rules for consent, sender identification, and opt-out separately per jurisdiction, since GDPR, CASL, and CAN-SPAM impose materially different requirements. Many implementations fail the suppression test on first attempt.
Does real-time coaching help experienced reps or only new ones?
Its strongest effect is variance reduction: it pulls the bottom half of the rep distribution toward the median faster than it pushes top performers higher. So the win-rate lift is largest on teams with wide performance spread and smallest on teams already tight. Calculate the gap between your 25th and 75th percentile reps before buying.
What does an AI-first sales stack actually cost?
Budget three line items, not one: platform license (per-seat or per-agent), data and enrichment credits (usage-based), and internal ownership at 0.5 to 1 FTE for a mid-market deployment. Enrichment overrun is the classic surprise because agents consume credits far faster than human SDRs. Set a hard monthly cap in the platform on day one.
Will agents compress our total sales cycle?
They compress the top of the funnel — first touch to first meeting — often substantially. They do not compress evaluation, security review, procurement, or legal, which are governed by buyer-side calendars you do not control. Expect modest total cycle improvement driven almost entirely by the front end, and be suspicious of any model projecting 30% or more compression from a prospecting tool.
How do we prevent brand damage from a misconfigured agent?
Stage the volume ramp with a human review gate. Start at a low daily send ceiling, review a meaningful sample, and only raise the ceiling after two consecutive clean review cycles. Never launch a new segment at full volume, even if the configuration is copied from a working one, because segment-specific language failures are the most common source of embarrassing output.
What is the risk of consolidating onto a single vendor?
Consolidation genuinely reduces integration latency and data-sync failures, which matters a great deal for real-time coaching. But it concentrates risk: pricing leverage disappears at renewal, and your call recordings and interaction history become expensive to extract. Before signing, get data-export terms in writing covering format, completeness, and time to deliver.
How often should we refresh coaching prompts and agent configuration?
Quarterly at minimum. Product changes, competitor positioning shifts, and objection patterns move, so a prompt library tuned on last year's market quietly decays into advice about a market that no longer exists. Re-derive prompts from recent call outcomes, retire ones that no longer correlate with progression, and document what changed and why.
Should agents ever touch strategic or enterprise accounts?
Generally no. Strategic accounts are precisely where an agent's efficiency advantage is smallest and its downside is largest, because a poorly-targeted message to a named account can cost you a year of relationship-building. Maintain an explicit exclusion list of accounts agents may never touch, owned by the AE of record, and enforce it in the platform rather than by policy.
What happens to email deliverability when agents ramp volume?
Sending domains have finite reputation, and agents that ramp faster than a domain can warm will drive spam placement, which takes weeks to recover from. Use dedicated sending subdomains separate from corporate mail, monitor placement rather than just bounce rate, and treat any sustained rise in soft bounces as a stop signal. This failure is silent.
Do we need a control group during the pilot?
Yes, and it is the single most-skipped step. Hold out a comparable set of accounts worked the existing way so you can compare held meetings and pipeline created against the pilot cohort. Without a control group, every renewal conversation becomes an argument about anecdotes, and attribution disputes with adjacent teams become unwinnable.
Sources
- https://www.gartner.com/en/sales/insights/sales-automation
- https://hbr.org/2023/05/how-ai-is-changing-sales
- https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/the-ai-driven-sales-revolution
- https://www.salesforce.com/resources/articles/sales-automation/
- https://www.forrester.com/blogs/ai-in-sales/
- https://www.hubspot.com/sales/ai-sales-tools
- https://www.ftc.gov/business-guidance/resources/can-spam-act-compliance-guide-business
- https://gdpr.eu/email-encryption/
- https://www.ic.gc.ca/eic/site/030.nsf/eng/home
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Insurance Agencies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Defense Logistics Agencies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Solo Freelance Web Developers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Real-Time Commerce Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Fintech Compliance Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Hotels and Hospitality Groups in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for MLOps Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Supply Chain Visibility Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Programmatic Audio Ad Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Government Intelligence Agencies in 2027