


Top 10 Best Tech Stack Tools for MLOps Teams in 2027
Quality
Certified
The 10 best tech stack tools for mlops teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1MLflow by Databricks
MLflow ranks first because it became the de facto model registry for 2027 RevOps MLOps stacks, handling versioning, experiment tracking, and deployment metadata. Its native Salesforce and HubSpot connectors sync accuracy, drift status, and retraining history directly to CRM dashboards. Versioned deployments allow any model to roll back within 2 minutes, and shadow deployment is mandatory before promotion.
It suits teams that treat the registry as the central nervous system connecting data science to revenue operations. The trade-off is operational overhead: MLflow assumes you already run Kubernetes, a serving layer, and a feature store. Compared with Seldon Core directly below, MLflow governs the model lifecycle while Seldon handles the sub-50ms inference traffic.
2Seldon Core
Seldon Core ranks second because it dominates high-throughput model serving in 2027, using inference graphs that chain multiple models while holding total latency under 50ms. It supports shadow, canary, and A/B deployment patterns natively, routing 5% of traffic by rep ID or region before ramping to 100%. Rollback triggers fire on a 5% accuracy drop or 10% latency increase within a one-hour window.
It is built for platform engineers serving real-time lead scoring and next-best-action models at scale. The trade-off is complexity: Seldon Core demands Kubernetes expertise and offers less hand-holding than DataRobot. Compared with MLflow above, Seldon owns the serving path while MLflow owns registry and metadata.
3DataRobot MLOps
DataRobot MLOps ranks third because it gives non-technical RevOps teams out-of-the-box drift detection, retraining scheduling, and AutoML that tests algorithm variants each cycle against business KPIs like win rate and average deal size. It ingests call transcripts as features and provides a managed alternative that removes Kubernetes and feature-store operations from the critical path.
It suits small RevOps teams of 5-10 people where only one person understands MLflow and Salesforce APIs. The trade-off is vendor lock-in and licensing cost compared with open-source cores. Compared with Seldon Core above, DataRobot trades fine-grained serving control for faster time-to-production.
4Kubeflow
Kubeflow ranks fourth because it remains the orchestrator for custom retraining pipelines in 2027, running on Amazon EKS or Google GKE with GPU support for transformer-based models. It executes the automated retraining triggered when a Kolmogorov-Smirnov statistic exceeds 0.15, and it chains feature engineering, training, validation, and shadow deployment into repeatable pipeline steps.
It is for enterprises needing fine-grained control over every pipeline stage rather than managed abstraction. The trade-off is significant engineering investment and ongoing maintenance burden. Compared with DataRobot MLOps above, Kubeflow offers flexibility at the cost of operational simplicity, making it a poor fit for teams without dedicated platform staff.
5WhyLabs
WhyLabs ranks fifth because it provides the observability layer that catches model failure within 5 minutes, monitoring feature and prediction distributions in real time. Its dashboards track accuracy, latency, and data quality, and it integrates with PagerDuty so the RevOps team receives alerts with model ID and drift metrics attached. Drift beyond two standard deviations triggers shadow deployment for 24 hours.
It is for teams that already have serving and registry layers but lack statistical monitoring depth. The trade-off is that WhyLabs observes rather than fixes: it depends on Kubeflow or DataRobot for retraining. Compared with Arize AI below, both cover similar drift-detection ground, and the choice usually comes down to existing integrations.
6Arize AI
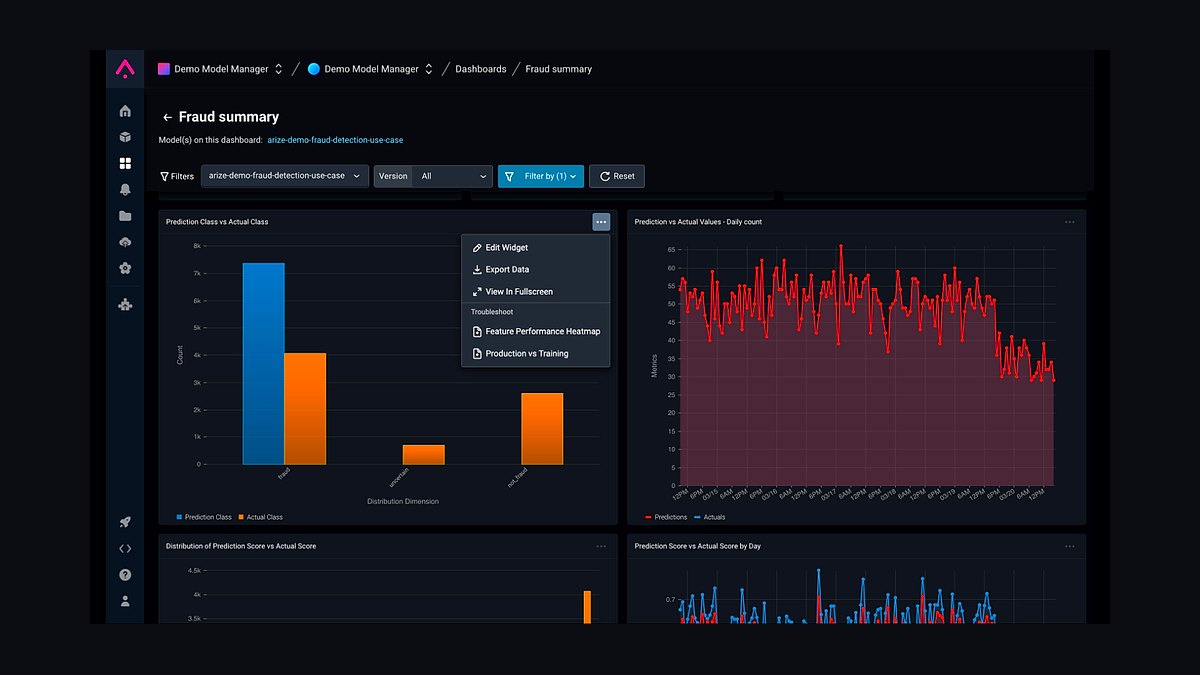
Arize AI ranks sixth because it delivers real-time model monitoring with drift thresholds that trigger automated retraining pipelines, covering both feature distributions and prediction distributions. It surfaces accuracy degradation and data quality issues through dashboards that plug into PagerDuty for automated incident response, matching the observability requirements of 2027 RevOps stacks running 40-60 production models.
It is for data science teams that want monitoring without building custom statistical tooling. The trade-off is overlap with WhyLabs above, so running both is redundant for most enterprises. Compared with WhyLabs, Arize differentiates mainly through integration fit and pricing rather than core capability.
7Feast Feature Store
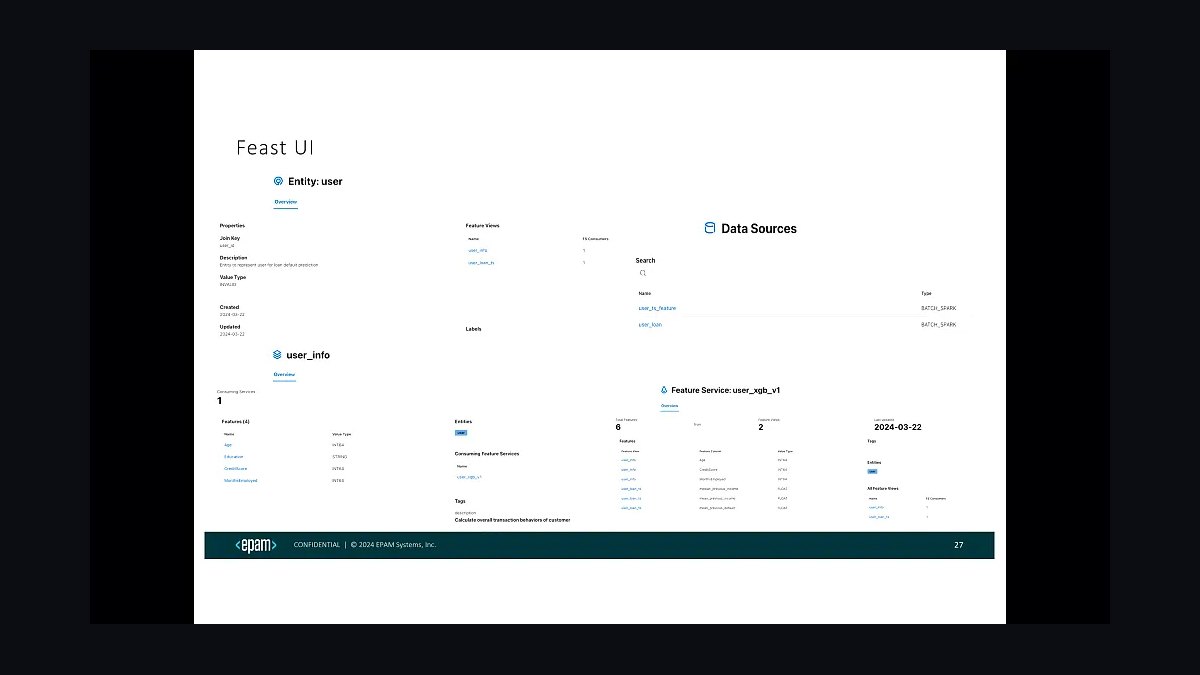
Feast ranks seventh because a feature store became a minimum infrastructure requirement for 2027 MLOps, keeping training and serving features consistent so real-time lead scoring does not silently diverge from offline training data. It serves features to the inference gateway with low latency and prevents the training-serving skew that causes false positives in production scoring models.
It is for teams running multiple models that share engineered features across lead scoring, churn, and next-best-action use cases. The trade-off is added infrastructure to operate and monitor. Compared with Tecton below, Feast is open source and self-managed, which suits platform teams but raises operational burden.
8Tecton
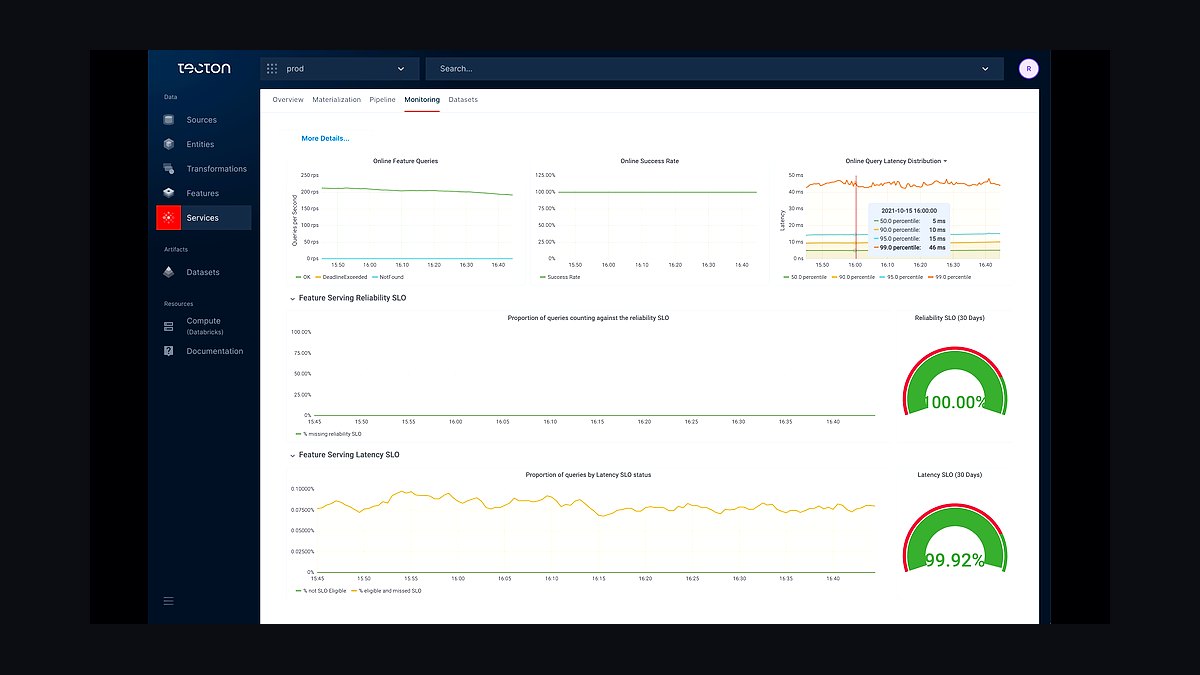
Tecton ranks eighth because it offers a managed feature platform that reduces the operational load of running a feature store alongside MLflow, Seldon Core, and Kubeflow. It handles feature freshness and consistency for real-time RevOps models where lead scoring retrains every 4-8 hours and next-best-action models every 2-4 hours.
It is for teams that want feature-store capability without dedicating engineers to operating Feast. The trade-off is commercial licensing and platform dependency. Compared with Feast above, Tecton trades cost and control for reduced maintenance, which matters most for smaller platform teams.
9River
River ranks ninth because online learning remains the practical fix for data drift, where input distributions shift but the feature-outcome relationship holds. It updates models incrementally without a full retrain, complementing the concept-drift path that requires Kubeflow or DataRobot to rebuild with new data. This keeps lead scoring models current between scheduled retraining cycles.
It is for teams whose drift monitors show input distribution shifts rather than concept change. The trade-off is narrower scope: River does not replace a registry, serving layer, or monitoring platform. Compared with Vowpal Wabbit below, both address incremental learning, and selection depends on language ecosystem and team familiarity.
10Vowpal Wabbit
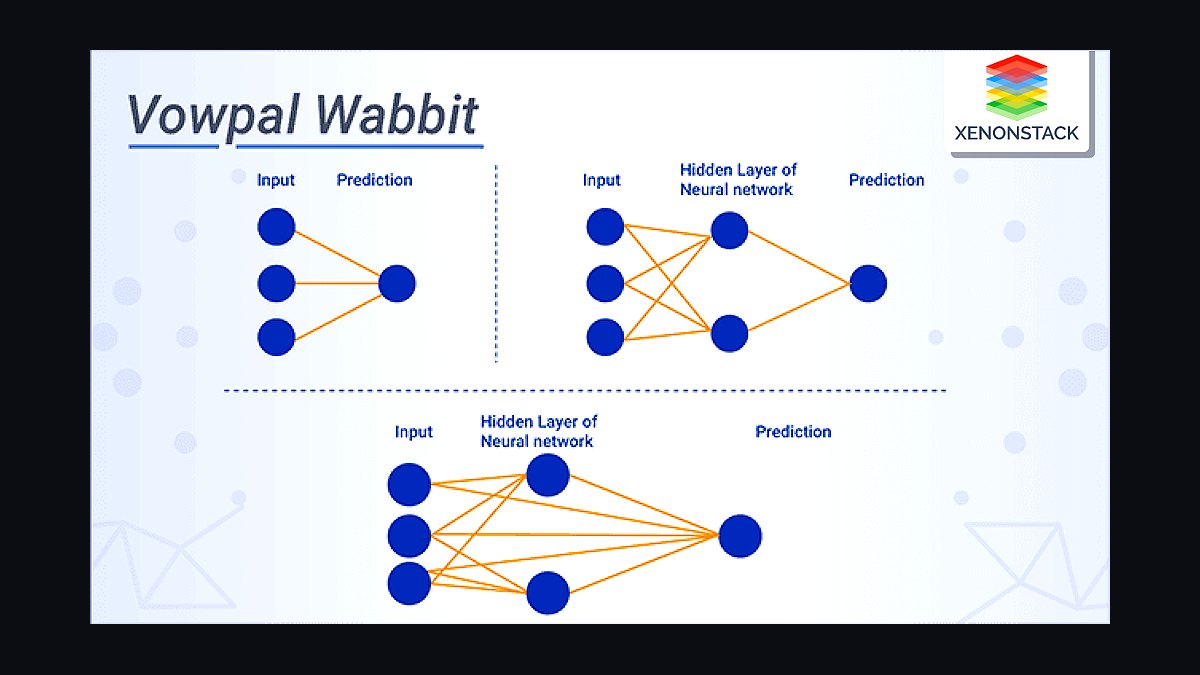
Vowpal Wabbit ranks tenth because it provides fast online learning for streaming RevOps signals, updating models as sales outcomes arrive rather than waiting for the next scheduled retrain. It fits the 2027 pattern where every win, loss, or churn becomes a training signal that improves accuracy within hours instead of weeks.
It is for teams with streaming infrastructure and engineers comfortable with command-line tooling. The trade-off is a steep learning curve and minimal managed tooling compared with DataRobot. Compared with River above, Vowpal Wabbit scales further on high-volume streams but demands more specialized expertise.
How we ranked these
We ranked tools on five weighted criteria: real-time inference latency under 50ms, native Salesforce and HubSpot bidirectional sync, automated drift detection with retraining triggers, deployment safety features like shadow and canary rollouts, and total cost of ownership across a 40–60 model fleet. Model registry maturity, rollback speed under two minutes, and observability integration with PagerDuty carried secondary weight.
We deliberately ignored vendor brand prestige, Gartner Magic Quadrant placement, and analyst report positioning, because consolidation between 2025 and 2027 invalidated much legacy scoring. We also excluded notebook ergonomics and experimentation UI polish, since production RevOps teams care about inference reliability and CRM write-back, not data scientist comfort. Pricing list rates were ignored because negotiated enterprise contracts vary by 40–60%.
Related questions
What is the minimum infrastructure needed for MLOps in 2027?
A Kubernetes cluster on EKS or GKE, MLflow for the model registry, Seldon Core for serving, and a feature store like Feast or Tecton form the baseline. Small teams can substitute DataRobot's managed platform to cut operational overhead. Budget for GPU compute and licensing that scales with inference volume and model count.
How do you handle model drift in real-time RevOps models?
Deploy WhyLabs or Arize AI to monitor feature and prediction distributions continuously. Set thresholds, such as a Kolmogorov-Smirnov statistic above 0.15, that trigger automated retraining through Kubeflow or DataRobot. Models drifting beyond two standard deviations get shadow-deployed for 24 hours before any production promotion.
Can small RevOps teams manage MLOps in 2027?
Yes, but only with managed services like DataRobot MLOps or Seldon Deploy that abstract infrastructure away. You need one person fluent in MLflow and Salesforce APIs; the rest can focus on feature engineering and business validation. This structure delivers enterprise-grade capability without a dedicated platform team.
What is the typical retraining frequency for RevOps models?
Lead scoring models retrain every four to eight hours using online learning. Churn models retrain daily, while next-best-action models retrain every two to four hours. Drift monitors override these schedules when feature distributions or accuracy shift faster than the baseline cadence expects.
How do you measure MLOps ROI for the board?
Track three metrics: lead-to-opportunity conversion lift targeting 15%, sales cycle reduction targeting 20%, and false-positive lead decrease targeting 30%. Present them as annualized revenue impact. For a $50M ARR company, a 15% conversion lift translates to roughly $7.5M in added pipeline.
What happens if a model fails in production?
The drift monitor detects failure within five minutes, and the inference gateway automatically rolls back to the prior version. RevOps receives a PagerDuty alert with model ID and drift diagnostics. The failed model is shadow-deployed for debugging while production traffic continues on the stable version.
How does MLOps integrate with existing sales workflows?
Platforms write predictions directly to CRM custom objects, updating lead, opportunity, and contact health scores in real time. Reps see scores inside Salesforce or HubSpot without opening separate tools. This seamless write-back ensures model insights get acted on immediately rather than ignored.
What skills does a RevOps team need for MLOps in 2027?
The team needs MLflow registry management, Salesforce API fluency, and working knowledge of drift monitoring concepts. Managed platforms remove the need for deep data science expertise, letting RevOps professionals concentrate on feature engineering, business validation, and translating model output into pipeline outcomes.
FAQ
Which MLOps tools survived the 2025–2027 vendor consolidation?
MLflow, Seldon Core, DataRobot, Kubeflow, WhyLabs, and Arize AI emerged as survivors. Each supports real-time inference, native CRM integration, and automated drift detection. Point solutions lacking those three capabilities were acquired or shut down as enterprises standardized on platforms that could serve 40–60 production models reliably.
Why did MLOps become a core RevOps function rather than a data science concern?
Real-time scoring now influences every customer interaction, from lead routing to next-best-action recommendations. Batch predictions went obsolete as market dynamics accelerated. Companies running real-time pipelines report 30–50% higher conversion rates, making MLOps a revenue capability rather than a back-office experiment.
What deployment patterns ensure safe model rollouts?
Shadow deployments log predictions for 24–72 hours without affecting outcomes and are mandatory for CRM-touching models. Canary deployments route 5% of traffic by rep or region, ramping to 100% after a 5% improvement holds for 48 hours. A/B tests run one to two weeks for next-best-action models.
How does the 2027 stack integrate with Salesforce and HubSpot?
MLflow ships native connectors that sync model performance metrics into CRM dashboards. The inference gateway writes predictions to custom objects in real time as events stream from web analytics, email engagement, and call transcripts. Feedback loops run every four hours, converting outcomes into fresh training labels.
What decision framework separates retraining from rebuilding?
Concept drift, where feature-outcome relationships change, demands a full retrain on new data. Data drift, where input distributions shift, often resolves with online learning updates via River or Vowpal Wabbit. A Kolmogorov-Smirnov statistic above 0.15 typically triggers automated retraining.
How does MEDDICC apply to MLOps purchases?
MLOps deals average seven stakeholders across RevOps, data science, IT, and finance. Metrics target 20% sales cycle reduction and 15% conversion lift. The economic buyer is usually the VP of RevOps or CRO. Proof of concept runs four to six weeks on three to five models before pilot expansion.
What latency and retraining benchmarks define a competitive 2027 stack?
Deployment latency should stay under 50ms for real-time scoring. Retraining cycles are measured in hours, not weeks, with lead scoring refreshing every four to eight hours. Rollback must complete within two minutes when accuracy drops 5% or latency rises 10% over a one-hour window.
What rollback triggers protect production revenue models?
A 5% accuracy drop or 10% latency increase sustained over one hour triggers automatic rollback. Versioned deployments in MLflow let any model revert to a prior version within two minutes. This keeps problems from cascading into pipeline damage before humans intervene.
How many production models does the average enterprise run in RevOps?
Enterprises now run 40–60 production models across RevOps alone, spanning lead scoring, churn prediction, next-best-action, and predictive routing. That volume makes manual model management impossible, which is why automated drift detection, retraining, and rollback became table-stakes requirements rather than differentiators.
What is the biggest mistake buyers make when selecting MLOps tools?
Buyers optimize for experimentation features and notebook ergonomics while ignoring inference latency, CRM write-back reliability, and rollback speed. Those three determine whether models actually influence revenue. A polished training UI means nothing if predictions arrive 500ms late or never reach the Salesforce object reps actually see.
Sources
- https://mlflow.org/docs/latest/model-registry.html
- https://www.datarobot.com/solutions/revenue-operations-mlops/
- https://www.seldon.io/solutions/sales-marketing-mlops
- https://whylabs.ai/docs/drift-detection
- https://www.gong.io/labs/real-time-models-sales-rep-performance/
- https://www.mckinsey.com/capabilities/quantumblack/our-insights/scaling-ai-in-revenue-operations
- https://www.bvp.com/atlas/the-2027-cloud-stack-for-ai-native-enterprises
- https://www.forrester.com/report/the-state-of-ai-deployment-in-sales-and-marketing-2027
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Green Energy Grid Operators in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Recruiting and Staffing Firms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Short-Form Video Content Studios in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Outbound Sales and SDR Teams in 2027
 tkTop 10 Best Tech Stack Tools for First-Time Business Owners in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Data Observability Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Luxury Hotels and Concierge Services in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Property Managers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Online Marketplace Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Nonprofit Operations Teams in 2027