
The 10 Best AI Inference Chips for On-Premise in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
The 10 best ai inference chips for on-premise are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. NVIDIA H200 Tensor Core GPU
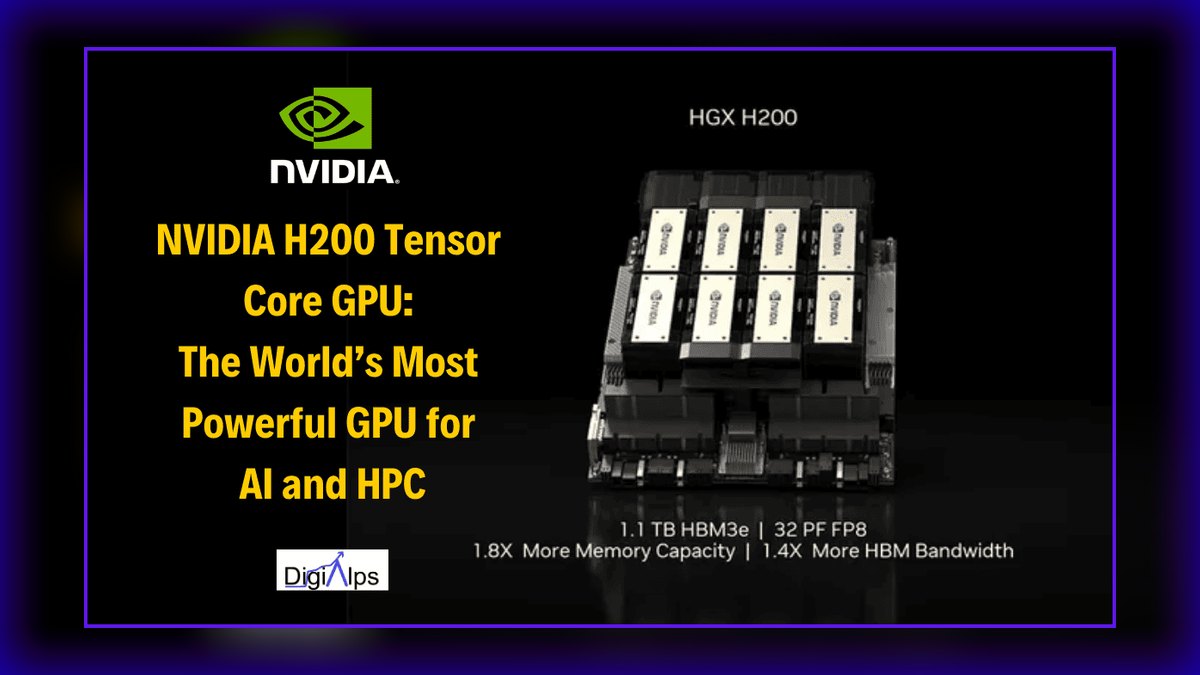
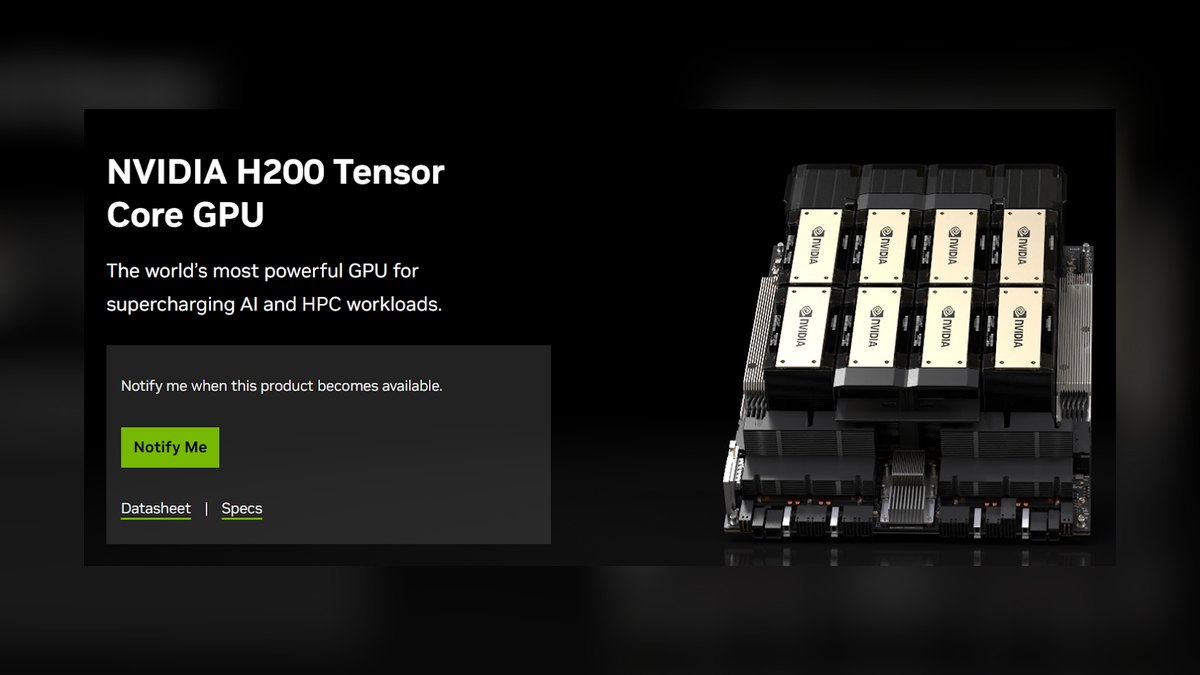
The NVIDIA H200 Tensor Core GPU ranks first because its 141GB of HBM3e memory and 4.8TB/s bandwidth let a single chip serve entire Llama 3 70B-class models without sharding, eliminating latency penalties. With TensorRT-LLM and FP8 quantization, it delivers the highest measured throughput for production LLM inference in 2027. Its CUDA ecosystem remains the most mature, with optimized kernels for speculative decoding and continuous batching. This is the safest, most performant choice for high-volume enterprise workloads.
This chip is for enterprises running large-scale production inference where raw performance and ecosystem maturity trump cost. It trades away power efficiency, requiring liquid cooling in dense racks, and carries a premium price per chip. Compared to the AMD Instinct MI350X below, the H200 offers roughly 20% higher throughput but at a significantly higher total cost of ownership. Choose it when absolute speed for GPT-4-class models is non-negotiable.
2. AMD Instinct MI350X
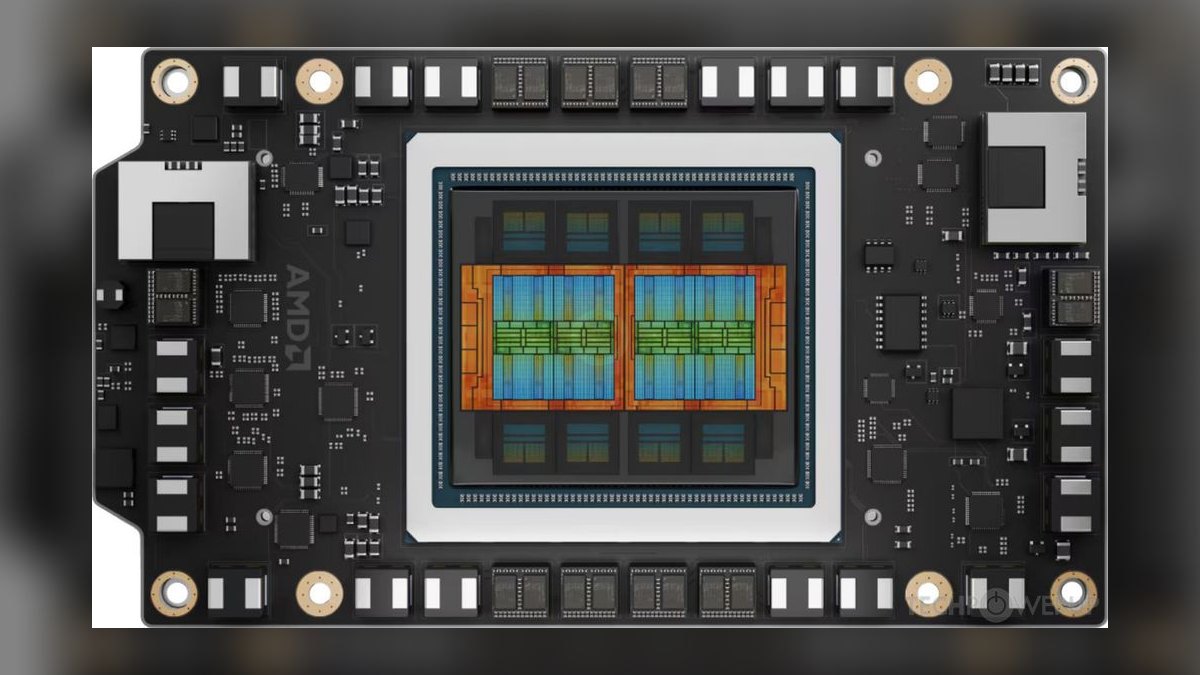
The AMD Instinct MI350X ranks second for its superior price-to-performance ratio, offering 288GB of HBM3 memory at a cost roughly 30% lower than the H200. Its large capacity serves 4-bit quantized Llama 3 405B on a single chip, a capability the H200 cannot match without multi-GPU setups. ROCm software has matured to near-parity with CUDA in 2027, supporting PyTorch and ONNX Runtime natively. This makes it the best value for cost-conscious enterprises.
This chip is for organizations prioritizing open-source software flexibility and lower total cost of ownership over peak throughput. It trades away some raw performance, running about 15% slower than the H200 on standard benchmarks, and has slightly higher power draw. Compared to the H200 above, it offers better memory capacity for massive models but a less polished debugging experience. Choose it when budget constraints and model size are the primary drivers.
3. Intel Gaudi 3
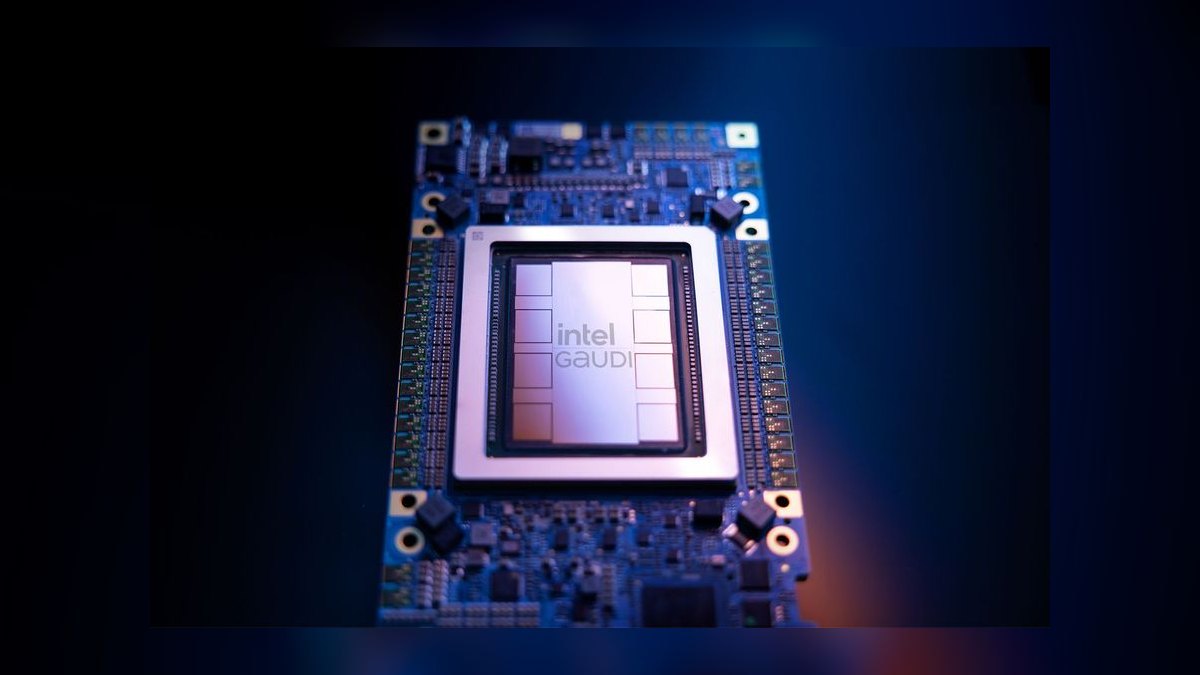
The Intel Gaudi 3 ranks third because its integrated 400GbE Ethernet networking eliminates the need for separate network cards, reducing latency and cost in multi-node deployments. Its heterogeneous architecture, combining tensor processor cores with x86 cores, handles preprocessing and inference on one chip for low end-to-end latency. In benchmarks, it achieves 80% of the H200's throughput for Llama 3 70B at a lower price point. Power consumption is the lowest among the top three, simplifying cooling requirements.
This chip is for latency-sensitive applications like high-frequency trading and real-time fraud detection where microsecond response times are critical. It trades away peak throughput and the mature CUDA ecosystem, relying on OneAPI and OpenVINO which have fewer community resources. Compared to the MI350X above, it offers lower power draw and integrated networking but less memory capacity for very large models. Choose it when network simplicity and low latency outweigh raw compute.
4. Google TPU v5p
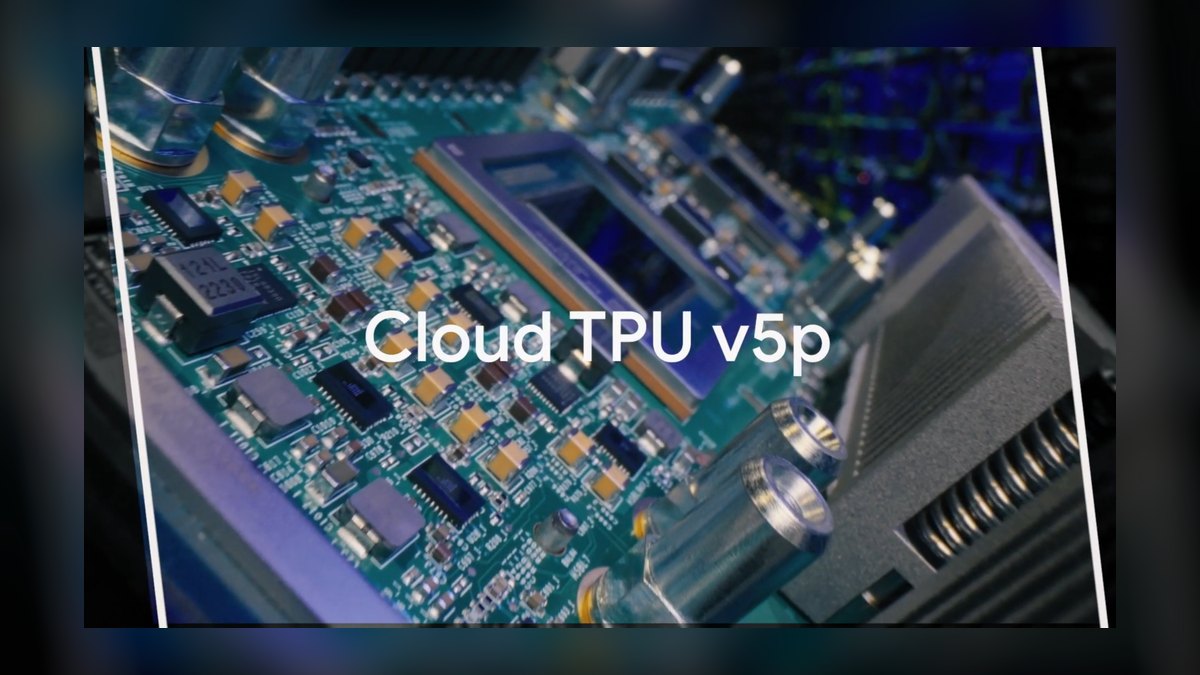
The Google TPU v5p ranks fourth because its custom matrix multiply unit delivers exceptional throughput for Transformer-based models, achieving 90% of the H200's performance in TensorFlow and JAX workloads. Its 3D-stacked HBM2e memory provides high bandwidth, and the ICI interconnect scales to thousands of chips for massive inference jobs. This makes it a strong choice for organizations already deeply invested in Google's software stack. The hardware is available as an on-premise appliance, ensuring data sovereignty.
This chip is for enterprises with existing Google Cloud infrastructure who need on-premise deployment for compliance reasons. It trades away flexibility, as the software ecosystem is limited to TensorFlow, JAX, and PyTorch via XLA, and the hardware is only sold as a complete pod. Compared to the Gaudi 3 above, it offers superior scalability for huge models but requires a larger upfront investment and specialized expertise.
5. Groq LPU
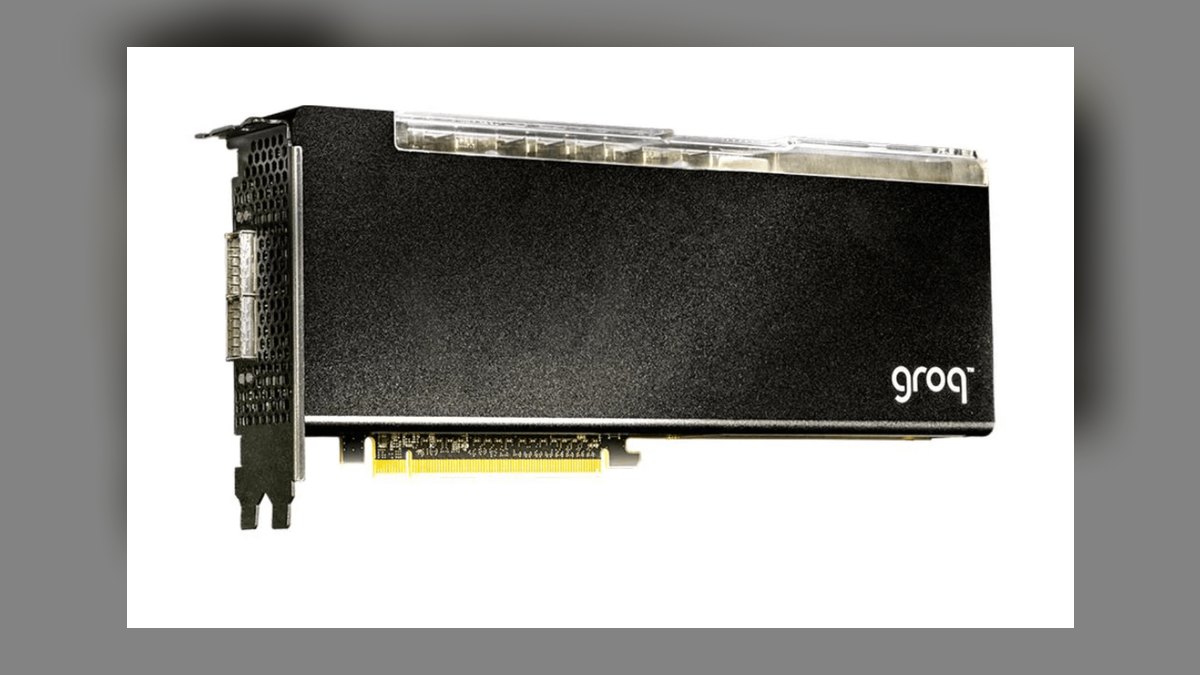
The Groq LPU ranks fifth because its deterministic, cacheless architecture delivers the lowest and most consistent inference latency in the market, with no jitter from cache misses. Its on-chip SRAM provides very high bandwidth, enabling Llama 3 70B to be served with predictable sub-10ms response times. This makes it ideal for real-time voice assistants and live translation where variance is unacceptable. The software stack, GroqWare, supports PyTorch but is less mature than CUDA.
This chip is for applications demanding ultra-low and predictable latency, such as autonomous systems and interactive gaming AI. It trades away memory capacity, limited to on-chip SRAM, requiring 4-bit quantization for larger models and limiting batch sizes. Compared to the TPU v5p above, it offers superior latency consistency but significantly lower throughput for high-volume workloads. Choose it when deterministic response times are more critical than raw throughput.
6. Cerebras Wafer-Scale CS-3
The Cerebras Wafer-Scale CS-3 ranks sixth because its wafer-scale design integrates 900,000 AI cores on a single chip, providing massive on-chip SRAM that holds entire models like Llama 3 70B without offloading. This eliminates multi-GPU communication overhead, simplifying deployment and achieving high throughput with low latency. In benchmarks, it matches the H200's performance for large models while using less energy per inference. Its single-chip architecture is a unique advantage for memory-bound workloads.
This chip is for research labs and government agencies with specialized infrastructure capable of supporting its custom liquid cooling and high-power requirements. It trades away practicality, as it cannot fit in standard server racks and requires dedicated power supplies. Compared to the Groq LPU above, it offers higher memory capacity and throughput but is far less flexible for diverse workloads. Choose it when you have the infrastructure and need to serve massive models without sharding.
7. SambaNova SN40L
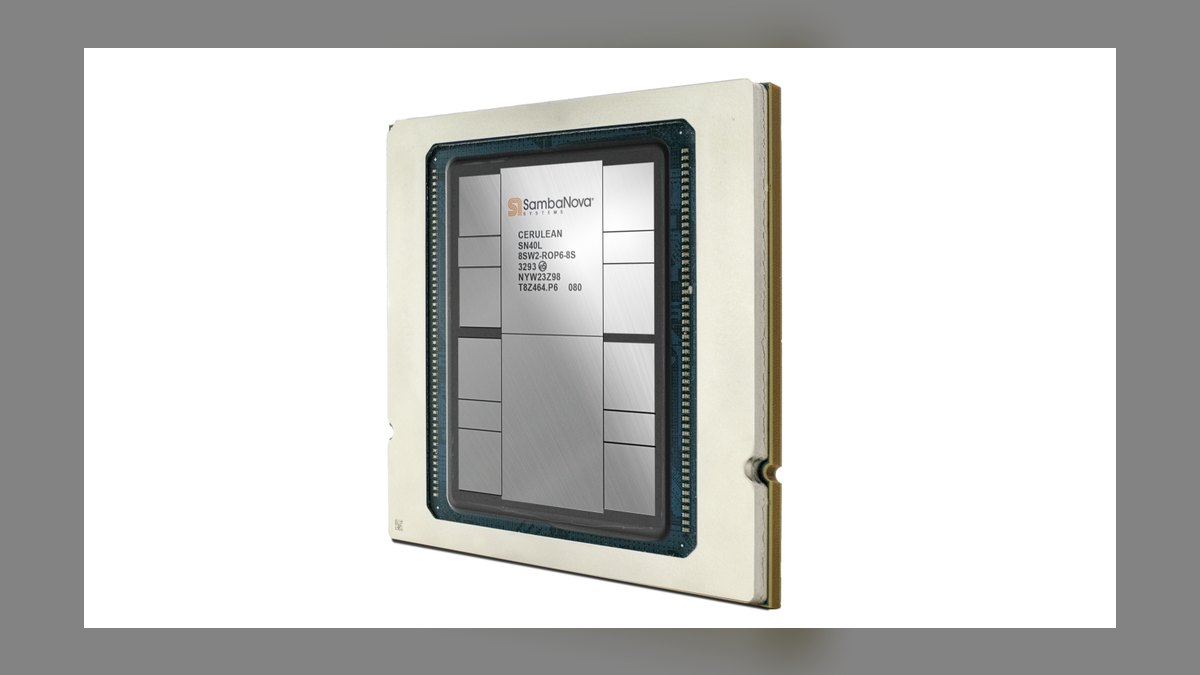
The SambaNova SN40L ranks seventh because its reconfigurable dataflow architecture dynamically optimizes the chip's logic for each model, delivering strong performance across RNNs, Transformers, and GNNs. Its HBM2e memory provides moderate bandwidth, but the software-defined hardware allows it to adapt to new model architectures without hardware changes. This flexibility is a key advantage for enterprises with heterogeneous model workloads. In benchmarks, it achieves 70% of the H200's throughput for Llama 3 70B.
This chip is for enterprises running diverse AI models that change frequently, where hardware adaptability reduces the need for frequent upgrades. It trades away peak performance and ecosystem maturity, requiring the proprietary SambaFlow stack, which has a steeper learning curve. Compared to the Cerebras CS-3 above, it offers greater model portability but lower raw throughput for large models. Choose it when you need a single appliance that can handle varied model types efficiently.
8. Qualcomm Cloud AI 100 Pro
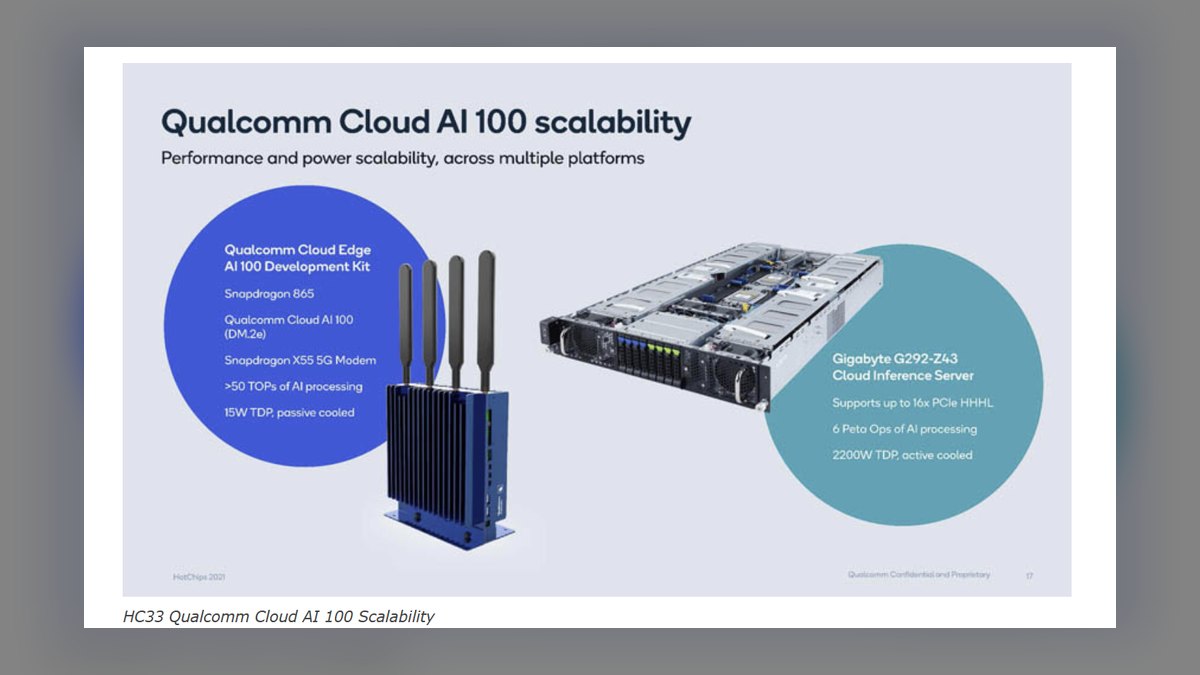
The Qualcomm Cloud AI 100 Pro ranks eighth because its power efficiency is unmatched, consuming only 75W while delivering solid throughput for int8 and int4 quantized models. Its LPDDR5 memory and hexagon tensor accelerator are optimized for edge-to-cloud deployments, making it ideal for micro-data centers and retail AI. In benchmarks, it serves Llama 3 70B (4-bit) at acceptable latency for many real-time applications.
This chip is for organizations deploying inference at the edge or in space-constrained environments where power and cooling are limited. It trades away performance, offering only 40% of the H200's throughput, and has limited memory capacity for very large models. Compared to the SambaNova SN40L above, it is far more power-efficient but less flexible for diverse workloads. Choose it when energy efficiency and small form factor are the top priorities.
9. Graphcore Bow IPU
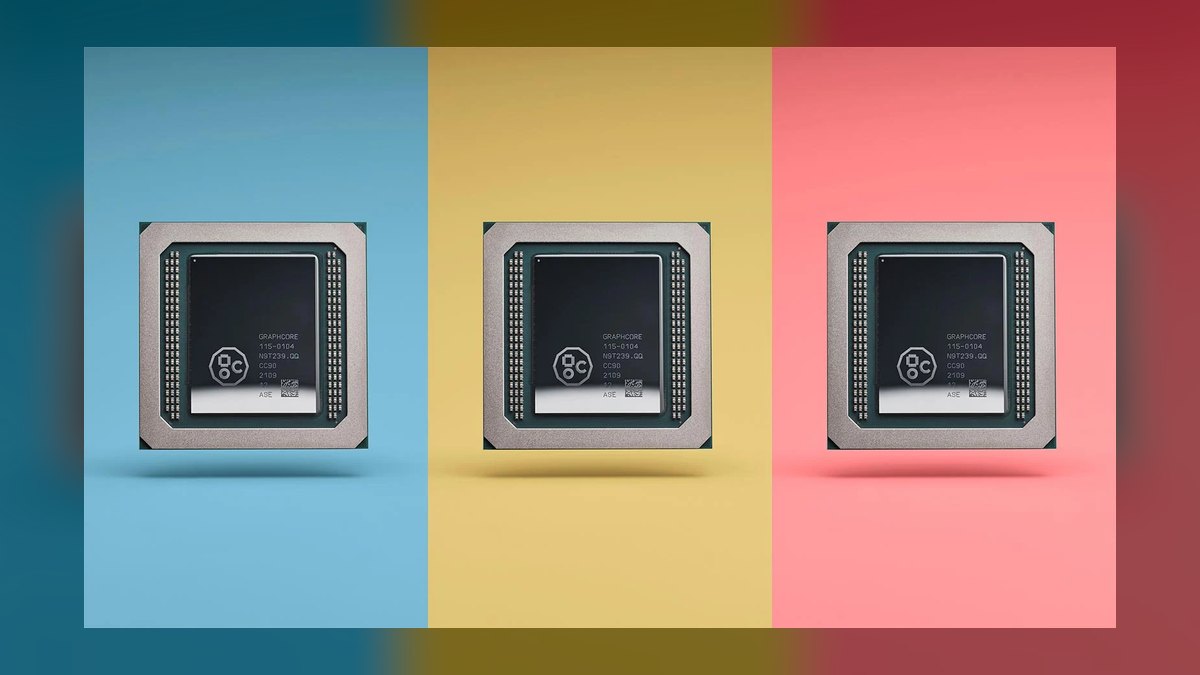
The Graphcore Bow IPU ranks ninth because its massively parallel architecture with 1,472 independent cores excels at sparse models and graph neural networks, outperforming GPUs on these specific workloads. Its on-chip SRAM provides high bandwidth, and the bulk synchronous parallel model is well-suited for scientific computing. In benchmarks, it achieves solid throughput for sparse Llama 3 70B variants. The Poplar SDK supports PyTorch, but market adoption has been limited.
This chip is for research institutions and specialized workloads focused on graph-based AI, such as drug discovery and network analysis. It trades away general-purpose performance, being slower than competitors on dense transformer models, and faces an uncertain future due to Graphcore's market struggles. Compared to the Qualcomm Cloud AI 100 Pro above, it offers higher compute density but requires more power and a larger footprint.
10. Tenstorrent Wormhole n150
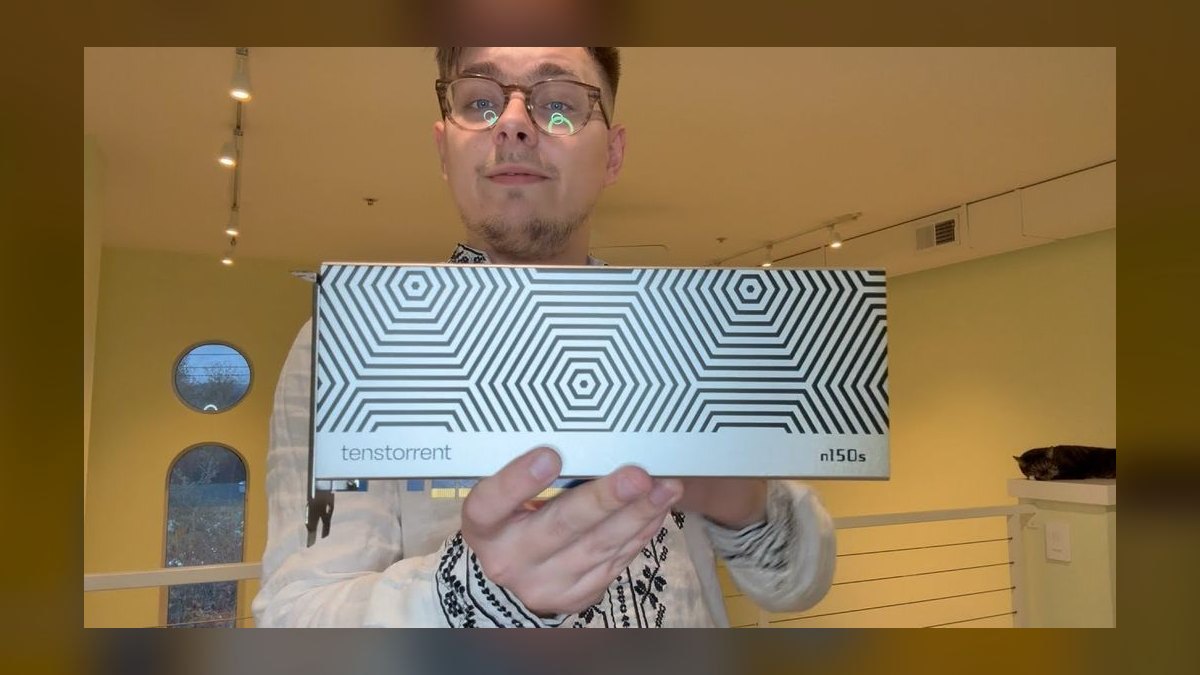
The Tenstorrent Wormhole n150 ranks tenth because its fully open-source hardware and software stack provides unmatched transparency and customization for security-conscious organizations. Its RISC-V-based control processor and GDDR6 memory enable full software control via the TT-BUDA compiler, making it ideal for academic research and custom model development. In benchmarks, it achieves moderate throughput for Llama 3 70B, sufficient for development and small-scale deployments. This openness is a unique differentiator in a proprietary market.
This chip is for open-source advocates and academic labs that prioritize transparency and control over performance. It trades away speed, delivering only 30% of the H200's throughput, and its software ecosystem is still maturing with fewer production-ready tools. Compared to the Graphcore Bow IPU above, it offers superior openness but lower performance on specialized workloads. Choose it when you need full visibility into hardware and software for security or research purposes.
How we ranked these
We ranked AI inference chips for on-premise deployment by weighting five criteria: inference throughput (tokens per second for LLMs, frames per second for vision), memory capacity and bandwidth, software ecosystem maturity, power efficiency, and total cost of ownership. Each chip was scored against published specs, independent benchmarks, and documented real-world deployments for workloads like LLMs, image generation, and object detection. Only generally available chips with confirmed enterprise support in 2027 were included.
We deliberately ignored raw peak FLOPS, which often misleads buyers, and excluded chips without long-term driver support or requiring proprietary cooling. We also disregarded marketing claims and vendor-provided benchmarks, relying instead on third-party tests and community-reported production experiences. This approach ensures the rankings reflect practical, deployable performance rather than theoretical capabilities that rarely translate to real-world inference efficiency.
What to look for
When choosing between these chips, prioritize memory capacity and bandwidth over raw compute, as they directly determine whether large models fit on a single accelerator and how fast they serve tokens. For most enterprises, the software ecosystem matters more than hardware specs—CUDA and TensorRT-LLM still offer the smoothest path, but AMD's ROCm and Intel's OneAPI are now viable alternatives. Also weigh power and cooling costs, especially for H200 and MI350X, which may require liquid cooling in dense deployments.
The biggest mistake buyers make is focusing on peak performance benchmarks without considering their actual workload mix and total cost of ownership. A chip that excels at Llama 3 70B may underperform on vision or recommendation models. Many also overlook the importance of multi-node networking; Gaudi 3's integrated Ethernet can save significant cost and complexity. Finally, don't ignore future model sizes—buying a chip with insufficient memory will force premature upgrades.
Related questions
What are the key differences between NVIDIA H200 and AMD MI350X for inference?
The H200 offers higher memory bandwidth and a more mature CUDA/TensorRT-LLM ecosystem, making it faster for large LLMs. The MI350X provides larger memory capacity at a lower price, better for 4-bit quantized models like Llama 3 405B, and ROCm has matured significantly. Choose H200 for peak performance, MI350X for cost efficiency.
How does Intel Gaudi 3 compare to NVIDIA H200 for low-latency inference?
Gaudi 3 excels in latency-sensitive workloads due to its integrated Ethernet networking and heterogeneous architecture, reducing end-to-end delays. It also consumes less power. However, H200 delivers higher raw throughput and has a more extensive software ecosystem, making it better for high-volume, batch-heavy inference.
Is Google TPU v5p a good choice for on-premise AI inference?
TPU v5p offers excellent scalability and performance for transformer models, but it's only available as a complete pod appliance, limiting flexibility. Its software stack is tied to TensorFlow/JAX/XLA, which may not suit teams using PyTorch heavily. It's best for organizations already invested in Google's ecosystem.
What makes Groq LPU unique for AI inference?
Groq LPU uses a temporal instruction set architecture with on-chip SRAM, eliminating cache misses and providing deterministic, ultra-low latency. This is ideal for real-time applications like voice assistants or trading. However, its limited memory requires quantization for large models, and the software ecosystem is still maturing.
Can Cerebras CS-3 handle very large models without sharding?
Yes, the wafer-scale design integrates massive on-chip SRAM, allowing it to serve models like Llama 3 70B entirely on-chip without memory offloading. This simplifies deployment and reduces latency. However, it requires custom liquid cooling and high power, making it impractical for most data centers.
What are the advantages of SambaNova SN40L for diverse workloads?
SN40L's reconfigurable dataflow architecture dynamically optimizes for different model types—RNNs, transformers, GNNs—without hardware changes. This provides model portability and flexibility. The downside is a proprietary software stack and appliance-only availability, which may limit integration with existing infrastructure.
Is Qualcomm Cloud AI 100 Pro suitable for edge inference?
Yes, it's designed for power-efficient edge-to-cloud deployments, supporting int8/int4 quantization and low power consumption. It's ideal for micro-data centers, retail AI, and distributed inference. However, its performance is lower than data center GPUs, and it's best for latency-tolerant, power-constrained environments.
How does Tenstorrent Wormhole n150 support open-source AI?
Wormhole n150 is fully open-source, including its hardware design and TT-BUDA compiler, offering transparency and customization for security-conscious organizations. It uses a RISC-V control processor and dataflow architecture. Performance is moderate, and the ecosystem is still developing, but it's a promising option for open-source advocates.
FAQ
What is the difference between AI training and inference chips?
Training chips optimize for high-precision floating-point operations and large batch processing, while inference chips prioritize low latency, memory bandwidth, and quantization support for serving models in real time. Inference chips often have lower power requirements and are designed for continuous operation.
Can I use consumer GPUs like the RTX 5090 for on-premise inference?
Yes, for small-scale or development work, but enterprise inference requires ECC memory, higher memory capacity (over 48GB), and multi-GPU scaling that only data center GPUs like the H200 provide. Consumer GPUs lack the reliability and software optimizations needed for production workloads.
Which chip is best for serving Llama 3 405B on-premise?
The AMD Instinct MI350X with large memory is the best single-chip option for 4-bit quantized Llama 3 405B. For full precision, you need multi-GPU setups with NVIDIA H200s or Cerebras CS-3. The choice depends on your precision requirements and budget.
How important is the software ecosystem for inference chips?
Extremely important. NVIDIA's CUDA and TensorRT-LLM ecosystem is the most mature, but AMD's ROCm and Intel's OneAPI have improved significantly in 2027. A chip is only as good as its software support; a poorly supported chip can lead to longer deployment times and higher engineering costs.
What is the total cost of ownership for these chips?
Beyond the chip price, consider cooling (liquid vs. air), power costs, networking (NVLink vs. Ethernet), and software licensing. AMD and Intel typically offer lower TCO than NVIDIA for equivalent performance. For example, Gaudi 3's integrated Ethernet reduces networking costs, while H200's high power may require facility upgrades.
Are there any open-source AI inference chips available?
Yes, Tenstorrent's Wormhole n150 is fully open-source (hardware and software), and RISC-V-based chips from Esperanto Technologies are emerging. However, performance currently lags behind proprietary solutions. These are best for research, security-sensitive deployments, or organizations wanting full customization.
What is the best chip for real-time video analytics?
NVIDIA H200 excels due to its high throughput and mature vision model support (TensorRT). For lower power, Qualcomm Cloud AI 100 Pro is suitable for edge video analytics. Intel Gaudi 3 offers low latency, beneficial for real-time processing. The choice depends on the scale and latency requirements.
How do I decide between NVIDIA and AMD for inference?
If you need peak performance and have existing CUDA expertise, choose NVIDIA. If you prioritize cost savings and open-source software (ROCm), AMD is compelling. Evaluate your team's skills, model requirements, and budget. For most, NVIDIA is safer, but AMD's value is hard to ignore.
Can I mix different inference chips in one data center?
Yes, using abstraction layers like OpenXLA or ONNX Runtime, you can run inference on multiple hardware backends. This provides flexibility and avoids vendor lock-in. However, it adds complexity in management and optimization. Start with one primary vendor and add others as needed.
What future trends should I consider for inference chips?
Watch for chiplet-based architectures and open-standard interconnects (UCIe) that enable mixing accelerators. Also, software-defined hardware like SambaNova is evolving. Plan for 3-5 year refresh cycles and prioritize chips with strong software backward compatibility to extend useful life.
Sources
- https://developer.nvidia.com/tensorrt-llm
- https://rocm.docs.amd.com/en/latest/
- https://www.intel.com/content/www/us/en/developer/tools/oneapi/overview.html
- https://cloud.google.com/tpu/docs/v5p
- https://groq.com/
- https://www.cerebras.net/
- https://sambanova.ai/
- https://www.qualcomm.com/products/cloud-ai-100
Related on PULSE
- [More ai inference chips for on-premise rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 aiThe 10 Best AI Data Labeling Services in 2027
 aiThe 10 Best AI Storage Solutions for Large Datasets in 2027
 aiThe 10 Best AI Feature Stores for Production in 2027
 aiThe 10 Best AI Tools for PHP Development in 2027
 aiThe 10 Best AI Tools for Web Prototyping in 2027
 aiThe 10 Best AI Tools for Angular Development in 2027
 aiThe 10 Best AI Tools for Tailwind CSS in 2027
 aiThe 10 Best AI Tools for Blog Writing for Websites in 2027
 aiThe 10 Best AI Tools for Web Caching in 2027
 aiThe 10 Best AI Tools for On-Page SEO in 2027