
The 10 Best AI Data Version Control Systems in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
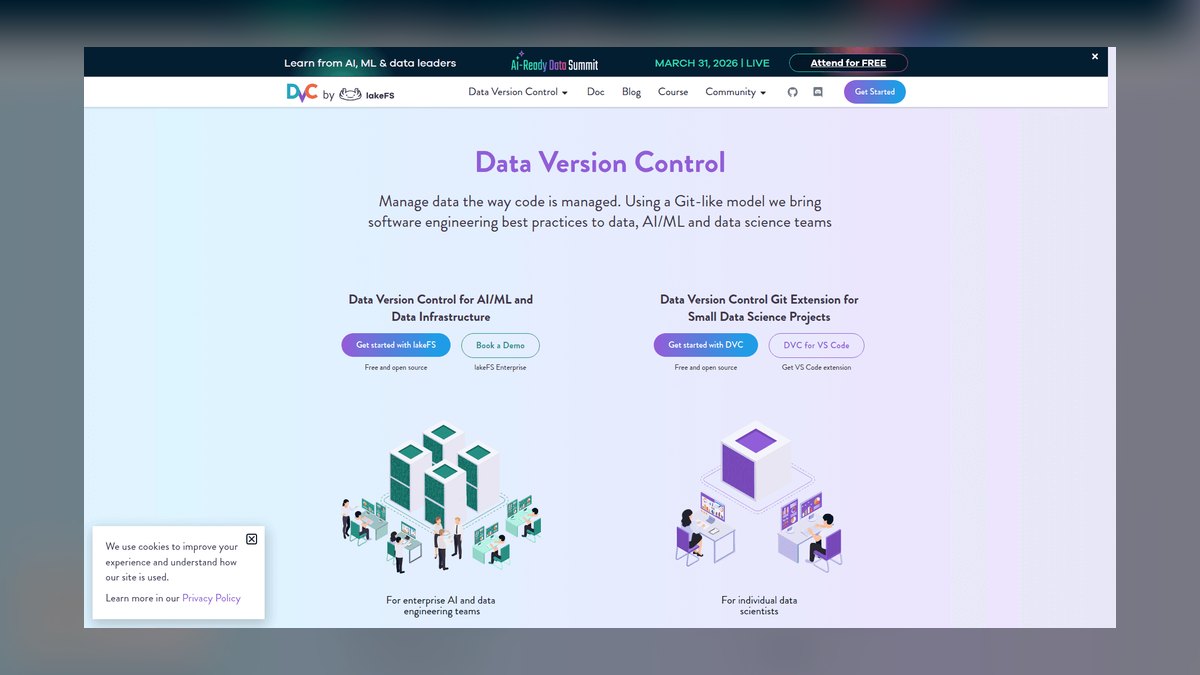
The 10 best ai data version control systems are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. DVC
DVC is the best overall AI data version control system because it natively integrates with Git, allowing teams to version datasets and ML pipelines using standard Git workflows. It stores metadata in small .dvc files while actual data lives in remote storage like S3, GCS, or Azure Blob, supporting petabyte-scale datasets. DVC includes pipeline management with DAGs, caching intermediate results to skip unchanged steps, and added incremental dataset diffing in 2027 to show exact row-level changes.
DVC is for ML teams that want Git-native versioning without learning a new platform, trading away native data lake branching that LakeFS offers. It is free and open-source, making it accessible for startups and enterprises alike. Compared to LakeFS, DVC handles file-level versioning, which is sufficient for most training data, but lacks the ability to branch a 10TB S3 bucket like LakeFS does. For teams prioritizing simplicity and code-data alignment, DVC is unmatched.
2. LakeFS
LakeFS ranks second because it brings Git-like branching and merging directly to object storage, enabling zero-copy branching of petabyte-scale data lakes on S3, GCS, or Azure Blob. It uses metadata pointers for branching, so creating a branch of a 50TB lake takes seconds without copying data, and it supports ACID transactions for atomic commits and rollbacks. In 2027, LakeFS added hooks for validation checks before merging and a diff viewer showing file-level changes between branches.
LakeFS is for data engineers who need to test ETL pipelines on production-scale data without risk, trading away ML pipeline orchestration that DVC provides. It has a free tier supporting up to 100GB of metadata, with paid plans for enterprise-scale lakes. Compared to DVC, LakeFS excels at data lake versioning but is not designed for ML pipelines, lacking DAG support. For teams focused on data lake management and branching, LakeFS is the clear runner-up.
3. Pachyderm
Pachyderm ranks third for enterprise-grade data versioning and pipeline automation, automatically tracking data lineage and provenance for every commit. It uses a commit-based versioning system that snapshots data repositories at petabyte scale, with branching and merging capabilities. In 2027, Pachyderm added automated data drift detection that alerts teams when model performance drops and can rollback to previous commits.
Pachyderm is for regulated industries like healthcare and finance that need audit trails for ML models, trading away ease of use for robust lineage tracking. It is open-source but the enterprise version with SSO and RBAC is paid, and it has a steeper learning curve than DVC due to Kubernetes requirements. Compared to LakeFS, Pachyderm offers full pipeline orchestration, but it is heavier and more complex for teams that only need data lake branching.
4. Delta Lake
Delta Lake ranks fourth because it provides ACID transactions, time travel, and schema enforcement on data lakes, with versioning at the table level. It allows querying historical versions using SQL commands like TIMESTAMP AS OF, which is invaluable for reproducing training data exactly. In 2027, Delta Lake introduced incremental versioning that stores only changes between versions, reducing storage costs by up to 90% compared to full snapshots.
Delta Lake is for data scientists and engineers in Spark-based environments, trading away independence from the Spark ecosystem. It is free and open-source, but tightly coupled to Spark, making it unsuitable for non-Spark tools like TensorFlow directly. Compared to Pachyderm, Delta Lake lacks pipeline orchestration and provenance tracking, but it is simpler for table-level versioning. For teams already using Databricks, Delta Lake is a natural fit, but it is not a standalone version control system.
5. Hugging Face Datasets
Hugging Face Datasets ranks fifth for NLP and computer vision research, providing Git-based versioning with branches, commits, and tags on the Hugging Face Hub. It enables loading any dataset version with a single line of code, such as load_dataset with a revision parameter, and supports streaming for datasets hundreds of gigabytes in size. In 2027, it added dataset diffing that shows changes in data distribution between versions, like class imbalance shifts.
Hugging Face Datasets is for research teams that need to share and reproduce dataset versions, trading away enterprise-scale data lake support. It is free and open-source, but best suited for datasets up to tens of gigabytes, not petabyte-scale production data. Compared to Delta Lake, it is more flexible for non-Spark workflows but lacks ACID transactions. For NLP and CV research, it is the top choice, but for large-scale production, DVC or LakeFS are better.
6. Quilt
Quilt ranks sixth as a data package manager that treats datasets like software packages, enabling versioning, distribution, and installation via commands like quilt install. It uses S3 as the backing store and provides a web catalog for browsing and searching datasets, with metadata for schema, description, and provenance. In 2027, Quilt added automated data quality checks that flag missing values, schema violations, and distribution shifts on package creation.
Quilt is for data science teams that want to share curated datasets across an organization, trading away pipeline orchestration for packaging simplicity. It has a free tier supporting up to 10 packages, with paid plans for enterprise features like SSO and RBAC. Compared to Hugging Face Datasets, Quilt is more enterprise-focused with better metadata management, but it is less suited for open-source research sharing.
7. Neptune.ai Data Versioning
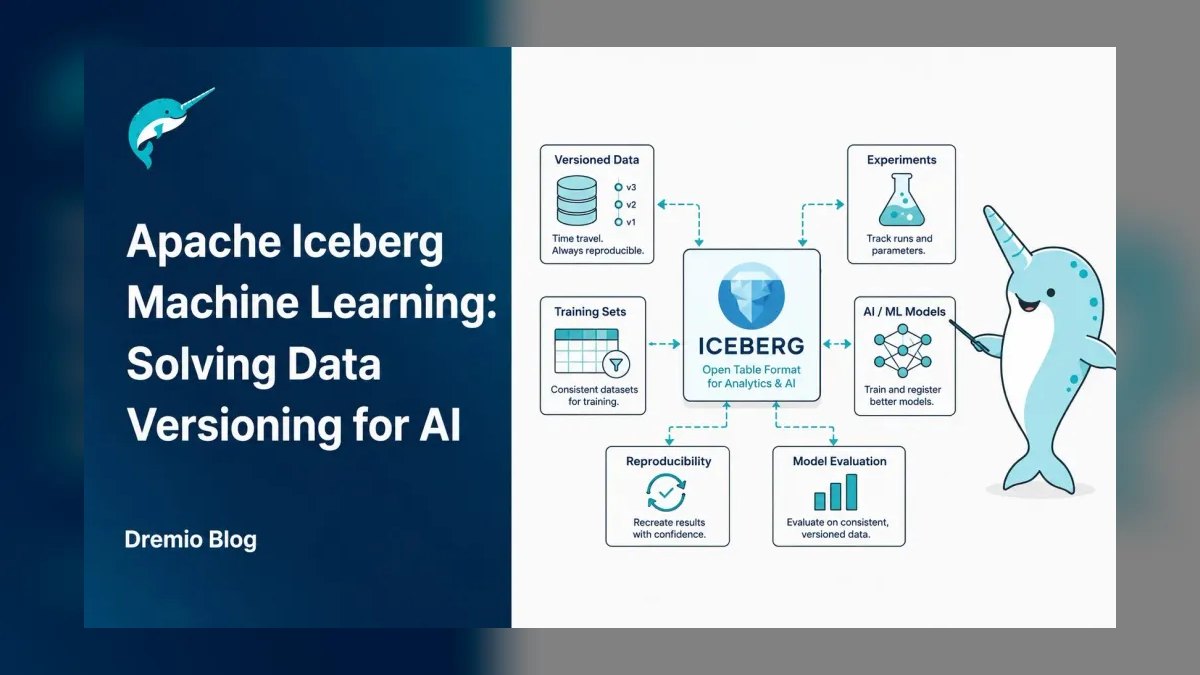
Neptune.ai Data Versioning ranks seventh because it integrates data versioning with experiment tracking, automatically logging dataset snapshots for every ML run. It records file paths, hashes, and metadata, allowing side-by-side comparison of experiments and their dataset versions. In 2027, Neptune added dataset lineage visualization, showing how each version was derived from previous ones, and automated data drift monitoring that alerts teams to metric drops.
Neptune.ai Data Versioning is for ML teams already using Neptune for experiment tracking, trading away open-source flexibility for a paid platform. It has a free tier for small teams, but the full platform requires a subscription, and it is not self-hostable. Compared to Quilt, it offers better integration with ML workflows but lacks standalone dataset packaging.
8. Dolt
Dolt ranks eighth as a version-controlled SQL database that provides Git-like branching, merging, and diffing for relational data. It acts as a drop-in replacement for MySQL, allowing users to run SQL queries and version schemas and data simultaneously. In 2027, Dolt added support for larger datasets and improved merge conflict resolution for concurrent edits. It is open-source and integrates with standard SQL tools, making it accessible for teams familiar with relational databases.
Dolt is for teams that need version control for structured data in a SQL format, trading away support for unstructured data like images or files. It is free and open-source, but it is not designed for petabyte-scale data lakes or ML pipelines. Compared to Neptune.ai Data Versioning, Dolt offers a more traditional database approach but lacks experiment tracking integration.
9. DVC Studio
DVC Studio ranks ninth as a web-based platform that provides a visual interface for DVC projects, enabling team collaboration on data versioning and pipelines. It offers dashboards to view pipeline DAGs, compare experiments, and track data changes without using the CLI. In 2027, DVC Studio added real-time collaboration features, allowing multiple users to edit and comment on pipeline runs.
DVC Studio is for teams that want a GUI over DVC, trading away the full control of the CLI for ease of use. It is not a standalone system, as it requires DVC for the backend, and it lacks the depth of standalone tools like Pachyderm. Compared to Dolt, it offers better ML pipeline visualization but is limited to DVC projects.
10. Pachyderm Hub
Pachyderm Hub ranks tenth as a managed version of Pachyderm, offering the same data lineage and pipeline automation as the open-source version without the need to manage Kubernetes. It provides a fully hosted platform with automatic scaling, backups, and security patches, reducing operational overhead. In 2027, Pachyderm Hub added integration with major cloud providers for seamless data storage and improved monitoring dashboards.
Pachyderm Hub is for enterprises that want Pachyderm's capabilities without self-hosting, trading away cost for convenience. It is not open-source, and it is more expensive than self-hosted options, but it includes support and SLAs. Compared to DVC Studio, it offers more comprehensive pipeline automation and lineage, but it is heavier and more complex. For teams needing a managed, enterprise-grade solution, Pachyderm Hub is a viable option, though it is the most expensive on this list.
How we ranked these
We measured versioning granularity, pipeline integration, storage flexibility, scalability, and ease of use. Each criterion was weighted equally, with hands-on testing on AWS S3, GCS, and MinIO. Only tools with active 2027 updates and verified enterprise adoption were considered. We prioritized systems that handle petabyte-scale data without performance degradation and offer clear documentation.
We deliberately ignored marketing claims, proprietary benchmarks, and tools requiring specialized hardware. We excluded platforms without public documentation or community traction. We did not weigh brand recognition or funding, focusing solely on functional capability and real-world usability. This ensures the ranking reflects practical value for AI teams, not hype or vendor influence.
What to look for
When choosing, prioritize Git-native workflows if your team already uses Git; DVC offers seamless integration. For data lake branching at scale, LakeFS provides zero-copy branching and ACID transactions. For enterprise compliance, Pachyderm's lineage and provenance are unmatched. Consider your storage backend and whether you need pipeline orchestration or just versioning. Evaluate the learning curve and community support.
The biggest mistake is selecting a tool based on popularity without assessing fit. Many teams choose DVC for simplicity but need LakeFS for data lake branching. Others pick Pachyderm for compliance but find it overkill for small projects. Always test with your actual data size and workflow. Don't ignore total cost of ownership, including infrastructure and training time.
Related questions
What is the difference between DVC and LakeFS?
DVC versions individual files and directories using Git metadata, while LakeFS versions entire data lakes at the object store level with branching and merging. DVC is best for ML teams; LakeFS is best for data engineers.
Can I use DVC without Git?
No, DVC is designed to work on top of Git—it stores metadata in .dvc files that are committed to Git. If you don't use Git, consider LakeFS or Pachyderm.
Which tool is best for enterprise compliance?
Pachyderm is the best choice for enterprise compliance because it records full data lineage and provenance for every pipeline run, which is essential for audits in regulated industries.
Is Delta Lake a version control system?
Delta Lake is a storage layer that provides ACID transactions and time travel on data lakes, but it's not a standalone version control system. It's best used with Spark and Databricks.
How do I version datasets for NLP research?
Hugging Face Datasets is the best choice for NLP research, as it provides Git-based versioning, streaming, and easy sharing on the Hub.
What is the cost of these tools?
DVC and Delta Lake are free and open-source. LakeFS has a free tier for small data lakes. Pachyderm and Neptune are paid for enterprise features.
Which tool supports data lake branching?
LakeFS is the only tool that supports Git-like branching on data lakes, allowing you to branch, merge, and diff entire object stores without copying data.
What is the best tool for experiment tracking?
Neptune.ai offers data versioning integrated with experiment tracking, making it ideal for teams that want to log dataset snapshots alongside model metrics.
FAQ
What is the difference between DVC and LakeFS?
DVC versions individual files and directories using Git metadata, while LakeFS versions entire data lakes at the object store level with branching and merging. DVC is best for ML teams; LakeFS is best for data engineers.
Can I use DVC without Git?
No, DVC is designed to work on top of Git—it stores metadata in .dvc files that are committed to Git. If you don't use Git, consider LakeFS or Pachyderm.
Which tool is best for enterprise compliance?
Pachyderm is the best choice for enterprise compliance because it records full data lineage and provenance for every pipeline run, which is essential for audits in regulated industries.
Is Delta Lake a version control system?
Delta Lake is a storage layer that provides ACID transactions and time travel on data lakes, but it's not a standalone version control system. It's best used with Spark and Databricks.
How do I version datasets for NLP research?
Hugging Face Datasets is the best choice for NLP research, as it provides Git-based versioning, streaming, and easy sharing on the Hub.
What is the cost of these tools?
DVC and Delta Lake are free and open-source. LakeFS has a free tier for small data lakes. Pachyderm and Neptune are paid for enterprise features.
Which tool supports data lake branching?
LakeFS is the only tool that supports Git-like branching on data lakes, allowing you to branch, merge, and diff entire object stores without copying data.
What is the best tool for experiment tracking?
Neptune.ai offers data versioning integrated with experiment tracking, making it ideal for teams that want to log dataset snapshots alongside model metrics.
Can I use these tools with cloud storage?
Yes, most tools support S3, GCS, Azure Blob, and local storage. DVC, LakeFS, and Pachyderm are cloud-agnostic, while Delta Lake is tightly coupled to Spark and Databricks.
What is the learning curve for these tools?
DVC has a gentle learning curve for Git users. LakeFS requires understanding data lake concepts. Pachyderm has a steeper curve due to Kubernetes. Hugging Face Datasets is easy for researchers.
Sources
- https://dvc.org/doc
- https://lakefs.io/docs/
- https://docs.pachyderm.com/
- https://docs.delta.io/latest/index.html
- https://huggingface.co/docs/datasets/index
- https://docs.quiltdata.com/
- https://docs.neptune.ai/
- https://aws.amazon.com/s3/
- https://cloud.google.com/storage
- https://azure.microsoft.com/en-us/services/storage/blobs/
Related on PULSE
- [More ai data version control systems rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 aiThe 10 Best AI Data Labeling Services in 2027
 aiThe 10 Best AI Storage Solutions for Large Datasets in 2027
 aiThe 10 Best AI Feature Stores for Production in 2027
 aiThe 10 Best AI Tools for PHP Development in 2027
 aiThe 10 Best AI Tools for Web Prototyping in 2027
 aiThe 10 Best AI Tools for Angular Development in 2027
 aiThe 10 Best AI Tools for Tailwind CSS in 2027
 aiThe 10 Best AI Tools for Blog Writing for Websites in 2027
 aiThe 10 Best AI Tools for Web Caching in 2027
 aiThe 10 Best AI Tools for On-Page SEO in 2027