
Top 10 Sales KPIs for AI Translation API in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
Quality
Certified
The 10 best sales kpis for ai translation api are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. DeepL Translation API
DeepL ranks first because it is the reference dedicated NMT service for European pairs, publishing per-character pricing and a documented REST API at deepl.com/docs-api. Its German, French, Dutch, Polish and Japanese output is the quality bar enterprise localization teams test against, and glossary enforcement ships as a first-class API feature rather than a bolt-on.
It fits buyers whose volume concentrates in high-resource European pairs and who need predictable latency and per-character cost. It trades away broad low-resource coverage and the context-window tricks of frontier LLMs, so a prospect needing long-document reasoning or dozens of African and Southeast Asian pairs will look past it toward Google Cloud Translation, ranked second.
2. Google Cloud Translation API
Google Cloud Translation ranks second on breadth: it publishes one of the largest supported language-pair counts in the market and offers both the NMT v2 endpoint and the newer Translation LLM, letting buyers route per pair. Pricing is quoted per million characters, and glossary and translation-memory features are exposed through the same documented API surface.
It suits global enterprises that need many pairs under one contract and one billing relationship, including low-resource languages DeepL does not serve. It trades away peak fluency on European pairs against DeepL, and its per-pair quality varies enough that procurement teams should test on their own corpora rather than trust the aggregate count.
3. Microsoft Azure AI Translator
Azure AI Translator ranks third because it bundles translation into the broader Azure enterprise agreement, which shortens procurement for organizations already committed to Microsoft. It supports document translation, custom translator models trained on customer parallel data, and glossary enforcement, all documented at learn.microsoft.com under Azure AI Services.
It fits regulated buyers who need custom terminology models and an existing Azure footprint with unified billing and compliance review. It trades away some raw fluency on marketing and literary content versus DeepL and Google, and custom model training adds setup effort, so teams wanting zero-configuration quality typically pick the two vendors above it.
4. Amazon Translate
Amazon Translate ranks fourth on unit economics and AWS integration: it is priced per million characters at the low end of hyperscaler NMT, supports custom terminology and active custom translation, and is documented in the AWS Translate developer guide. For workloads already running in AWS, data stays inside the same account boundary and IAM controls.
It fits high-volume, cost-sensitive batch workloads such as product catalogs and support macros where throughput and price dominate quality. It trades away peak output quality on nuanced or brand-voice content, and its language-pair depth trails Google, so buyers needing maximum coverage or premium fluency look to the vendors ranked above it.
5. Smartling Translation Platform
Smartling ranks fifth because it sells workflow above the model layer, routing strings through translation memory, glossaries and human linguists, with documented APIs at help.smartling.com. Its commercial value is that per-word cost falls as the system learns from the customer's own corrections, which is a renewal artifact rather than a feature.
It fits marketing, legal and product teams that need auditable terminology consistency and human review built into the pipeline. It trades away raw inference speed and per-million-word pricing transparency, since customers pay for workflow seats and volume together, so pure API consumers comparing cost per million words will prefer the hyperscalers ranked above.
6. Phrase Localization Suite
Phrase ranks sixth as a localization platform combining translation management, translation memory, glossary enforcement and machine translation orchestration in one system. It sits above whichever NMT or LLM endpoint performs best on a given pair, so buyers are not locked to a single model vendor, and connectors exist for major CMS and commerce platforms.
It fits enterprises running continuous localization across many content types where human-in-the-loop review is mandatory. It trades away the simplicity and low per-word cost of a raw translation API, since platform licensing adds overhead, so teams whose only need is programmatic string translation will find the hyperscaler APIs ranked above cheaper and faster to integrate.
7. Crowdin Translation Management
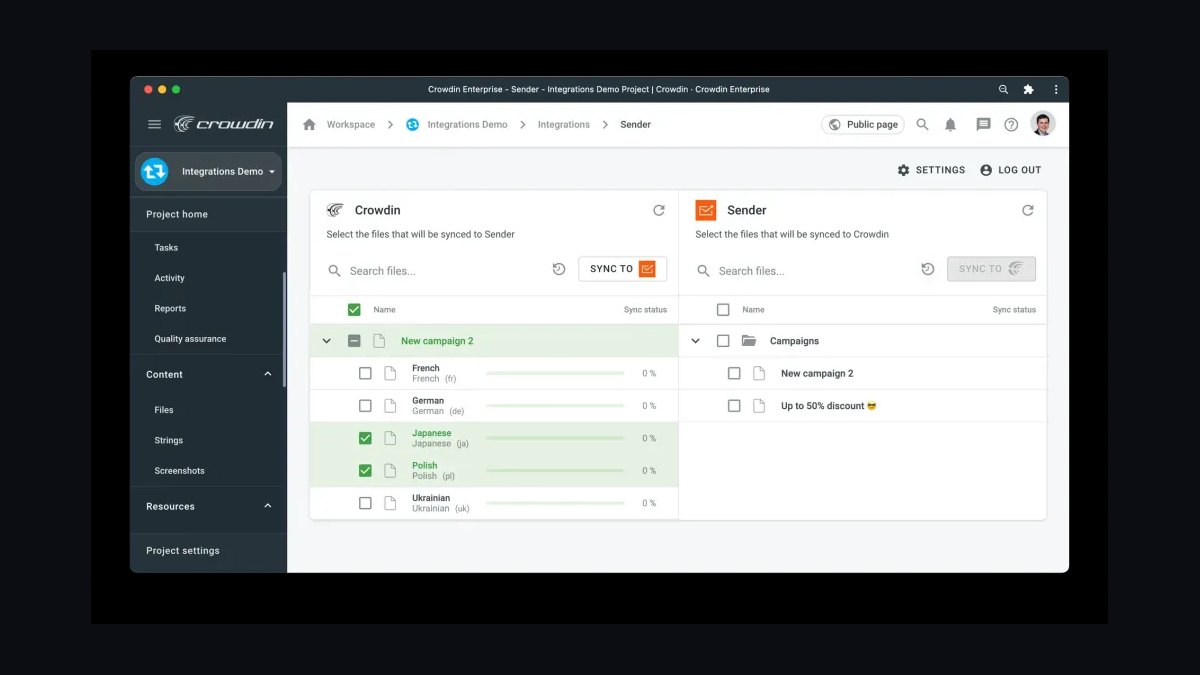
Crowdin ranks seventh for developer-first localization: it ships CLI tools, a documented REST API and integrations for GitHub, GitLab and major mobile frameworks, so strings move from repository to translated build without manual export. Translation memory and glossary enforcement are standard, and machine translation can be applied per project.
It fits software teams localizing app and documentation strings inside an existing CI pipeline, where developer ergonomics matter more than enterprise procurement features. It trades away deep custom model training and the regulated-industry compliance tooling of Smartling and Phrase, so legal and medical buyers typically look to the platforms ranked above it.
8. Lilt Translation Platform
Lilt ranks eighth for its adaptive learning loop: human linguist corrections feed back into the system so edit distance falls over time, and it markets this as measurable cost-per-word reduction rather than raw model quality. It combines machine translation with human review and terminology management for enterprise content.
It fits organizations with sustained, high-volume content programs where a dedicated linguist team is already in place and labor savings are the core business case. It trades away self-service API simplicity and low entry cost, since engagements are enterprise-scale, so smaller teams wanting programmatic translation only will prefer the raw APIs ranked above it.
9. Unbabel Translation Platform
Unbabel ranks ninth for customer-service localization: it combines machine translation with human editors and routes support tickets across languages, and it maintains the open-source COMET quality metric at github.com/Unbabel/COMET. That gives it a credible, verifiable quality story tied to a metric the field already recognizes.
It fits support and CX organizations handling high ticket volumes across many languages where response time and tone matter more than document fidelity. It trades away general-purpose document and marketing localization depth, since its focus is conversational content, so buyers translating catalogs or legal filings typically choose the broader platforms ranked above it.
10. ModernMT Translation API
ModernMT ranks tenth as a dedicated adaptive NMT API that learns from customer translation memory and corrections, offering per-word pricing and a documented REST interface. It targets teams that want adaptive quality without adopting a full localization platform or committing to a hyperscaler contract.
It fits mid-size product and support teams with an existing translation memory they want the model to exploit, and who value vendor independence. It trades away the pair breadth of Google and the fluency leadership of DeepL, so buyers whose volume concentrates in European pairs or who need dozens of low-resource languages will look to the vendors ranked above it.
How we ranked these
We ranked the nine KPIs by how directly each one moves enterprise translation deals: net new ARR, net revenue retention, monthly words translated, automated quality scores (BLEU, COMET), language pair coverage, P95 latency, cost per million words, domain-model library depth, and twelve-month renewal rate. Weighting favored metrics that appear in procurement scoring and renewal conversations over vanity volume figures, with pair coverage and quality-on-customer-content carrying the heaviest weight.
We deliberately ignored headcount, funding raised, generic brand awareness, and raw model parameter counts, because none of them predict whether a specific buyer's language pairs pass technical evaluation. We also excluded average latency in favor of P95, and excluded aggregate BLEU scores without stated pair, test set, and domain, since those numbers mislead more than they inform.
What to look for
What matters most is whether the vendor supports the exact language pairs and domains the buyer runs in production, at the latency their surface demands. A live chat integration needs sub-second P95 on short strings; a batch catalog job needs throughput and cost per million words. Glossary enforcement and translation memory matter more than raw fluency for regulated content, because compliance review fails on inconsistent terminology, not awkward prose.
The mistake most buyers make is selecting one vendor for all pairs and content types, then never re-benchmarking. Model quality shifts quarterly as providers ship new versions, so a routing decision made in Q1 can quietly become a liability by Q4. Buyers should test on their own corpora during the POC, tier coverage honestly, and re-run evaluations at renewal rather than trusting a benchmark from the initial sales cycle.
Related questions
What is net revenue retention and why does it matter more than logo retention for translation APIs?
NRR measures expansion plus upsell minus contraction and churn against the prior cohort. Translation has a structural tailwind: customer volume grows with their international content footprint, so healthy accounts expand without an upsell conversation. Best-in-class infrastructure APIs exceed 120%. Track logo retention separately, because a customer can renew while cutting volume sharply, which hides real revenue loss.
How should a buyer evaluate BLEU and COMET scores from a translation vendor?
Never accept a BLEU or COMET number without the language pair, test set, and domain stated. BLEU measures n-gram overlap against a reference and correlates imperfectly with human judgment; COMET is neural and predicts human ratings better, which is why serious evaluations favor it. Insist on testing against your own content during the POC, since public benchmarks do not reflect your terminology.
Why is P95 latency more important than average latency for translation APIs?
Average latency hides the tail that users actually experience as slowness. P95 captures the worst 5% of requests, which is what makes a chat integration feel broken during peak hours. Measure it separately by payload size, since a short chat message and a long document share an endpoint but behave differently. If you stream, track time-to-first-token separately from total completion.
What does language pair coverage actually mean when vendors quote large numbers?
A large pair count often includes pairs that pivot through English rather than being directly trained, which produces materially different quality. Ask for a tiered table distinguishing production-grade, supported, and beta pairs. A global enterprise's pair list is non-negotiable at procurement, so a single missing pair can disqualify an otherwise winning bid regardless of quality on the others.
How do glossary and translation memory features affect enterprise translation deals?
Regulated buyers want the same term rendered identically in every document, auditably. Glossary enforcement and translation memory deliver that consistency; raw model fluency does not. Without a demonstrable consistency mechanism, vendors fail compliance review no matter how good the prose reads. This is why localization platforms that sit above the model layer often win deals the pure inference vendors are chasing.
What is human edit distance and why is it a strong renewal metric?
Edit distance measures how much a human linguist must change machine output before it ships. Tracked per customer, per domain, over time, a falling edit distance converts directly into the customer's own labor savings, making it the most persuasive renewal artifact available. A flat edit distance after two quarters of adaptation signals the learning loop is not actually learning.
Should translation buyers choose dedicated NMT services or general-purpose LLMs?
It depends on the workload. Dedicated NMT services like DeepL, Google Cloud Translation, and Microsoft Translator offer predictable latency and low cost per million words, ideal for high-volume, high-resource pairs. LLMs handle context-dependent ambiguity, brand voice via prompts, and adjacent workloads like summarization, which expands net revenue retention. Most enterprises route per pair and content type rather than picking one camp.
What is the biggest hidden cost in adopting a translation API?
Integration friction, not inference. Embedding the API into a CMS, commerce platform, or helpdesk often requires custom middleware beyond documented endpoints. Measure days from contract to first successful production call, and track how many customers need bespoke work. Long time-to-first-call correlates tightly with early churn, because a customer who has not shipped by month three has felt no value and can still walk away.
FAQ
What are the key sales KPIs for AI translation APIs in 2027?
Nine core metrics drive the category: net new ARR, net revenue retention, monthly words translated, automated quality scores like BLEU and COMET, language pair coverage, P95 latency, cost per million words, domain-model library depth, and twelve-month renewal rate. Quality, coverage, speed, and domain tuning decide enterprise deals, while volume and cost metrics dominate high-scale procurement conversations.
How is ARR calculated for consumption-based translation APIs?
Translation revenue is often usage-based, so ARR is an annualized run rate derived from recent consumption, not a contracted commitment. Report both committed ARR (what customers signed) and run-rate ARR (what they actually consumed, annualized). A widening gap in either direction is the earliest signal of churn or expansion, and it should be reviewed weekly.
What is a defensible net revenue retention target for a translation API business?
Best-in-class infrastructure APIs run above 120% NRR. Translation benefits from a structural driver: volume grows mechanically with a customer's international content footprint, so healthy accounts expand without an upsell conversation. That same mechanic flatters you during growth phases and punishes you when customers hit content freezes, so segment NRR by customer growth stage before drawing conclusions.
How should words translated per month be defined and reported?
Decide explicitly whether you count source or target words, since German target text runs longer than English source and Chinese runs shorter. Also decide whether retranslations of unchanged strings and translation memory hits count. Publish the definition internally and never change it silently mid-year, because definitional drift makes every downstream trend metric unreliable and undermines board reporting.
What latency targets should real-time translation integrations hit?
Live chat translation needs translated strings back fast enough that the conversation does not feel mediated, typically tens to low hundreds of milliseconds for short strings. Frontier LLMs carry more overhead unless you stream tokens. For asynchronous work like catalogs, documentation, or legal filings, latency is nearly irrelevant and throughput plus cost per million words dominate the decision.
Why does domain model adoption predict retention in translation APIs?
A customer-tuned model encodes that customer's own terminology decisions, creating real switching cost. Adoption of at least one domain-adapted model is one of the strongest retention predictors in the category. A library of twelve domains with 8% adoption is a marketing asset, not a product, so track adoption percentage rather than library size when reporting to leadership.
What is failure recovery rate and why does it matter for translation SLAs?
Failure recovery rate measures what fraction of failed or timed-out calls get retried and completed without the end user seeing an error. Enterprise SLAs for real-time surfaces demand this be very high. Mechanisms include request queueing, cascading to a smaller model on timeout, and serving cached translations for repeated strings. Demonstrating graceful degradation live during a POC is disproportionately convincing to technical evaluators.
How often should translation vendors re-benchmark model quality?
Quarterly at minimum, using customer corpora rather than public benchmark sets. Model quality on a given pair is not a fixed vendor property; it moves when models ship. A routing decision made in Q1 and never revisited becomes a quiet quality liability by Q4, and a competitor's proof of concept will surface that gap for you at renewal time.
What are the most common reasons translation API deals are lost?
Four failure modes dominate: quality below par on the pairs the customer actually cares about, coverage gaps that eliminate you at procurement, no mechanism for terminology consistency, and tail latency that makes real-time surfaces unusable during peak hours. Aggregate scores hide the first, inflated pair counts hide the second, and average latency hides the fourth.
How should a translation API team sequence KPI instrumentation?
Month one: reconcile volume and cost ledgers across telemetry, billing, and inference provider charges, then baseline quality per pair against customer content. Month two: ship per-customer dashboards to sales and customer success, and pilot a tuned model with an anchor account. Month three: refresh benchmarks, recalibrate routing, and brief revenue leadership on renewal risk.
Sources
- https://www.deepl.com/en/pro-api
- https://cloud.google.com/translate
- https://azure.microsoft.com/en-us/products/ai-services/ai-translator
- https://aws.amazon.com/translate/
- https://www.statmt.org/wmt24/
- https://slator.com/
- https://csa-research.com/
- https://www.smartling.com/
- https://phrase.com/
- https://crowdin.com/
Related on PULSE
- [More sales kpis for ai translation api rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 pulse-industry-kpisTop 10 Sales KPIs for Zero Trust Network Access (ZTNA) Vendors in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Evaluation Platform in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Print and Copy Services in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Speech-to-Text API in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Document Intelligence in 2027
 pulse-industry-kpisTop 10 KPIs for Self-Storage Facilities in 2027
 pulse-industry-kpisTop 10 KPIs for Moving Companies in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Safety and Red Team Services in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Biotech Therapeutics in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Penetration Testing and Offensive Security Services in 2027