


How do you prove Palantir Ontology improved win rate without creating a new shadow data mart for outbound SDR teams on HubSpot when multi-currency ARR rollups in 2027?
Quality
Certified
Tag deals with a single HubSpot property—Ontology Source—when Palantir Ontology drives outbound SDR prioritization, then compare win rate and ARR (converted to base currency via HubSpot's native multi-currency rollup) between tagged and untagged deals over a rolling window. This proves the lift using existing CRM objects, without creating a second warehouse or shadow data mart to maintain.
The scenario: an SDR pod, a new scoring layer, and a skeptical RevOps leader
Picture a 12-rep outbound SDR org running entirely on HubSpot. Sales leadership just licensed Palantir Ontology to unify account, product-usage, and intent signals that today live scattered across a data warehouse, a few Looker dashboards, and one analyst's spreadsheet. The pitch is that Ontology's semantic layer will let SDRs prioritize accounts with a single "next-best-account" recommendation instead of guessing from six disconnected reports. Leadership approves a pilot. Within a week, someone on the data team proposes standing up a new Snowflake schema — call it ontology_signals — to store the daily Ontology exports so RevOps can "properly analyze" the results. This is the exact moment the shadow data mart is born, and it is also the moment the RevOps leader running this pilot has to say no.
The reason to say no isn't dogma about tooling minimalism. It's that a second copy of deal data, refreshed on its own schedule, joined by hand to HubSpot exports, immediately diverges from the system of record. Three weeks later nobody can agree whether "win rate" means closed-won divided by closed (won+lost) in the mart, or closed-won divided by all created deals in HubSpot, because the two pipelines count differently and nobody owns the reconciliation. The audit trail leadership actually wants — did Ontology-influenced deals close at a higher rate than the deals SDRs picked on their own — gets buried under a data-quality argument that has nothing to do with the underlying question.
The fix is to keep the CRM as the single source of truth and use Ontology as an input signal, not a second ledger. Every time Ontology surfaces a recommended account or contact for a rep, a lightweight webhook writes two things back to the HubSpot deal record once a deal is created from that recommendation: a picklist property (Ontology Source = Ontology-influenced or Rep-sourced) and a numeric property (Ontology Score, 0–100, the confidence Ontology assigned at the moment of recommendation). No new database, no nightly batch job reconciling two systems, no analyst maintaining a join key between Foundry object IDs and HubSpot deal IDs in a spreadsheet that only they understand.
This also solves the multi-currency wrinkle baked into the question. If this SDR org sells in USD, EUR, and GBP, ARR comparisons across the Ontology-influenced and rep-sourced cohorts are meaningless unless they're expressed in one currency. HubSpot's native multi-currency deal property already stores both the original transaction currency and the converted amount in your company's base currency, updated against the exchange rate set at deal creation (or updated periodically, depending on your currency settings). That converted field is the one every rollup, every report, and every executive dashboard should reference — never the raw local-currency amount — because mixing currencies inside a single average or win-rate denominator silently corrupts the comparison in exactly the kind of way that erodes trust in the proof once someone check the math.
How the mechanism actually works
The mechanical chain has five moving parts, and every one of them lives inside tools you already pay for. First, Palantir Ontology runs its scoring or recommendation model against whatever objects you've mapped into it — accounts, contacts, product usage events, intent data. Second, when Ontology surfaces a recommendation to an SDR (through whatever interface your team uses — a Slack alert, an embedded panel, a daily digest), that recommendation event carries a unique identifier and a confidence score. Third, a small integration — Zapier, Make, or a custom serverless function calling both the Foundry API and the HubSpot API — listens for deal-creation events in HubSpot and checks whether the associated contact or company was recently surfaced by Ontology. If so, it writes the Ontology Source and Ontology Score properties onto that deal at creation time, not retroactively, so the tag reflects what actually happened rather than a guess reconstructed later. Fourth, HubSpot's workflow and reporting engine treats those two properties like any other deal property — they can be filtered, segmented, and rolled up exactly like deal stage or pipeline. Fifth, and this is the part teams skip, the deal's currency-converted amount property (the base-currency ARR field) feeds every downstream rollup so a $40,000 EUR deal and a $45,000 USD deal aggregate correctly into one number.
Nothing in this chain requires Ontology's own storage layer to become the analytical source of truth for sales performance. Ontology is upstream — it produces a recommendation and a score. HubSpot stays downstream and authoritative — it owns the deal lifecycle, the currency conversion, and the win/loss outcome. The proof lives entirely inside that downstream system, which is also why finance and RevOps ops can both audit it without learning a second platform's query language.
Real numbers, ranges, and benchmarks
Setup time for the webhook-plus-property approach typically runs 3–5 hours for a team with existing Zapier or Make familiarity and API access to both platforms — mapping the two properties, writing the trigger logic, and testing against a handful of sandbox deals. Teams building the equivalent connector from scratch in a serverless function (AWS Lambda or a Netlify function calling both APIs) should budget closer to a day, mostly for handling retries and API rate limits gracefully rather than for the core logic itself.
For the pilot itself, size and duration both matter. A single pod of 3–5 SDRs generating fewer than 10 closed-won deals a month per rep needs at least 4 weeks, and often a full quarter, before the tagged-vs-untagged win rate difference is more signal than noise — with that little volume, one or two anomalous deals can swing the percentage by 10-plus points. A larger pod — 8–12 SDRs with healthier deal velocity — can often get a directionally reliable read in 2–3 weeks, though a 4-week window remains the safer default because it absorbs a normal weekly cadence of meetings, demos, and follow-ups rather than catching an unrepresentative slice of the funnel.
On the currency side, HubSpot's multi-currency feature updates exchange rates against a schedule you control (commonly daily or weekly), and it's worth locking that cadence during a pilot so a rate swing mid-test doesn't get mistaken for a performance swing. A 3–4% currency fluctuation over a four-week window is common for major pairs and can move a base-currency ARR rollup by a similar percentage — small next to a real win-rate lift, but large enough to misread if you're eyeballing raw numbers instead of the converted field.
On the outcome side, teams running this kind of tagged-cohort comparison typically look for a win-rate delta in the range of 3–8 percentage points to call the pilot a genuine success worth scaling — smaller deltas are usually within the noise band for pod-sized sample sizes, and RevOps leaders should treat anything under 3 points as "no clear signal yet" rather than proof of failure. Time-to-first-touch and time-to-qualified are worth tracking alongside win rate because Ontology's biggest early effect is often prioritization speed — SDRs reaching the right account sooner — which shows up in cycle-time metrics before it shows up in the win-rate percentage itself.
Trade-offs and alternatives
The property-tagging approach isn't the only way to prove impact, and it isn't free of trade-offs. Its biggest limitation is granularity: a single 0–100 score and a binary source tag can't capture everything Ontology's underlying model considered, so if leadership eventually wants to know which specific signal (usage spike, hiring signal, funding event) drove a given recommendation, the HubSpot property alone won't answer that — you'd need to go back to Foundry's own audit log for that deal. That's an acceptable trade-off for a pilot proving aggregate win-rate lift, but it's worth naming explicitly so nobody assumes the two properties are a full substitute for Ontology's native analytics.
The alternative most teams reach for first is exactly the shadow data mart this question is trying to avoid — replicate HubSpot deal data and Foundry object data into a shared warehouse table so a BI tool can join them freely. That does buy flexibility: an analyst can slice by any dimension without waiting on new HubSpot properties. But it also means someone now owns a second pipeline's uptime, its refresh schedule, its schema drift when either source system changes a field, and its reconciliation against the CRM whenever the two disagree — which they eventually will. For a pilot meant to answer one focused question — did Ontology-influenced deals close at a higher rate — that ongoing maintenance cost is disproportionate to the question being asked.
A middle path some teams use once a pilot has already proven the value case: push Ontology-derived scores into HubSpot as before, but also stream a read-only export to a BI tool (Looker, Tableau) via HubSpot's native reporting API rather than a hand-built ETL job into a new schema. This gets you richer visualization without a second write-path for deal data — HubSpot stays the only place anyone edits a deal, and the BI layer is purely a read replica refreshed on a schedule, which is a meaningfully smaller governance burden than a mart designed to be queried and joined ad hoc.
Common pitfalls and how to avoid them
The most common mistake is tagging deals retroactively instead of at creation. If the Ontology Source property gets backfilled weeks after a deal closes based on someone's memory of "I think Ontology surfaced this one," the comparison is contaminated by hindsight bias — reps and managers unconsciously tag deals that already look good as Ontology-influenced. Write the tag at the moment of deal creation, driven by the webhook, never by a human filling in a dropdown after the fact.
A second pitfall is mixing currencies into the comparison without using the converted field. It is tempting to just sum the amount property because it's the first number visible on a deal record, but that property holds the local transaction currency, not the base-currency equivalent. Every rollup used for this proof needs to reference the base-currency converted amount specifically — check your HubSpot currency settings to confirm which property that is before building the report, because the raw amount field will silently produce a nonsense average the moment your pilot pod closes deals in more than one currency.
A third pitfall is declaring victory or failure too early on thin volume. A pod that closes six deals in two weeks and sees a 20-point win-rate swing between tagged and untagged cohorts is looking at noise, not a result — six deals is a small enough sample that a single unusually strong or weak account distorts the whole percentage. Set the sample-size threshold before the pilot starts (a reasonable floor is 15–20 closed deals per cohort) and hold the line on waiting for it rather than reading tea leaves at week two because leadership wants an early answer.
A fourth pitfall, and the one this question is built around, is letting "we need better analytics" become the justification for creating a parallel mart mid-pilot. That request almost always comes from a genuine desire for flexibility, not malice, but granting it turns a two-week proof into a six-month data-platform project with its own budget line. If an analyst genuinely needs ad hoc joins the HubSpot properties can't support, that's a signal to finish the pilot on the lightweight path first, then make the mart decision separately, with its own owner and its own maintenance budget, once the win-rate case has already been proven or disproven.
Finally, don't let the definition of "win rate" drift between the baseline period and the pilot period. If deal stages, required fields, or pipeline structure changed in HubSpot between the two windows — a common side effect of a RevOps team cleaning up hygiene at the same time it runs an Ontology pilot — the comparison silently breaks. Freeze the pipeline configuration for the duration of the test, and if a change is unavoidable, document it next to the results so nobody mistakes a definitional shift for a performance shift.
Related questions
Do I need to sync Ontology data into my data warehouse at all?
No — for a win-rate pilot, HubSpot properties driven by a webhook are sufficient. Reserve warehouse syncing for later, broader analytics needs that a single deal property genuinely can't answer, and scope that separately.
What if my team uses Salesforce instead of HubSpot?
The same pattern applies: write an Ontology Source and Ontology Score field onto the Opportunity object via a platform event or Flow, then compare win rate and currency-converted amount across cohorts using native Salesforce reports.
How do I avoid rep bias if SDRs know which deals are tagged?
Keep the tag invisible to reps in daily views, or at minimum don't let it influence forecast category or coaching conversations during the test window, so behavior doesn't change simply because a deal is being watched.
Can this same approach measure Palantir AIP recommendations instead of Ontology?
Yes — the mechanism is identical; only the upstream signal source changes. Tag deals at creation based on which AIP-driven action triggered them, then compare outcomes using the same currency-normalized HubSpot rollups.
What's the minimum team size to run this pilot credibly?
A single pod of three to five reps is workable, but plan for a longer window (four-plus weeks) to offset small-sample noise; larger pods reach a reliable read faster because deal volume accumulates sooner.
FAQ
Do I need engineering resources to build this, or can RevOps do it alone? A RevOps admin with HubSpot property and workflow access, paired with a no-code connector like Zapier or Make, can build the tagging pipeline without a dedicated engineer. A custom serverless integration is faster and more reliable at scale but isn't required to prove the initial win-rate case.
What happens to the Ontology Score property after the pilot ends?
Leave it in place if the pilot shows a lift — it becomes a permanent enrichment field useful for ongoing reporting and for training reps on which recommendations to trust. If the pilot shows no lift, archive the property rather than deleting it, so the historical record of what was tested remains intact.
Does this approach work if Ontology scores contacts rather than whole accounts or deals? Yes — tag the deal based on whether its primary contact or company was recently surfaced by Ontology, using whatever object-level identifier Foundry exposes. The comparison logic stays the same; only the join key on the webhook changes.
How is this different from just tracking a UTM-style source field on leads? A source field on the lead object only tells you where a contact originated. Tagging at the deal level, with a live confidence score, lets you correlate the strength of Ontology's recommendation with the eventual outcome — a much finer-grained signal than a simple yes/no attribution tag.
Should finance be involved before I start the pilot? Loop finance in once, at the start, specifically to confirm the base-currency rollup logic and exchange-rate cadence you're using matches what they already report on. That single alignment conversation prevents a dispute later about whether your win-rate numbers match the official ARR figures.
What's the fastest way to know if the pilot is worth scaling? Watch the win-rate delta between cohorts alongside time-to-first-touch. A meaningful win-rate lift paired with a shorter time-to-first-touch is a strong signal Ontology's prioritization is doing real work, not just correlating with reps who were already going to perform well.
Sources
- https://www.palantir.com/platforms/foundry/ontology/
- https://knowledge.hubspot.com/properties/create-and-edit-properties
- https://knowledge.hubspot.com/deals/manage-multiple-currencies
- https://knowledge.hubspot.com/reports/create-reports-with-multiple-data-sources
- https://www.gartner.com/en/sales
- https://hbr.org/topic/sales
- https://www.forrester.com/blogs/category/sales/
- https://www.saastr.com/
Related on PULSE
- How do you prove Palantir Signals for GTM alerts improved win rate without creating a new shadow data mart for marketplace listings teams on HubSpot when multi-currency ARR rollups?
- How do you forecast mutual action plans ignored in stage gates when multi-currency ARR rollups and leadership only reviews expansion rate monthly on HubSpot during outbound SDR?
- How do you use Palantir AIP to alert on multi-thread gaps on enterprise deals in HubSpot during renewal-only CS motion when multi-currency ARR rollups?
- How do you prove Palantir Ontology improved win rate without creating a new shadow data mart for partner-sourced pipeline teams on Salesforce when legal redlines on order forms?
- How do you prove Palantir Ontology improved win rate without creating a new shadow data mart for channel co-sell teams on Pipedrive when rev rec on multi-element deals?
- How do you prove Palantir Ontology improved win rate without creating a new shadow data mart for renewal-only CS motion teams on Dynamics 365 when BI in Looker?
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 revopsHow do you prove Palantir Ontology improved win rate without creating a new shadow data mart for multi-product bundles teams on Zoho CRM when strict IT security review blocks integrations in 2027?
 revopsHow do you prove Palantir Ontology improved win rate without creating a new shadow data mart for channel co-sell teams on Pipedrive when rev rec on multi-element deals in 2027?
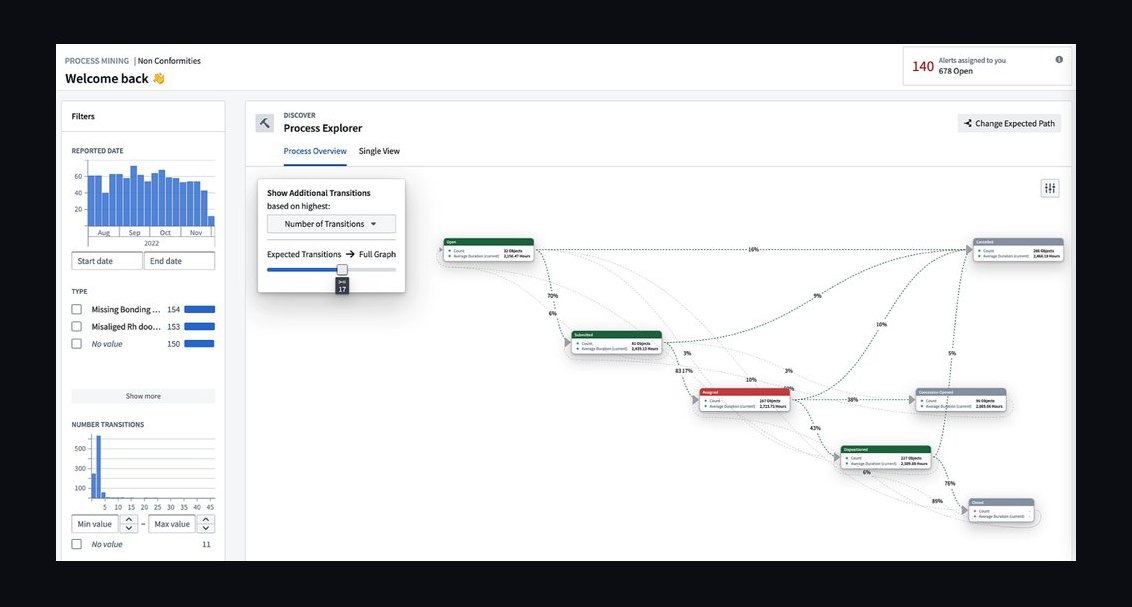 revopsHow do you use Palantir Foundry to automate broken lead routing across brands in HubSpot during marketplace listings when customer success on Gainsight in 2027?
 revopsHow do you use Palantir Ontology to measure multi-thread gaps on enterprise deals in HubSpot during enterprise outbound when no data engineer in 2027?
 revopsHow do you prove Palantir Foundry improved win rate without creating a new shadow data mart for BDR-to-AE split teams on HubSpot when AEs refuse new required fields in 2027?
 revopsHow do you use Palantir Ontology to document broken lead routing across brands in HubSpot during multi-year ramp contracts when AEs refuse new required fields in 2027?
 revopsHow do you prove Palantir Ontology improved win rate without creating a new shadow data mart for renewal-only CS motion teams on Dynamics 365 when BI in Looker in 2027?
 revopsHow do you prove Palantir Ontology improved win rate without creating a new shadow data mart for partner-sourced pipeline teams on Salesforce when legal redlines on order forms in 2027?
 revopsHow do you prove Palantir-driven forecast simulations improved win rate without creating a new shadow data mart for multi-product bundles teams on HubSpot when AEs refuse new required fields in 2027?
 revopsHow do you use Palantir-driven forecast simulations to forecast multi-thread gaps on enterprise deals in HubSpot during inbound SDR when no data engineer in 2027?