

What 2027 vendor consolidation scenario breaks the handoff between SDR and AE when both use different AI co-pilots?
 Curated byKory White · Fractional CRO · Maryland
Quality
Certified
The breaking scenario is a single vendor acquiring separate SDR and AE co-pilots but never merging their data models. The SDR's assistant scores on activity and conversation signals; the AE's scores on stakeholder coverage and deal criteria. Same lead, opposite verdicts, no shared ontology — so the handoff silently stalls inside one consolidated stack.
The outcome you should expect
The outcome is not a loud integration failure. Nothing throws an error, no sync job turns red, and no admin gets an alert. What you get instead is a slow bleed at exactly the point in your funnel where you have the least instrumentation: the moment a lead stops belonging to the SDR and starts belonging to the AE.
Concretely, expect four things to show up within one to two quarters of the consolidation closing.
First, lead acceptance rate drifts down without an obvious cause. If your AEs were accepting somewhere in the 55–70% range before, you will see that slide — often into the 35–50% band — while every upstream metric looks fine or better. Meetings booked hold steady. Call volume holds steady. Connect rates hold steady. The SDR team's dashboard is green. Only the acceptance number moves, and because acceptance is usually a lagging, manually-reviewed metric rather than a real-time one, it takes weeks for anyone to notice.
Second, the bounce-back rate climbs. Leads get passed, rejected, re-passed, rejected again. Each round trip adds days. A handoff that used to resolve in 24–48 hours starts taking five, seven, ten days. In a market where buyers routinely evaluate three or four vendors in parallel, a week of internal ping-pong is often the whole difference between being in the deal and being told "we've already shortlisted."
Third, you get orphaned records. These are the worst category because they are invisible. A lead is marked "handed off" in the SDR's system of record and simultaneously scored below the AE co-pilot's action threshold, so it never surfaces in the AE's daily queue. Neither person believes they own it. The SDR moves on because their tooling shows the task complete. The AE never sees it because their tooling filtered it out before it reached a worklist. The record exists, is fully populated, and is worked by nobody. These only surface during a manual pipeline audit, and by then the buying window has closed.
Fourth, and most corrosive, trust collapses between the two teams. The SDRs conclude the AEs are cherry-picking. The AEs conclude the SDRs are sandbagging quota with junk. Both are wrong, and both are looking at genuine evidence from their own tooling. That is the signature of this failure: two teams, two AI assistants, two internally-consistent stories, and no shared surface where the disagreement is visible to either of them.
What makes this a *consolidation* problem rather than a generic RevOps problem is the false confidence it creates. When your SDR tool and your AE tool came from different companies, everyone assumed they might not talk and budgeted for the seam — an integration owner, a mapping doc, a quarterly reconciliation. When both tools carry the same vendor's logo on the login screen, that budget disappears. Leadership signs the consolidation deal partly on the promise of "one platform, one source of truth," and the integration headcount gets cut in the same planning cycle. The seam is still there. The people who used to watch it are not.
What drives that outcome
The mechanism has four layers, and each one is independently sufficient to cause damage. Stacked, they compound.
Layer one: divergent training objectives. An SDR-oriented co-pilot is built by a company whose customers measured success in meetings booked. Every model, heuristic, and ranking inside it optimizes toward the top of the funnel: reply likelihood, engagement depth, conversation quality, speed-to-first-touch. An AE-oriented co-pilot is built by a company whose customers measured success in forecast accuracy and closed-won rate. It optimizes toward the bottom: stakeholder breadth, qualification completeness, deal risk, slippage prediction. Neither is wrong. They are answering different questions, and both have been rewarded for years for answering their own question well.
Layer two: incompatible object shapes. Conversation-intelligence tooling tends to think in terms of people, interactions, and relationships — a graph. Deal-management tooling tends to think in terms of opportunities, stages, and fields — a table. A relationship graph showing five connected individuals at an account is rich signal to the first system and nearly unreadable to the second, which wants a primary contact and a set of populated fields. Translating between them is not a mapping exercise. It is a modeling exercise, and it usually needs someone who understands both domains and has the authority to declare a canonical shape.
Layer three: no shared scoring ontology. Even if you solve the object shapes, "score" means different things. One system's 85 and another system's 85 are not comparable quantities. They are not on the same scale, do not represent the same probability of anything, and were calibrated against different outcome definitions. Passing a number across the handoff without a translation layer is worse than passing nothing, because a number carries false authority. A human who sees "score: 85" assumes it means something to the recipient system. It does not.
Layer four: no escalation path when they disagree. This is the layer teams most often skip, and it is the cheapest to fix. When one co-pilot says 90 and the other says 30, nothing happens. There is no rule that fires, no queue that fills, no person who gets paged. The disagreement is the single most informative event in the whole pipeline — it means the lead is genuinely ambiguous and deserves a human — and it is the one event neither system is built to emit.
The loop worth noticing in that diagram is the one at the bottom. The only path that improves anything over time is the one where a human resolves a disagreement *and the resolution is written back somewhere both systems read*. Without that write-back, you are staffing a permanent manual reconciliation desk. With it, you are building the shared ontology you should have negotiated for during the consolidation.
Benchmarks and realistic ranges
Be careful with benchmarks here. Public research on multi-co-pilot handoff failure specifically is thin, and vendor-published numbers describe their own installed base under their own definitions. Use the following as planning ranges to calibrate your own instrumentation against, not as industry facts to put in a board deck.
Lead acceptance rate. Most healthy B2B teams land somewhere in the 50–70% band. Below 40% sustained, either the qualification bar is undefined or the AE side is filtering on criteria the SDR side cannot see. Above 90%, acceptance has become a formality and is not measuring anything — AEs are rubber-stamping to avoid conflict, which hides the problem rather than solving it.
Handoff-to-first-AE-touch. Same business day is the standard worth holding. Anything past 48 hours, and you are relying on the buyer's patience. When you instrument this, measure from the handoff event timestamp, not from when the AE first opened the record — the gap between those two is precisely where orphaned leads hide.
Bounce-back rate. Leads returned to the SDR after handoff should run in the low single digits to low teens. Persistent rates above roughly 20% mean the two sides are working from different definitions, and it is worth checking whether the bounces cluster on a specific segment, a specific rep pair, or a specific score band.
Disagreement rate between the two co-pilots. Once you can compute this — and you should make it a first-class metric — expect 10–25% of handed-off leads to sit in the "one says yes, one says no" zone. That is not a bug. That is genuine ambiguity, and it is the population your human review queue exists for. If your disagreement rate is near zero, one of the two scores is not actually being consulted.
Time cost of manual reconciliation. Teams that hit this without a plan typically burn a meaningful chunk of an ops person's week comparing dashboards, pulling exports, and adjudicating individual records. Budget for this honestly when you build the business case for a fix. The middleware project is almost always cheaper than the ongoing manual labor, but the manual labor is invisible on the P&L and the middleware project is not, which is why the wrong choice keeps getting made.
Adjacent handoffs worth measuring at the same time. This failure mode is not unique to SDR→AE. Anywhere two roles use two different intelligent tools and pass records between them, the same four layers apply. Marketing→SDR has it, where an MQL model and an outbound-prioritization model disagree about the same lead. AE→CS has it, where a deal-scoring model's "great fit" and an onboarding-health model's "high risk" describe the same account. Partner-sourced→direct routing has it. Renewals→expansion has it. If you are building a disagreement-detection layer for one seam, build it as a general pattern with a seam parameter rather than a one-off, because you will need it three more times within a year.
A note on the deal-size math. It is tempting to multiply a conversion drop by an average contract value and present a large lost-pipeline number. Resist the clean version of that. Bounced leads are not uniformly lost — a meaningful share get recovered late, some were genuinely unqualified and the AE co-pilot was right, and the counterfactual conversion rate is unknowable. Model a range with an explicit recovery assumption and show the assumption. A defensible range beats a precise number you cannot defend in the follow-up question.
Risks, edge cases, and failure modes
The AE co-pilot is sometimes correct. The most common overcorrection is to conclude the AE side is too strict and loosen its threshold. Sometimes the strict filter is genuinely catching leads that would waste weeks. If you loosen without measuring downstream close rates, you will trade a visible acceptance problem for an invisible win-rate problem, and the second one takes two quarters to show up. Always pair a threshold change with a downstream conversion check.
Averaging two incomparable scores produces a meaningless number. The instinct is to build a blended score — average the two, or weight them. Do not do this without first checking that both inputs are calibrated. Averaging an aggressive scorer with a conservative one yields a number that is systematically wrong in both directions depending on the segment. Convert each score to a percentile within its own distribution first, *then* combine. Percentiles are comparable; raw scores are not.
Vendor roadmap promises are not a plan. During a consolidation, the acquiring vendor will tell you unification is coming. It may well be, and their intent may be entirely genuine. But post-acquisition data model merges are among the hardest engineering projects a software company undertakes, they routinely slip, and the two product teams involved have every incentive to protect their own model. Ask for the specific release, the specific object, and a named contact. Build your interim layer regardless. If the merge lands early, you delete your layer and celebrate.
Compensation quietly overrides everything. If SDRs are paid per meeting passed and AEs are paid on closed-won, both AI tools will be steered — by the humans using them — toward those incentives. You can build a perfect reconciliation layer and watch it get gamed within a quarter. Any structural fix to the handoff needs a compensation component: partial SDR credit for leads that reach a mid-funnel stage, or an AE component tied to accepting and working what they receive. This is the fix teams skip because it requires finance's agreement, and it is the one that determines whether the technical fix survives.
Human review queues become the new bottleneck. A disagreement queue is the right answer, but if you route 25% of leads into it and staff it with one part-time analyst, you have just moved the delay rather than removed it. Size the queue against realistic volume, set an SLA measured in hours not days, and — critically — require the reviewer to record *why* they decided what they decided in a structured field. The reasons are your training data for eventually automating the queue away.
Silent failures during the migration window itself. The riskiest period is the weeks around the actual platform cutover, when field mappings change, IDs get remapped, and historical data gets backfilled. Handoff events written during that window can land in the wrong place entirely. Freeze the handoff logic during cutover if you can, run a daily reconciliation count during it if you cannot, and hold a list of every lead that crossed the seam during the window for manual review afterward.
Territory, routing, and segment interactions. Score disagreement is rarely uniform. It usually concentrates — in a specific segment, a specific region, a named-account tier, or a product line the AE model was never trained on. Before you change any global threshold, cut the disagreement population by segment. More often than not you will find that 70% of the problem lives in 20% of the book, and a targeted routing rule solves it faster and more safely than a platform-wide change.
The best-of-breed reversal is a real option. If the consolidated vendor cannot or will not unify the models on a timeline you can live with, unwinding one side back to a separate tool is legitimate. It costs you the consolidation savings and adds an integration to maintain. It also gives you an explicit, documented seam that someone owns — which is frequently better than an implicit seam that nobody does. Price the reversal honestly and keep it on the table as leverage in the vendor conversation.
A practical rollout plan
Sequence matters. Do not start by changing thresholds or negotiating with the vendor. Start by making the disagreement visible, because you cannot fix or negotiate about something you cannot count.
Weeks 1–2: instrument the seam. Capture both scores on the same record at the moment of handoff, plus the timestamp. That is it. No logic changes, no threshold changes, no new rules. You need a clean baseline distribution before you touch anything, and you need at least a few hundred handoffs to see the shape.
Weeks 3–4: quantify and segment. Compute the disagreement rate. Cut it by segment, region, deal size, product, and rep pair. Identify where the disagreement concentrates. In parallel, pull the last quarter's bounced leads and hand-review a sample of forty or fifty — read the actual records and decide, as a human, who was right. That sample tells you whether you have a too-loose SDR problem, a too-strict AE problem, or a genuine ontology gap. Those three have completely different fixes.
Weeks 5–8: ship the review gate. Build one rule: when the two scores disagree beyond a defined margin, route the lead to a human queue with a two-hour SLA during business hours. Require a structured reason code on every decision. This is deliberately unsophisticated. It stops the bleeding immediately, it costs almost nothing, and every decision it captures is labeled training data for the next phase.
Weeks 9–16: build the normalization layer. With a few hundred human decisions logged, convert each co-pilot's raw score into a percentile within its own recent distribution, then build a combined score weighted by which signals actually predicted your reviewers' decisions. Run it in shadow mode first — compute it, log it, act on nothing. Compare its recommendations against the human queue's actual decisions for four weeks before letting it route anything.
Weeks 9–16, in parallel: fix compensation. Get finance in the room. Give SDRs partial credit at a mid-funnel milestone rather than at handoff, and give AEs an accountability metric on working what they accept. Announce it before the technical change ships, so the two land together and nobody experiences the new routing as an unexplained quota threat.
Weeks 17–24: automate the easy cases and escalate the vendor conversation. Let the normalized score auto-route the clear cases and reserve the human queue for genuine ambiguity — you should be able to cut queue volume substantially. Simultaneously, take your disagreement data to the vendor. A conversation that starts with "our two products disagree on 18% of our handoffs, here is the distribution, here are 40 examples" gets a materially different response than one that starts with "your integration feels broken."
The reason this sequence works is that every phase produces value on its own. If you stop after week 4, you have a metric you did not have. If you stop after week 8, you have stopped the leakage. If you stop after week 16, you have a working normalization layer and aligned incentives. Nothing depends on the vendor doing anything, which is the point — the vendor's roadmap is the one variable you do not control.
Related questions
Does this only happen after an acquisition?
No. Any two intelligent tools scoring the same record on different objectives will diverge. Acquisition makes it worse because the shared vendor logo removes the assumption that a seam exists, and the integration budget usually disappears in the same planning cycle.
Can a CDP or unified data platform solve it?
Partially. A CDP unifies the underlying records so both systems see the same raw data. It does not reconcile the scoring logic layered on top. You still need a normalization layer that translates two incomparable scores into one comparable decision.
Should we just turn one co-pilot off?
Sometimes, yes — if one side's signals are genuinely redundant. But run it as an experiment on a slice of the team for a full sales cycle before deciding. Turning off the AE-side filter often surfaces a win-rate problem two quarters later.
How do we detect orphaned leads today, before building anything?
Query for records marked handed off with no AE activity within a defined window — 72 hours is a reasonable first cut. Run it weekly. That single report typically finds more revenue than the first month of any platform project.
Does the same pattern hit marketing-to-SDR handoffs?
Yes, and usually earlier. An MQL model and an outbound-prioritization model disagree constantly. Build your disagreement-detection layer with the seam as a parameter, not hardcoded to SDR→AE, and you will reuse it across three or four boundaries.
FAQ
What is the fastest thing I can do this week?
Log both scores on the same record at handoff and compute how often they disagree. No rules, no threshold changes, no vendor calls. Most teams have never seen this number, and seeing it reframes the entire conversation from a people problem into a measurable data problem with a known fix path.
How do I tell whether the SDR side is too loose or the AE side is too strict?
Hand-review a sample of forty to fifty bounced leads and judge each one yourself against your actual qualification bar. If most should have been worked, the AE filter is too strict. If most were genuinely unready, the SDR bar is too loose. If you cannot decide on a third of them, you have an ontology gap and neither threshold is the real problem.
Is middleware always necessary, or can this be done natively?
It depends on whether the platform exposes both scores on the same object with a hook you can act on. If it does, a native rule and a custom field are often enough. If the scores live in separate modules with separate data stores, you will need something outside both to read, normalize, and route. Check the native path first — it is cheaper to maintain.
How long should a human review queue stay in place?
Indefinitely, but shrinking. The queue's purpose shifts over time: at first it catches everything ambiguous, and later it handles only the genuinely hard cases the normalization layer cannot resolve. Aim to cut its volume substantially by month six, but do not plan to eliminate it. Genuine ambiguity does not go to zero.
What should we have asked the vendor before signing the consolidation deal?
Whether the two products share a data model today, and if not, the named release in which they will. Ask for it in writing. Also ask whether both scores are exposed on the same record via API, because that single answer determines whether your interim fix takes two weeks or two quarters.
Does fixing this require a data engineer?
For the first two phases, no — a capable RevOps analyst can instrument the seam and stand up a review gate. The normalization layer benefits from someone comfortable with distributions and shadow testing. A full data model merge across two acquired platforms is genuine engineering work, and that is usually the vendor's job, not yours.
Sources
- Gartner — B2B Sales and Marketing Research
- Forrester — B2B Sales Research
- Salesforce Data Cloud
- HubSpot — Breeze AI
- Microsoft — Dynamics 365 Copilot for Sales
- Gong Labs
- Winning by Design — Revenue Architecture
- Workato — Integration Platform
- Tray.ai — Integration and Automation
- SaaStr
Related on PULSE
- What's the best alternative to BANT when BANT breaks down, and when do you switch?
- What breaks first when you hire reps faster than you can train them?
- How do you validate 2027 intent data when the same AI tool generates both supply and demand?
- What's the core tension between founder pricing authority and CFO/FPA governance in a growing B2B org — and how do you structure CPQ so both stakeholders feel they own the output?
- How do you attribute CHIEF executive introduction requests to bookings vs billings in Dynamics 365 during renewal-only CS motion when broken lead routing across brands breaks reporting and strict IT security review blocks integrations?
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 revopsHow Do I Reconcile Competing Sales Forecasting Methods in 2027?
 revopsHow do you operationalize net revenue retention in 2027?
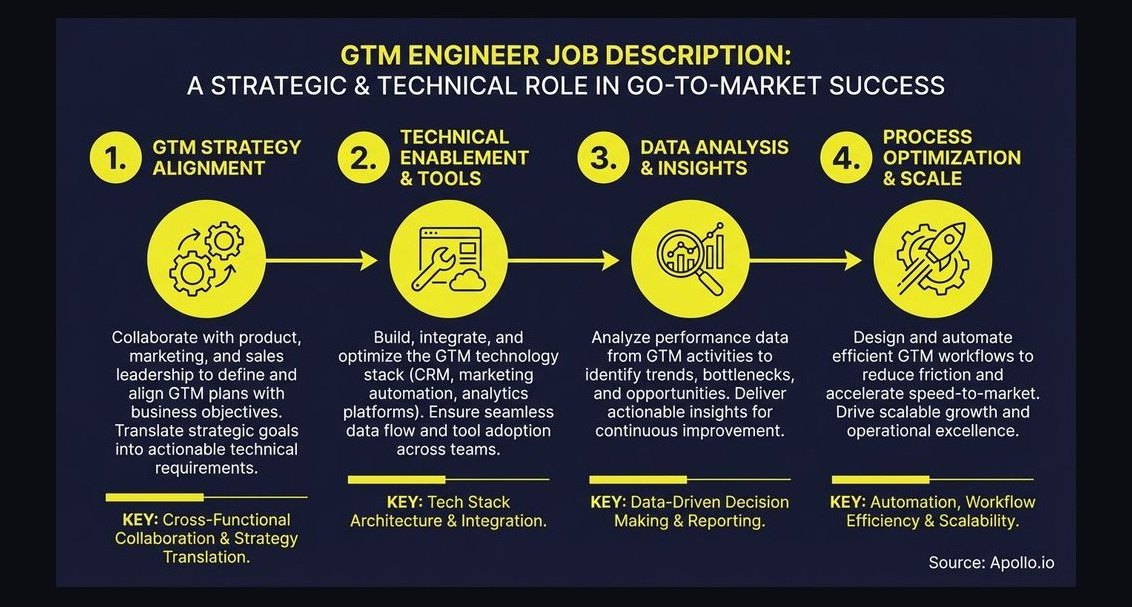 revopsWhat is a GTM engineer and why is the role exploding in 2027?
 revopsHow Do I Build a Board-Ready GTM Efficiency Dashboard in 2027?
 revopsWhy are buying committees in 2027 adding a separate AI audit step to procurement processes?
 revopsWhy are 2027 sales cycles 40% longer for AI-native product launches?
 revopsHow does vendor consolidation impact sales tech stack integration costs in 2027?
 revopsWhich AI in the funnel features are buying committees in 2027 treating as non-negotiable?
 revopsHow is AI in the funnel reshaping the scoring of B2B inbound leads in 2027?
 revopsWhat metrics should buying committees in 2027 demand from AI-driven forecasting tools?