
What are the best strategies for organizing digital resources so you can find them fast in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
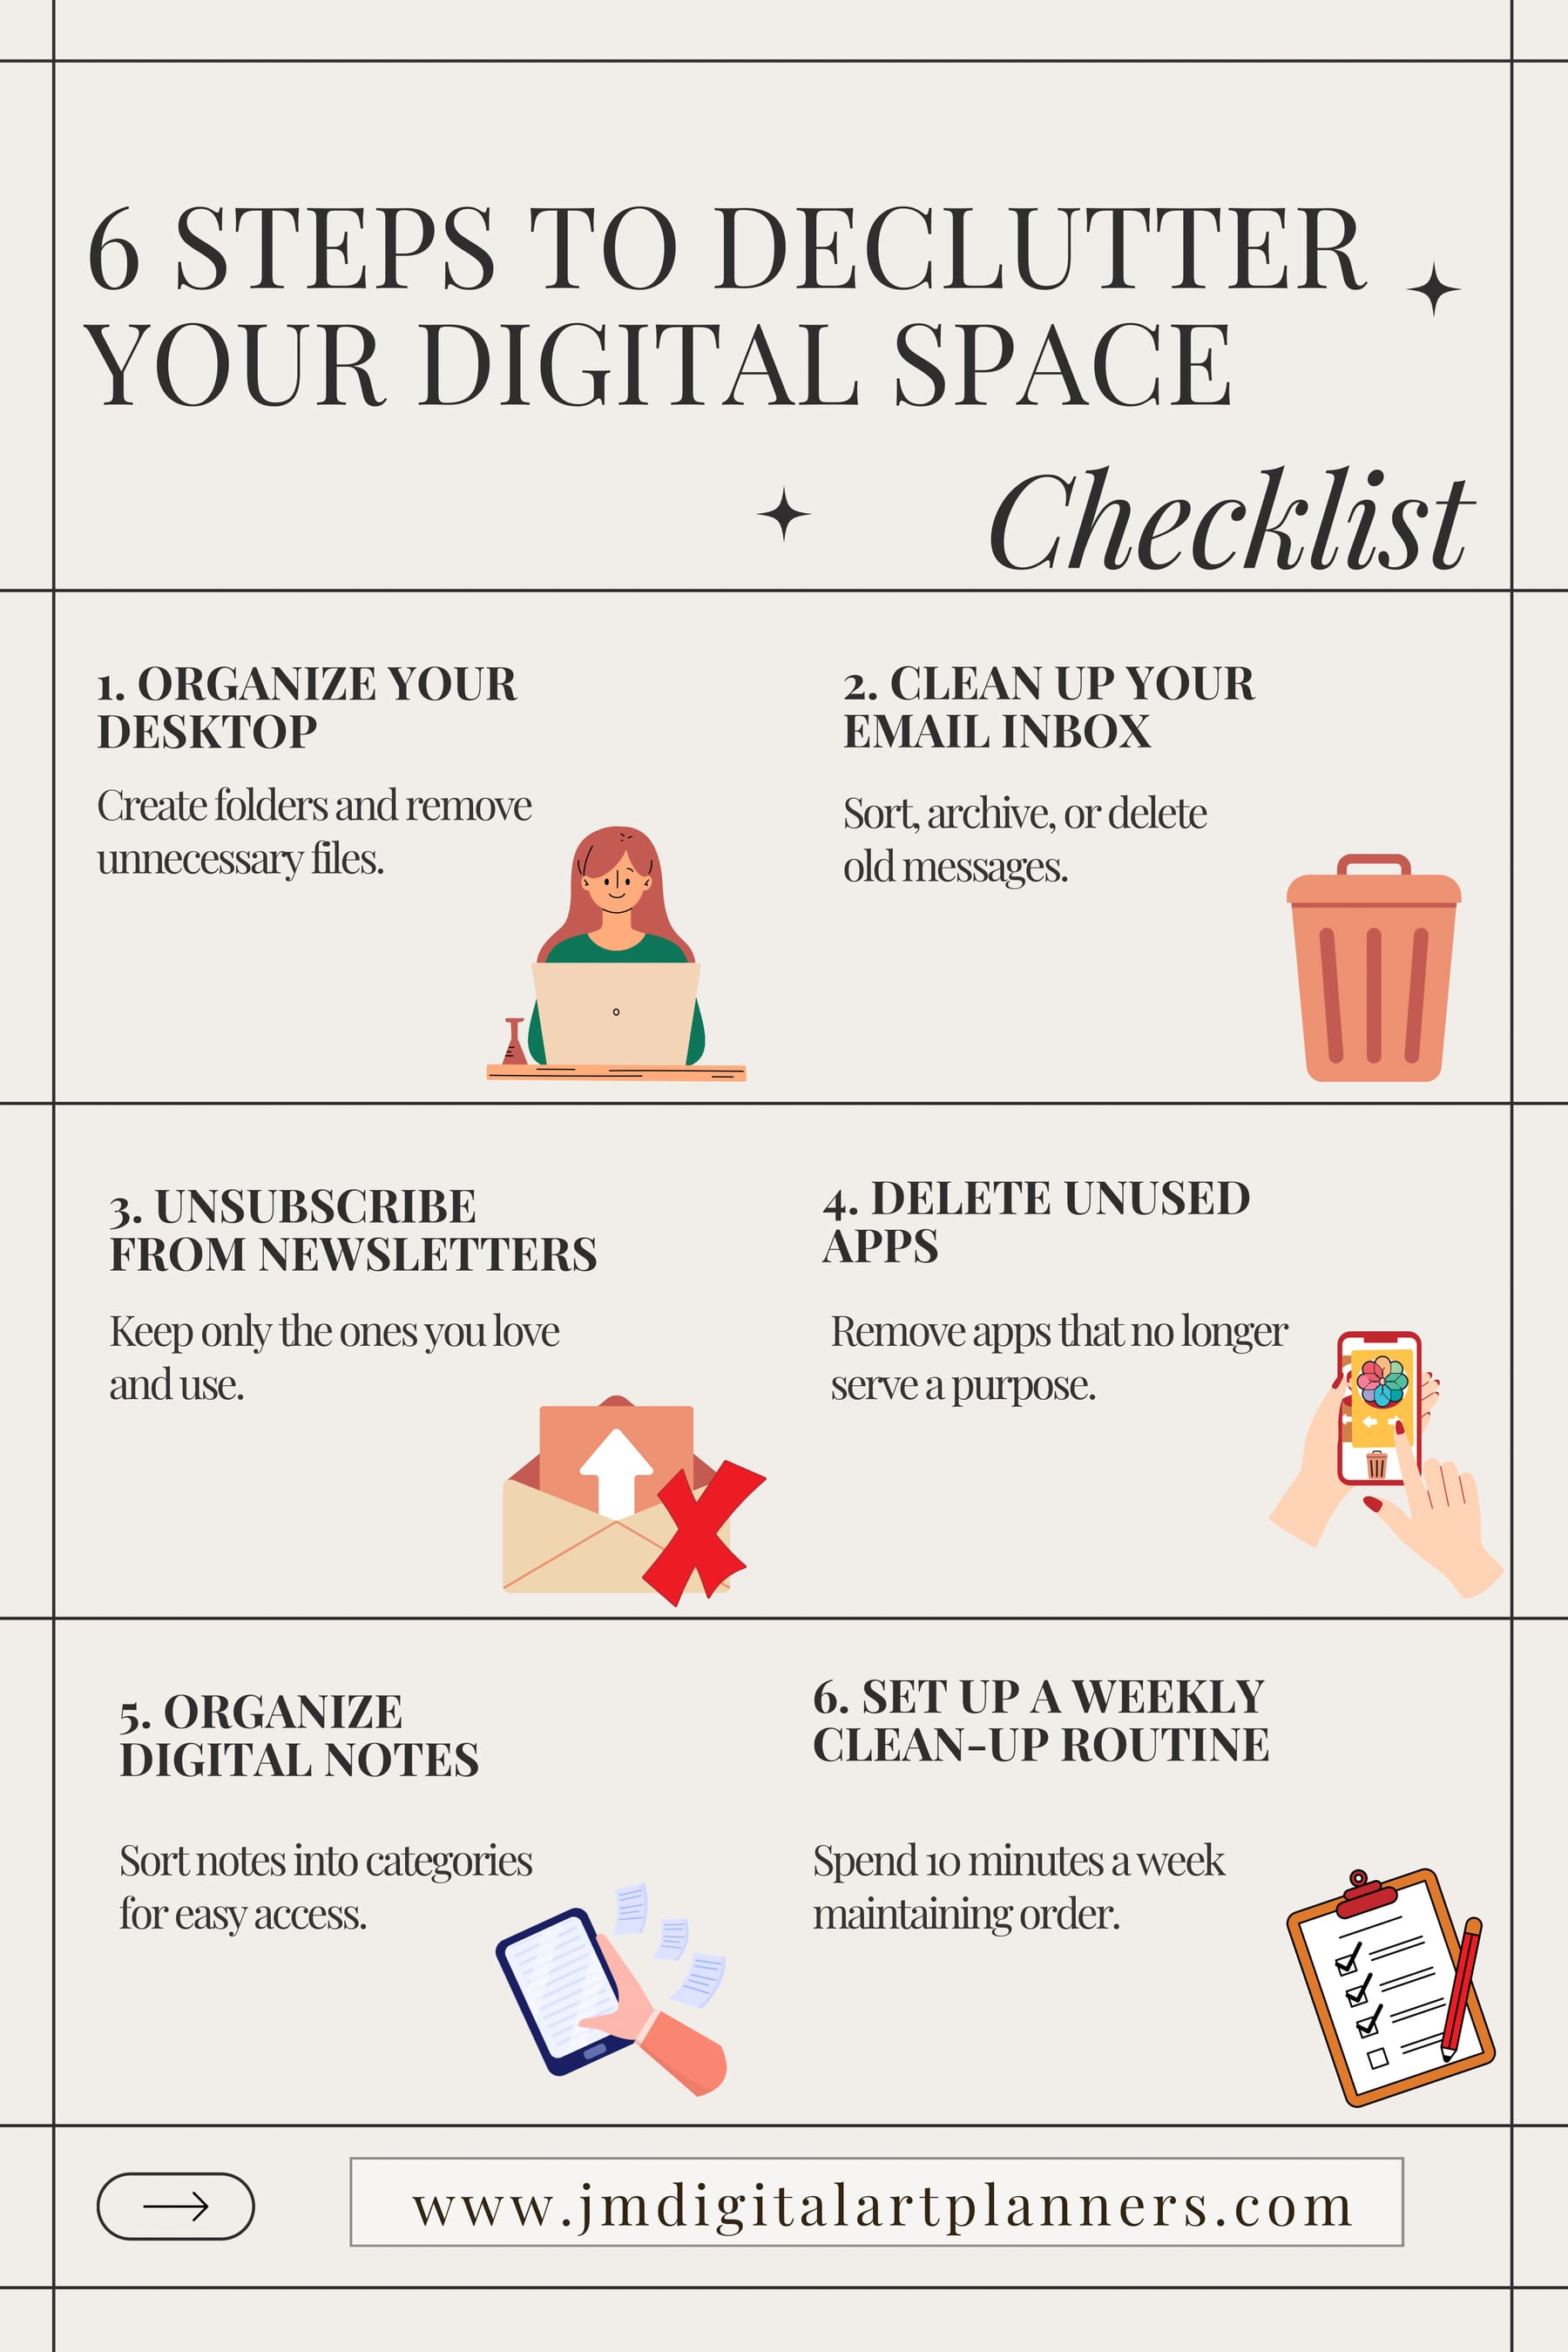
The fastest digital resource organization combines a flat storage layer with structured metadata, a strict naming convention, and automated tagging at upload. Skip deep folder trees. Tag once, search always. Teams that standardize 15–25 metadata fields and enforce naming at intake typically cut retrieval from minutes to seconds, because search replaces navigation entirely.
The two architectures, side by side
Every digital resource system in the wild is some blend of two philosophies, and understanding where each one breaks is more useful than picking a winner in the abstract.
Hierarchical folder trees encode meaning in position. A file's location *is* its metadata: Clients > Acme > 2027 > Proposals > Final. The advantage is that it requires zero training — every knowledge worker since 1995 has understood a nested folder. Browsing is genuinely useful when you don't know what you're looking for, and permissions map cleanly onto folder boundaries, which is why IT departments love them. A new hire can open the tree and infer how the business thinks about its own work.
The failure mode is dimensional. A folder path forces you to commit to *one* primary axis of organization at creation time. Is a signed MSA filed under the client, under the year, under "contracts," or under the deal it closed? Whichever you pick, the other three retrieval paths are now dead ends. Multiply that ambiguity across a ten-person team and you get the classic symptom: three copies of the same asset in three plausible locations, each slightly different in version, none authoritative. Depth compounds the problem — each additional nesting level multiplies the number of wrong turns a searcher can take, and past three or four levels people stop browsing and start guessing.
Flat metadata-driven systems invert the model. Resources live in one undifferentiated container — an object store bucket, a database table, a digital asset manager's library — and *all* meaning lives in attributes attached to the record: client, document type, owner, status, effective date, confidentiality level, related deal, language, region. Retrieval becomes a filtered query rather than a walk down a path. Because a record can carry unlimited attributes, the same MSA is simultaneously findable by client, by year, by type, and by deal — no commitment, no dead ends.
The cost is discipline. A flat system with bad metadata is strictly worse than a mediocre folder tree, because there is no fallback navigation. If nobody tagged the file, it is effectively invisible. This is the single most important trade-off to internalize: hierarchies degrade gracefully and metadata systems degrade catastrophically. That's why the implementation sequencing later in this piece leads with governance rather than tooling.
The hybrid most mature teams actually run. In practice, almost nobody ships a purely flat system. The common pattern is a *shallow* hierarchy — one or two levels, usually by business unit or by security boundary — with metadata carrying everything below that. The shallow layer solves permissions and mental orientation; the metadata layer solves retrieval. Google Drive shared drives, SharePoint document libraries with managed columns, and most DAM platforms all nudge you toward exactly this shape. Treat folders as *access control containers*, not as a filing system, and the tension largely dissolves.
There's a third architecture worth naming because it's arriving fast: semantic/vector retrieval, where an embedding model indexes the *contents* of documents so you can search by meaning rather than by attribute. This doesn't replace metadata — it complements it. Metadata answers "show me every executed contract for this client"; semantic search answers "where's that doc where we described the renewal-risk scoring logic?" The strongest 2027 setups run both: structured filters to narrow the candidate set, semantic ranking to order what's left. Anyone building internal AI assistants or RAG pipelines will recognize this as the same architecture, because it is — an internal knowledge assistant is just resource retrieval with a language model on top, and it inherits every weakness of your metadata hygiene.
How to decide between them
The decision isn't taste. It's a function of three measurable variables: how many resources you hold, how many people touch them, and how often retrieval happens.
Volume. Under roughly 500 resources, a disciplined two-level folder structure plus a naming convention will serve you well and cost nothing. Above that, the number of plausible-but-wrong locations grows faster than anyone's memory of where things go. The threshold isn't magic — it's the point at which a person can no longer hold the tree in their head.
Team size. The moment more than three or four people file into the same space, folder navigation becomes a coordination problem rather than an individual one. Each person builds a slightly different mental model of the tree, and those models drift. Metadata eliminates the drift because there's one record with many labels instead of many copies in many places.
Search frequency. If someone hits the library twenty-plus times a day — sales reps pulling collateral mid-call, ops pulling process docs, marketers pulling approved assets — every saved second compounds. At low frequency, the migration cost may genuinely exceed the benefit. Be honest about which regime you're in.
Two secondary factors that override the above. First, regulatory or audit exposure: if you need to prove retention, chain of custody, or who approved what, you need structured metadata regardless of volume, because a folder path can't record an approval state. Second, external collaboration volume: heavy client-facing sharing pushes you toward metadata, since you'll want a clean, attribute-driven way to generate share links without exposing internal structure.
A useful rule of thumb for a mixed environment: pick metadata for anything with a lifecycle (contracts, proposals, approved creative, policies) and leave pure folders for ephemeral working files (drafts, scratch exports, meeting scraps). Working files don't need retrieval infrastructure — they need a delete policy.
What the numbers actually look like
Vendor case studies are noisy, so anchor on measurements you can take yourself. These are the metrics that matter, with realistic target ranges rather than borrowed statistics.
Time-to-first-result. Instrument it crudely: pick ten resources people commonly need, ask three team members to find each, and time them with a stopwatch. In a broken folder system you'll routinely see 45–120 seconds per lookup, plus the failures where the person gives up and Slacks a colleague — which costs *two* people's time and is the hidden expense nobody tracks. A healthy metadata system should land the 90th-percentile lookup under about ten seconds. Anything above thirty seconds at the median means the taxonomy doesn't match how people actually think about the work.
Metadata completeness rate. The percentage of resources with every required field populated. Track it weekly; it's the leading indicator for everything else. Below about 90% completeness, trust erodes — people start assuming search is unreliable and revert to asking humans, at which point the system is dead regardless of what the dashboard says. Above 95%, search becomes the default reflex. Note the asymmetry: completeness falls slowly and trust falls fast, so treat any downward trend as urgent.
Duplicate ratio. Count near-identical files (same name stem, different suffixes like _v2_final_FINAL). In an unmanaged folder tree it's common to find 15–30% of storage is duplicates and stale versions. A version policy — keep the current plus two prior, archive the rest — collapses this quickly and makes every search result list shorter and more decisive.
Access recency. What share of the library hasn't been opened in twelve months? In most libraries the answer is uncomfortable: the large majority of files are never touched again after their first month. That long tail isn't harmful in storage cost — storage is cheap — it's harmful as *search noise*. Archiving cold resources out of the primary index is one of the highest-leverage, lowest-risk moves available, because it improves relevance without anyone having to change behavior.
The 20/80 concentration. Access logs almost always show a small fraction of resources absorbing most retrieval traffic. This is the single most actionable pattern in the whole exercise: it means you do not need to perfectly tag everything to get most of the benefit. Tag the hot set by hand, automate the rest, and you capture the bulk of the value in a fraction of the effort. Pull your platform's access report before planning any migration — it will tell you exactly which few hundred files to prioritize.
Cost framing. Convert time to money for the business case: hours lost per person per week to searching, times headcount, times loaded hourly rate. Even conservative assumptions produce a number that dwarfs the license cost of any DAM or knowledge platform. Present the *time* figure alongside the money figure, because leadership responds to "our reps lose two hours a week to hunting for collateral" more reliably than to a spreadsheet.
Implementation details and sequencing
Migrations fail when they start with tooling. Start with the taxonomy, prove it on a slice, then automate.
Phase 1 — audit before you touch anything. Export the file inventory and, critically, the access log. You want three columns: resource, last accessed, access count. Sort by access count descending. The top slice of that list is your pilot scope. Do not attempt a big-bang migration of everything; it's the most common way these projects die.
Phase 2 — design the taxonomy. Aim for 15–25 total fields, of which only 5–8 are *required*. Required fields should be the ones you'd filter on in a hurry: document type, owner, client or account, status, effective date. Everything else is optional enrichment. The discipline here is subtractive — every required field is a tax on every future upload, and each one you add slightly lowers your completeness rate forever. Use controlled vocabularies (dropdowns) rather than free text wherever possible; free-text tags fragment into Q3, q3, Q3-2027, and Quarter 3 within a month.
Design the *values* as carefully as the fields. A "status" field with fourteen options will be used wrong; four or five states (draft, in review, approved, superseded, archived) covers nearly every real workflow.
Phase 3 — the naming convention. This is the cheapest insurance you will ever buy, and it works even when metadata fails. Use a consistent pattern like [DocumentType]_[Client]_[YYYY-MM-DD]_[Version] — for example Proposal_AcmeCorp_2027-03-15_v2.1.pdf. Three rules make it stick: ISO dates only (2027-03-15, never 3/15/27) so chronological sort works everywhere; no spaces or special characters, since they break URLs and command-line tooling; and version numbers rather than words, because final_FINAL_v3_real is what happens when you allow adjectives. A file with a compliant name is findable by plain substring search even in a system with no metadata at all — that's your fallback layer when the primary one degrades.
Phase 4 — automate at the point of intake. Manual tagging never survives contact with a busy quarter. Wire automation into upload: extract the client from the filename, infer document type from the source folder or file extension, stamp the uploader as owner, set the date automatically. Native platform automations, workflow tools, or a small script against the platform API all work — the choice matters far less than the principle, which is that *the human should confirm metadata, not author it*. Every field you can derive is a field that will always be populated.
For text-heavy libraries, this is also where you add a content-extraction step: OCR scanned PDFs, pull text from documents, and index it. Untranscribed scans are a large invisible hole in most libraries — they exist, they're relevant, and no search will ever surface them.
Phase 5 — migrate the tail. With the hot set proven and intake automated, bulk-process the remainder. Two passes: an automated one that infers metadata from existing folder paths (the old hierarchy is itself a metadata source — the fact that a file lived in Clients/Acme/Contracts tells you two fields for free), then a human spot-check on a sample to measure accuracy. If the inferred accuracy is above roughly 90%, ship it and fix errors as they surface. If it's lower, your old tree was inconsistent and you're better off archiving the tail and tagging on demand as items get requested.
Phase 6 — governance, or it all decays. Name a taxonomy steward — one person, not a committee — who owns the field list and reviews new values. Run a quarterly audit against completeness and duplicate ratio. Set an automatic archive policy for resources untouched in twelve months, with a notification to the owner and a grace period before anything moves. Archived does not mean deleted; it means removed from the primary search index so it stops competing with live material.
Two failure modes to watch for specifically. Taxonomy sprawl: fields multiply because every request for "just one more tag" sounds reasonable in isolation. Cap the field count and force trade-offs. Shadow libraries: when the official system is slow or annoying, teams quietly start a parallel folder in someone's personal drive. That's not a discipline problem, it's a usability signal — find out what the official path made hard and fix that, rather than sending a reminder email.
Where this connects to the rest of the operation
Resource organization looks like an IT housekeeping chore and is actually a revenue-adjacent system, because the same metadata layer feeds several downstream workflows.
Sales enablement. A rep on a live call needs the right one-pager in under ten seconds. If your collateral carries industry, deal stage, persona, and approval status as structured fields, you can surface exactly the right asset from inside the CRM, filtered to what's currently approved. Without that, reps recycle whatever PDF is in their downloads folder, which is how out-of-date pricing reaches prospects. The approval status field is doing compliance work, not just organizational work.
Onboarding. New hires are the best diagnostic instrument you have. They don't know where anything lives, so their search behavior in week one reveals precisely which parts of the taxonomy match reality and which encode institutional trivia. Sit with one new person and watch them search for five common things; you'll learn more than a quarter of audits.
AI assistants and RAG. Any internal chatbot or retrieval-augmented system is only as good as the corpus it indexes. Stale duplicates make it confidently wrong — it will happily cite the superseded contract because nothing told it which version won. Metadata fields like status: superseded and effective_date are what let a retrieval layer filter to current truth. Teams planning AI initiatives for 2027 should treat library hygiene as a prerequisite rather than a follow-on project, because the cleanup is the expensive part and the model integration is comparatively trivial.
Compliance and audit. Retention schedules, access logs, and approval trails are metadata problems. A folder path cannot tell you who approved a document or when it expires; a field can. If you operate anywhere with data-retention obligations, structured metadata converts audit prep from an archaeology project into a saved search.
External sharing. Build a deliberate path for outbound assets that strips internal fields before sharing. Nobody outside your company should see deal_stage: negotiation or internal reviewer notes riding along in file properties. A simple export step that generates a clean copy — flattened, internal fields removed — prevents an embarrassing and entirely avoidable leak.
Adjacent domains use the same playbook. Photo and video libraries add technical fields (resolution, usage rights, expiry on licensed imagery — an expired stock license is a legal problem hiding in a metadata gap). Codebases solve it with monorepos plus rigorous naming and searchable symbols, which is the flat-plus-metadata pattern in a different costume. Research and clinical teams add provenance chains. The underlying principle is constant: flat storage, rich attributes, ruthless deprecation of stale items, and search as the default motion.
Related questions
How long does a metadata migration typically take?
For a library under 5,000 resources with a clear hot set, plan four to eight weeks: one week auditing, one to two designing and piloting taxonomy, two to three automating intake, and the rest on tail migration. The tail is where estimates slip.
Do I need a dedicated DAM, or will my existing tools work?
Most teams under about 5,000 assets can succeed with Google Drive, SharePoint, Notion, or Airtable using custom fields. A dedicated DAM earns its cost when you need rights management, renditions, or brand approval workflows — not merely when you have lots of files.
What happens to the old folder structure after migration?
Freeze it read-only for at least one quarter rather than deleting it. It's your rollback path and a useful metadata source. Once the new system's completeness rate holds above 95% and nobody has requested the archive in months, retire it.
Should tags be free text or controlled vocabularies?
Controlled vocabularies for anything you filter on — free text fragments into near-duplicate variants within weeks. Reserve free text for a single optional "notes" or "keywords" field where full-text search can still reach it.
How do you keep the system working after the person who built it leaves?
Document the field list and its rationale in a page linked from the library itself, and name a successor steward before the current one departs. Undocumented taxonomies decay within two quarters of their author leaving.
FAQ
What is the single highest-impact change for organizing digital resources?
Enforcing a naming convention at the moment of creation. It costs nothing, requires no platform, and works as a fallback even when metadata is missing or the tooling changes. Metadata delivers more ceiling, but naming delivers the fastest floor — and it survives every migration you'll ever do.
How do you handle legacy resources already buried in folders?
Prioritize by access frequency, not by folder order. Pull the access log, hand-tag the frequently used top slice, and infer metadata for the remainder from their existing folder paths. Anything untouched in over a year goes straight to archive without tagging — you can always tag it on demand if someone actually asks for it.
How do you get a team to follow tagging standards consistently?
Make tagging part of the upload flow rather than a separate chore, pre-populate every field you can derive automatically, and keep the required-field count at five or fewer. Then close the loop: when someone can't find something, trace it back to the missing field and fix the intake step. Reminder emails don't change behavior; reduced friction does.
Does AI-powered semantic search make metadata obsolete?
No — it makes metadata more valuable. Semantic search is excellent at "find the doc that discussed X" and poor at "show me every currently-approved contract for this account," which is a structured filter. Retrieval systems also need status and date fields to avoid confidently surfacing superseded versions. Run both layers together.
How should versioning work in a metadata system?
Keep the current version plus two prior, mark older ones superseded, and exclude superseded items from default search results while keeping them retrievable. Never encode version state in the filename alone with words like "final" — use numbered versions in the name and authoritative status in a field.
What's the right cadence for auditing the system?
Weekly automated checks on completeness rate and duplicate count, quarterly human review of the taxonomy itself, and annual archiving of cold resources. The weekly automated check is the one that matters most — completeness declines gradually and is far cheaper to correct at 93% than at 70%.
Sources
- https://hbr.org/2022/09/how-to-organize-your-digital-files
- https://www.cio.com/article/228640/digital-asset-management-best-practices.html
- https://support.google.com/drive/answer/2375091
- https://learn.microsoft.com/en-us/sharepoint/managed-metadata
- https://www.nist.gov/publications/guidelines-media-sanitization
- https://www.archives.gov/records-mgmt/policy
- https://www.dublincore.org/specifications/dublin-core/dcmi-terms/
- https://www.smartsheet.com/content/digital-file-organization-best-practices
- https://www.techrepublic.com/article/how-to-organize-digital-files/
Related on PULSE
- [What are the best strategies for grading essays without taking them home in 2027](/knowledge/tr2)
- [What are the best methods for providing accommodations during a whole-class assessment in 2027](/knowledge/tr20)
- [How do you structure a math block to include direct instruction, guided practice, and independent work](/knowledge/tr19)
- [What are the best tools for tracking student behavior data without a complicated system in 2027](/knowledge/tr18)
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 pulse-teacher-resourcesWhat are the top 10 concrete steps to create a parent-teacher communication calendar that stays on track in 2027
 pulse-teacher-resourcesWhat are the top 10 concrete steps to create a grading scale that is fair across all assignment types in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to make your lesson plans more engaging for reluctant learners in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to create a differentiated homework policy that respects all learners in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to create a weekly parent communication log that is easy to maintain in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to create a lesson plan that meets 504 plan requirements in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to use formative assessment data to adjust your lesson plan mid-class in 2027
 pulse-teacher-resourcesWhat are the top 10 ways to create a classroom management plan that works for a new teacher in 2027
 pulse-teacher-resourcesWhat are the top 10 concrete steps to create a differentiated lesson plan for mixed-ability classrooms in 2027
 pulse-teacher-resourcesHow do you design a unit plan that naturally incorporates spiral review