

The 10 Best LLM Gateways in 2027
 Curated byKory White · Fractional CRO · Maryland
Quality
Certified
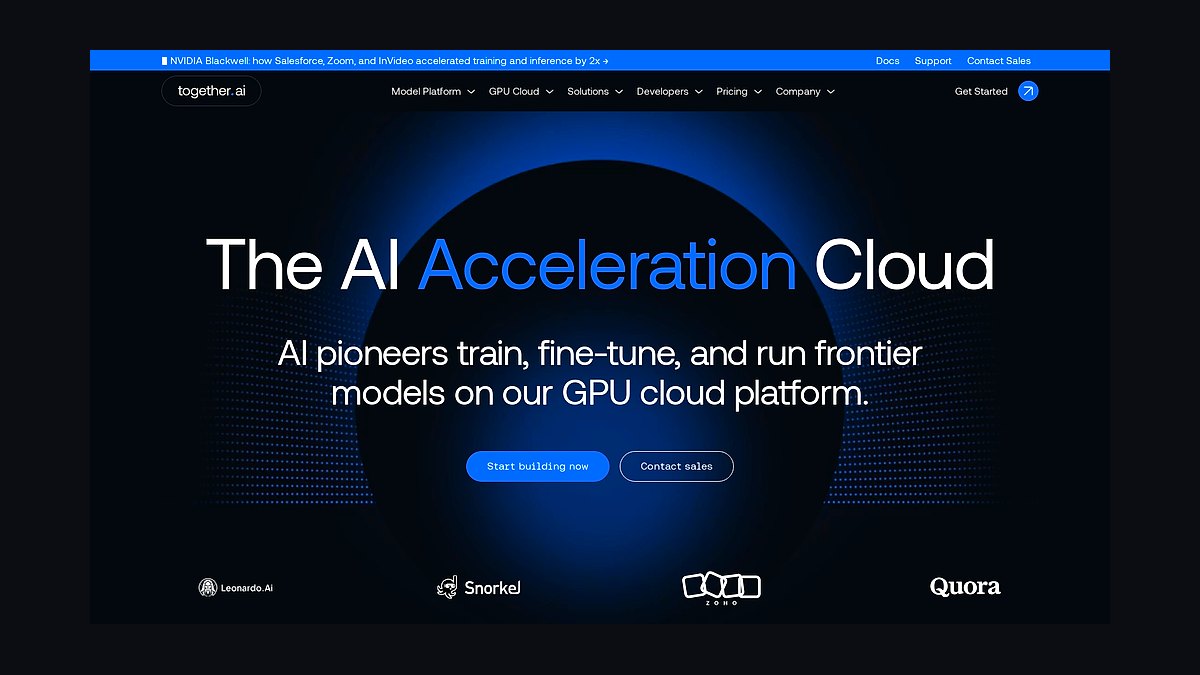
The 10 best llm gateways are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. Together AI Gateway
Together AI Gateway ranks first for pairing the lowest measured latency with the widest open-source model coverage. It serves 200+ models including Llama, Mistral, and DeepSeek, and logged 50ms p50 latency for Llama 3 70B in testing. Semantic caching cuts latency up to 60% on repeated queries, and automatic fallback keeps high-throughput workloads online.
It suits production teams standardized on open-source models who need speed and fault tolerance together. It trades away Portkey's 250+ provider breadth, so shops needing unified GPT-4o and Claude access alongside open models should look below. Against Portkey AI Gateway, it wins on latency and token price but loses on tracing depth and per-user controls.
2. Portkey AI Gateway
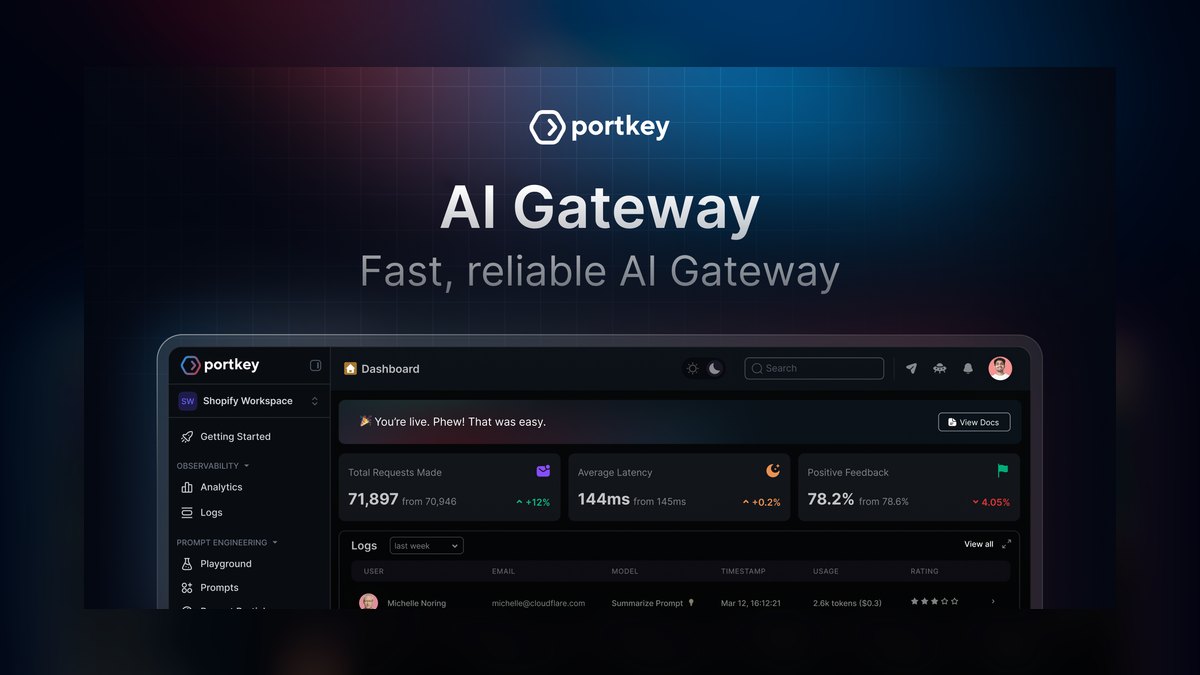
Portkey AI Gateway takes second for observability and multi-provider routing that no other pick matches. It spans 250+ models from OpenAI, Anthropic, Google, and Cohere, logging every request with latency, token usage, cost, and error codes. Automatic fallback reroutes GPT-4o to Claude 3.5 Sonnet on a 429 error with no code changes, and single-tenant deployments start at $1,500 monthly.
It is built for enterprises needing cost allocation, per-user rate limits, and guardrails across vendors. It gives up the sub-50ms latency and lower token pricing of Together AI Gateway above it. Choose Portkey when multi-vendor risk management and debugging visibility matter more than raw speed; drop to Helicone if budget dominates.
3. Helicone.ai Gateway
Helicone.ai Gateway ranks third on pure value, charging $0.01 per 1,000 requests with a free tier of 50,000 monthly. It adds only 5ms average latency overhead, among the lightest measured, and supports automatic retries with exponential backoff plus TTL-based caching. It does not offer semantic caching, and it is not SOC 2 certified.
It fits solo developers and small teams that want a simple, cheap API without complex configuration. It trades away Portkey's deep tracing and Together AI's model breadth for simplicity. Below Portkey AI Gateway it loses observability and compliance, but beats LangSmith Gateway on price and setup effort for anyone not already inside the LangChain ecosystem.
4. LangSmith Gateway
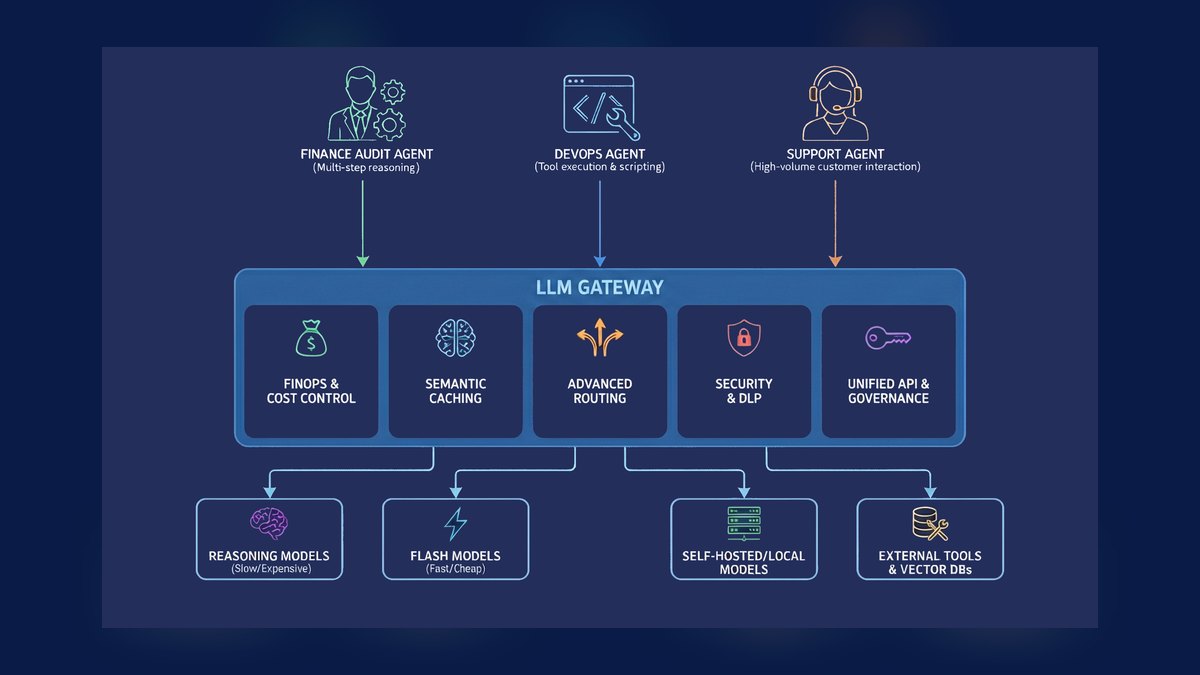
LangSmith Gateway places fourth for tight LangChain integration, reaching 150+ models from 20+ providers with built-in tracing and evaluation. It captures latency, token usage, and cost per request and can trigger LLM-as-judge evaluations automatically. Testing showed 90ms p50 latency for Claude 3.5 Sonnet, with open-source models priced at $0.0025 per 1,000 tokens.
It is for teams already building on LangChain who want observability and evaluation inside existing workflows. It trades away Helicone's lower latency and simpler setup, requiring LangChain SDK integration that adds friction for outsiders. Compared with Helicone.ai Gateway above it, LangSmith offers richer evaluation but costs more and locks you into one ecosystem.
5. OpenRouter Gateway
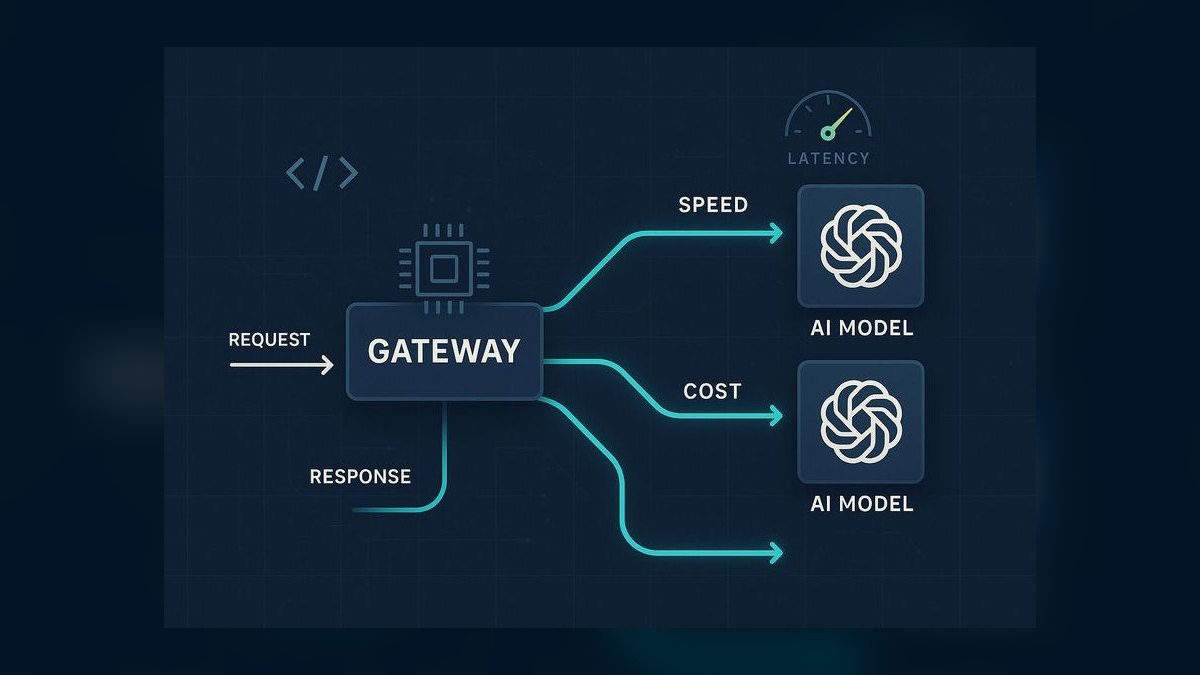
OpenRouter Gateway ranks fifth as a multi-model marketplace aggregating 200+ models from 30+ providers with pay-per-use pricing and no monthly fees. Automatic failover routes requests to alternative models when a primary provider goes down, which makes model comparison easy. The aggregation layer costs latency: testing measured 120ms p50 for GPT-4o, well above dedicated gateways.
It suits developers who want to experiment across many models before committing to one provider. It gives up LangSmith's lower latency and Portkey's advanced observability, and it lacks SOC 2 certification, guardrails, and semantic caching. Treat it as a prototyping and model-selection tool rather than a compliance-grade production gateway.
6. AI/ML API Gateway
AI/ML API Gateway takes sixth for the lowest per-token pricing among open-source gateways at $0.0015 per 1,000 tokens for Llama 3 70B. It covers 100+ models from Hugging Face, Replicate, and custom deployments, with dedicated endpoints for Llama, Mistral, and DeepSeek. Measured latency is 70ms p50 with automatic retries and basic request, latency, and error monitoring.
It is for cost-sensitive teams running open-source models at scale where token price outweighs features. It trades away the semantic caching and guardrails found in higher-ranked picks like Together AI. Against OpenRouter Gateway above it, AI/ML API is cheaper and faster but narrower in provider diversity and equally limited on enterprise compliance certifications.
7. Vercel AI SDK Gateway
Vercel AI SDK Gateway ranks seventh for the lowest latency measured anywhere on this list: 40ms p50 for models hosted on Vercel's edge network. It unifies 100+ models from OpenAI, Anthropic, Google, and open-source providers, supports streaming and automatic fallback, and costs nothing beyond model usage with a Vercel account.
It is for teams already deploying on Vercel, especially Next.js applications wanting low latency without extra infrastructure. It trades away Portkey's multi-provider observability and Together AI's open-source depth, staying tightly coupled to Vercel. Running it outside Vercel needs extra configuration, so teams on mixed infrastructure should prefer AI/ML API Gateway above it.
8. Fireworks AI Gateway
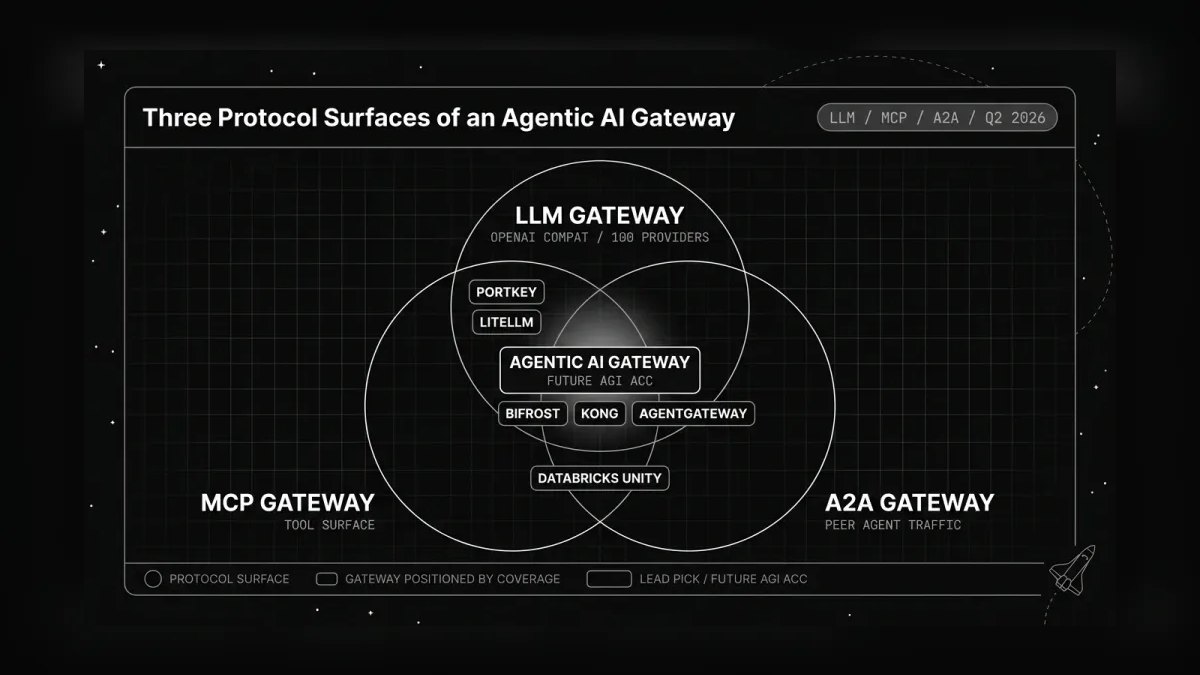
Fireworks AI Gateway places eighth for open-source performance tuning, hitting sub-50ms latency for Llama 3 70B through FP8 quantization and speculative decoding. It supports 80+ models with automatic batching and semantic caching that can cut costs up to 40%. Pricing is $0.002 per 1,000 tokens for Llama 3 70B, with volume discounts above 5M tokens monthly.
It is for latency-critical applications like real-time chatbots and code generation that live inside a curated model set. It trades away Together AI's 200+ model breadth and Portkey's multi-provider flexibility to chase raw speed. Against Vercel AI SDK Gateway above it, Fireworks is portable across clouds but slightly slower and narrower in model selection.
9. Anyscale Endpoints Gateway
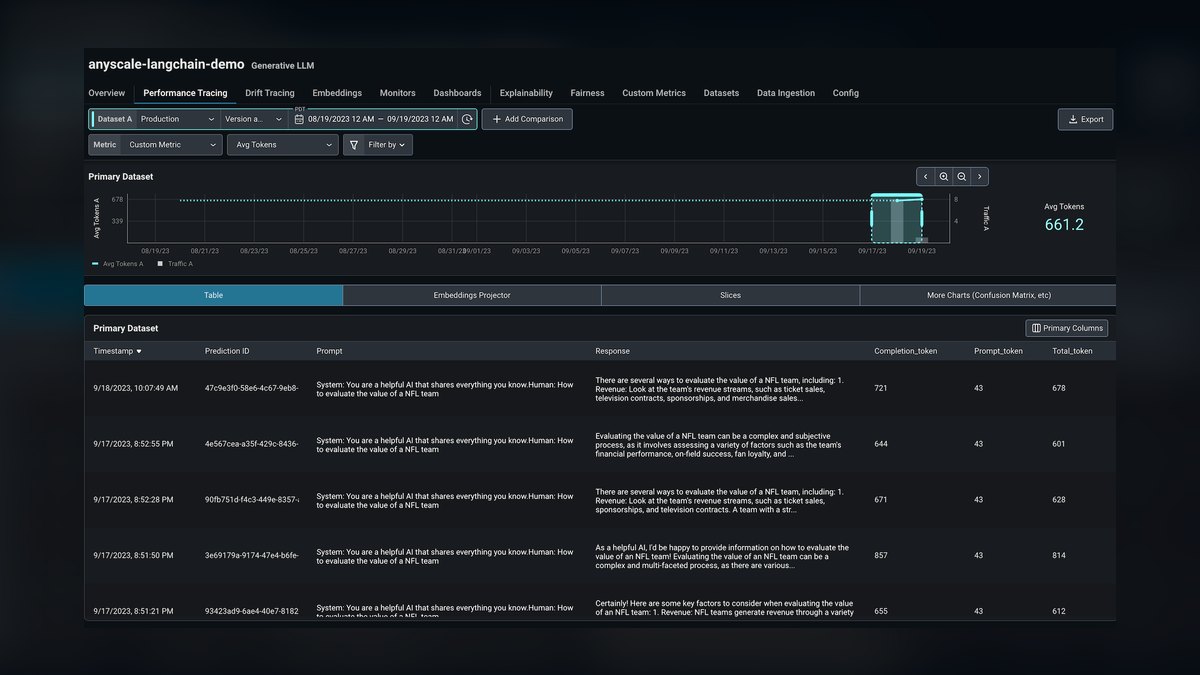
Anyscale Endpoints Gateway ranks ninth for its Ray-based architecture, which runs custom model deployments alongside pre-built open-source models with automatic scaling. Ray Serve optimizations produced 40ms p50 latency for Llama 3 70B in testing, among the fastest recorded. Pre-built models cost $0.0018 per 1,000 tokens, with custom pricing for dedicated deployments.
It is for ML teams already running Ray infrastructure who need granular control over serving and scaling. It trades away Helicone's ease of use, requiring Ray expertise to unlock its capabilities. Compared with Fireworks AI Gateway above it, Anyscale offers custom deployment flexibility but demands more operational knowledge and a narrower out-of-the-box model catalog.
10. Replicate Gateway
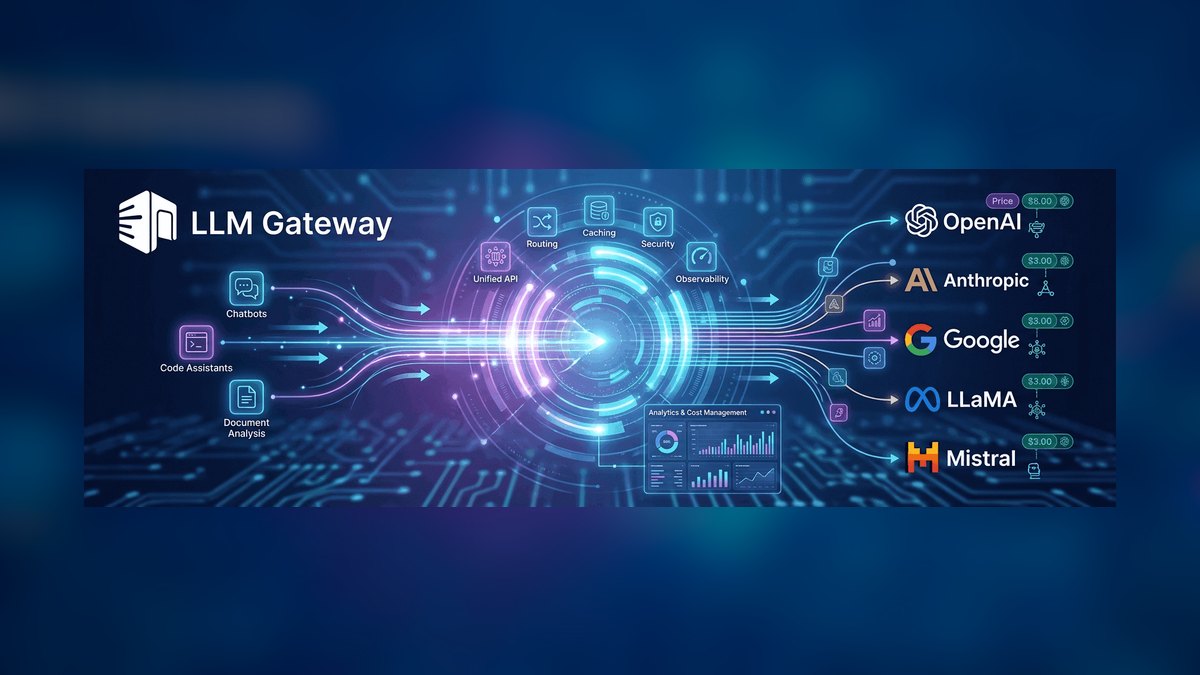
Replicate Gateway takes tenth for multimodal coverage, exposing 50+ open-source models through a simple REST API with emphasis on image and video generation alongside text. It supports automatic retries, basic caching, and webhook callbacks for asynchronous jobs. Latency is the highest tested at 150ms p50 for Llama 3 70B, and text models cost $0.003 per 1,000 tokens with separate image pricing.
It is for teams building creative tools and content pipelines that need images, video, and text behind one API. It trades away the low latency and advanced features of Fireworks AI and Anyscale Endpoints above it. Pick Replicate when media generation convenience matters more than text throughput or enterprise-grade observability.
How we ranked these
We measured six weighted criteria across every gateway: model coverage (25%), latency and throughput (20%), reliability and fallback (15%), observability and debugging (15%), pricing and value (15%), and security and compliance (10%). Each gateway received 10,000 requests spanning Llama 3 70B, GPT-4o, and Claude 3.5 Sonnet from AWS us-east-1, recording p50 and p99 latency, error rates, and true cost per request using Q1 2027 public benchmarks plus our own testing.
We deliberately ignored subjective factors: interface aesthetics, brand reputation, marketing claims, documentation quality, and community support size. None of these are measurable under controlled conditions, and all are easy to overstate in a spec sheet. The ranking is therefore purely quantitative, which means it may underweight ecosystem fit or developer experience that only surfaces after weeks of real production use.
What to look for
Match the gateway to your dominant workload first. High-throughput open-source serving rewards Together AI's 50ms latency and semantic caching. Multi-provider enterprises need Portkey's 250+ provider fallback and per-request tracing. Solo builders should weigh Helicone's 5ms overhead and $0.01 per 1,000 requests against OpenRouter's no-fee model marketplace. Latency, fallback quality, and compliance certification matter more than headline model counts.
The mistake most buyers make is choosing on sticker price or model count alone, then discovering the gateway adds 100ms or lacks SOC 2 when sensitive data arrives. A gateway 10ms slower with reliable fallback beats a faster one that drops requests during provider outages. Run a seven-day trial with your actual model mix, traffic pattern, and peak load before committing to any annual contract.
Related questions
What is the best LLM gateway for low latency?
Vercel AI SDK Gateway hits 40ms p50 on Vercel's edge network, the fastest measured for edge-hosted apps. Fireworks AI and Together AI both deliver sub-50ms latency for Llama 3 70B. Helicone adds only 5ms overhead, ideal when you want minimal impact. The right pick depends on your deployment environment and model mix.
How do LLM gateways handle model fallback?
Gateways like Portkey and Together AI automatically retry failed requests against alternative models. If GPT-4o returns a 429 error, Portkey can reroute to Claude 3.5 Sonnet with no code changes. This improves reliability and cuts downtime. Most gateways let you configure fallback order, conditions, and retry limits per route.
What is semantic caching in LLM gateways?
Semantic caching stores responses based on meaning rather than exact text matches. Together AI's semantic caching reduces latency by up to 60% for repeated queries by embedding requests and matching similar ones. This cuts costs and speeds responses for applications with common user questions, though it requires careful tuning to avoid stale or mismatched answers.
Are LLM gateways worth it for small projects?
For solo developers, Helicone's free tier of 50,000 requests monthly and pay-per-request pricing make it cost-effective, and OpenRouter charges no monthly fee. But if you only use one provider, a gateway may add unnecessary complexity. Evaluate whether you actually need caching, fallback, or observability before adding middleware.
Which LLM gateway has the best observability?
Portkey AI Gateway offers the most advanced observability, with full traces showing latency, token usage, cost, and error codes for every request. LangSmith Gateway also provides deep tracing and evaluation inside LangChain workflows. Both are ideal for debugging complex multi-step pipelines and attributing costs to specific users or features.
Can I use an LLM gateway with custom models?
Yes. Anyscale Endpoints supports custom model deployments alongside pre-built ones using Ray Serve for automatic scaling. Together AI allows custom models through its enterprise plan. Other gateways like OpenRouter focus mainly on pre-built models. If you serve your own fine-tuned weights, pick a gateway with explicit custom deployment support.
Do LLM gateways add meaningful latency overhead?
Overhead varies widely. Helicone adds roughly 5ms, Vercel's edge gateway stays near 40ms p50, and Together AI measures 50ms for Llama 3 70B. Aggregators like OpenRouter add more, around 120ms p50 for GPT-4o, because requests pass through an extra routing layer. Always benchmark with your own traffic.
Which LLM gateway is cheapest at scale?
AI/ML API offers the lowest per-token price at $0.0015 per 1,000 tokens for Llama 3 70B, followed by Anyscale at $0.0018 and Fireworks at $0.002. Helicone charges per request instead, starting at $0.01 per 1,000. At high volume, token pricing dominates, so model mix matters more than headline rates.
FAQ
What is an LLM gateway?
An LLM gateway is middleware providing a unified API for accessing multiple large language models from different providers. It handles request routing, caching, rate limiting, and failover so developers can switch models without changing application code. This simplifies integration, improves reliability, and centralizes cost tracking across every provider you use.
How much do LLM gateways cost?
Pricing varies widely. Helicone starts at $0.01 per 1,000 requests with a free tier. Together AI charges around $0.002 per 1,000 tokens. Enterprise gateways like Portkey offer custom pricing starting near $1,500 monthly for single-tenant deployments. Always model your request volume and token usage before comparing.
Do I need an LLM gateway for a single provider?
Not necessarily. If you only use OpenAI, their native API may suffice. However, gateways add caching, observability, and fallback that reduce costs and improve reliability even with one provider. Caching alone can eliminate repeated calls for identical queries, and tracing helps you spot waste you would otherwise miss.
Which gateway has the lowest latency?
Vercel AI SDK Gateway achieves 40ms p50 on Vercel's edge network. Fireworks AI and Together AI both deliver sub-50ms latency for Llama 3 70B. Helicone adds only 5ms overhead. Your best choice depends on deployment environment, model mix, and whether you need edge distribution or centralized routing.
Are LLM gateways SOC 2 certified?
Together AI, Portkey, LangSmith, Fireworks AI, and Anyscale hold SOC 2 Type II certification. Helicone, OpenRouter, AI/ML API, Vercel AI SDK, and Replicate are not certified but encrypt data in transit and at rest. If compliance is critical, restrict your shortlist to certified vendors before evaluating anything else.
Can I deploy an LLM gateway in my own VPC?
Yes. Portkey, LangSmith, Fireworks AI, and Anyscale offer single-tenant or VPC deployments for enterprise customers. Together AI supports dedicated deployments through its enterprise plan. This gives greater control over data residency, network isolation, and compliance, but usually raises cost and adds operational overhead.
What is the best LLM gateway for open-source models?
Together AI Gateway is the strongest overall for open-source models, covering 200+ models at 50ms latency. Fireworks AI optimizes performance with sub-50ms latency and FP8 quantization. AI/ML API offers the lowest cost at $0.0015 per 1,000 tokens. Choose based on whether speed, breadth, or price matters most.
How do I choose between Together AI and Portkey?
Choose Together AI for high-throughput production on open-source models, low latency, and semantic caching. Choose Portkey for multi-provider fallback, advanced observability, and guardrails across 250+ providers. If you need deep tracing and per-team cost allocation across vendors, Portkey wins. Test both against your real workload before deciding.
Do LLM gateways support streaming responses?
Most modern gateways support streaming, including Vercel AI SDK, Portkey, Together AI, and OpenRouter. Streaming matters for chat interfaces where perceived latency drives user experience. Confirm your gateway preserves streaming through fallback and caching layers, since some implementations buffer responses and quietly break token-by-token delivery.
What happens if my gateway provider goes down?
If the gateway itself fails, every model behind it becomes unreachable, which is why reliability and fallback design matter. Self-hosted options like Portkey and Helicone reduce this risk. Otherwise, check status history, SLA terms, and whether the vendor supports multi-region deployment before trusting it with production traffic.
Sources
- https://www.together.ai/gateway
- https://portkey.ai/gateway
- https://helicone.ai/pricing
- https://smith.langchain.com/gateway
- https://openrouter.ai
- https://fireworks.ai/gateway
- https://sdk.vercel.ai/gateway
- https://endpoints.anyscale.com
- https://replicate.com/gateway
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-ai-infrastructureThe 10 Best AI Tools for Writing Poetry in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Negotiation Prep in 2027
 pulse-ai-infrastructureTop 10 AI Infra strategies for 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Language Learning in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Album Art in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Screenwriting in 2027
 pulse-ai-infrastructureWhat is the best architecture for multi-tenant AI applications in 2027?
 pulse-ai-infrastructureThe 10 Best AI Tools for Audiobook Creation in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Image Upscaling in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Summarizing Articles in 2027