
How do longer sales cycles in 2027 affect the accuracy of quarter-end close predictions?
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
Quality
Certified
Longer cycles push more of the pipeline outside the quarter you are forecasting, so quarter-end predictions increasingly rest on deals whose signals are months stale. Accuracy degrades because stage probability assumes a 90-day horizon. RevOps restores it by scoring deal age, activity recency, and close-date stability separately from stage.
A quarter that looked safe until the last three weeks
Picture a mid-market software company entering the final month of a quarter with what looks like a healthy book. The commit number sits at $4.2M against a $3.8M target. Coverage is roughly 3.2x. Every deal in commit is in a late stage, every one has a close date inside the quarter, and the weighted pipeline model — the standard exercise of multiplying stage probability by amount — says the team lands somewhere between $3.9M and $4.4M. The forecast call is short. Nobody argues.
Three weeks later the quarter closes at $2.9M. Not because deals were lost. Almost nothing in that commit list came back marked Closed Lost. What happened instead is that seven of the nineteen commit deals moved their close dates into the following quarter, four of them for the second time. One waited on a security questionnaire that had been sitting with the buyer's infosec team since two months earlier. Two were paused while the buyer ran a broader review of overlapping tools they already owned. One lost its internal champion to a job change and had to restart the business case with a new sponsor who had never seen the original pitch. The rest just went quiet in the way deals go quiet when a buying group is deliberating internally and has nothing to say to a vendor yet.
Every one of those deals was, in stage terms, exactly where it had been at the start of the month. The CRM said "Negotiation." The stage probability said 80%. The forecast model dutifully multiplied. What the model could not see was that these deals had been in the pipeline for eight, ten, and in two cases fourteen months, and that the relationship between "reached late stage" and "closes in the next thirty days" had quietly broken for deals of that vintage. When cycles were six months long, reaching negotiation meant you were near the end of a short road. When cycles stretch past a year, reaching negotiation means you are near the end of one road and possibly at the start of another — legal review, procurement consolidation, budget re-approval in a new fiscal period.
This is the structural problem. Forecast accuracy in a short-cycle world came almost free, because the entire deal lifespan fit inside the forecast horizon. You could watch a deal from first meeting to signature within a single quarter and your intuition about it stayed fresh the whole way. In a long-cycle world, the forecast horizon is a narrow window onto a much longer process, and most of what determines whether a deal closes in your window happened outside it, months ago, in conversations you have no record of. The forecast is not wrong because the model is bad at math. It is wrong because it is being asked a question — will this close in the next N weeks — using inputs that were designed to answer a different one: is this deal real.
The scenario above also illustrates a second-order effect worth naming early. The miss was not $1.3M of lost revenue. Most of that $1.3M closed over the following two quarters. But the *reporting* treated it as a miss, which triggered a round of pipeline-generation panic, a marketing budget reallocation, and a set of quota conversations that were all responses to a problem that did not exist. Bad close-date prediction does not only produce a wrong number. It produces wrong decisions downstream, in hiring plans, in capacity models, in board narratives, and in the compensation conversations that follow a "missed" quarter.
How the mechanism actually works
The failure is mechanical, not mysterious. Trace it through and you can see exactly where the error enters.
A conventional weighted-pipeline forecast has three inputs per deal: amount, stage, and close date. Stage supplies probability through a lookup table calibrated on historical win rates — deals that reached Proposal historically closed X% of the time. Close date determines which quarter the deal lands in. Amount scales it. Sum across the commit set and you have a number.
Two of those three inputs are quietly unreliable once cycles lengthen. The stage-to-probability table is calibrated on a historical population whose cycle length differs from today's. If your table was built on deals that averaged seven months and your current pipeline averages eleven, the table's "Proposal = 60%" is describing a different animal than the one in front of you. It is not that 60% is too high or too low in the abstract — it is that the historical Proposal-stage deal was three months from a decision and yours is six months from one, and probability of closing *ever* is a different quantity from probability of closing *this quarter*. Conflating them is the root error.
The close date is worse, because it is not measured at all. It is asserted by a rep, often at deal creation, often as a default, and updated under pressure to keep deals in the current period. Close date is the only input in the model that determines quarter attribution, and it is the input with the least evidence behind it. When cycles were short, the rep's guess had a small error bar simply because there was less time available for the guess to be wrong. Stretch the cycle and the error bar widens with it.
The third mechanism is signal decay. Modern revenue-intelligence tooling improves on stage probability by scoring engagement — meeting cadence, email reciprocity, number of distinct contacts engaged, whether pricing and legal documents have been opened. These signals genuinely predict outcomes, but they predict them over a horizon roughly matched to how recent they are. Engagement from four weeks ago tells you a lot about the next four weeks. Engagement from seven months ago tells you very little about the next four weeks, and a model that treats old signals and fresh signals as equally informative will confidently produce a stale answer. Any scoring system applied to a long-cycle pipeline needs an explicit recency weighting, or it will keep scoring a deal on evidence from a phase of the process that has already ended.
The diagram makes the correction visible. Notice that stage does not appear as a gate anywhere in it. Stage is still useful for pipeline management and for coaching, but as a *timing* predictor in a long-cycle environment it carries less information than three things that most CRMs already record and most forecast models ignore: how long since the buyer last did something two-way, how many times the close date has moved, and whether the specific procedural artifacts that must exist before a signature actually exist.
That last gate deserves emphasis because it is the one that converts a soft forecast into a hard one. A deal cannot close this quarter if the security review has not started, if legal has not received paper, or if the budget line has not been confirmed for the current period — regardless of how enthusiastic the champion is. These are not probabilistic. They are prerequisites with known lead times. Once you know that your average security review runs six weeks and your average legal redline cycle runs three, you can compute a latest-possible-start date for any deal you want to close in the quarter, and any deal past that date is arithmetically out no matter what the stage field says. Substituting arithmetic for optimism at that single gate typically removes more forecast error than any amount of model tuning.
Real numbers, ranges, and benchmarks
Precision matters here more than borrowed statistics, so treat the following as the measurements you should take in your own data rather than industry constants. Every one of them is computable from a standard CRM export plus opportunity history.
Cycle length by segment, measured honestly. Compute median, not mean — long-cycle distributions have a heavy right tail and the mean will overstate the typical deal. Compute it separately for new logo and expansion, and separately by deal size band, because a $30K expansion and a $400K new-logo purchase are not the same process. Also measure from the right starting point: first qualified meeting, not lead creation, or your marketing-sourced deals will look artificially slower than sales-sourced ones for reasons that have nothing to do with buyer behavior. Track the trend quarter over quarter. The trend line matters more than the absolute number, because a cycle that is lengthening by a few weeks per quarter will invalidate your probability tables faster than a long-but-stable cycle will.
Close-date drift. For every deal closed in the last several quarters, count how many times its close date moved and by how many days in aggregate. Then cross-tabulate drift count against whether the deal closed in the quarter it was first committed to. In most pipelines this produces a strikingly clean relationship: zero-drift deals honor their dates at a high rate, one-drift deals meaningfully lower, and two-or-more-drift deals rarely land in the quarter they claim. Once you have your own version of that table, it becomes the single most defensible probability adjustment you can apply, because it is derived from your buyers rather than borrowed from someone else's.
Slip-versus-loss decomposition. Take every deal that was in commit at the start of a quarter and did not close in it. Split into three buckets: closed lost, closed in a later quarter, still open. The proportions tell you what kind of accuracy problem you have. A pipeline dominated by the "closed in a later quarter" bucket has a *timing* problem, and the fix is close-date discipline. A pipeline dominated by "closed lost" has a *qualification* problem, and no forecast model will fix it. Most long-cycle organizations discover they are overwhelmingly in the first bucket and have been treating it as the second, which is why their remediation — more pipeline, more activity, more pressure — never improves accuracy.
Coverage ratio, recalculated for your actual cycle. The familiar 3x rule was derived in an environment where most of a quarter's closes came from deals created within the preceding two quarters. If your median cycle is now materially longer than that, the deals that will close in Q4 were largely created before Q2, and the coverage number you need for a given quarter is a function of how much of that older cohort has survived. Rather than adopting a new multiple on faith, compute cohort survival: of deals created in quarter N, what fraction closed in N+1, N+2, N+3, N+4? That curve gives you a coverage requirement grounded in your own conversion behavior, and it updates automatically as cycles change.
Forecast accuracy, measured as a distribution rather than a single number. Reporting "we were 94% accurate" hides the variance that actually hurts. Track absolute percentage error per quarter over at least eight quarters and look at the spread. A team that alternates between +15% and −15% has a worse forecasting process than one that consistently runs −4%, even though the first team's average error is closer to zero. Consistent bias is correctable with a coefficient. Wide variance is not, and it is the thing that makes a forecast unusable for planning.
Stage-to-close lead times. For each late stage, measure the distribution of days from entering that stage to signature. Then use the 75th percentile, not the median, as your planning number. If entering Proposal historically means 45 days to close at the median but 90 at the 75th percentile, a deal entering Proposal with 50 days left in the quarter is a coin flip, not a commit — and stating it that way in the forecast call is far more useful than stating a probability.
Activity recency thresholds, calibrated locally. Rather than adopting a generic "30 days quiet equals dead" rule, plot win rate against days-since-last-two-way-activity in your own data. The curve usually has a visible knee. That knee is your threshold, and it varies enormously by segment — enterprise buyers routinely go quiet for stretches that would be alarming in SMB, because internal evaluation genuinely takes that long. Applying an SMB-calibrated threshold to an enterprise pipeline will strip out live deals; applying an enterprise threshold to SMB will keep dead ones.
Trade-offs between the available approaches
There is no single correct forecasting method, and the honest framing is that each approach trades a different kind of error for a different kind of cost.
Weighted pipeline is cheap, automatic, and requires no human time. It is also the approach that degrades worst as cycles lengthen, for all the reasons above. Its real virtue is as a floor: it is hard to game because it derives entirely from fields, and it gives you a consistent baseline to measure other methods against. Keep it running, but stop treating its output as the forecast.
Rep-committed forecasting — asking each seller what they will close and rolling it up — captures information no model has. The seller knows the champion resigned. The model does not. Its weakness is that it is a judgment call made by a person with a strong incentive about the answer, and the direction of bias is not even consistent: some sellers sandbag to protect themselves, others inflate to avoid a difficult conversation. It also scales poorly in accuracy terms, because rolling up twenty biased estimates does not cancel the bias unless the biases happen to be symmetric, and they rarely are.
Manager-adjusted commit improves on the raw rep number by adding a layer of skepticism from someone who has seen more deals. It works, up to a point, and most organizations find manager adjustment is their single best-performing method in absolute accuracy terms. The cost is time — a real manager review of a long-cycle pipeline is hours per week — and the failure mode is that managers develop consistent personal biases that then get baked in permanently because nobody measures each manager's historical accuracy separately. Measuring it is the fix, and it is a small amount of work: track each manager's forecast versus actual over several quarters and apply their personal coefficient.
Machine-learned scoring handles volume and consistency well, catches patterns humans miss, and never gets tired in week thirteen. It struggles with exactly the situations long cycles create: regime changes, thin training data for the specific long-cycle cohort, and any circumstance where the future does not resemble the training window. It also cannot see anything not in the data — a buyer's internal reorganization, a competitor's aggressive move, a macro shift that freezes budgets across a whole segment.
Cohort and flow-based forecasting takes a different angle entirely: instead of predicting individual deals, predict the aggregate. Given the size and age distribution of the current pipeline and historical conversion rates by cohort, how much revenue should convert this quarter? This method is unreasonably effective for long-cycle businesses because aggregate behavior is far more stable than individual deal behavior, and it is immune to per-deal optimism. Its limitation is granularity: it tells you the number but not which deals make it up, so it cannot drive the deal-level actions a sales team needs. Its right role is as an independent check on the bottom-up number.
Running three methods and comparing them is more work than running one, and that is the trade-off. What you buy is a calibrated sense of your own uncertainty. When the three converge, you can commit to a point number with real confidence. When they diverge sharply, that divergence is itself the most valuable signal available — it tells you the quarter is genuinely uncertain, and communicating a range at that moment is more honest and more useful than a false point estimate that everyone will plan against.
One more trade-off deserves mention because it is usually decided by default rather than deliberately: forecast frequency. Weekly forecasting in a long-cycle business generates a great deal of activity around deals that have not changed and cannot change on a weekly rhythm. Some organizations respond by moving to biweekly or monthly deal reviews while keeping a lightweight weekly exception report — flagging only deals whose date moved, whose activity went quiet, or whose score dropped. That split preserves responsiveness on the deals that are actually moving without spending the whole team's Monday re-litigating deals that are waiting on someone else's legal department.
Common pitfalls and how to avoid them
Treating a slip as a loss. The most common and most expensive error. When a deal moves out of the quarter, the reporting system usually records a forecast miss and the deal stays in pipeline, so the same revenue gets counted as a problem now and as new pipeline later. This double-counts the bad news and produces overreaction. Fix it by reporting slips as a separate category with its own metric, and by tracking cohort revenue — how much did the deals created in a given quarter eventually produce — alongside quarter-attainment. Cohort revenue is the number that actually reflects whether the business is working.
Letting close dates be edited without a reason code. If a rep can move a date with a click and no explanation, the field carries no information. Require a reason — buyer requested, procurement delay, budget cycle, security review, champion change, competitive re-evaluation, no specific reason — and the drift data suddenly becomes diagnostic rather than merely descriptive. Within a quarter or two you will know which of those reasons predicts eventual close and which predicts eventual loss, and you can weight accordingly.
Applying a single set of thresholds across segments. Enterprise, mid-market, expansion, and renewal all behave differently under lengthening cycles, and a rule calibrated on the blend will be wrong for every individual segment. Segment first, calibrate within segment, then aggregate.
Confusing activity with progress. A deal generating a high volume of email is not necessarily advancing; it may be generating that volume precisely because it is stuck and people are negotiating internally. The distinguishing feature is *two-way* activity with *new* participants and *forward* artifacts — a security questionnaire returned, a redline received, a new stakeholder joining a call. Volume alone is a weak signal. Direction is a strong one.
Cleaning the pipeline only at quarter-end. Running a purge in week twelve produces a sudden, alarming drop in coverage precisely when leadership is most anxious, and the political pressure to reverse it is intense. Doing the same hygiene continuously — a small number of deals reviewed every week on a rolling basis — produces the same clean pipeline without the cliff, and the decisions get made when they are calm rather than when they are loaded.
Letting the forecast drive the number instead of describing it. When the published forecast becomes a commitment that people are punished for missing, the forecast stops being a prediction and becomes a negotiation. Sellers learn to submit numbers they can beat. Managers learn to hold back a reserve. The organization ends up with a number that is politically safe and informationally worthless. Separating the forecast — this is what we believe will happen — from the target — this is what we are asking you to achieve — is a management decision, not an analytics one, and no tooling will substitute for it.
Assuming the fix belongs entirely to sales. Longer cycles change what marketing must produce, because a buying process that runs a year needs material that supports internal selling — business cases, security documentation, comparison content the champion can forward without you in the room. It changes what customer success owes, because reference calls become a gating step much earlier. It changes finance's planning cadence, because bookings arrive in a different distribution than the plan assumed. A quarter-end accuracy problem that is only ever discussed in the sales forecast call is being addressed at one point in a system that has several.
Neglecting the renewal and expansion side. Attention concentrates on new logo, but expansion deals in a consolidation-minded buying environment increasingly go through the same committee review as new purchases, and renewals that were once automatic now attract scrutiny. If your forecast treats expansion as reliably predictable because it historically was, you have an unmeasured error source growing quietly in the part of the number you assumed was safe.
Related questions
Does lengthening the sales cycle always mean win rates fall?
Not necessarily. Cycles often lengthen because more stakeholders are validating the purchase, which can raise eventual win rates while reducing in-quarter close rates. Measure win rate on a cohort basis — by creation quarter, tracked to eventual outcome — rather than by close quarter, or the two effects get confused.
How far out should we forecast if cycles run over a year?
Keep publishing a quarterly number, but add a rolling four-to-six-quarter cohort view derived from pipeline age distribution. The quarterly number serves operational decisions; the cohort view serves hiring, capacity, and board planning, where being roughly right over a year matters more than precision in one quarter.
Should stage probabilities be recalibrated, or replaced?
Recalibrate for probability-of-ever-closing, and replace for timing. Stage genuinely predicts whether a deal converts. It has stopped predicting when. Use stage for the first question and use activity recency, date stability, and procedural prerequisites for the second.
What is the fastest single change that improves accuracy?
Add a hard-evidence gate to commit: budget confirmed for the current period, security review complete or not required, and paper with legal. Deals missing any of the three cannot be commit regardless of stage or enthusiasm. This one rule typically removes the majority of preventable forecast error.
How do you keep reps engaged when their deals will not close for months?
Shift recognition toward leading indicators that reps control — new stakeholders engaged, business cases delivered, security reviews initiated — and pay attention to pipeline-generation quality alongside closed revenue. Comp plans built entirely around in-quarter bookings create the pressure that corrupts close dates in the first place.
FAQ
Is longer-cycle forecast error a modeling problem or a data problem?
Predominantly a data problem. The models are usually adequate; they are being fed a close date that nobody measured and a stage probability calibrated on a population that no longer resembles the current pipeline. Improving date discipline and adding activity-recency and prerequisite fields will move accuracy further than switching forecasting tools.
How many quarters of history do we need before our own benchmarks are trustworthy?
Enough closed deals for the segment you are analyzing to produce stable rates — typically several quarters, and more if deal volume is low. If a segment closes only a handful of deals per quarter, resist per-segment statistics entirely and reason from the aggregate plus qualitative review, because small-sample rates will swing wildly and invite overreaction.
Should deals older than some threshold be automatically removed from the forecast?
Automatic removal from *commit* based on activity staleness is reasonable and easy to defend. Automatic removal from the *pipeline* is not, because genuinely long enterprise processes go quiet for extended stretches and still close. Separate the two actions: quiet deals leave the quarter's number but stay in the pipeline until they fail a re-qualification review.
Does AI-based deal scoring help or hurt in long-cycle pipelines?
It helps for consistency and for surfacing deals a human review would skip, and it hurts when applied without recency weighting, because it will score a deal on engagement patterns from a phase of the buying process that ended months ago. Require any score to expose how old its supporting signals are, and discount accordingly.
How should the forecast be communicated when uncertainty is genuinely high?
As a range with named swing factors: the specific deals that determine which end you land on, and what would have to be true for each. A range with three named dependencies is more actionable for the people planning around it than a point number that everyone privately discounts anyway.
Does any of this change how quota and territory planning should work?
Yes. If the median cycle exceeds two quarters, a new seller's ramp is bounded by cycle length, not by onboarding speed, and quotas that assume in-quarter productivity from a rep hired mid-quarter are arithmetically impossible. Build ramp schedules from measured cycle length and adjust capacity planning to match the lag.
Sources
- Gartner — Sales insights and B2B buying research
- Harvard Business Review — Sales topic archive
- McKinsey — Growth, Marketing & Sales insights
- Forrester — Blogs
- SaaStr
- Salesforce — Research and reports
- HubSpot Sales Blog — Sales forecasting
- Bessemer Venture Partners — Atlas
- OpenView / SaaS metrics reference at KeyBanc Capital Markets
Related on PULSE
- How do you handle deal slippage at quarter-end without sandbagging the forecast?
- How does the reliability of AI-generated sales predictions degrade with longer cycle times?
- How does your RevOps team audit AI predictions that change weekly in 2027?
- How do you triangulate forecasts between manager commits and ML predictions?
- How do you build a pipeline coverage model that survives a lengthening sales cycle?
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 revopsBest fractional CRO firms in 2027
 revopsHow does vendor consolidation impact sales tech stack integration costs in 2027?
 revopsWhat does the WNBA's 2026 CBA mean for player pay and revenue sharing in 2027?
 revopsCRO compensation — fractional, full-time, equity in 2027
 revopsWhat role does AI play in reducing vendor bloat for enterprise GTM stacks in 2027?
 revopsHow can RevOps use AI to map influence dynamics inside buying committees in 2027?
 revopsHow do longer sales cycles in 2027 change the optimal frequency of B2B follow-up communications?
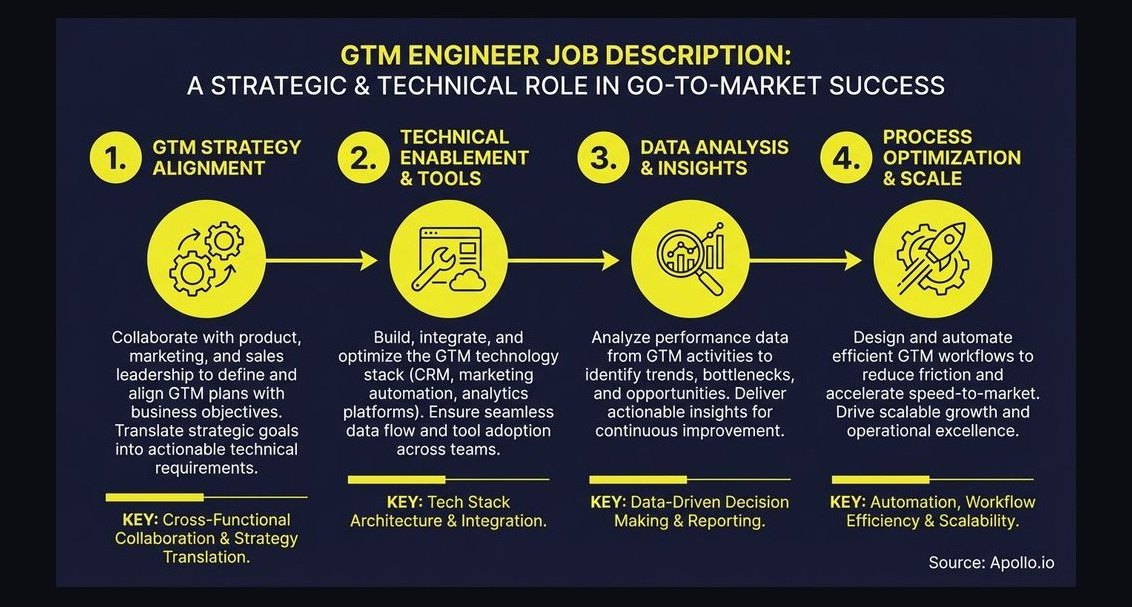 revopsWhat is a GTM engineer and why is the role exploding in 2027?
 revopsWhich vendor consolidation strategies are causing the most friction in B2B sales handoffs in 2027?
 revopsWhat is the cost of AI vendor lock-in for B2B sales teams in 2027?