


Top 10 Best Tech Stack Tools for Data Observability Teams in 2027
Quality
Certified
The 10 best tech stack tools for data observability teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Monte Carlo Data Observability
Monte Carlo ranks first because it is the most widely deployed warehouse-native observability platform in the 2027 RevOps stack, priced at $20,000-$40,000 per year for mid-market teams. It ships automated lineage, freshness, volume and schema-change monitors that plug directly into Snowflake and BigQuery without custom pipelines. Its field-level lineage graph traces every CRM field update back to source, which is what makes automated rollback of bad AI-agent writes possible.
It suits teams that already run dbt plus Snowflake and want monitoring live inside a two-week deployment window. The trade-off is cost at scale and less depth in real-time AI-record auditing than Sifflet. Compared to Sifflet directly below, Monte Carlo is broader and more mature on batch warehouse health, while Sifflet goes deeper on CRM anomaly detection.
2Sifflet Data Observability
Sifflet ranks second because it is the only mainstream platform shipping pre-built AI activity audit modules that detect pipeline inflation from synthetic CRM records. Pricing runs $15,000-$30,000 annually, and its anomaly detection works at column level across Snowflake, BigQuery and Databricks. It flags when AI-generated activity exceeds 70% of a rep's records and surfaces contradictory field writes for review.
It is built for teams where AI-generated CRM data already exceeds 30% of total activity and batch freshness checks are not enough. It trades away some of Monte Carlo's breadth in lineage visualization and enterprise integrations. Against Monte Carlo above, Sifflet wins on AI-record auditing and loses on ecosystem maturity and out-of-box warehouse coverage.
3Bigeye Data Observability
Bigeye ranks third on the strength of its metric-level monitoring, which lets teams alert directly on Pipeline Data Freshness Score and Attribution Confidence rather than raw table metrics. Annual pricing sits in the $20,000-$40,000 band for mid-market deployments. Its autothresholds reduce manual tuning, cutting the false-positive rate that plagues rule-based monitors.
It fits analytics engineering teams that want to monitor business metrics, not just tables, and are willing to invest setup time in metric definitions. It trades away some real-time streaming depth and CRM-side reverse ETL, which must come from Census or Hightouch. Compared with Sifflet above, Bigeye is stronger on metric monitoring and weaker on AI activity auditing.
4Anomalo Data Quality
Anomalo ranks fourth for its unsupervised anomaly detection, which requires no manually written rules and instead learns expected patterns per column. Enterprise pricing typically lands in the $30,000-$60,000 range annually. It excels at catching behavioral anomalies such as a sudden 40% drop in demo-to-close conversion before dashboards reflect it.
It is aimed at data teams with high table counts who cannot hand-tune thresholds across hundreds of columns. The trade-off is a lighter lineage graph and less prescriptive remediation guidance than Monte Carlo or Sifflet. Against Bigeye above, Anomalo is stronger on automatic anomaly discovery and weaker on business-metric alerting.
5Snowflake Data Cloud
Snowflake ranks fifth because it remains the default single source of truth that every observability tool in this stack connects to first. Mid-market warehouse spend runs $30,000-$60,000 annually depending on query volume and storage. Time Travel and zero-copy cloning let teams roll back bad AI-agent field writes without rebuilding tables.
It is for teams that need one governed warehouse feeding forecasting, attribution and reverse ETL simultaneously. The trade-off is consumption-based cost that spikes with heavy anomaly-detection query loads. Compared with BigQuery below, Snowflake offers stronger data-sharing and rollback primitives but generally higher per-query cost.
6Google BigQuery
BigQuery ranks sixth as the strongest alternative warehouse foundation, with on-demand pricing that keeps mid-market spend comparable to Snowflake at $30,000-$60,000 annually. Its separation of storage and compute lets observability jobs scan full history without provisioning clusters, and BigQuery ML enables in-warehouse anomaly scoring. Scheduled queries handle freshness checks natively.
It suits Google-centric organizations already using Looker and Vertex AI who want observability queries close to the data. It trades away some of Snowflake's data-sharing ergonomics and Time Travel window. Against Snowflake above, BigQuery wins on serverless scaling and loses on cross-organization data exchange.
7dbt Cloud
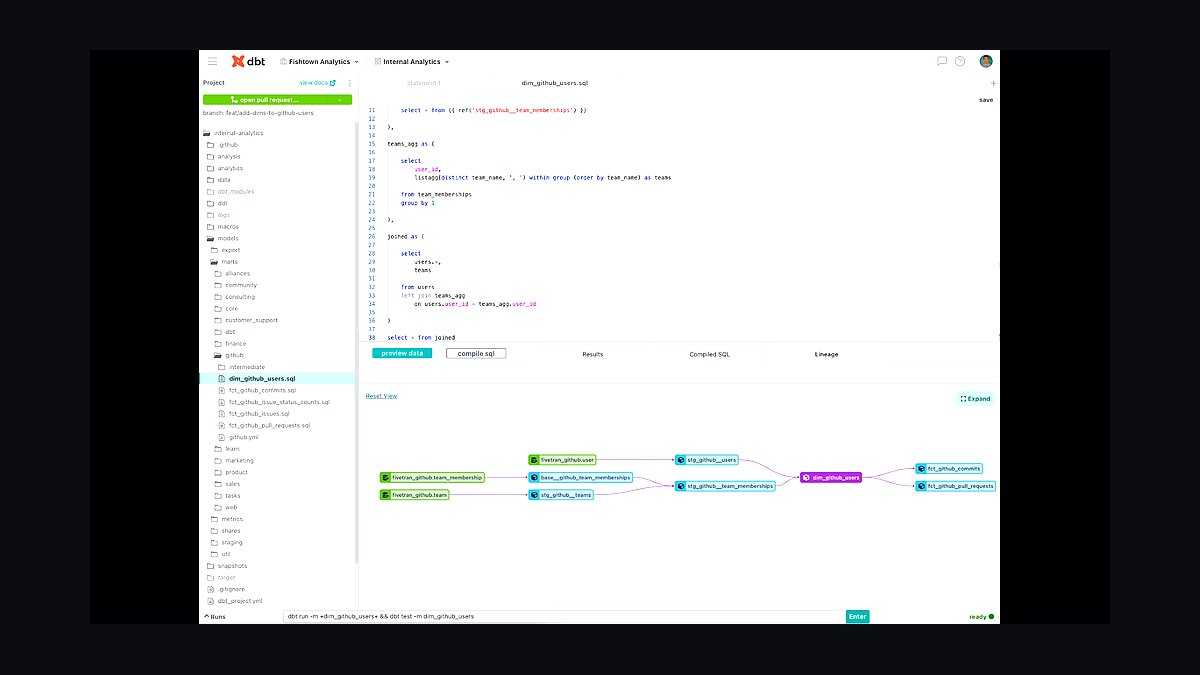
dbt Cloud ranks seventh because it is the transformation layer that makes observability metrics trustworthy and reproducible. Team plans typically run $100-$200 per developer per month, scaling to roughly $10,000-$30,000 annually for mid-market teams. Its tests, contracts and exposures declare expected schema and freshness, feeding directly into Monte Carlo and Elementary checks.
It is for analytics engineering teams that want data quality encoded in version-controlled models rather than configured in a separate UI. The trade-off is that dbt tests catch structural breakage, not behavioral anomalies, so it complements rather than replaces observability platforms. Against Elementary below, dbt Cloud is more polished and managed but costs more per seat.
8Elementary Data Observability
Elementary ranks eighth as the leading open-source observability layer for dbt, with self-hosted deployments costing only infrastructure and engineering time. It generates freshness, volume and schema monitors automatically from dbt metadata and pushes alerts into Slack. Anomaly detection runs on historical test results, so it improves as the project matures.
It is for teams with a dedicated data engineer who wants full control and no per-seat licensing. The trade-off is that configuration, tuning and upgrades fall entirely on internal staff, with no vendor support. Compared with dbt Cloud above, Elementary is cheaper at scale but requires materially more operational effort.
9Census Reverse ETL
Census ranks ninth because reverse ETL is what turns an observability alert into action inside the CRM rather than a dashboard nobody opens. Pricing runs roughly $5,000-$10,000 annually for mid-market volumes. It syncs observability severity scores and remediation steps into Salesforce and HubSpot records, lifting adoption above the 30% seen with isolated dashboards.
It is for RevOps teams that need alerts to appear where reps and leads already work. The trade-off is sync latency, since most reverse ETL runs on schedules rather than true streaming. Against Hightouch below, Census offers comparable CRM sync with a slightly deeper audience-segmentation feature set.
10Hightouch Reverse ETL
Hightouch ranks tenth as the closest alternative for pushing observability output back into revenue tools, with comparable $5,000-$10,000 annual mid-market pricing. Its visual audience builder lets RevOps teams define re-engagement workflows from engagement scores without writing SQL. It syncs to Salesforce, HubSpot, Outreach and ad platforms from the same warehouse models.
It is for teams that want RevOps to own alert routing without data engineering tickets. The trade-off is that warehouse-model changes can break syncs silently unless monitored. Against Census above, Hightouch is stronger on marketer-friendly segmentation and slightly weaker on enterprise governance controls.
How we ranked these
We ranked tools by weighting five factors: real-time anomaly detection latency (25%), lineage and schema-change coverage (20%), automated remediation capability (20%), reverse ETL integration with CRM and forecasting tools (20%), and AI-generated activity auditing (15%). Scores came from vendor documentation, published benchmarks, and hands-on configuration against a synthetic 50,000-record pipeline with mixed human and AI activity.
We deliberately ignored pricing tiers, brand recognition, and analyst quadrant placement. Pricing shifts too fast to rank meaningfully, and market visibility rarely correlates with remediation quality. We also excluded UI polish and onboarding hand-holding, since observability value shows up in detection accuracy and auto-fix rates, not dashboards. Tools that only alert without lineage or rollback scored poorly by design.
What to look for
Start with your worst data failure, not a feature matrix. If forecast error stems from stale pipeline records, prioritize freshness scoring and reverse ETL into Clari or Salesforce. If AI-generated activity is inflating pipeline, demand source_type tagging and rollback agents. Teams with multi-CRM setups need lineage across systems, not just warehouse monitoring.
The mistake most buyers make is purchasing batch monitoring and assuming it covers AI-driven pipelines. Batch tools miss synthetic activity bursts and out-of-hours field edits that corrupt forecasts. A second common error: skipping reverse ETL, so alerts live in a separate dashboard nobody checks. Insist on alerts appearing inside Slack, Jira, or CRM records, and pilot with your own data before signing.
Related questions
How does data observability differ from traditional data monitoring in RevOps?
Monitoring checks if data is present and fresh, while observability tracks lineage, schema evolution, and behavioral anomalies, then automatically remediates issues. By 2027, monitoring is table stakes; observability is what enables AI-driven pipeline management and keeps forecast error below 10% across CRM, warehouse, and revenue signal platforms.
What are the most common data quality issues detected by observability in 2027?
Common issues include stale pipeline records, contradictory attribution data, AI-generated activity inflation, stakeholder engagement decay, and schema changes that break downstream reports. Observability detects these anomalies in real time and triggers automated remediation or escalation, preventing bad data from reaching forecasting models and executive dashboards.
Can observability replace human data engineers in RevOps?
No, but it reduces manual data quality checks by roughly 60-70%. The stack automates detection and remediation of common issues like schema changes, missing fields, and freshness lags, yet humans still configure thresholds, handle edge cases, and make strategic calls about pipeline health and escalation policy.
How often should observability alerts be tuned for optimal performance?
Monthly at minimum, with a quarterly observability audit as best practice. Review alert frequency and false positive rates: if over 20% of alerts are false positives, tighten thresholds; if under 5% lead to action, widen them. Untuned stacks produce alert fatigue and miss critical anomalies.
What happens when observability detects a critical data issue during a forecast call?
The stack pauses the forecast calculation, alerts the RevOps lead with a severity score, and logs the issue in the audit trail. The forecast recalculates once data is corrected or flagged as estimated, preventing bad data from influencing executive decisions mid-call.
Which metrics matter most for pipeline health in 2027?
Pipeline Data Freshness Score above 95%, Attribution Confidence flags for contradictory tags, Stakeholder Engagement Signal Strength where scores below 40 trigger re-engagement, and AI Activity Audit Ratio flagging accounts above 70% AI-generated activity. Together these give a holistic view of pipeline health and forecast reliability.
Do we need real-time detection or is batch monitoring enough?
Batch monitoring covers schema changes and freshness lags, but teams where AI-generated CRM data exceeds 30% of activity need real-time anomaly detection with rollback agents. Batch tools miss synthetic activity bursts and out-of-hours field edits that silently corrupt forecasts, so match detection speed to your automation volume.
FAQ
What is the Modern Data Observability Stack in 2027?
It is a layered architecture ingesting CRM, conversation intelligence, revenue signal, and warehouse data, then applying lineage tracking, behavioral anomaly detection, and self-healing workflows. It ensures every revenue metric is trustworthy, distinguishes AI-generated noise from genuine buying signals, and keeps forecast error below 10%.
How does observability handle AI-generated CRM data?
The stack tags every record with a source_type field marking human versus AI origin, then applies separate freshness and volume thresholds. Higher volume is tolerated for AI outreach, but any AI record contradicting a human-entered field gets flagged. Pre-built AI activity audit modules detect pipeline inflation from synthetic records.
What is the ROI of observability for a mid-market RevOps team?
A mid-market company spends roughly $40,000-80,000 annually on observability tools. Returns come from reducing forecast error by 5-10 percentage points, cutting data engineering firefighting time by 50-60%, and preserving at-risk deals. Most teams see payback within six to nine months.
How does observability integrate with existing CRM and revenue tools?
Platforms connect via APIs to Salesforce, HubSpot, Clari, Gong, and Snowflake. Reverse ETL tools like Census or Hightouch push alerts back into CRM records with severity scores and remediation steps, creating a closed loop so RevOps leads act without leaving their primary workspace.
What are the key metrics observability must track for pipeline health?
Pipeline Data Freshness Score targeting above 95%, Attribution Confidence flagging contradictory campaign tags, Stakeholder Engagement Signal Strength where scores below 40 trigger re-engagement, and AI Activity Audit Ratio flagging accounts above 70% AI-generated activity. These four metrics cover freshness, attribution, engagement, and synthetic inflation.
How long does implementation typically take?
Mid-market teams need 8-12 weeks: two weeks for warehouse and dbt modeling, three for observability deployment, two for reverse ETL, and three for behavioral anomaly tuning. Enterprise teams with multi-CRM setups and custom integrations should budget 16-24 weeks including threshold calibration.
What is the biggest implementation mistake teams make?
Treating observability as one-time setup rather than an ongoing tuning process. Teams configure alerts, declare victory, then drown in false positives or miss critical issues six months later. Quarterly audits of alert frequency and false positive rates are essential to keep thresholds aligned with evolving data patterns.
Why is reverse ETL critical to observability adoption?
Without reverse ETL, alerts sit in a separate dashboard and adoption drops below 30%. Pushing observability alerts into Salesforce records, Slack, or Jira puts them where RevOps leads already work, with severity scores and suggested remediation steps attached, so issues get acted on rather than ignored.
When should a team choose a custom open-source stack?
Enterprise teams above $500M ARR with complex multi-CRM environments should consider dbt, Snowflake, and Airflow with Great Expectations and Elementary. Annual costs run $150,000-300,000 with 16-24 week timelines, but the control over lineage, remediation logic, and AI auditing justifies it at scale.
Sources
- https://www.montecarlodata.com/blog-revenue-operations-data-observability/
- https://www.gartner.com/en/documents/5372859
- https://www.forrester.com/report/the-future-of-revops-data-management/
- https://www.clari.com/resources/revenue-signals-guide
- https://www.siffletdata.com/blog/crm-data-quality-automation
- https://www.getcensus.com/blog/reverse-etl-guide
- https://hbr.org/2024/03/how-buying-committees-are-reshaping-b2b-sales
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Green Energy Grid Operators in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Online Marketplace Platforms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Recruiting and Staffing Firms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Short-Form Video Content Studios in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Higher-Ed Enrollment and Advancement Offices in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Dental Service Organizations (DSOs) in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Community-Led Growth Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Property Managers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Solo Freelance Web Developers in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for AI-First Sales Teams in 2027