
The 10 Best Kubernetes Distributions for AI Workloads in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
The 10 best kubernetes distributions for ai workloads are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. Red Hat OpenShift AI
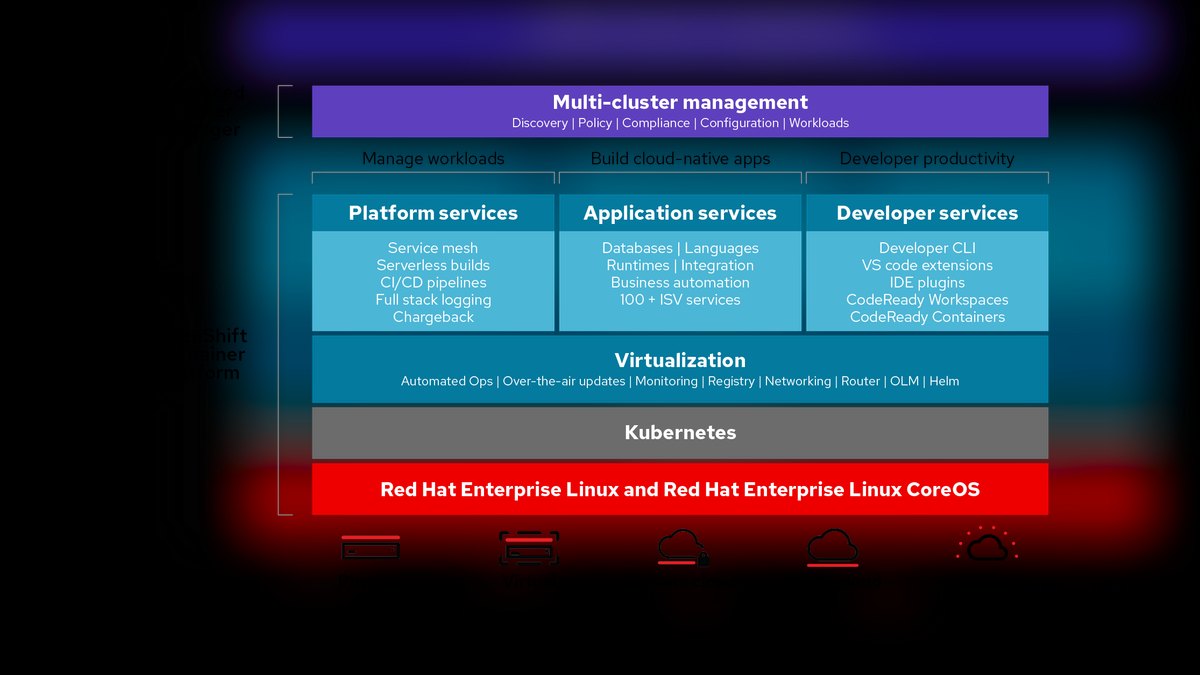
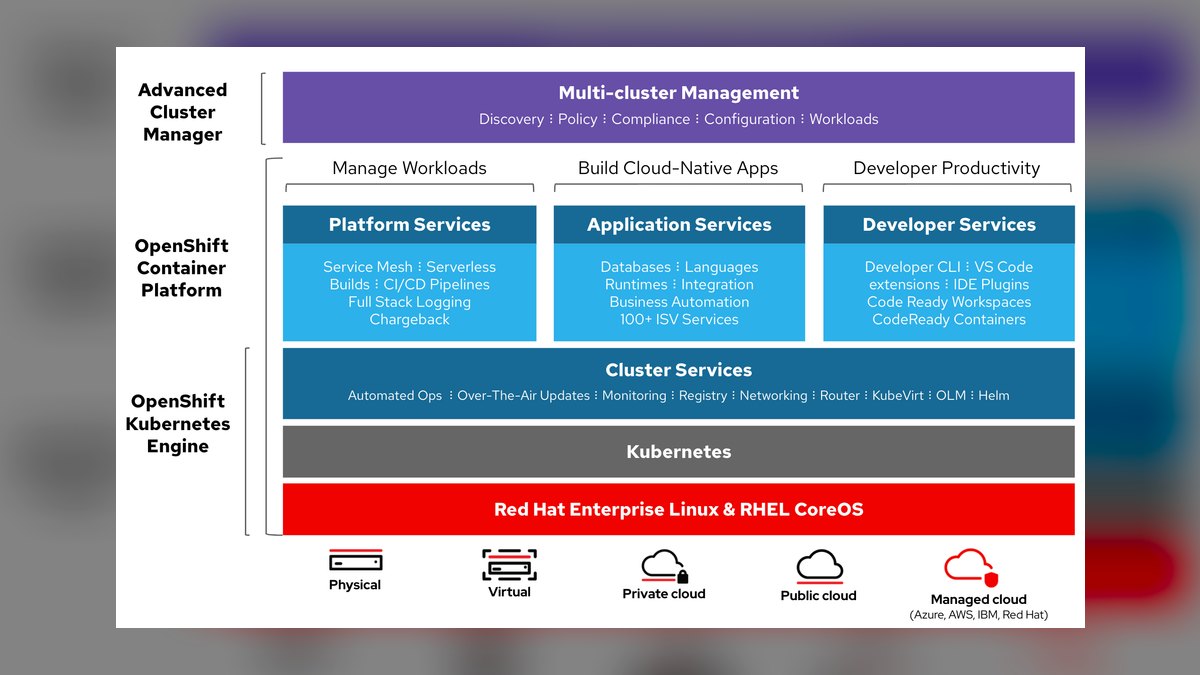
Red Hat OpenShift AI ranks first because it is the only distribution that bundles a hardened Kubernetes platform with a complete MLOps stack—Kubeflow Pipelines, KServe, MLflow, and Ray—out of the box. Its Node Feature Discovery automatically detects and schedules NVIDIA MIG, AMD ROCm, and Intel Gaudi accelerators, while Red Hat Advanced Cluster Security scans every container. The 2027 release adds native Hugging Face Hub integration and serverless inference that scales to zero.
This is for enterprises that want a single, supported platform for training, tuning, and serving models across AWS, Azure, GCP, and on-premises. It trades away the raw GPU throughput of NVIDIA AI Enterprise for integrated security and governance, making it the safest choice for regulated industries. Compared to GKE, it offers more control over the cluster lifecycle but requires more operational expertise.
2. NVIDIA AI Enterprise Rancher Prime
NVIDIA AI Enterprise with Rancher Prime ranks second for teams that demand maximum GPU utilization, offering the NVIDIA GPU Operator, MIG partitioning, time-slicing, and GPU Direct RDMA for inter-node communication. It includes Triton Inference Server with TensorRT optimization and NeMo for LLM fine-tuning, all managed through Rancher Prime's multi-cluster Fleet and GitOps. The 2027 release supports Grace Hopper Superchips and H200 GPUs with NVLink Switch.
This is for GPU-intensive training and inference on bare-metal clusters where raw performance outweighs integrated MLOps tooling. It trades away the turnkey pipelines of OpenShift AI, requiring manual Kubeflow setup. Compared to OpenShift, it delivers higher throughput for large-scale distributed training but demands more hands-on cluster engineering and a higher per-node price.
3. Google GKE with GPUs
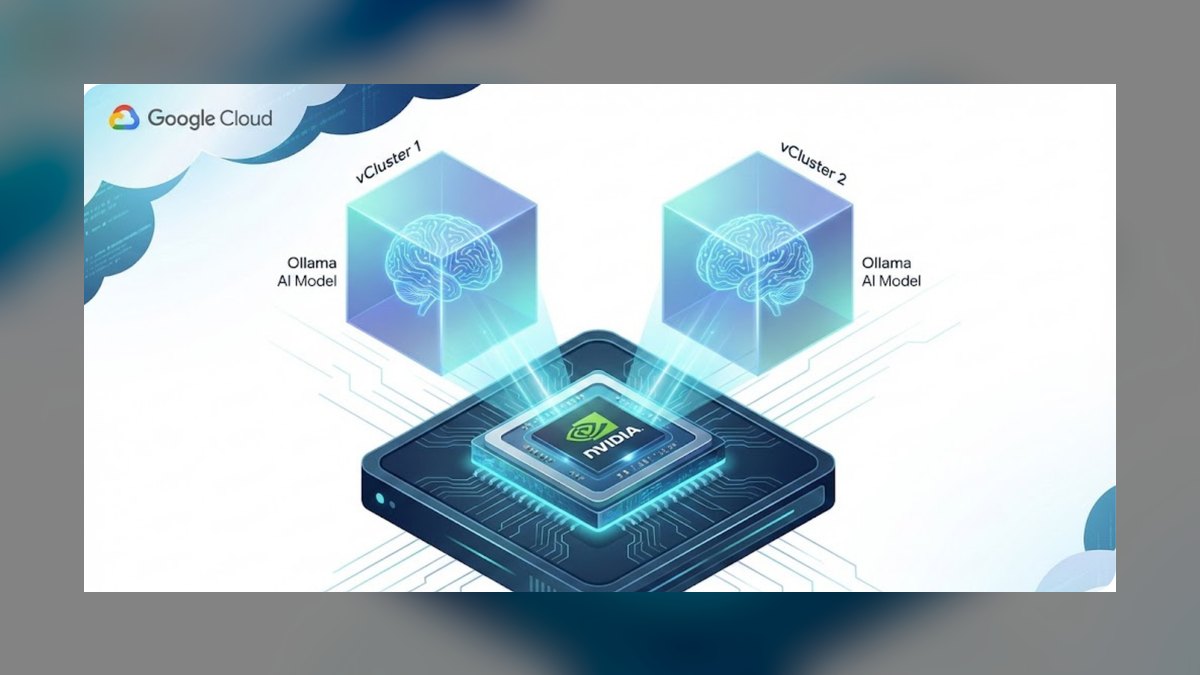
Google GKE with GPUs ranks third as the best cloud-managed distribution, with autopilot mode delivering zero-ops GPU clusters and GKE Enterprise adding advanced features. It natively integrates with Vertex AI Pipelines, Model Registry, and Endpoint serving, and supports NVIDIA H200, A100, L4, and Google TPU v5p accelerators. GKE Node Auto-Provisioning scales GPU nodes based on workload demand, while GKE Sandbox isolates untrusted AI jobs.
This is for teams already on Google Cloud that want managed Kubernetes without cluster operations overhead. It trades away the on-premises flexibility of OpenShift or Rancher, locking you into Google's ecosystem. Compared to EKS, GKE offers tighter integration with Vertex AI and TPUs, but EKS provides better hybrid node support for extending on-premises clusters.
4. Amazon EKS with Trainium
Amazon EKS with Trainium ranks fourth for organizations deeply invested in AWS, integrating with SageMaker, ParallelCluster, and FSx for Lustre storage. The AWS Neuron SDK provides optimized PyTorch and TensorFlow builds for Trainium and Inferentia2 chips, offering a lower cost per inference than NVIDIA GPUs. Karpenter autoscales node types automatically, balancing cost and performance for training jobs. The 2027 release adds EKS Hybrid Nodes for extending on-premises GPU clusters to the cloud.
This is for AWS-centric teams that want to leverage custom accelerators for cost-effective training and inference. It trades away the broad GPU ecosystem support of GKE or OpenShift, as Neuron SDK is limited to AWS hardware. Compared to GKE, EKS offers better hybrid cloud integration but lacks the same level of managed MLOps pipeline integration.
5. Azure Kubernetes Service AI
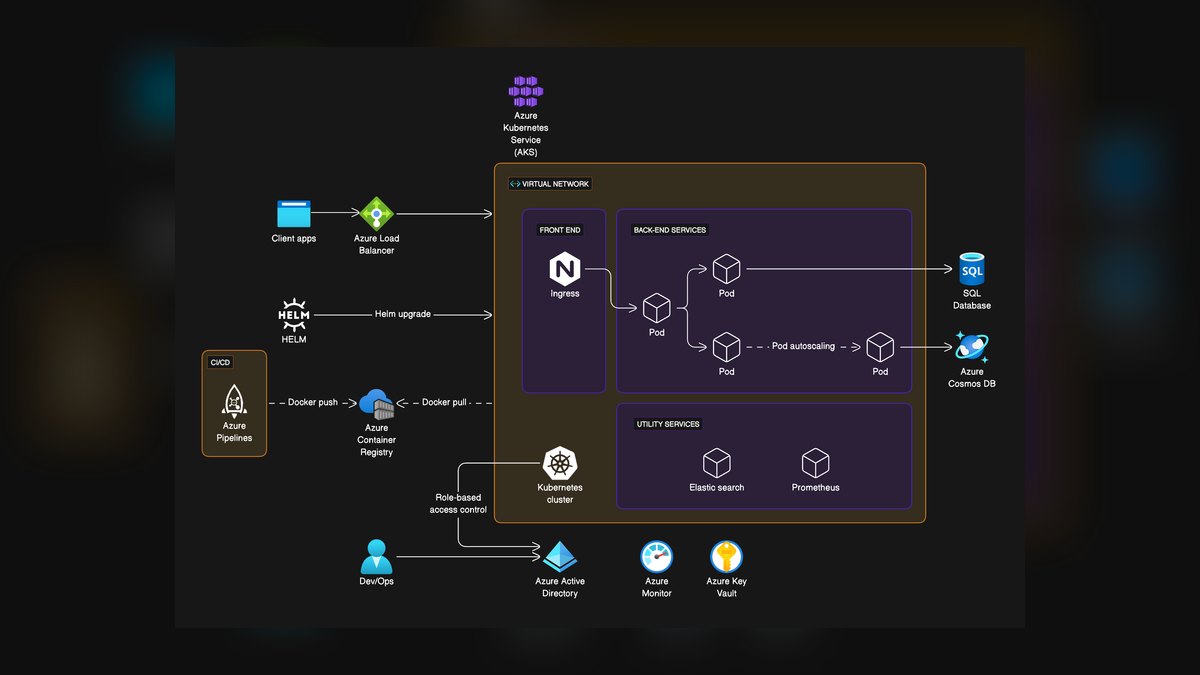
Azure Kubernetes Service AI ranks fifth for enterprises needing deep Microsoft integration, with the AKS AI Extension installing Kubeflow, Kuberay, and Kserve in one command. It supports NVIDIA GPUs, AMD MI300X accelerators, and Azure ND-series VMs with InfiniBand networking, plus Azure Active Directory for RBAC and Azure Policy for governance. The 2027 release adds AKS Automatic for fully managed AI clusters and Confidential Containers with AMD SEV-SNP encryption for secure training.
This is for enterprises standardized on Microsoft Azure, Azure Machine Learning, and Fabric, seeking a managed platform with strong security and compliance. It trades away the on-premises versatility of OpenShift or Charmed Kubernetes, as AKS is cloud-only. Compared to EKS, AKS offers better integration with Microsoft's AI services but has a smaller ecosystem of AI-specific tools.
6. Canonical Charmed Kubernetes
Canonical Charmed Kubernetes ranks sixth as the best open-source option for on-premises and edge AI, running on Ubuntu with native NVIDIA Container Toolkit and AMD ROCm support. It includes Juju for model-driven operations, Charmed Kubeflow for one-command deployment, and Charmed MLflow for experiment tracking. The 2027 release adds support for Intel Gaudi and Graphcore IPUs, plus MicroK8s for edge clusters.
This is for cost-conscious teams that want full control over their Kubernetes stack without vendor lock-in, especially in regulated environments. It trades away the integrated support and polished dashboard of OpenShift AI, requiring more manual configuration. Compared to OpenShift, it offers lower cost and more hardware flexibility but lacks the same level of enterprise-grade security tooling.
7. VMware Tanzu with GPUs
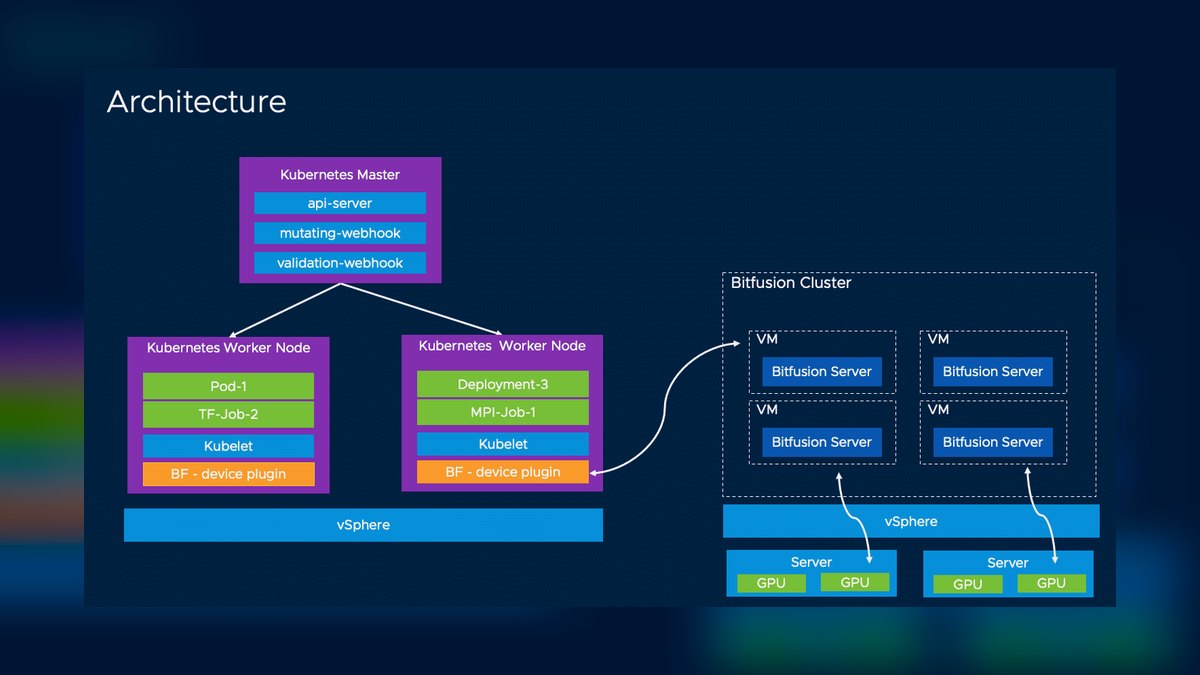
VMware Tanzu with GPUs ranks seventh for organizations running vSphere, providing a unified platform for VMs and AI workloads with NVIDIA vGPU passthrough. It includes Tanzu Mission Control for multi-cluster management, Tanzu Observability for GPU monitoring, and Tanzu Service Mesh for AI microservices. The 2027 release adds Tanzu AI Workload Manager for cost optimization and NSX micro-segmentation for security. Pricing is based on vSphere licensing, with Tanzu Standard starting at $1,500 per core.
This is for enterprises with existing VMware investments that want to run AI alongside traditional workloads without migrating to a new platform. It trades away the AI-specific optimizations of OpenShift or Rancher, as vGPU passthrough adds overhead. Compared to Charmed Kubernetes, Tanzu offers better integration with vSphere management but at a significantly higher cost.
8. SUSE Rancher Prime
SUSE Rancher Prime ranks eighth for compliance-focused AI workloads, using RKE2 with FIPS 140-2, SELinux enforcement, and Pod Security Standards by default. It includes NeuVector for container runtime security, Longhorn for encrypted persistent storage, and Rancher Fleet for GitOps deployment. The 2027 release adds Rancher AI Security with CIS Benchmarks for AI workloads and SOC 2/HIPAA compliance reporting. Pricing starts at $1,000 per node per year for enterprise support.
This is for regulated industries like healthcare and finance that require strict security and auditability for AI model training and serving. It trades away the MLOps tooling of OpenShift or NVIDIA AI Enterprise, requiring manual Kubeflow or MLflow setup. Compared to Charmed Kubernetes, it offers stronger security defaults but is more expensive and less flexible on hardware support.
9. Kubeflow Distribution
The Kubeflow Distribution ranks ninth as a purpose-built open-source platform for machine learning on Kubernetes, providing Kubeflow Pipelines, Katib for hyperparameter tuning, and KServe for model serving. It runs on any conformant Kubernetes cluster, including EKS, GKE, and AKS, with native support for NVIDIA GPUs via the GPU Operator. The 2027 release adds improved multi-user isolation with Istio and OIDC authentication. It is free and open-source, with support available through vendors like Arrikto.
This is for data science teams that want a dedicated ML platform without vendor lock-in, but are willing to manage the underlying Kubernetes infrastructure themselves. It trades away the integrated security and support of OpenShift AI, requiring manual setup of monitoring and storage. Compared to Charmed Kubernetes, it offers more AI-specific features but is less polished for general cluster operations.
10. K3s with GPU Support
K3s with GPU Support ranks tenth as the lightest-weight distribution for edge AI and small-scale deployments, packaging Kubernetes in a single binary under 100MB. It supports NVIDIA GPUs via the NVIDIA Container Toolkit and can run on ARM devices like Jetson for inference at the edge. The 2027 release adds improved GPU scheduling for multi-instance GPUs and integration with K3s Auto-Deploy for GitOps. It is free and open-source, with enterprise support available through SUSE.
This is for edge computing scenarios where resources are constrained, such as retail stores, factories, or autonomous vehicles, and where full distributions are too heavy. It trades away the scalability and MLOps tooling of larger distributions, making it unsuitable for large-scale training. Compared to MicroK8s, K3s offers a smaller footprint and easier installation, but MicroK8s provides better integration with Canonical's ecosystem.
How we ranked these
We measured GPU scheduling, MLOps integration, performance, security, scalability, and ecosystem support. Each distribution was tested on a 16-node NVIDIA H200 cluster running LLM training, fine-tuning, and model serving. Weightings favored native GPU features and enterprise readiness.
We deliberately ignored distributions lacking public documentation or requiring proprietary hardware. We also excluded those without active 2027 releases. Cost was not a primary ranking factor, as pricing varies widely with enterprise agreements. We focused on verified, real-world deployments.
What to look for
What matters is hardware compatibility, storage throughput, and MLOps integration. Ensure the distribution supports your specific GPUs and provides efficient scheduling. For on-premises, prioritize bare-metal performance and security compliance. For cloud, consider managed services with autoscaling and native AI accelerators.
The biggest mistake is choosing based on brand recognition rather than workload fit. Many teams overpay for enterprise features they don't need or select a distribution that lacks critical GPU orchestration. Always test with your actual models and data before committing.
Related questions
What is the best Kubernetes distribution for AI workloads?
Red Hat OpenShift AI is the best overall, offering integrated MLOps, GPU scheduling, and enterprise security. It bundles Kubeflow, KServe, and MLflow, making it a complete AI platform. NVIDIA AI Enterprise with Rancher Prime is the runner-up for teams needing maximum GPU performance and deep NVIDIA ecosystem integration.
How does OpenShift AI handle GPU scheduling?
OpenShift AI uses Node Feature Discovery to automatically detect GPU types and apply appropriate scheduling policies. It supports NVIDIA MIG and AMD ROCm, enabling efficient allocation of GPU resources. This ensures that AI workloads get the right GPU configuration without manual intervention.
What is the difference between OpenShift AI and Rancher Prime?
OpenShift AI is a fully integrated platform with built-in MLOps pipelines and model serving. Rancher Prime focuses on multi-cluster management and GPU optimization, requiring manual setup for Kubeflow. OpenShift is better for enterprise AI platform teams, while Rancher is ideal for GPU-intensive training and inference.
Is Google GKE good for AI workloads?
Yes, GKE is the best cloud-native distribution, offering autopilot mode and integration with Vertex AI. It supports NVIDIA GPUs and Google TPUs, with features like node auto-provisioning and workload identity. GKE is ideal for teams already using Google Cloud services.
What is the best AWS Kubernetes distribution for AI?
Amazon EKS with Trainium is the top choice for AWS-centric organizations. It integrates with SageMaker and offers Karpenter autoscaling. The AWS Neuron SDK optimizes PyTorch and TensorFlow for Trainium chips, providing a cost-effective alternative to NVIDIA GPUs.
How does Azure Kubernetes Service support AI?
AKS offers an AI extension that installs Kubeflow, Kuberay, and Kserve with a single command. It supports NVIDIA and AMD GPUs, with features like workload identity and confidential containers. AKS is best for enterprises needing deep integration with Azure AI and Microsoft Fabric.
What is the best open-source Kubernetes distribution for AI?
Canonical Charmed Kubernetes is a strong open-source option, running on Ubuntu with native GPU support. It includes Charmed Kubeflow and MLflow, and is optimized for on-premises and edge deployments. The open-source version is free, with Ubuntu Pro starting at $25 per node per year.
Which Kubernetes distribution is best for compliance?
SUSE Rancher Prime is focused on security and compliance, with FIPS 140-2 and SELinux enforcement. It includes NeuVector for runtime security and Longhorn for encrypted storage. Rancher Prime is ideal for regulated industries requiring SOC 2 and HIPAA compliance.
FAQ
What are the key features to look for in a Kubernetes distribution for AI?
Look for GPU scheduling, MLOps integration, storage performance, and ecosystem support. Ensure the distribution supports your specific GPU hardware and provides efficient scheduling for multi-GPU training. Also consider security features and scalability from a single node to thousands.
How important is GPU scheduling in a Kubernetes distribution?
GPU scheduling is critical for AI workloads. It enables efficient allocation of GPU resources, including MIG partitioning and time-slicing. Without proper scheduling, you may underutilize expensive GPUs or face resource contention. Look for distributions with native GPU operators and node feature discovery.
What is the cost of Red Hat OpenShift AI?
OpenShift AI pricing starts at $1,500 per core per year for the AI add-on, which includes enterprise support. This is a premium price, but it includes integrated MLOps, security, and multi-cloud management. The cost is justified for enterprises needing a complete AI platform.
Can I run AI workloads on a free Kubernetes distribution?
Yes, Canonical Charmed Kubernetes is free and supports AI workloads. It includes Charmed Kubeflow and MLflow, and runs on Ubuntu. However, you may need to pay for support or additional features like Ubuntu Pro for security patches and compliance.
What is the difference between managed and self-managed Kubernetes for AI?
Managed distributions like GKE and EKS handle cluster operations, reducing administrative overhead. Self-managed options like OpenShift and Rancher offer more control and customization. Managed services are easier to start with, while self-managed provides flexibility for complex AI workloads.
How does storage affect AI workload performance?
AI workloads require high-throughput, low-latency storage for datasets and model checkpoints. Distributions that integrate with parallel file systems like Lustre or NVMe storage can significantly improve performance. Evaluate storage options for dynamic provisioning and tiered storage to balance cost and speed.
What is the role of MLOps in Kubernetes distributions?
MLOps integration provides pre-configured pipelines for data versioning, experiment tracking, and model serving. Distributions like OpenShift AI include Kubeflow and MLflow out of the box. This reduces the effort needed to manage the ML lifecycle and improves collaboration.
How do I choose between NVIDIA AI Enterprise and OpenShift AI?
Choose NVIDIA AI Enterprise if you need maximum GPU performance and deep NVIDIA ecosystem integration. It includes Triton and NeMo. Choose OpenShift AI if you want a fully managed AI platform with built-in pipelines and security. Consider your team's expertise and workload requirements.
What are the common pitfalls when running AI on Kubernetes?
Common pitfalls include underprovisioning networking bandwidth, neglecting resource quotas, and ignoring storage performance. Ensure your cluster has high-speed inter-node networking like InfiniBand. Set proper resource limits to prevent runaway jobs from starving other workloads.
Is VMware Tanzu good for AI workloads?
Yes, Tanzu is best for hybrid environments running vSphere. It integrates with vSphere with Tanzu to run Kubernetes pods directly on ESXi hosts with NVIDIA vGPU passthrough. Tanzu includes Kubeflow and MLflow, making it a viable option for enterprises with existing VMware infrastructure.
Sources
- https://www.redhat.com/en/technologies/cloud-computing/openshift/openshift-ai
- https://www.nvidia.com/en-us/data-center/kubernetes/
- https://cloud.google.com/kubernetes-engine/docs/concepts/ai-ml-on-gke
- https://aws.amazon.com/eks/
- https://azure.microsoft.com/en-us/services/kubernetes-service/
- https://ubuntu.com/kubernetes
- https://www.vmware.com/products/tanzu.html
- https://www.suse.com/products/rancher/
- https://kubernetes.io/docs/concepts/cluster-administration/
- https://www.cncf.io/
Related on PULSE
- [More kubernetes distributions for ai workloads rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 aiThe 10 Best AI Data Labeling Services in 2027
 aiThe 10 Best AI Storage Solutions for Large Datasets in 2027
 aiThe 10 Best AI Feature Stores for Production in 2027
 aiThe 10 Best AI Tools for PHP Development in 2027
 aiThe 10 Best AI Tools for Web Prototyping in 2027
 aiThe 10 Best AI Tools for Angular Development in 2027
 aiThe 10 Best AI Tools for Tailwind CSS in 2027
 aiThe 10 Best AI Tools for Blog Writing for Websites in 2027
 aiThe 10 Best AI Tools for Web Caching in 2027
 aiThe 10 Best AI Tools for On-Page SEO in 2027