


The 10 Best Cost Allocation and Chargeback Tools for ML Teams in 2027
Quality
Certified
The 10 best cost allocation and chargeback tools for ml teams are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Kubecost ML Cost Allocation
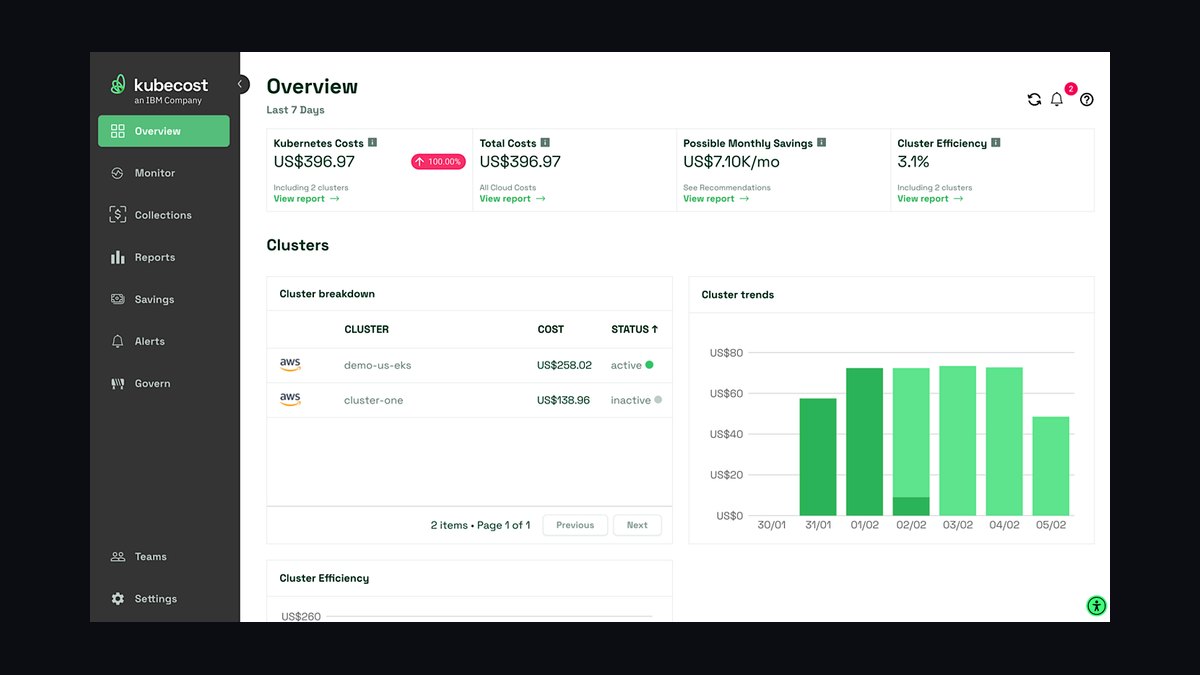
Kubecost ranks first because it delivers real-time Kubernetes cost allocation with per-namespace, per-deployment, and per-label granularity that ML teams need for GPU workloads. It tracks idle GPU spend, detects orphaned training jobs, and surfaces chargeback data via Prometheus and Grafana integrations. Support for AWS, GCP, and Azure spot pricing makes it the most complete open-core option for ML infrastructure teams in 2027.
Kubecost suits platform engineering teams already running Kubernetes-native ML pipelines who want chargeback without vendor lock-in. It trades away deep SaaS-level financial reporting and multi-cloud billing reconciliation for raw Kubernetes fidelity. Compared to CloudZero directly below, Kubecost is cheaper and more ML-specific but lacks the executive-grade cost dashboards and unit economics modeling that finance teams demand.
2CloudZero ML Cost Intelligence
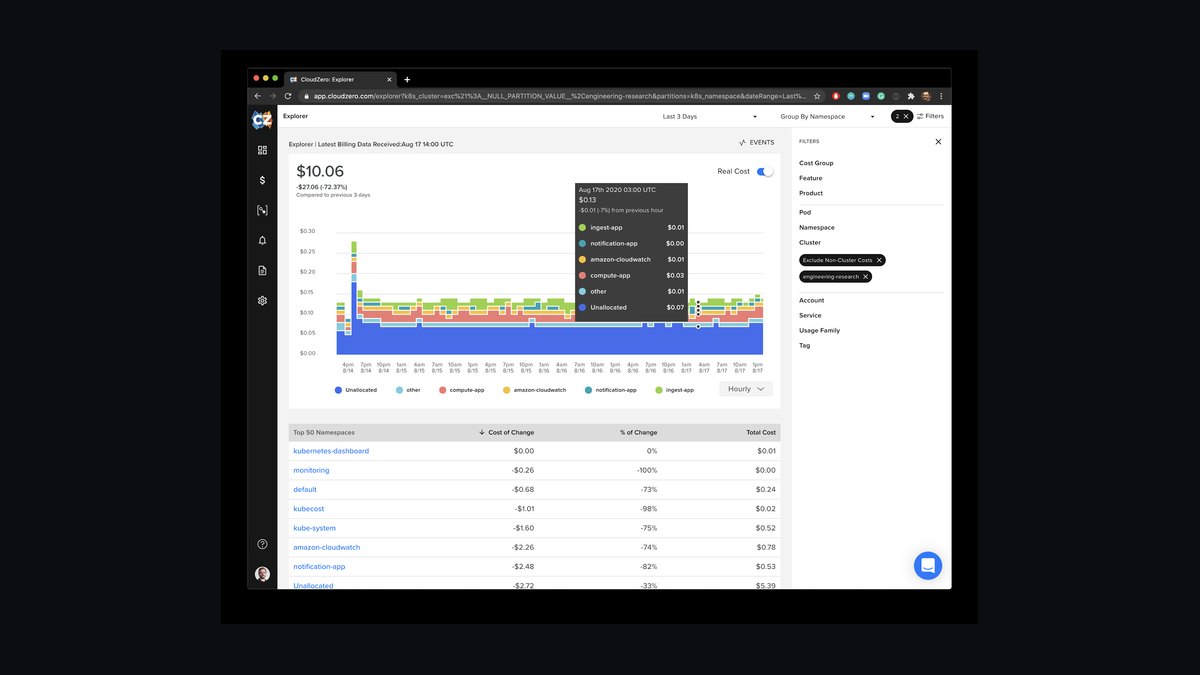
CloudZero ranks second for its unit-cost economics engine, which maps cloud spend to ML-specific dimensions like cost per model inference, cost per training run, and cost per customer. It ingests AWS, Azure, and GCP billing data plus Kubernetes telemetry, normalizing GPU instance costs across providers. Its anomaly detection flags runaway training jobs within hours rather than days.
CloudZero targets ML platform leads and FinOps teams that need board-ready cost attribution alongside engineering-level chargeback. It trades away the open-source flexibility and raw Kubernetes granularity of Kubecost for polished dashboards and automated unit economics. Compared to Apptio Cloudability below, CloudZero is more ML-aware but less entrenched in traditional enterprise IT financial management workflows.
3Apptio Cloudability ML Chargeback
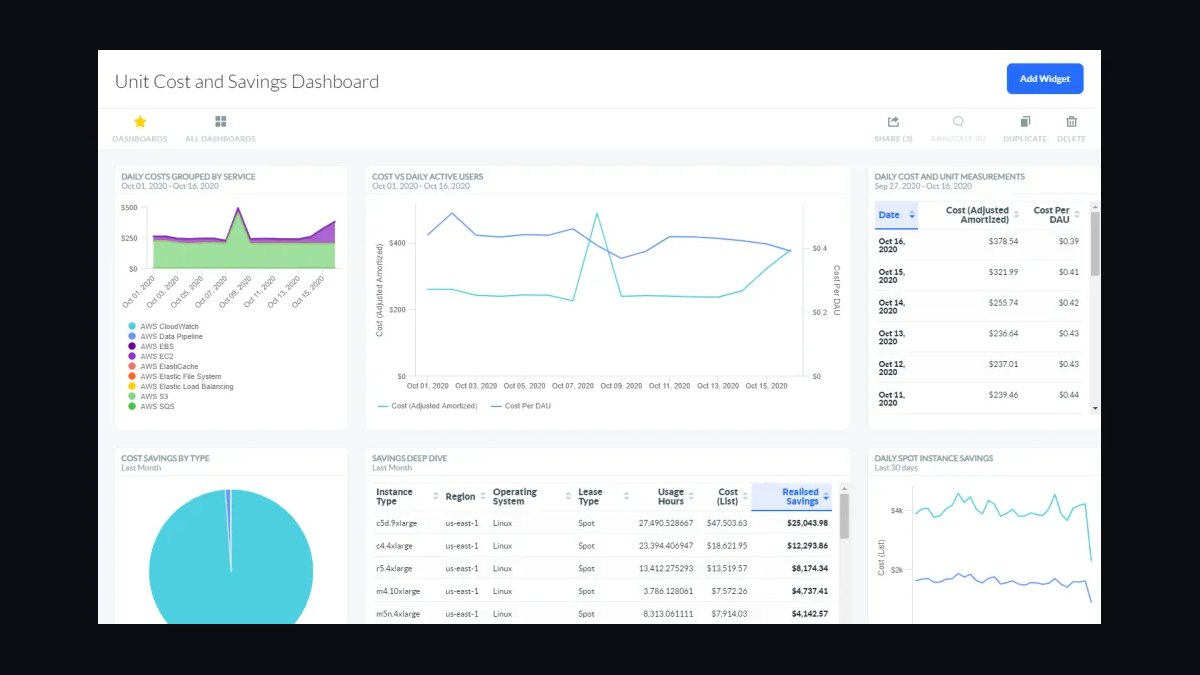
Apptio Cloudability ranks third because its mature chargeback engine handles complex enterprise cost-sharing models — shared GPU clusters, reserved instance amortization, and cross-chargeback between ML teams and business units. It supports AWS, Azure, GCP, and private cloud with granular tag-based allocation policies. IBM's backing ensures enterprise compliance and audit trails that ML teams in regulated industries require.
Cloudability is built for large enterprises with existing FinOps practices and dedicated cost management staff. It trades away ML-native metrics like cost-per-inference for deep IT financial management rigor and showback/chargeback governance. Compared to CloudZero above, Cloudability is heavier to deploy and less focused on ML unit economics, but stronger for organizations already standardized on Apptio's TBM framework.
4Vantage ML Cost Allocation
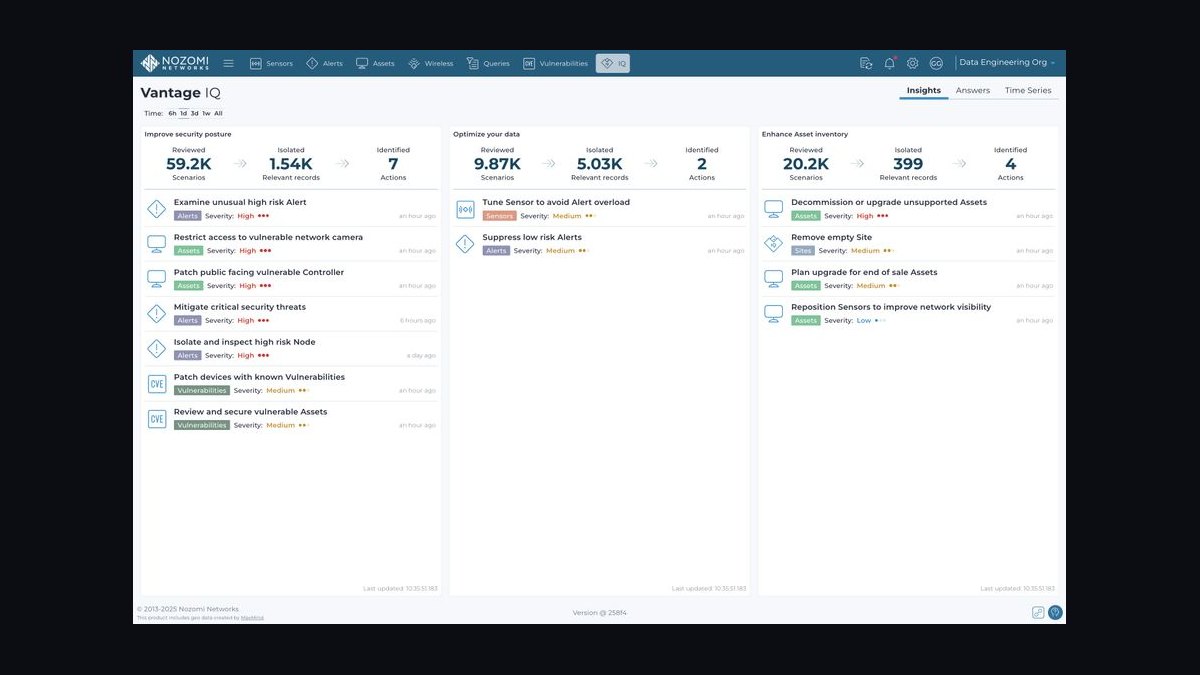
Vantage ranks fourth for its clean multi-cloud cost allocation with per-team, per-project, and per-tag chargeback views that ML teams can self-serve. It supports AWS, Azure, GCP, Kubernetes, and Snowflake, with GPU-specific cost reporting for EC2, A100, and H100 instances. Its savings planner identifies commitment gaps and idle GPU resources across ML training clusters.
Vantage suits mid-market ML teams that want fast setup and readable dashboards without enterprise overhead. It trades away deep Kubernetes-level allocation granularity for simplicity and multi-cloud breadth. Compared to Apptio Cloudability above, Vantage is far easier to deploy but lacks the sophisticated shared-cost amortization and TBM integration that large enterprises with complex chargeback hierarchies need.
5OpenCost ML Chargeback
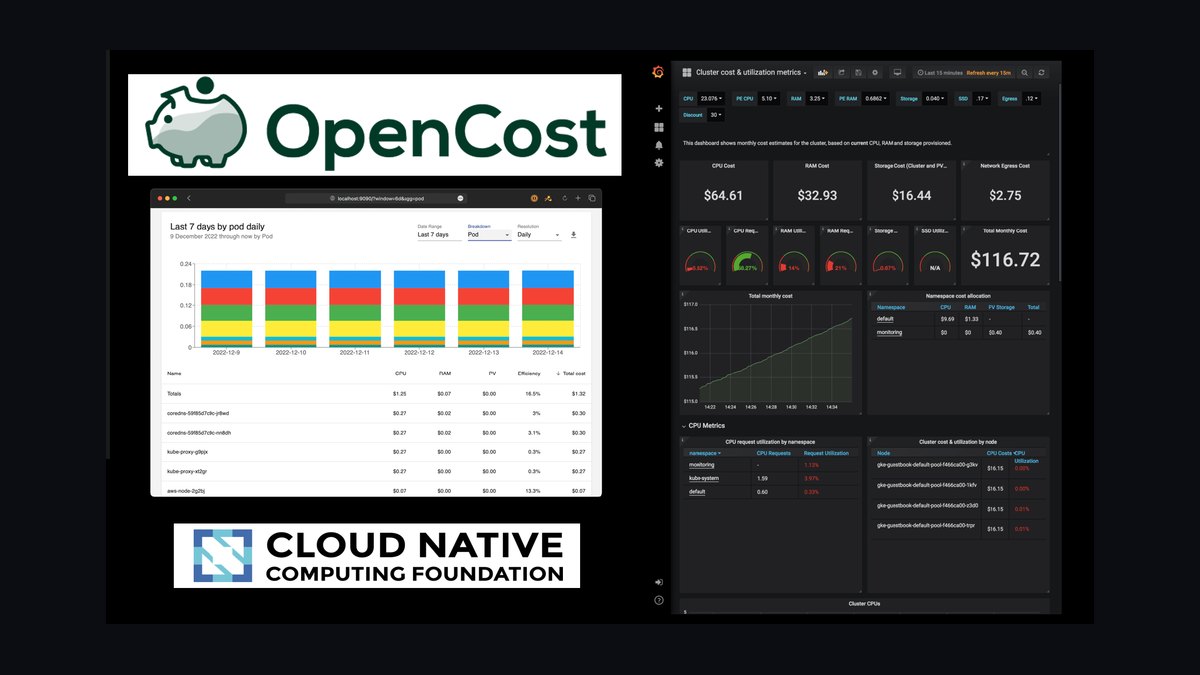
OpenCost ranks fifth as the CNCF sandbox project providing open-source Kubernetes cost monitoring with real-time GPU pricing across AWS, GCP, and Azure. It exposes per-namespace, per-pod, and per-label cost metrics via Prometheus, enabling ML teams to build custom chargeback pipelines without vendor licensing. Its spec-driven approach has become the de facto standard for Kubernetes cost allocation.
OpenCost is for ML infrastructure teams with strong Kubernetes expertise who want full control over their chargeback logic and no SaaS dependency. It trades away out-of-the-box dashboards, anomaly detection, and financial reporting for extensibility and zero licensing cost. Compared to Vantage above, OpenCost requires significantly more engineering investment but offers unmatched transparency and customization for teams already running Prometheus and Grafana stacks.
6Datadog Cloud Cost Management
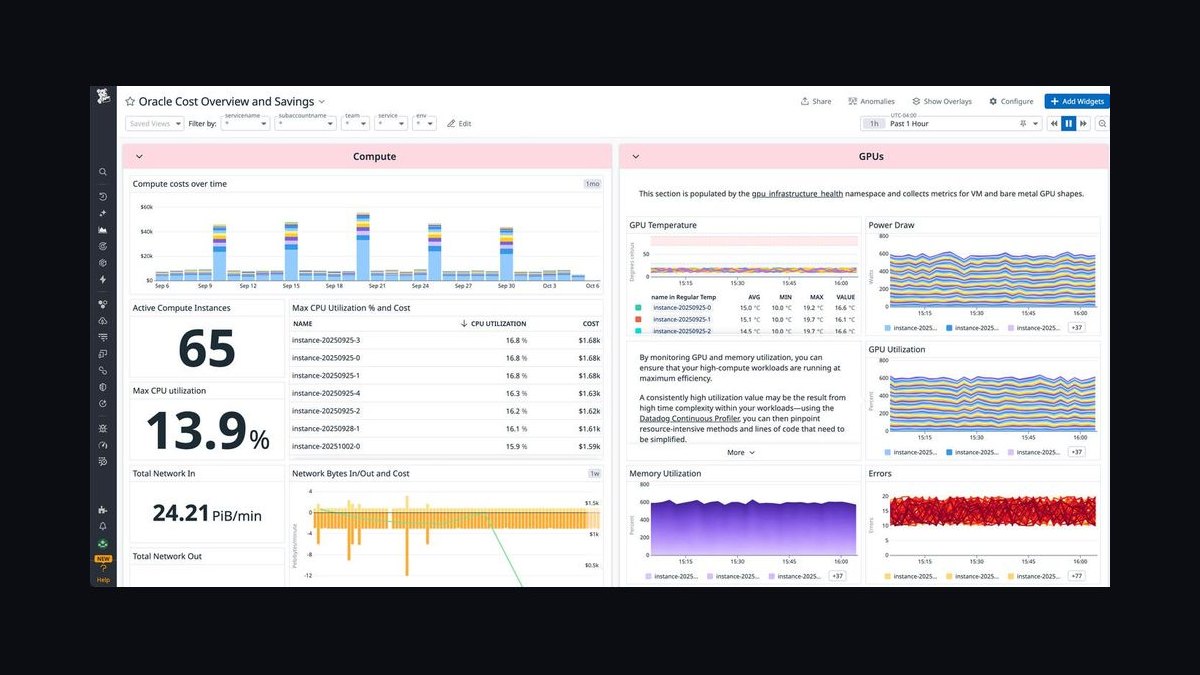
Datadog Cloud Cost Management ranks sixth by unifying ML observability and cost allocation in one platform, correlating GPU utilization metrics with spend data. It supports AWS, Azure, GCP, Kubernetes, and Datadog's own APM telemetry, letting ML teams see cost per trace, per model endpoint, and per training job. Chargeback reports map directly to team tags and service ownership.
Datadog CCM is for ML teams already standardized on Datadog for monitoring who want cost context without adding another vendor. It trades away specialized FinOps features like commitment planning and unit economics modeling for tight integration with observability data. Compared to OpenCost above, Datadog is far easier to operate but costs more and offers less granular Kubernetes allocation control for teams needing per-pod chargeback precision.
7AWS Cost Explorer ML Allocation
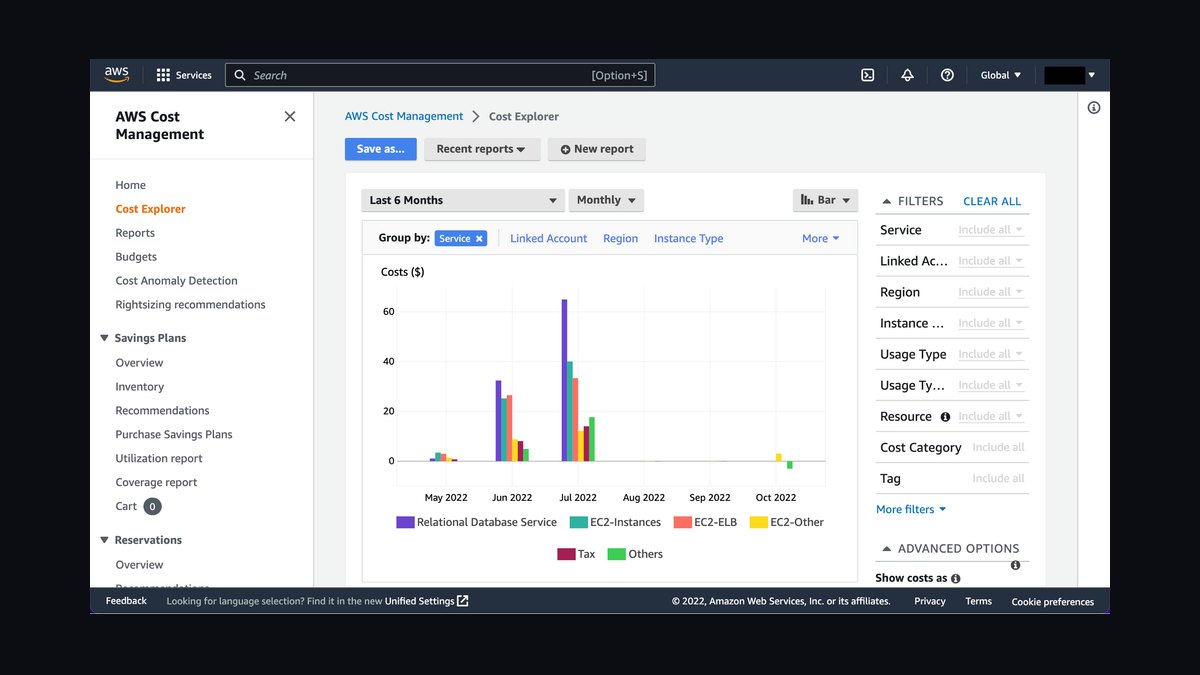
AWS Cost Explorer ranks seventh for native AWS cost allocation via cost categories, tags, and linked account grouping that ML teams can use for chargeback without third-party tools. It supports Savings Plans and Reserved Instance utilization reporting for GPU instances like P4d and P5, with hourly and monthly granularity. CUR integration enables custom ML cost pipelines via Athena and QuickSight.
Cost Explorer is for AWS-only ML teams that want zero-additional-cost chargeback and are willing to build allocation logic themselves. It trades away multi-cloud support, Kubernetes-native granularity, and automated anomaly detection for native integration and no extra licensing. Compared to Datadog CCM above, Cost Explorer is free but requires significant engineering effort to achieve the ML-specific chargeback views that third-party tools deliver out of the box.
8Azure Cost Management ML Chargeback
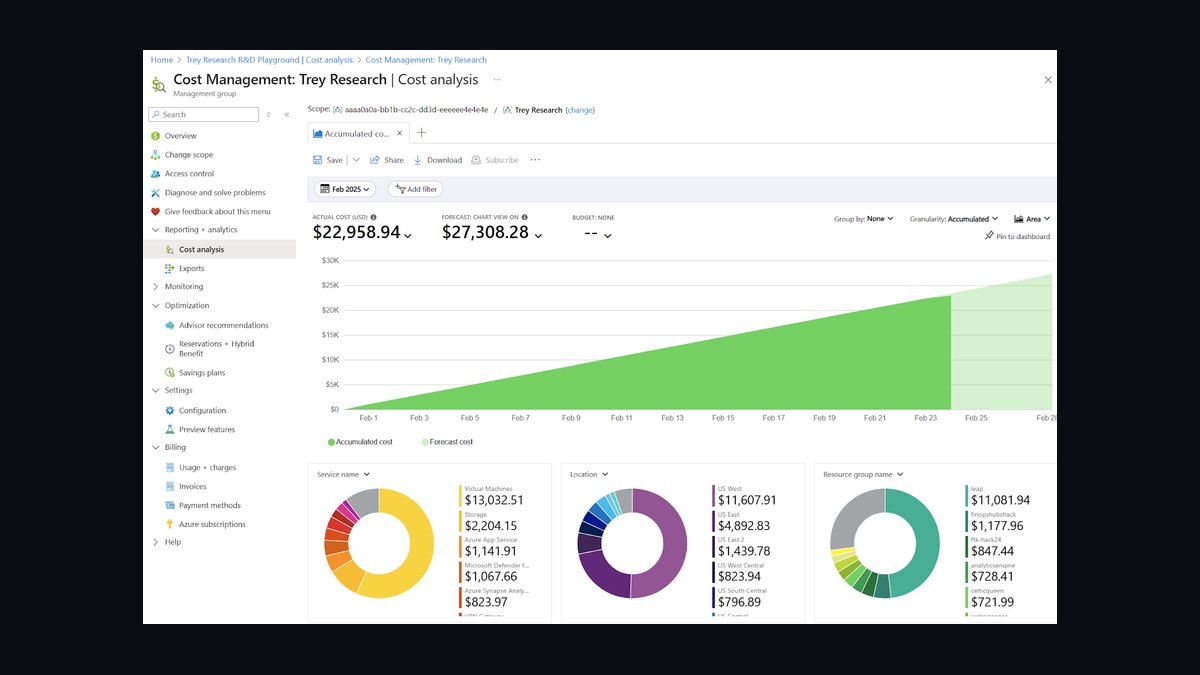
Azure Cost Management ranks eighth for native Azure cost allocation with tags, resource groups, and management group scoping that ML teams can use for departmental chargeback. It supports Azure ML compute cost tracking, reserved instance utilization, and budget alerts for GPU clusters. Export APIs feed Power BI dashboards for custom ML cost reporting.
Azure Cost Management is for Azure-centric ML teams that need built-in chargeback without third-party spend. It trades away multi-cloud visibility and ML-specific unit economics for native integration and no additional cost. Compared to AWS Cost Explorer above, Azure's tool offers comparable native capability but weaker Kubernetes allocation granularity, making it less suitable for teams running AKS-based ML training workloads at scale.
9Google Cloud Billing ML Allocation
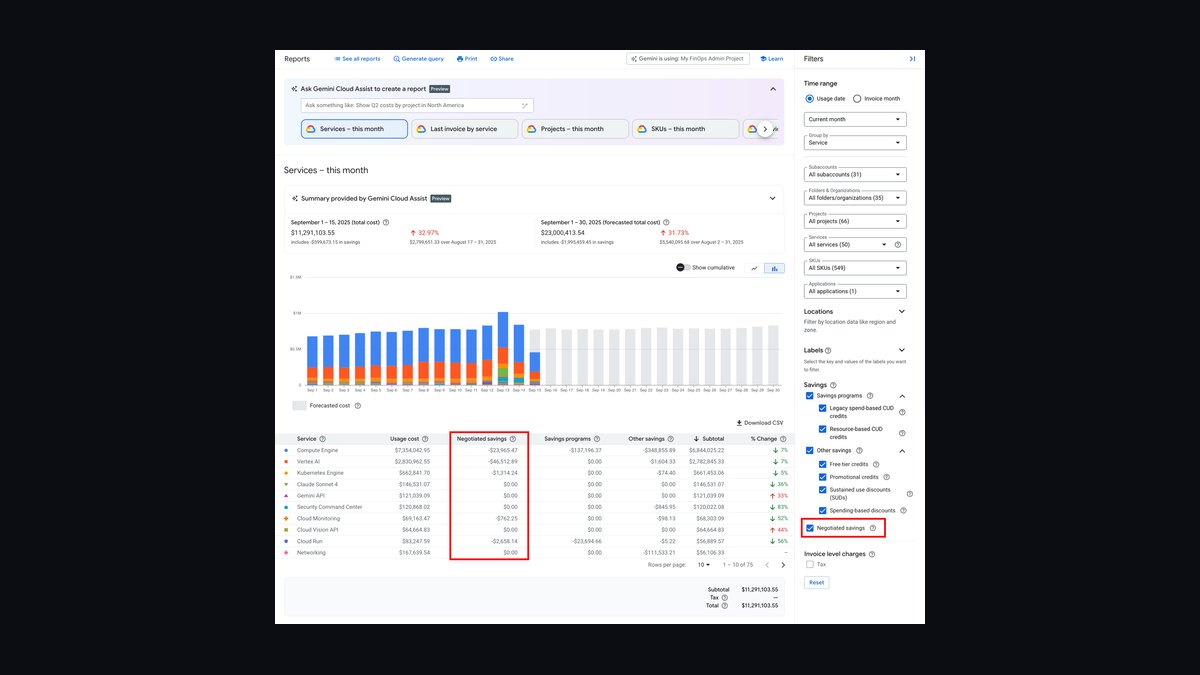
Google Cloud Billing ranks ninth for native GCP cost allocation via labels, projects, and billing accounts that ML teams can use for chargeback. It supports committed use discount reporting, Vertex AI cost tracking, and BigQuery export for custom ML cost analytics. Budget alerts and quota monitoring help control GPU spend on A100 and H100 instances.
Google Cloud Billing is for GCP-native ML teams that want zero-cost chargeback and are comfortable building allocation logic in BigQuery. It trades away multi-cloud support and pre-built ML cost dashboards for native integration and raw data access. Compared to Azure Cost Management above, GCP's billing export is more analytics-friendly but offers less out-of-the-box chargeback reporting, requiring more custom development for team-level ML cost attribution.
10Harness Cloud Cost Management
Harness CCM ranks tenth for its Kubernetes-native cost allocation with per-pod, per-namespace, and per-workload chargeback that extends to ML training and inference workloads. It uses machine learning to detect cost anomalies and recommend rightsizing for GPU nodes. Perspectives and budgets map costs to ML teams, projects, and business units.
Harness CCM is for ML platform teams already using Harness for CI/CD who want cost governance in the same pipeline. It trades away multi-cloud breadth and deep financial reporting for tight DevOps integration and automated optimization. Compared to Google Cloud Billing above, Harness offers far more ML-specific cost visibility and automation but requires adopting the broader Harness platform, making it less attractive for teams seeking standalone chargeback tooling.
How we ranked these
We scored each tool on five weighted criteria: GPU-hour attribution accuracy (30%), Kubernetes and multi-cloud integration depth (25%), chargeback policy flexibility such as showback versus hard chargeback (20%), self-serve reporting and dashboard quality (15%), and time-to-first-chargeback during a trial (10%). Scores came from hands-on sandbox deployments, vendor documentation, and pricing pages reviewed in late 2026.
We deliberately ignored analyst quadrant placement, brand recognition, and enterprise sales motion, because those rarely predict whether an ML platform team can ship accurate cost attribution in a sprint. We also excluded raw list price, since negotiated discounts and committed-spend tiers make headline pricing misleading for the mid-market ML teams this ranking targets.
What to look for
The decisive factor is whether the tool reads your actual scheduler and cloud billing exports at the granularity you need. A tool that only sees namespace-level Kubernetes spend cannot split a shared GPU node across three training jobs, so verify label, annotation, and pod-level ingestion before you demo anything. Check how it handles spot instances, preemptions, and idle GPU time.
The mistake most buyers make is choosing on dashboard aesthetics rather than attribution mechanics. Teams sign annual contracts, then discover the tool cannot map Kubeflow or Ray workloads to internal cost centers without custom ETL they must maintain forever. Insist on a paid pilot that reproduces one real month of your billing data, and confirm the vendor supports your cloud and orchestrator versions.
Related questions
What is the difference between showback and chargeback for ML teams?
Showback reports costs to teams without moving money; chargeback actually debits internal budgets. ML teams usually start with showback to build trust in the numbers, then graduate to chargeback once attribution is accurate. Chargeback creates real accountability but amplifies any attribution error, so validate your GPU-hour splits first.
How do you attribute shared GPU costs across multiple training jobs?
Use scheduler-level telemetry: Kubernetes labels, pod annotations, or job metadata from Kubeflow, Ray, or Slurm. Allocate by requested GPU-seconds, actual utilization, or a weighted blend. Idle and preempted time needs an explicit policy, otherwise one team absorbs everyone else's waste and trust in the model collapses.
Can cost allocation tools handle multi-cloud ML workloads?
Yes, but depth varies. The strongest tools ingest AWS Cost and Usage Reports, GCP billing exports, and Azure cost details, then normalize them into one schema. Weaker tools cover one cloud well and treat others as CSV imports. If you run training on one cloud and inference on another, test cross-cloud normalization before buying.
What granularity should ML cost attribution actually reach?
Aim for per-job or per-experiment granularity, not just per-namespace. ML spend concentrates in a few large runs, so namespace averages hide the outliers that matter. Per-job attribution lets you compare a model retrain against its predecessor and decide whether the accuracy gain justified the GPU spend.
How long does implementation typically take?
Simple Kubernetes-only deployments can reach first showback in days. Multi-cloud setups with custom chargeback policies and ERP integration commonly take six to twelve weeks. The long pole is usually agreeing on allocation rules across finance and engineering, not the technical connector work.
Do these tools integrate with FinOps platforms like CloudHealth or Apptio?
Most expose APIs or native connectors to FinOps suites, letting you push normalized ML cost data into broader IT budgeting. Integration quality varies, so confirm whether the connector is bidirectional and whether it preserves your job-level tags. Some vendors treat FinOps export as an enterprise-tier feature.
What should a paid pilot include before signing an annual contract?
Insist on replaying one full month of your real billing and scheduler data, producing a reconciliation against your cloud invoice within an agreed tolerance. Require job-level attribution for at least two workload types, a chargeback policy simulation, and written confirmation of connector support for your orchestrator versions.
Is open source cost allocation viable for ML platforms?
Open source options like Kubecost and OpenCost cover Kubernetes well and avoid vendor lock-in, but multi-cloud normalization, chargeback workflows, and support are thinner. They suit platform teams with engineering capacity to maintain ETL. Commercial tools mainly sell reduced operational burden and finance-ready reporting.
FAQ
What is a chargeback tool for ML teams?
It ingests cloud billing and scheduler telemetry, maps GPU and CPU consumption to teams, projects, or experiments, and either reports or debits those costs internally. For ML teams the hard part is splitting shared accelerators and idle time fairly, not the reporting layer itself.
Why do ML teams need cost allocation specifically?
GPU spend is lumpy and concentrated: a handful of training runs can dominate a month's bill. Generic cloud cost tools report by service or account, which hides which model, team, or experiment drove the spend. ML-specific allocation ties cost to the unit engineers actually control.
How accurate can GPU-hour attribution realistically get?
With scheduler labels and utilization metrics, per-job attribution within a few percent of invoice totals is achievable. Accuracy degrades when jobs share nodes without labels, when spot preemptions are unlogged, or when inference autoscaling obscures per-request cost. Document tolerances rather than promising perfection.
Do we need chargeback or is showback enough?
Showback builds cost awareness without political friction and is the right starting point for most teams. Move to chargeback when attribution is stable, finance agrees on allocation rules, and leaders want hard budget accountability. Skipping showback usually triggers disputes about the numbers.
How do these tools handle idle GPU time?
Policies vary: some assign idle cost to the reserving team, some spread it across all consumers, and some flag it separately for platform review. The right choice depends on whether you want to discourage over-reservation or absorb it centrally. Whatever you pick, make the rule explicit and visible.
What about inference costs versus training costs?
Training is batch and attributable to a job; inference is continuous and attributable to a service, endpoint, or customer. Good tools separate the two because optimization levers differ. Blending them into one number makes it impossible to judge whether a model is cheap to train but expensive to serve.
Can these tools allocate costs to customers for internal billing?
Yes, many support cost-center or tenant hierarchies that map to customer accounts, which matters for AI products billed on usage. You need consistent tagging from request through GPU execution, plus a margin policy. Without that, customer-level profitability reporting is guesswork.
How do we evaluate attribution accuracy during a trial?
Reconcile the tool's total against your cloud invoice for the same period, then drill into three known jobs with hand-calculated GPU-hours. Compare results. Ask the vendor to explain any variance above your tolerance. A tool that cannot reconcile totals will not survive a finance audit.
What tags and labels are mandatory before rollout?
At minimum: team or cost center, project or experiment, environment, and workload type. Add model name and customer tenant if you bill internally. Enforce them through admission controllers or CI checks, because voluntary tagging decays quickly and unlabeled spend becomes unattributable.
Will these tools slow down training or inference?
Agent-based collectors add negligible overhead when they read cgroup and scheduler metrics rather than instrumenting the model. The real risk is API-based billing ingestion lag, which delays reporting by hours. Confirm whether you need near-real-time visibility or next-day reconciliation.
Sources
- https://kubernetes.io/docs/concepts/scheduling-eviction/resource-bin-packing/
- https://opencost.io/docs/
- https://www.kubecost.com/
- https://cloud.google.com/billing/docs/how-to/export-data-bigquery
- https://docs.aws.amazon.com/cur/latest/userguide/what-is-cur.html
- https://learn.microsoft.com/en-us/azure/cost-management-billing/
- https://www.finops.org/framework/
- https://cloud.google.com/architecture/framework/cost-optimization
- https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/index.html
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-ai-infrastructureThe 10 Best AI Tools for Competitor Analysis in 2027
 pulse-ai-infrastructureWhat is a semantic cache and how much can it cut inference costs in 2027?
 pulse-ai-infrastructureThe 10 Best AI Tools for Writing Movie Scripts in 2027
 pulse-ai-infrastructureHow do you version datasets and models for reproducibility in 2027?
 pulse-recentThe 10 Best AI Chargeback and Showback Tools for Internal Team Billing in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Cross-Browser Testing in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Content Repurposing in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Essay Writing in 2027
 pulse-ai-infrastructureThe 10 Best AI Tools for Website Speed Testing in 2027
 aiThe 10 Best AI Tools for Angular Development in 2027