
Top 10 Sales KPIs for Text-to-Speech (TTS) Voice AI in 2027
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
Quality
Certified
The 10 best sales kpis for text-to-speech (tts) voice ai are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1. TTS Net New ARR
Net new ARR ranks first because it is the only metric that captures fresh logo revenue plus expansion in a single figure, and every other KPI on this list either feeds it or explains it. Track it monthly with the two components separated, since expansion carrying more than 70% of net new ARR for two consecutive quarters signals a broken new-logo engine that consumption tailwind temporarily masks.
It is built for CROs and finance leads who need one number for board reporting, and it trades away diagnostic detail — a flat ARR line tells you nothing about whether quality, latency, or pricing caused the stall. Compared with net revenue retention directly below, it is the gross measure rather than the efficiency measure, and the two must be read together.
2. TTS Net Revenue Retention
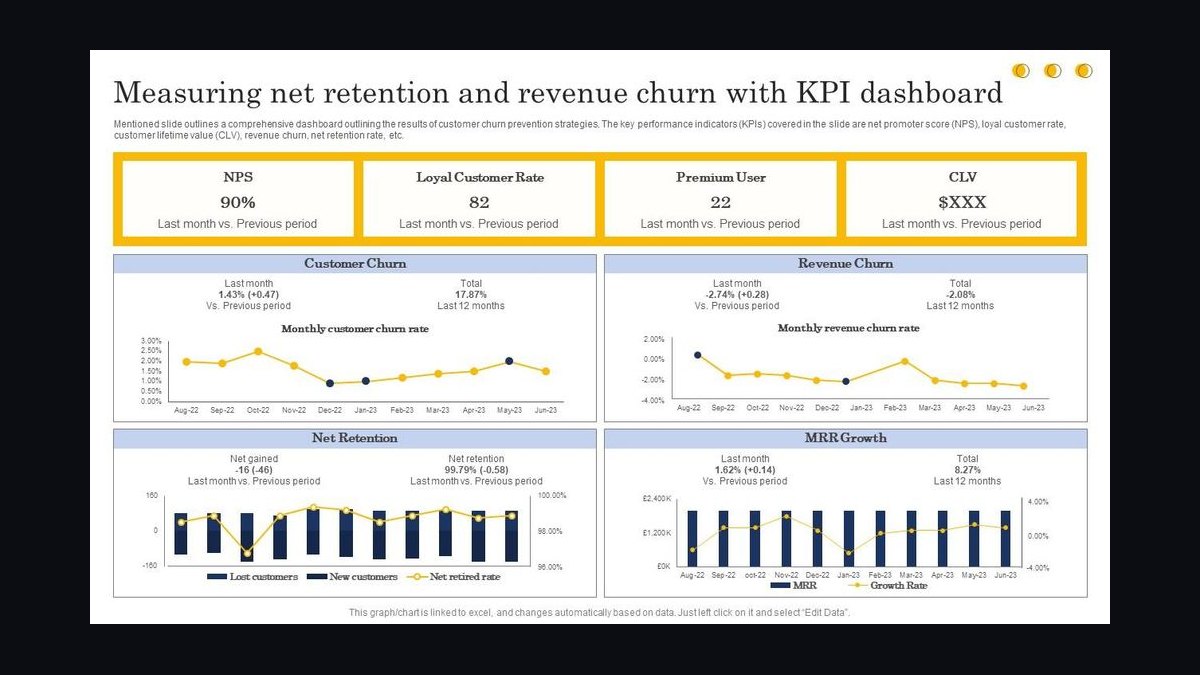
Net revenue retention ranks second because it separates a business growing on genuine customer expansion from one quietly leaking logos. Consumption-led speech vendors can reach 130–160% since usage compounds with the customer's own product growth, while enterprise-contract vendors run a healthy 110–130% band because expansion arrives in annual negotiated steps rather than continuously.
It is for revenue leaders and investors who need to know whether the installed base is deepening or eroding. It trades away new-logo signal entirely, so a strong NRR can hide a collapsing acquisition engine. Compared with net new ARR above, it measures the existing base only; compared with renewal rate below, it captures expansion that renewals ignore.
3. TTS Characters Synthesized Monthly
Characters synthesized per month ranks third because it is the headline volume number for any consumption-led TTS business, typically reported in billions and running into the tens of billions for platforms aggregating across their base. The aggregate figure is nearly useless alone, so split it three ways: batch versus streaming, cloned versus library voice, and by language.
It is for product and finance teams modeling unit economics, since those three splits reveal where cost sits, where the moat sits, and where the next expansion motion lives. It trades away quality signal completely — high volume at 3.6 MOS is a churn pipeline. Compared with cost per million characters below, it is the numerator; cost is the denominator.
4. TTS Voice Cloning MOS
Voice cloning quality in Mean Opinion Score ranks fourth because it decides blind listening bake-offs, and above roughly 4.5 is best-in-class while 4.0–4.5 is professionally usable and below 4.0 fails most commercial use cases. Cloned voices typically score slightly below library voices because output quality is bounded by source-recording quality.
It is for product leaders and sales engineers defending enterprise deals where fidelity is the deciding criterion. It trades away cost discipline — chasing MOS burns inference budget that consumption-first competitors avoid. Compared with streaming latency below, MOS governs whether a voice is acceptable at all; latency governs whether it is usable in real time.
5. TTS Streaming Latency P95
Streaming latency at P95 time-to-first-byte ranks fifth because the tail is what end users actually experience, and the mean hides it. Sub-200ms is competitive for streaming synthesis, the sub-100ms tier is where real-time conversational agents operate, and past roughly 500ms conversational applications feel broken regardless of how good the voice sounds.
It is for engineering and customer success teams supporting conversational and IVR workloads, where a latency regression is immediately visible to end users and generates escalations. It trades away relevance for batch content customers, who tolerate 500ms without noticing. Compared with cost per million characters below, latency is the quality-of-experience axis while cost is the margin axis.
6. TTS Cost Per Million Characters
Cost per million characters ranks sixth because it is the margin lever in a consumption business, and it must be tracked as realized price after volume discounts rather than list. The dangerous pattern is a stable blended number while the mix shifts toward cloned and emotionally-controlled voices, which carry meaningfully higher inference cost than standard library voices.
It is for finance and pricing teams defending gross margin as the customer base scales. It trades away fidelity headroom, since the cheapest routing usually means the least expressive model. Compared with characters synthesized monthly above, cost is the denominator that turns volume into revenue; compared with multilingual coverage below, cost varies sharply by language.
7. TTS Multilingual Coverage
Multilingual coverage ranks seventh because thirty-plus languages is the practical bar for global enterprise and fifteen covers regional deployments, but raw counts mislead without a quality dimension. A language supported at 3.6 MOS is a language you lose deals in, so the useful artifact is an internal coverage matrix with a MOS column per language that reps can actually see.
It is for sales teams qualifying global enterprise deals where the requirement list is non-negotiable and typically includes Spanish, French, German, Portuguese, Japanese, Mandarin, Korean, and Hindi. It trades away depth for breadth, since thin quality in many languages is worse than excellence in a few. Compared with renewal rate below, coverage wins deals that renewal rate later confirms.
8. TTS Twelve-Month Renewal Rate
Twelve-month renewal rate ranks eighth because it is the lagging confirmation that everything upstream worked. Enterprise contracts should renew in the high eighties to low nineties, while self-serve and small-business tiers run 60–80% and that is normal rather than alarming. The number worth watching is renewal segmented by integration depth.
It is for customer success leaders deciding where to spend finite attention, since accounts with voice embedded in a production workflow renew far more reliably than episodic content users. It trades away forward-looking signal entirely — by the time renewal moves, the cause happened two quarters ago. Compared with net revenue retention above, renewal ignores expansion and isolates pure retention.
9. TTS Clone Approval Rate
Clone approval rate ranks ninth because it measures the share of cloning attempts a customer accepts as production-ready on the first try, which predicts onboarding friction better than any other early signal. A sustained decline usually points at a specific accent or recording-condition weakness rather than general model quality.
It is for onboarding and solutions teams diagnosing why technically strong clones still stall in customer workflows. It trades away comparability across vendors, since approval criteria are customer-specific and no industry benchmark exists. Compared with voice cloning MOS above, MOS measures how good a voice sounds to a rater while approval rate measures whether a specific customer shipped it.
10. TTS API Call Growth Rate
API call growth rate month over month ranks tenth because it separates many-small-realtime-calls from few-large-batch-jobs, a distinction no character-volume metric can make. High call growth with flat character volume means customers are shipping conversational products, the highest-value pattern in the category, and it should trigger a different sales motion entirely.
It is for product and sales leadership watching for the shift from episodic content production to embedded conversational deployment. It trades away stability as a planning metric, since call counts swing with end-user traffic nobody can forecast at signature. Compared with characters synthesized monthly above, it captures deployment shape rather than raw volume.
How we ranked these
We ranked the nine TTS sales KPIs by how directly each one moves revenue in 2027: net new ARR, net revenue retention, characters synthesized monthly, voice library size, cloning MOS, P95 streaming latency, cost per million characters, multilingual coverage, and twelve-month renewal rate. Weighting favored metrics that predict expansion or renewal over vanity catalog counts, and split scoring between consumption-led and enterprise-contract business models rather than assuming one motion.
We deliberately ignored list-price comparisons, raw model parameter counts, and total voice catalog size, because none of them survive contact with a real buying decision. We also excluded hyperscaler attach-rate metrics, since bundled cloud speech is priced to make the speech metric irrelevant. Benchmark bands reflect practitioner ranges, not vendor marketing claims, and every figure assumes telemetry reconciled against billing before it is trusted.
What to look for
What actually matters is fit between your workload and the vendor's scoreboard. Conversational agents need sub-200ms P95 time-to-first-byte and high call counts; dubbing and audiobooks need MOS above 4.5 and a defensible voice-rights indemnification position. Ask for P95 latency segmented by voice and region, effective library size, and a per-language MOS matrix rather than a coverage count. Demand clone approval rate data from onboarding cohorts.
The mistake most buyers make is running a single blended bake-off and picking the winner on average MOS. Blended numbers hide the specific accent, language, or streaming path that will generate your escalations. Test your actual scripts, in your actual languages, under your actual concurrency, and price the realized cost per million characters after volume discounts and voice-type mix. Also confirm who owns the cloned voice and what happens if a performer objects.
Related questions
What is a good net revenue retention rate for a TTS voice AI vendor?
Consumption-led speech businesses can reach 130–160% because customer usage compounds with their own product growth. Enterprise-contract vendors typically run 110–130%, since expansion arrives in annual steps rather than continuously. The absolute number matters less than its decomposition: gross retention, expansion from existing endpoints, and expansion from genuinely new use cases inside the same account. Flat NRR alongside a flat win rate usually means nobody has chosen a scoreboard.
How is Mean Opinion Score used in TTS vendor selection?
MOS is a 1–5 human rating across naturalness, intelligibility, and prosody. Above roughly 4.5 is best-in-class; 4.0–4.5 is professionally usable; below 4.0 fails most commercial work and quietly disqualifies you from bake-offs. Clone MOS usually runs slightly below library-voice MOS because it depends on source-audio quality. Insist on a standing rater panel and a fixed script set, or you will confuse rater drift with model regression.
What streaming latency do conversational voice agents actually need?
Sub-200ms P95 time-to-first-byte is competitive for streaming synthesis, and the sub-100ms tier is where real-time conversational agents live. Past roughly 500ms, applications feel broken and buyers stop caring about your MOS. Always request P95 rather than mean, because the mean hides the tail end users actually experience. Remember end-to-end latency sums ASR, language model, synthesis, and network, so your fast synthesis can still sit inside a sluggish round trip.
How many languages does an enterprise TTS vendor need to support?
Thirty-plus languages is the practical bar for global enterprise deployments; fifteen covers most regional rollouts. Coverage counts mislead without a quality dimension, though. A language you technically support at 3.6 MOS is a language you will lose deals in. Publish an internal coverage matrix with a MOS column per language and let sales see it, so reps disqualify early instead of burning a quarter on a deal the voice cannot win.
What is a reasonable cost per million characters for TTS in 2027?
Track realized price after volume discounts, not list, and segment it by cohort and voice type. Cloned and emotionally-controlled voices carry meaningfully higher inference cost than standard library voices. The dangerous pattern is a stable blended number while the mix shifts toward expensive voices, which erodes margin silently for two quarters. If a customer complains about per-character price, they are often actually complaining about total pipeline cost, so show the breakdown.
Why does voice library size matter less than vendors claim?
Anyone can pad a catalog, which makes library size the most gameable number in the category. What matters is effective library size: how many voices a paying account used in the last 90 days. Most vendors discover 15–25% of the catalog carries essentially all usage. That reframes the roadmap from adding voices to adding voices specifically in the accents and languages where deals are currently lost.
What renewal rate should an enterprise TTS contract expect?
Enterprise contracts should renew in the high eighties to low nineties. Self-serve and small-business tiers run dramatically lower, often 60–80%, and that is normal rather than alarming. The number worth watching is renewal rate segmented by integration depth: accounts that embedded voice into a production workflow renew far more reliably than accounts using it for episodic content. That gap should drive where customer success spends its time.
How do you decide between a consumption and enterprise sales motion for TTS?
Look at four things. If your top ten accounts exceed 55–60% of revenue, you are already enterprise. If top-fifty accounts swing 30% or more month to month, consumption forecasting is unreliable and you need committed contracts. If losses cluster around blind listening tests and voice rights, quality is your constraint. If new accounts reach steady-state usage within 30–45 days, land-and-expand is weak and you should price for commitment at signature.
FAQ
What are the key sales KPIs for the Text-to-Speech Voice AI industry in 2027?
Nine metrics run the business: net new ARR, net revenue retention, characters synthesized monthly, voice library size, cloning quality in Mean Opinion Score, streaming latency at P95, cost per million characters, multilingual coverage, and twelve-month renewal rate. Quality, latency, and language breadth decide most competitive deals. Consumption-led and enterprise-contract vendors weight these differently, so pick your scoreboard before you build dashboards.
What is the difference between a consumption and a quality scoreboard in TTS?
A consumption scoreboard headlines characters synthesized per month, with NRR as a second-order effect and cost per million characters as the margin lever. A quality-and-commitment scoreboard headlines MOS, cloning fidelity, and multilingual coverage, with annual contract value and renewal rate as the commercial metrics. The two reward opposite behavior, so a team measuring both without a tiebreaker ships a roadmap that is expensive on both axes and best-in-class on neither.
How should a TTS vendor instrument metrics in the first 90 days?
Days 1–30: reconcile character-synthesis telemetry against billing until they agree within about 1%, stand up P95 latency segmented by voice type and region, and fix a MOS script set with a standing rater panel. Days 31–60: build the per-account view joining characters, latency, MOS, and contract terms, and ship an internal multilingual coverage matrix. Days 61–90: put quality, latency, and unit cost in the same quarterly review as pipeline and renewals.
What cadence should TTS metric reviews follow?
Daily belongs to product telemetry: characters, P95 latency, error rates, MOS spot samples. Weekly belongs to commercial signal: NRR run-rate, cloning adoption, quality outliers, open escalations. Monthly belongs to slower business metrics: logo churn, per-million-character cost trend, multilingual adoption, voice and language rollouts. Quarterly is where architecture, voice library roadmap, and multilingual expansion get decided, because those have lead times measured in months and weekly reactions produce thrash.
What is clone approval rate and why does it matter?
Clone approval rate is the share of cloning attempts a customer accepts as production-ready on the first try. It predicts onboarding friction better than any other early signal. A sustained decline usually points at a specific accent or recording-condition weakness rather than general model quality, which makes it an unusually actionable diagnostic. Track it per segment, and treat a falling rate as a product signal rather than a customer-education problem.
How does workload archetype change which TTS KPIs matter?
Content production is batch-dominant and latency-insensitive, so MOS and cost per character dominate. Conversational agents and IVR are streaming-dominant and brutally latency-sensitive, with huge call counts and modest characters per call. Media localization and dubbing hinge on cloning fidelity and voice-rights licensing, with legal questions arriving before technical ones. Accessibility and public-sector deployments bring steady, predictable volume and heavy multilingual requirements.
Why is P95 latency more useful than mean latency for TTS?
The mean hides the tail that end users actually experience, and the tail is what generates escalations. A vendor can post an excellent average while a specific voice or region routinely spikes past a second. Report P95 segmented by voice type, region, and streaming versus batch, because a blended number will conceal exactly the path causing your support load. Sophisticated buyers ask for this split before they run a bake-off.
What are the most common failure modes when tracking TTS sales KPIs?
Sitting below 4.0 MOS quietly disqualifies you from professional work, and nobody tells you — you simply stop appearing in bake-offs. A stable blended cost per character can mask a mix shift toward expensive cloned voices. Expansion carrying more than 70% of net new ARR for two quarters signals a broken new-logo engine. And measuring both scoreboards without choosing a tiebreaker produces a roadmap that wins on neither axis.
How does end-to-end pipeline latency affect TTS vendor blame?
Most Voice AI deployments in 2027 are not standalone. The speech layer sits between an automatic speech recognition front end and a language model, and perceived latency is the sum of all three plus network. Your sub-150ms synthesis can still land inside a 1.2-second round trip the customer experiences as sluggish. Instrument the full pipeline in customer deployments or publish latency budget guidance, because the alternative is being blamed for someone else's bottleneck.
What adjacent metrics should be added once the core nine are stable?
Two are worth adding. Clone approval rate predicts onboarding friction and usually points at a specific accent or recording-condition weakness rather than general model quality. API call growth rate month over month separates many-small-realtime-calls from few-large-batch-jobs; high call growth with flat character volume means customers are shipping conversational products, the highest-value pattern in the category, and it should trigger a different sales motion entirely.
Sources
- https://www.gartner.com/en/newsroom/press-releases
- https://www.mckinsey.com/capabilities/quantumblack/our-insights
- https://www2.deloitte.com/us/en/insights/industry/technology.html
- https://www.nvidia.com/en-us/ai-on-rtx/nvidia-rtx-voice/
- https://cloud.google.com/text-to-speech
- https://aws.amazon.com/polly/
- https://azure.microsoft.com/en-us/products/ai-services/text-to-speech
- https://www.elevenlabs.io/
- https://arxiv.org/list/eess.AS/recent
- https://www.isca-archive.org/interspeech_2024/index.html
Related on PULSE
- [More sales kpis for text-to-speech (tts) voice ai rankings and buying guides](/knowledge)
- [PULSE Tools and calculators](/tools)
- [Everything on PULSE RevOps](/)
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
 pulse-industry-kpisTop 10 KPIs for Dance Studios in 2027
 pulse-industry-kpisTop 10 KPIs for HVAC Contractors in 2027
 pulse-industry-kpisTop 10 Sales KPIs for equine breeding in 2027
 pulse-industry-kpisTop 10 Sales KPIs for GPU Cloud Provider in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Branded Drug Manufacturer in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Code Review in 2027
 pulse-industry-kpisTop 10 KPIs for Preschools in 2027
 pulse-industry-kpisTop 10 Sales KPIs for AI Music Generation in 2027
 pulse-industry-kpisTop 10 Sales KPIs for Computer Vision API in 2027
 pulse-industry-kpisTop 10 Sales KPIs for EDA (Electronic Design Automation) Software in 2027