
How do longer sales cycles in Q1 2027 correlate with the rise of AI-based deal risk prediction?
 Curated byKory White · Fractional CRO · Maryland
 PULSEKNOWLEDGE LIBRARY
Quality
Certified
Longer sales cycles and AI-based deal risk prediction correlate because prediction tools surface problems earlier, and surfaced problems get worked rather than ignored. Every flagged risk triggers remediation — stakeholder mapping, proof rebuilds, legal review — that adds calendar time. Buyer-side AI compounds it. Cycles stretch; forecast accuracy and late-stage survival rates improve in exchange.
A deal that should have closed in March
Picture a mid-market RevOps team selling a $180K annual platform contract into a manufacturing company. In 2023 this deal ran a predictable path: discovery in week two, demo in week four, security review in week seven, signature by week eleven. Eleven weeks, give or take, and the rep's gut told them roughly where it stood.
Now run the same deal through a stack where a revenue intelligence tool scores it continuously. Week three, the model drops the deal's health score because the economic buyer hasn't joined a call and email response latency from the champion has doubled. That's a real signal — it usually is. But now it's visible, timestamped, and sitting in a dashboard the VP of Sales reviews every Monday. The rep can't shrug it off. A remediation motion starts: re-map the buying committee, get a second champion, build an ROI model specific to this plant's downtime costs. That work is genuinely good work. It also takes three weeks.
Week nine, the buyer's procurement team runs the proposal through their own AI-assisted evaluation tooling, which benchmarks the pricing against comparable contracts and flags two clauses as non-standard. Legal gets pulled in on both sides. Another two to three weeks.
Week fourteen, the model flags renewed risk because a new stakeholder — a plant IT director who wasn't in the original map — has appeared on the thread. Another discovery loop.
The deal closes in month six instead of month three. And here's the part that makes the correlation hard to argue with from inside the org: it *closed*. The 2023 version of this deal, without the flags, had maybe a coin-flip chance of going dark in month four when the unmapped IT director surfaced an integration objection nobody had answered. The prediction layer didn't slow the deal down out of malice. It found the things that would have killed the deal and forced someone to deal with them, and dealing with them takes time.
That's the whole shape of the correlation in one anecdote. Every mechanism described below is a variation on it — visibility creates obligation, obligation consumes calendar, calendar shows up as cycle length. The question worth asking isn't whether the tools lengthen cycles. It's whether the time bought back in win rate, forecast accuracy, and avoided late-stage collapse is worth the calendar.
How the mechanism actually works
The causal chain has four links, and each one is observable in a CRM if you instrument for it.
Link one: detection moves earlier. Classical pipeline hygiene caught problems at stage-gate reviews — a human looked at a deal when it tried to advance. That's a checkpoint model: risk surfaces on a schedule, and only for deals attempting to move. A prediction model scores continuously, including deals that are sitting still. Sitting still is itself a strong negative signal, and it's the one checkpoint reviews structurally miss because a stalled deal never triggers a gate. So the population of deals under scrutiny expands, and the moment of scrutiny moves weeks earlier.
Link two: a flag creates an obligation. This is the underrated link. A risk score that nobody acts on doesn't change cycle time at all — it's a number in a column. Cycle time only moves when the flag is wired to a workflow: a task gets created, a manager gets notified, a deal review gets scheduled. Teams that deploy prediction and *don't* operationalize it see no cycle change and no win-rate change. Teams that wire it in see both. If you're trying to work out whether your own cycles will lengthen after a rollout, the honest predictor isn't the model's accuracy — it's whether your ops team built the automation.
Link three: remediation is slower than the thing it replaces. The pre-AI alternative to remediation was usually *hope*, which takes zero days. Replacing hope with stakeholder mapping, a rebuilt business case, a champion-enablement session, and an executive-alignment call takes real weeks. There's no version of this where the substitution is time-neutral.
Link four: the buyer runs the same play. Procurement organizations have their own analytical tooling — spend platforms, contract-review assistants, benchmarking data. When a buyer can rapidly compare your pricing to comparable agreements and auto-flag clause deviations, the seller has to answer questions that previously never got asked. Symmetric capability, asymmetric effect on calendar: both sides adding diligence means the sum adds up on the seller's cycle-time report.
Notice the loop at the bottom. Outcome data feeds the model, and the model's next generation is trained partly on cycles that were themselves lengthened by the previous generation. That's not a flaw — it's how any feedback-controlled system behaves — but it does mean "the model says deals like this take five months" is a statement about your own process as much as about the market.
What the numbers actually support, and what they don't
Be careful here, because this topic attracts confident-sounding figures with no provenance. What's genuinely well-documented across published sales research is directional:
Buying committees have grown. Enterprise B2B purchases involving six to ten-plus stakeholders is a well-replicated finding in Gartner's buyer research, and the practical consequence is arithmetic: each additional stakeholder adds scheduling latency, an approval step, and a new objection surface. A committee of ten with a two-week average scheduling lag per required meeting produces cycle length that has nothing to do with sales skill.
Cycles have lengthened in the enterprise segment. This shows up consistently in vendor benchmark reports and in public SaaS company disclosures during periods of budget scrutiny. The cause is over-determined — macro budget tightening, CFO-level approval thresholds dropping, procurement centralization, and yes, more diligence tooling. Anyone attributing the entire lengthening to AI risk prediction is overselling. Anyone claiming prediction tooling is cycle-neutral is ignoring the mechanism.
Forecast accuracy improves with structured signal capture. Also well-supported directionally: teams that capture engagement data systematically forecast better than teams relying on rep-submitted commit calls. The magnitude varies enormously by baseline discipline.
What is *not* well-supported, and what you should refuse to repeat: precise accuracy percentages attributed to named vendor models, precise "weeks added per flag" figures, or industry-wide win-rate deltas quoted to the point. Those numbers circulate widely and almost always trace back to a vendor's own marketing sample rather than an independent study.
So instead of borrowing numbers, instrument your own. Here's the measurement design that actually answers the question for your business:
Segment before you compare. Split by deal size band, segment, and product line. Aggregate cycle time is nearly meaningless when your mix shifts — a quarter with more enterprise deals shows "longer cycles" with no process change whatsoever. Mix shift is the single most common false positive in this analysis.
Use a cohort, not a period. Compare deals *created* in a window, not deals *closed* in a window. Closed-in-period cohorts are structurally biased: fast deals appear in the same quarter they started, slow ones spill forward, so any period where volume changed distorts the average.
Measure stage-level dwell time, not just total. Total cycle length hides the mechanism. If prediction tooling is doing what's described here, you'll see dwell time increase specifically in mid-funnel validation stages and possibly *decrease* in late stages, because problems that used to surface at contract time surfaced earlier. If your increase is concentrated in legal and procurement instead, the driver is buyer-side process, not your prediction layer.
Track the flag-to-action lag separately. Time from risk flag to first remediation action is a pure process metric you control. If it's measured in days, your team is engaged. If it's measured in weeks, the flags are decorative and any cycle lengthening you're seeing has a different cause.
Watch pull-forward on losses. The strongest evidence that prediction is working isn't win rate — it's that lost deals are being *identified as lost earlier*. Time-to-disqualification dropping while time-to-win rises is the healthy pattern. It means rep capacity is being reallocated off dead deals, which is worth more than the cycle-length line item costs.
Hold the counterfactual honestly. You cannot A/B test this cleanly in most orgs, but you can compare teams that adopted the workflow automation early against teams that adopted late, controlling for segment. It's imperfect. It's still better than a before-and-after chart spanning a macro shift.
Trade-offs, and the alternatives nobody names
The framing "AI risk prediction makes cycles longer" implies a straightforward cost. It isn't straightforward, because the alternative isn't "same deals, shorter cycles." The alternative is a different distribution of outcomes.
What you buy with the extra calendar time. Fewer surprise late-stage losses, which are the most expensive kind — full cost of sale spent, zero revenue. Better forecast reliability, which has downstream value in headcount planning and, for public companies, in guidance credibility. Earlier disqualification, which returns rep hours to live pipeline. And a documented deal history that makes deal reviews substantive instead of theatrical.
What you pay. Longer cycles mechanically reduce pipeline velocity, which reduces bookings per rep per year unless win rate rises enough to offset. There's a real math threshold: if cycles lengthen 30% and win rate rises less than roughly 30%, throughput went down. Run that arithmetic for your own numbers before declaring the program a success.
Alert fatigue is the failure mode that eats the benefit. A model that flags 40% of pipeline as at-risk is functionally flagging nothing. Reps triage by ignoring. The tuning question — what threshold, what flag volume a team can genuinely act on — matters more than model accuracy. A less accurate model with a threshold set so that 10–15% of deals get flagged, all of which get worked, beats a more accurate model flagging half the pipeline into noise.
Segment sensitivity is extreme. Velocity businesses — self-serve, low-ACV, short consideration — should probably not wire risk flags to mandatory remediation at all. The overhead exceeds the deal value. The economics only work above a deal size where several weeks of seller effort is cheap relative to contract value.
Regulated industries already have the diligence. In healthcare, financial services, and government, procurement rigor is mandated. Adding seller-side prediction there produces less incremental lengthening because the buyer was already going to take that long. The correlate is weaker precisely where cycles are longest.
The alternative approaches worth considering. Rather than a full prediction layer, some RevOps teams get most of the value from three deterministic rules: flag any deal with no economic-buyer contact by stage three, flag any deal with no activity in fourteen days, flag any deal where the close date has slipped twice. Those rules are transparent, cheap, and generate the same remediation obligation without a model. They also lengthen cycles for exactly the same reason. If your team is debating a prediction purchase, run the deterministic rules for a quarter first — you'll learn whether your reps will actually act on flags, which is the real variable.
Pitfalls, and how teams avoid them
Blaming the tool for the mix. The most common analytical error. Cycle time went up 25% and prediction tooling went live the same quarter, so the tool caused it. Meanwhile the team moved upmarket and average deal size doubled. Always segment before attributing.
Treating the risk score as a forecast. A risk score estimates probability of an adverse event under current conditions. It is not a commit number, and using it as one produces a forecast that moves every time a rep logs an email. Keep the two artifacts separate: score drives action, forecast drives commitments.
Letting remediation become unbounded. A flagged deal with no time limit on remediation becomes a zombie — worked forever, never disqualified. Put a clock on it. Two remediation cycles without a score improvement should force a decision, not a third cycle. This single rule prevents most of the pathological cycle inflation people blame on the tooling.
Ignoring the reverse causation. Longer cycles also *cause* higher risk scores, because time-in-stage is an input to nearly every model. A deal that's slow for benign reasons — buyer's fiscal year, a holiday period, a reorg — gets flagged for slowness, triggering remediation, which consumes more time. Teams that add a "known-benign delay" flag that suppresses scoring for a defined window break this spiral cheaply.
Scoring on inputs reps control. If activity volume drives the score and the score drives manager attention, reps will generate activity. You'll get logged calls that didn't advance anything. Weight the model toward buyer-side signals — response latency, meeting acceptance, stakeholder breadth — which reps can influence but not manufacture.
Skipping the enablement. The tools produce flags; converting a flag into a better outcome requires the rep to know what to do about *that specific risk type*. "No economic buyer engaged" and "competitor mentioned in three calls" need entirely different plays. Teams that ship the model without a play-per-risk-type get the cycle cost and none of the win-rate benefit — the worst quadrant.
Not preparing for buyer-side tooling. Sellers still walking in with a generic ROI deck get taken apart by a procurement team with benchmarking data. The counter is to bring the specificity preemptively: named assumptions, defensible sources, a model the buyer can manipulate themselves. It costs seller time upfront and saves cycle time later, which is the same trade in miniature.
Declaring victory on the wrong metric. Forecast accuracy improving is easy to celebrate and easy to game — a team that sandbags everything forecasts accurately and grows nothing. Pair every accuracy claim with a throughput claim.
Related questions
Does the correlation hold for renewals and expansions?
Weakly. Renewal risk models flag churn signals, but the remediation motion is usually a customer-success play running in parallel with the renewal rather than blocking it. Cycle lengthening is minimal; the effect shows up as earlier intervention instead.
Can you get the win-rate benefit without the cycle cost?
Partially — by tightening flag thresholds so fewer, higher-confidence deals get worked, and by time-boxing remediation. You won't eliminate the cost. Surfacing a real problem and then fixing it takes time by definition.
How long before the lengthening stabilizes?
Typically two to three quarters after workflow automation goes live, once the backlog of previously-invisible risk in existing pipeline has been worked through. The first quarter overstates the steady-state effect substantially.
Does this apply to inbound and product-led motions?
Much less. Where the buyer self-educates and the contract is small, there's no committee to map and no procurement gauntlet. Prediction tooling in those motions is better aimed at expansion timing than deal risk.
What's the first metric to instrument?
Flag-to-first-action lag. It separates "our tooling changed behavior" from "our tooling generated dashboards," and everything else you'd want to measure is uninterpretable until you know which situation you're in.
FAQ
Is the relationship between longer cycles and AI deal risk prediction causal or just coincidental timing?
Both are happening at once, which is exactly why it's easy to overclaim. There is a genuine causal mechanism — flags create remediation obligations that consume calendar time — and it's observable at the stage level in any CRM. But cycles have also lengthened for reasons entirely independent of prediction tooling: larger buying committees, centralized procurement, lower CFO approval thresholds, and general budget scrutiny. The honest position is that prediction tooling is one contributing driver among several, and its share of the effect is measurable in your own data if you segment properly and look at stage-level dwell time rather than aggregate cycle length.
If the tools make cycles longer, why would a RevOps team adopt them?
Because cycle length is one term in an equation, not the whole equation. The value proposition is fewer late-stage collapses, earlier disqualification of dead deals, and forecast numbers that survive contact with the quarter. A deal that takes six months and closes beats a deal that takes three months and dies in month four with full cost of sale already spent. The adoption case fails only when win rate doesn't rise enough to offset the velocity loss — which happens, and which is why measuring throughput rather than any single component metric matters.
How many deals should a well-tuned model flag?
There's no universal number, but the operating constraint is capacity, not accuracy. Ask how many remediation motions your team can genuinely run per rep per month, multiply out, and set the threshold so flag volume lands under that. Most teams that complain about alert fatigue set thresholds by model confidence rather than by team capacity, and end up flagging far more pipeline than anyone can work. Flags nobody acts on are worse than no flags — they teach the team to ignore the system.
Do buyer-side evaluation tools really affect seller cycle time?
Yes, and it's the part sellers most often underestimate. When a procurement organization can rapidly benchmark your pricing and auto-flag contract clauses that deviate from their standards, questions get asked that previously went unasked. Each question is a round trip: legal review, revised terms, re-approval. The practical counter is to front-load specificity — bring defensible assumptions and standard terms into the proposal rather than defending them reactively three weeks later.
Should smaller teams with shorter cycles bother with this at all?
Generally no, not as a purchased prediction layer. Below a deal size where several weeks of seller effort is economically justified, the remediation overhead exceeds the value recovered. Smaller teams get most of the benefit from three deterministic rules — no economic buyer by mid-funnel, no activity in two weeks, close date slipped twice — which cost nothing and produce the same behavioral obligation. Start there and only graduate to a model when flag volume outgrows manual review.
What single change most improves the trade-off?
Time-boxing remediation. Cap it at two cycles: if a deal's risk profile hasn't materially improved after two remediation attempts, force an explicit decision to advance or disqualify. This one rule prevents the zombie-deal pattern that produces most of the pathological cycle inflation teams blame on their tooling, and it converts the prediction layer from something that slows everything down into something that sorts deals faster.
Sources
- Gartner — Sales buyer behavior and buying group research
- Harvard Business Review — The New Sales Imperative
- McKinsey — B2B sales growth and analytics insights
- Forrester — B2B research and buyer insights
- Salesforce — State of Sales research
- HubSpot Research — sales and CRM benchmarks
- Gong Labs — sales research and benchmarks
- Clari — revenue operations resources
- MIT Sloan Management Review — AI and analytics research
Related on PULSE
- How is AI reshaping the B2B sales funnel in Q1 2027 away from linear stages?
- How does the 2027 rise of AI-based procurement agents change the way sellers structure initial discovery calls?
- Why are longer sales cycles in 2027 driving adoption of AI-based meeting summarization tools?
- What slip prediction indicators show deals moving outside forecast window?
- How do RevOps teams measure pipeline velocity when deal sizes shift upmarket?
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 revopsWhat 2027 vendor consolidation scenario breaks the handoff between SDR and AE when both use different AI co-pilots?
 revopsAre longer sales cycles in 2027 forcing RevOps to redefine the 'MQL-to-revenue' attribution model?
 revopsWhich vendor consolidation patterns are signaling a shift toward single-platform GTM stacks in 2027?
 revopsHow are 2027 buying committees using generative AI to compare vendor pricing before any contact?
 revopsWhy are sales cycles extending for companies without AI adoption playbooks in 2027?
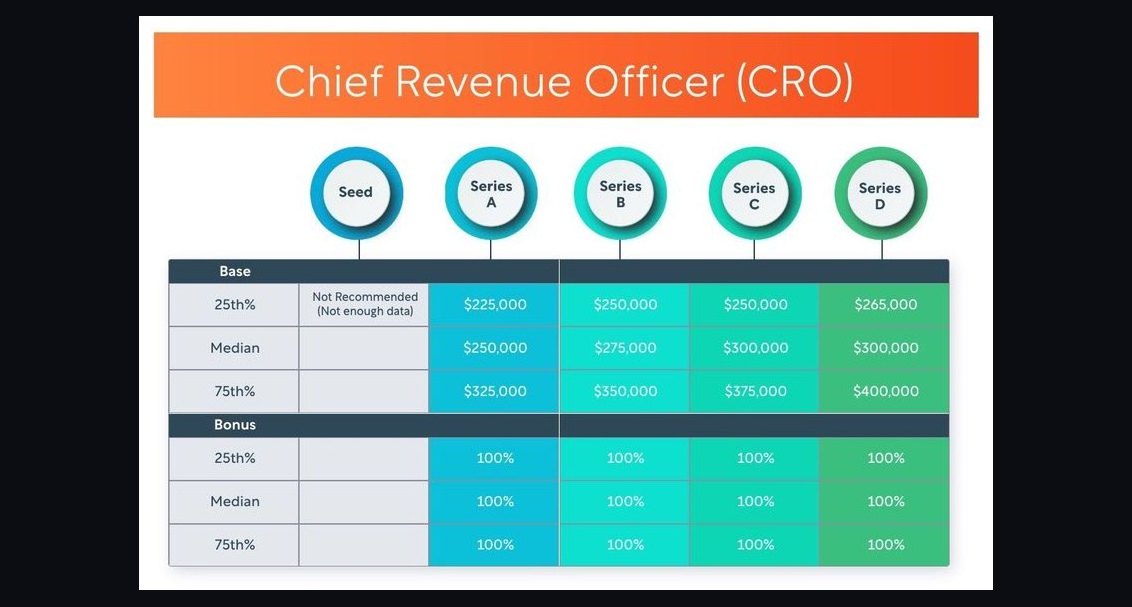 revopsCRO compensation — fractional, full-time, equity in 2027
 revopsWhy Do Buying Committees Now Insist on AI-Generated ROI Proof Before Vendor Demos in 2027?
 revopsIs the rise of the 14-person buying committee making vendor consolidation a necessity for RevOps efficiency in 2027?
 revopsWhat role does AI play in reducing vendor bloat for enterprise GTM stacks in 2027?
 revopsHow do you prioritize the RevOps backlog in 2027?