


Top 10 Best Tech Stack Tools for Mid-Size Logistics Tech Companies in 2027
Quality
Certified
The 10 best tech stack tools for mid-size logistics tech companies are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Temporal Cloud
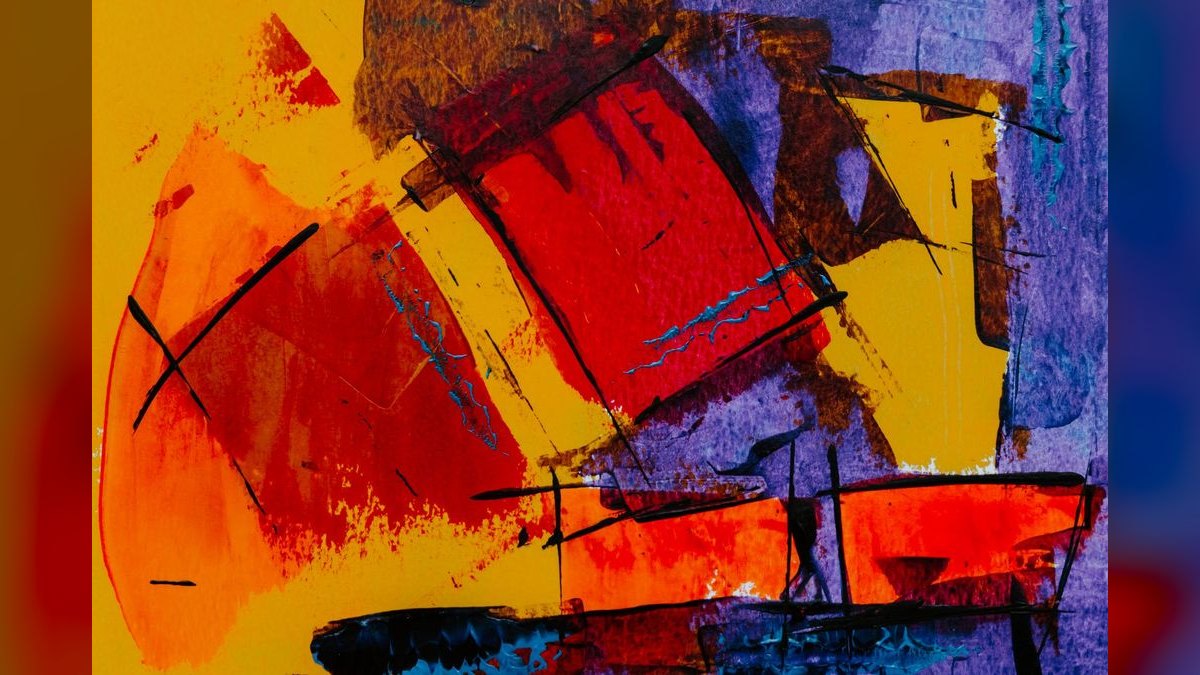
Temporal Cloud ranks first because it removes the Cassandra and Elasticsearch operational burden that consumes 0.5–1.5 full-time engineers on self-hosted Cadence. The managed service handles server-side scaling, persistence, and visibility storage, so your team runs only workers and application code. For spiky freight volume, that converts lumpy on-call load into a predictable usage-based line item.
It is built for mid-size logistics teams without spare platform engineers, where shipment orchestration reliability maps directly to revenue. It trades away raw cost control at massive steady-state throughput and some data-residency flexibility. Compared to self-hosted Cadence directly below, Temporal Cloud costs more per action but eliminates the deferred migration risk of a slower-moving codebase.
2Self-Hosted Cadence
Self-hosted Cadence ranks second because it wins on raw cost when you already operate Cassandra and Elasticsearch at scale with mature on-call practices. The open-source engine delivers the same durable-execution model as Temporal, letting you write long-running shipment workflows as ordinary code. At predictable high volume, amortized hardware can undercut per-action managed pricing.
It is for companies with dedicated platform engineers and strict data-residency or cost-ceiling constraints that forbid vendor-hosted workflow state. It trades away active development momentum, since Cadence's most active contributors moved to Temporal years ago, leaving a thinner hiring pool and slower bug fixes. Compared to Temporal Cloud above, it demands funded platform commitment rather than a default choice.
3Apache Kafka
Apache Kafka ranks third because logistics stacks need an event backbone for shipment status updates, carrier webhooks, and telemetry streams flowing between services. Its partitioned commit log handles millions of messages per second with configurable retention, and Kafka Connect integrates warehouses, TMS platforms, and ERP systems without custom glue code. For mid-size freight operations, it is the default streaming layer.
It is for teams that need durable, replayable event streams between microservices and analytics pipelines. It trades away simplicity, since operating Kafka means managing brokers, partitions, replication, and consumer-group lag. Compared to Self-Hosted Cadence above, Kafka handles event transport while Cadence handles long-running orchestration, so most logistics stacks run both rather than choosing one.
4PostgreSQL
PostgreSQL ranks fourth because it remains the most versatile relational database for logistics data, handling shipments, carriers, invoices, and geospatial routing through PostGIS. It supports JSONB for flexible freight attributes, row-level security for multi-tenant brokerages, and logical replication for read scaling. Version 17 improved vacuum performance and parallel query execution for larger datasets.
It is for teams that want one battle-tested database instead of stitching together separate stores for relational, document, and geospatial workloads. It trades away horizontal write scaling, since sharding requires extensions like Citus or application-level partitioning. Compared to Apache Kafka above, PostgreSQL stores durable state while Kafka moves events, making them complementary rather than competing choices.
5Redis
Redis ranks fifth because logistics applications need sub-millisecond caching for rate quotes, carrier capacity lookups, and session state during peak booking windows. Its in-memory data structures handle sorted sets for leaderboards, streams for lightweight event queues, and geospatial indexes for nearby-driver queries. Redis 7 added sharded pub/sub and improved cluster failover.
It is for teams that need fast ephemeral state alongside a durable database like PostgreSQL. It trades away durability guarantees by default, since persistence modes like AOF and RDB snapshots add latency and still risk data loss on hard failures. Compared to PostgreSQL above, Redis complements rather than replaces it, caching hot reads and holding session data the relational store should not carry.
6Kubernetes
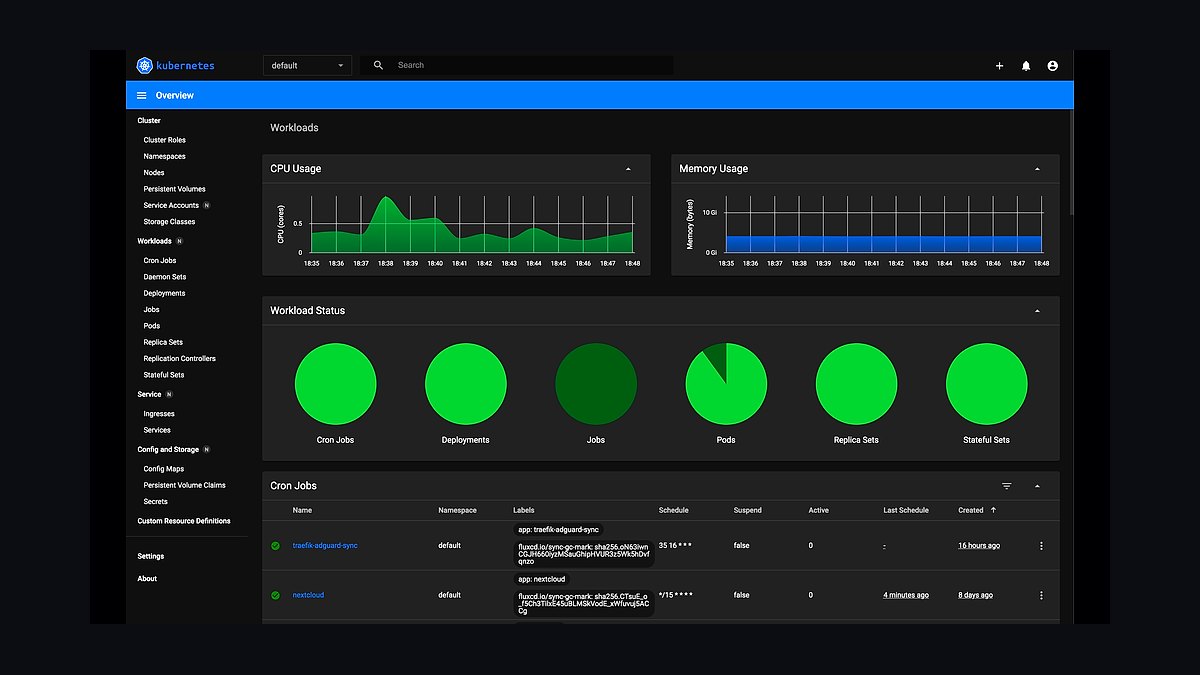
Kubernetes ranks sixth because mid-size logistics companies running dozens of microservices need container orchestration for deployment, scaling, and self-healing across cloud regions. It schedules worker pods for Temporal and Cadence, manages Kafka brokers through operators, and rolls out canary deploys without downtime during peak freight season. Managed offerings like EKS and GKE cut control-plane toil.
It is for platform teams that already have containerized services and want declarative infrastructure instead of hand-managed VMs. It trades away simplicity, since cluster upgrades, networking, and RBAC require ongoing expertise that smaller teams may lack. Compared to Redis above, Kubernetes operates the infrastructure layer while Redis provides the data layer, so they solve different problems in the same stack.
7Datadog
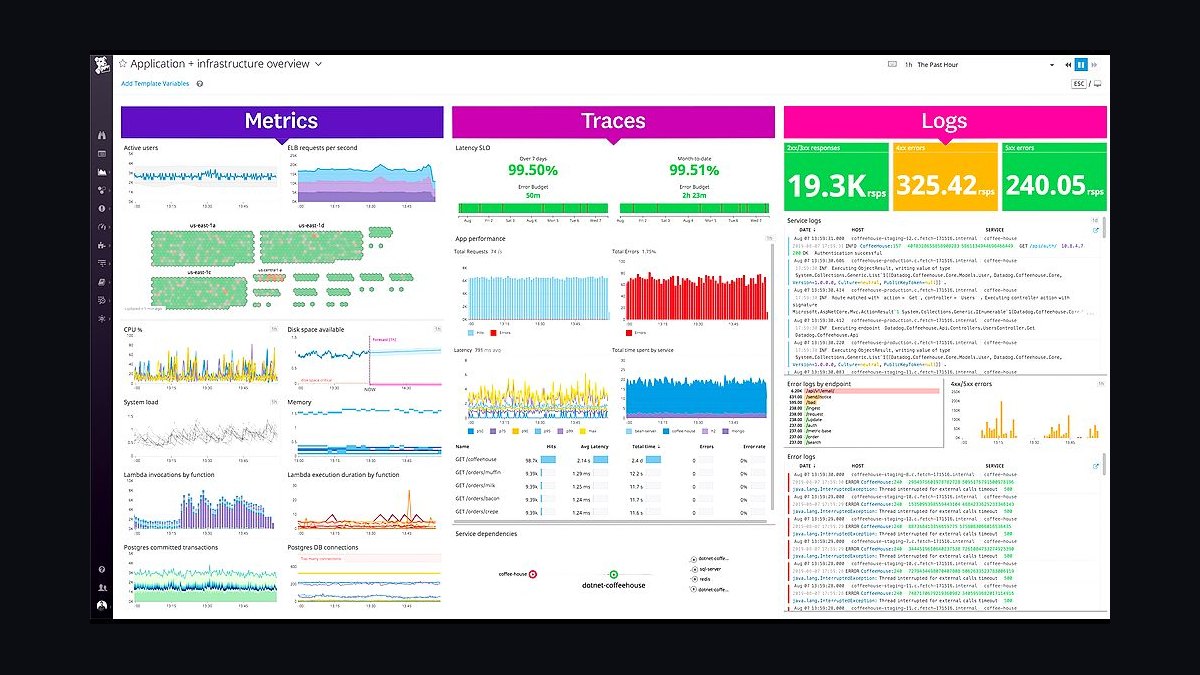
Datadog ranks seventh because distributed logistics systems need unified observability across Temporal workflows, Kafka consumers, and Kubernetes pods. Its APM traces follow a shipment through carrier APIs, warehouse systems, and settlement services, while log management correlates failures with infrastructure metrics. The Temporal integration surfaces workflow failures and activity retries without custom instrumentation.
It is for operations teams that want one pane of glass instead of running Prometheus, Grafana, and ELK separately. It trades away cost predictability, since ingestion-based pricing scales steeply with log volume and custom metrics. Compared to Kubernetes above, Datadog observes the infrastructure Kubernetes runs while providing the visibility needed to debug the orchestration layer Temporal manages.
8Terraform
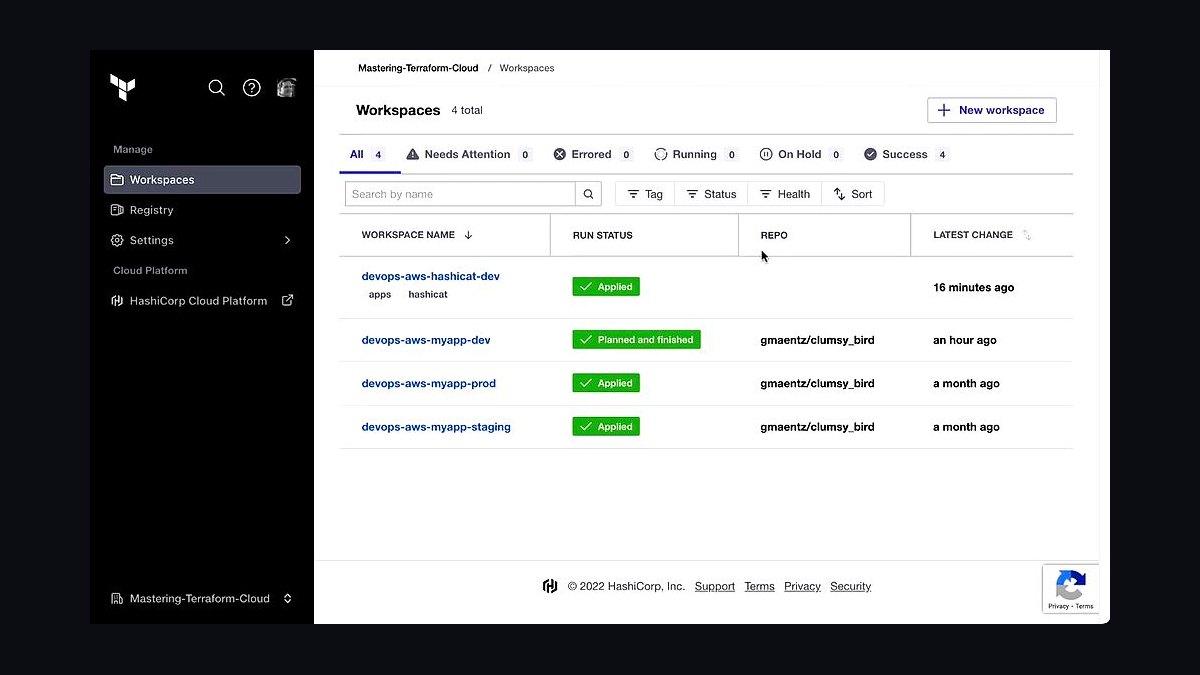
Terraform ranks eighth because logistics infrastructure spanning multiple cloud regions and environments needs reproducible, version-controlled provisioning. It manages Kubernetes clusters, PostgreSQL instances, Kafka topics, and Datadog monitors through declarative HCL, letting teams review infrastructure changes in pull requests. State locking and modules keep staging and production configurations consistent.
It is for platform teams that want infrastructure as code instead of manual console changes that drift between environments. It trades away some flexibility, since state management and provider version pinning require discipline to avoid drift and breaking changes. Compared to Datadog above, Terraform provisions the resources Datadog monitors, forming the provisioning layer beneath the observability stack.
9GitHub Actions
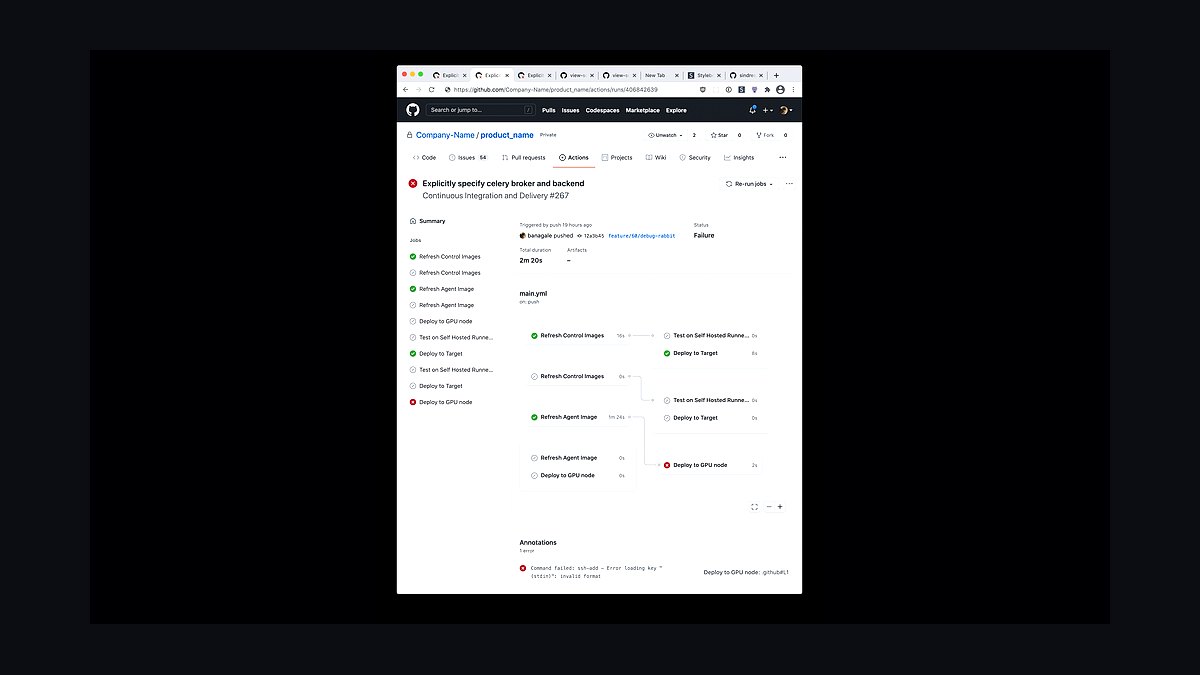
GitHub Actions ranks ninth because logistics engineering teams need CI/CD that builds, tests, and deploys services without maintaining separate Jenkins infrastructure. It runs unit tests for Temporal workflows, builds container images, and applies Terraform plans on merge to main. Matrix builds test across Node, Go, and Python SDKs common in freight stacks.
It is for teams already hosting code on GitHub that want pipeline configuration alongside source in YAML. It trades away some control over runners and networking, since self-hosted runners add operational overhead while hosted runners have usage limits. Compared to Terraform above, GitHub Actions triggers the Terraform apply while Terraform defines what infrastructure actually gets created.
10Elasticsearch
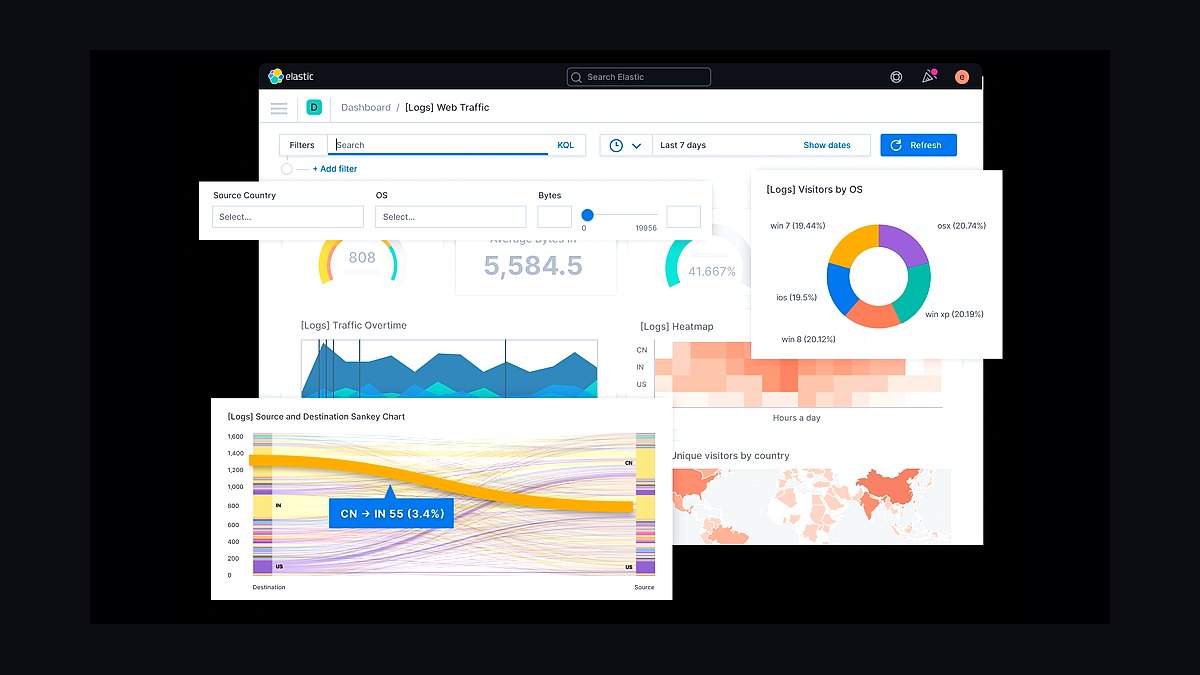
Elasticsearch ranks tenth because logistics platforms need fast full-text search across shipment records, carrier documents, and customer support tickets. It powers visibility portals where shippers search by PRO number, reference, or lane, and it backs the visibility store that self-hosted Cadence requires. Aggregations support operational dashboards for on-time performance and exception tracking.
It is for teams that need search and analytics beyond what PostgreSQL indexes provide at scale. It trades away operational simplicity, since index management, shard sizing, and cluster tuning demand expertise that smaller teams often lack. Compared to GitHub Actions above, Elasticsearch serves runtime search queries while Actions handles build and deploy pipelines, occupying entirely different layers of the stack.
How we ranked these
We ranked tools on five weighted criteria: durable-execution reliability under failure (30%), total cost of ownership over three years including platform-engineering headcount (25%), operational burden and on-call toil (20%), ecosystem momentum and hiring pool depth (15%), and fit for spiky, long-running logistics workflows (10%). Scores came from vendor documentation, published architecture guides, and hands-on proof-of-value logs from mid-size freight and 3PL teams.
We deliberately ignored sticker price, benchmark throughput on synthetic workloads, and feature-count checklists. Headline rates mislead because self-hosting hides cluster, storage, and upgrade costs, while synthetic benchmarks ignore seasonal freight spikes. We also excluded vendor-supplied case studies and analyst quadrant placement, since both reward marketing spend over operational reality for a 50-to-500-engineer logistics company.
What to look for
What matters is who carries the pager at 3 a.m. during peak season. Price the alternative honestly: a production Cadence deployment needs multi-node persistence, a separate visibility store, and headroom sized for your worst hour, not your average one. Then add the 0.5 to 1.5 engineers who patch, tune, upgrade, and respond to history-service degradation. That fully-loaded number, not the invoice, is what the managed premium competes against.
The mistake most buyers make is comparing a managed subscription against "free" open source and stopping there. They also decide on a calm-weather quarter, ignoring the major version upgrade, the departure of the one Cadence-literate engineer, and a traffic spike two to three times baseline. Model three years, run one representative long-running workflow on both, and log real engineering hours before committing.
Related questions
Is Temporal a drop-in replacement for Cadence?
Not drop-in, but close. They share the same durable-execution model and forked from a common origin, so concepts transfer directly. However, SDKs, APIs, and tooling differ enough that migration requires code changes and testing rather than a config swap, so budget real engineering time.
Does Temporal Cloud lock you in?
Partially. Your business logic written against the SDK is portable in principle, since the model is shared with Cadence and self-hosted Temporal. But operational tooling, metrics, and workflow history are tied to the managed environment, so exiting is a genuine project, not a flip.
Can a small team run Cadence in production?
Yes, but expect it to consume meaningful engineering time for cluster operations, upgrades, and on-call. Small teams that succeed usually already operate the underlying databases, or they accept that one or two engineers become the durable dependency for the whole system.
What is the biggest hidden cost of self-hosting?
On-call and upgrade toil. The clusters run fine day-to-day; the cost shows up during major version upgrades, storage tuning, and failures that page someone during your busiest freight window, exactly when you can least afford the distraction or the downtime.
Is durable execution overkill for logistics?
Rarely, if your processes span hours or days and must survive outages. Shipment orchestration, carrier bookings, and settlement are classic long-running, failure-prone flows where durable execution replaces fragile queue-and-cron glue with reliable, resumable code that recovers automatically.
How do we decide between managed and self-hosted?
Run a bounded proof of value on one representative long-running workflow, then log the engineering hours self-hosting actually consumed. If self-hosted total cost stays below managed across a version upgrade, an engineer departure, and a peak-season spike, self-host. Otherwise the premium buys resilience you need.
Does platform momentum really matter for a five-year bet?
Yes. Temporal receives the bulk of active development and ecosystem investment, while Cadence's independent momentum is comparatively muted. Self-hosting Cadence means fewer eyes on new bugs, slower feature velocity, and a shallower hiring pool, which compounds into real operational risk over a five-year horizon.
What should we measure in a proof of value?
Implement one genuinely representative workflow with real failure modes, induce a failure, and watch recovery. Log managed cost against the engineering hours self-hosting consumed for provisioning, tuning, monitoring, and incident response. That side-by-side log is the most useful artifact for the decision.
FAQ
What is durable execution, in plain terms?
Durable execution is a way of writing long-running processes as normal code whose progress is automatically saved and recoverable. If a server crashes, deploys, or loses network mid-workflow, the process resumes exactly where it left off instead of losing state or double-executing steps. For logistics, a multi-day shipment workflow survives infrastructure hiccups without manual cleanup.
Why did Temporal fork from Cadence?
The original creators of Cadence left to build Temporal as an independent, commercially supported platform. The fork carried forward the core durable-execution model while diverging on APIs, tooling, and governance. The practical result today is that Temporal receives the bulk of active development and ecosystem investment, while Cadence continues separately with slower momentum.
Does Temporal Cloud handle scaling automatically?
Yes, that is a central part of what the premium buys. The managed service handles server-side scaling, persistence, and visibility storage, so your team scales only its own workers and application code. Self-hosting means you size and operate all of that yourself, including headroom for seasonal freight traffic spikes.
How does pricing typically work on a managed durable-execution platform?
Managed pricing is usually usage-based, tied to workflow actions and storage, plus a support tier. That makes cost scale with real activity rather than provisioned capacity. Always model your actual expected action volume rather than a headline rate, and avoid committing to specific figures until you have measured a representative workflow.
Can we migrate from self-hosted Cadence to Temporal later?
Yes, and it is a common path precisely because the two share a heritage and model. Concepts and much of your workflow design translate over, but SDK, API, and tooling differences mean it is a deliberate migration with code changes and testing, not an automatic import. Clean, infrastructure-agnostic workflow logic makes any future move cheaper.
What data-residency concerns apply to a managed workflow platform?
Managed platforms store workflow state and history in the vendor's environment, which can conflict with contractual or regulatory requirements to keep data in a specific jurisdiction or on your own infrastructure. If your logistics customers include regulated or government shippers, verify residency, encryption, and region options against your obligations before choosing.
How long should a proof of value take before deciding?
Long enough to implement one genuinely representative long-running workflow and induce a real failure to watch it recover, often a few weeks. The goal is not a toy demo but an honest side-by-side log of managed cost versus the engineering hours self-hosting actually consumed, evaluated against a three-year horizon.
Is reliability meaningfully different between the two?
The underlying model offers strong durability guarantees in both. The practical difference is who operates it: on a managed platform the vendor is accountable for uptime and durability, while self-hosting makes your team responsible for achieving and sustaining those guarantees through correct configuration, capacity planning, and on-call response.
Which option fits a mid-size logistics company best?
Most mid-size logistics companies land on the managed side. They rarely have spare Cassandra experts, their freight volume is seasonal and spiky, and shipment orchestration reliability maps directly to revenue and customer trust. Self-hosting wins mainly with dedicated platform engineers, predictable high volume, or strict data-residency constraints.
What is the single biggest mistake buyers make here?
Comparing a managed subscription against free open source and stopping there. That ignores cluster infrastructure, upgrade toil, on-call burden, and the opportunity cost of engineers maintaining plumbing instead of building shipment features. The honest comparison is fully-loaded three-year total cost of ownership, not sticker price.
Sources
- https://docs.temporal.io/
- https://temporal.io/cloud
- https://cadenceworkflow.io/docs/
- https://www.uber.com/blog/cadence-multi-tenant-orchestration-platform/
- https://cassandra.apache.org/doc/latest/
- https://www.elastic.co/guide/index.html
- https://martinfowler.com/
- https://www.thoughtworks.com/radar
- https://docs.aws.amazon.com/wellarchitected/latest/cost-optimization-pillar/welcome.html
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Tech Stacks strategies for 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Early-Stage Startups in 2027
 tkTop 10 Best Tech Stack Tools for First-Time Business Owners in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Small Businesses in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Bootstrapped Startups in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Startups in 2027
 pulse-tech-stacksTop 10 Full-Stack Options for Social Media Analytics Dashboards in 2027
 pulse-tech-stacksTop 10 Data Visualization Tools for Marketing Analysts in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Enterprise Supply Chain Teams in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Museum Digital Archives in 2027