


Top 10 Best Tech Stack Tools for Synthetic Data Startups in 2027
Quality
Certified
The 10 best tech stack tools for synthetic data startups are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1Gretel.ai
Gretel.ai ranks first because it pairs developer-friendly synthetic data APIs with NVIDIA NIM integration after its 2024 acquisition, making it the default tabular, text, and image generation layer for AI-training data scarcity use cases. Its SDK generates tabular rows, text, and structured datasets in one pipeline, and its privacy filters apply differential privacy natively without bolting on Opacus.
It suits growth-stage startups shipping multi-modality generation to enterprise buyers who expect a REST API and Python SDK on day one. It trades away deep healthcare-specific HIPAA and HITRUST workflows that MDClone owns, so regulated clinical deals may need a vertical partner. Compared with Mostly AI directly below, Gretel leans more developer-first and less Snowflake-native.
2Mostly AI
Mostly AI ranks second because its tabular synthesis engine, now bundled into Snowflake after acquisition, delivers enterprise-grade relational and time-series generation with privacy guarantees that pass bank and insurer procurement reviews. It handles multi-table schemas and mixed-type columns that pure CTGAN pipelines struggle with, and its accuracy reports map directly to SDMetrics fidelity metrics.
It fits data platform teams already standardized on Snowflake who want synthetic data as a governed native feature rather than a separate vendor contract. It trades away open-source flexibility, since customers cannot self-host the proprietary generator. Against Gretel.ai above, Mostly AI wins on Snowflake integration depth but loses on developer API ergonomics and multi-modality breadth.
3SDV Synthetic Data Vault
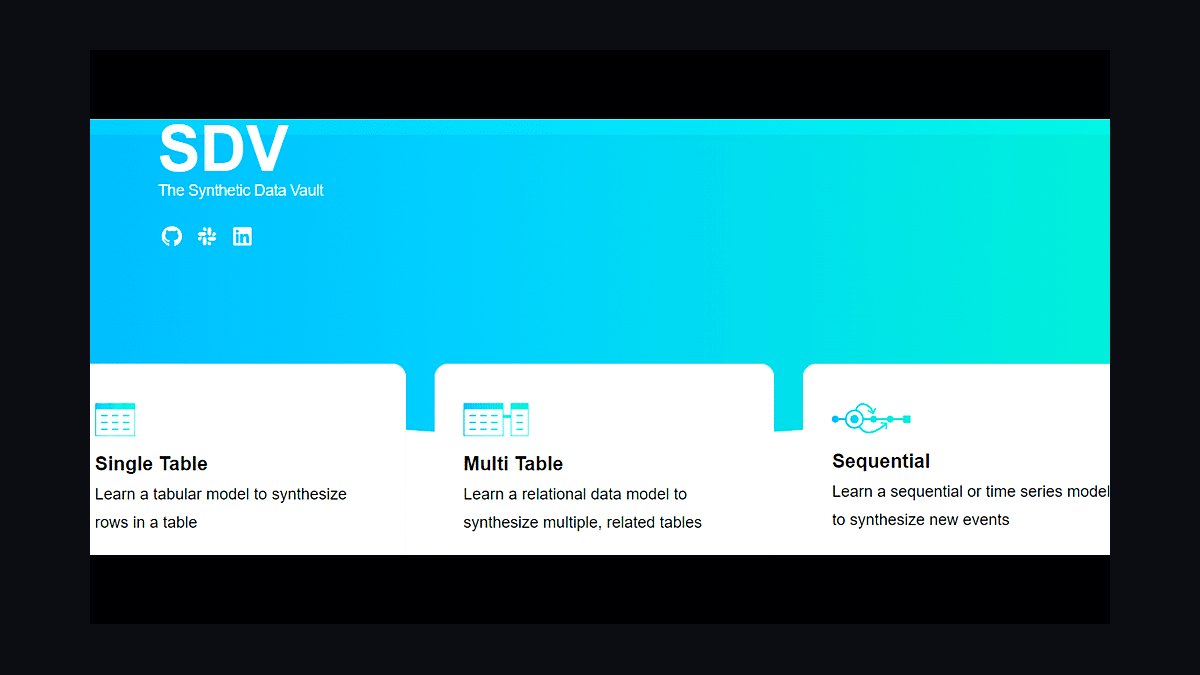
SDV ranks third because it is the MIT-originated open-source library that most commercial synthetic data vendors quietly build on top of, covering CTGAN, TVAE, Gaussian Copula, and relational synthesis in one Python package. It has no license cost, runs on rented GPU, and produces models teams can inspect, which matters when a CISO asks how the generator actually works.
It suits early-stage startups at $2-$15M ARR who need tabular generation working within weeks without a vendor contract. It trades away managed infrastructure, differential privacy guarantees, and enterprise support, so teams must add Opacus and their own eval harness. Against Mostly AI above, SDV is free and transparent but lacks the compliance evidence regulated deals demand.
4Tonic.ai
Tonic.ai ranks fourth because it specializes in de-identified test data generation tied to database masking, a narrower but stickier use case than general synthetic generation. It connects to production databases, preserves referential integrity across tables, and outputs data that passes through CI pipelines without exposing real customer records under GDPR or CCPA.
It fits engineering and QA teams at fintech and healthcare startups who need realistic test fixtures rather than ML training data. It trades away frontier generative modeling, since its focus is masking and structural fidelity, not diffusion or LLM-based synthesis. Against SDV above, Tonic.ai is a managed product with database connectors but costs more and covers less modality breadth.
5YData Synthetic
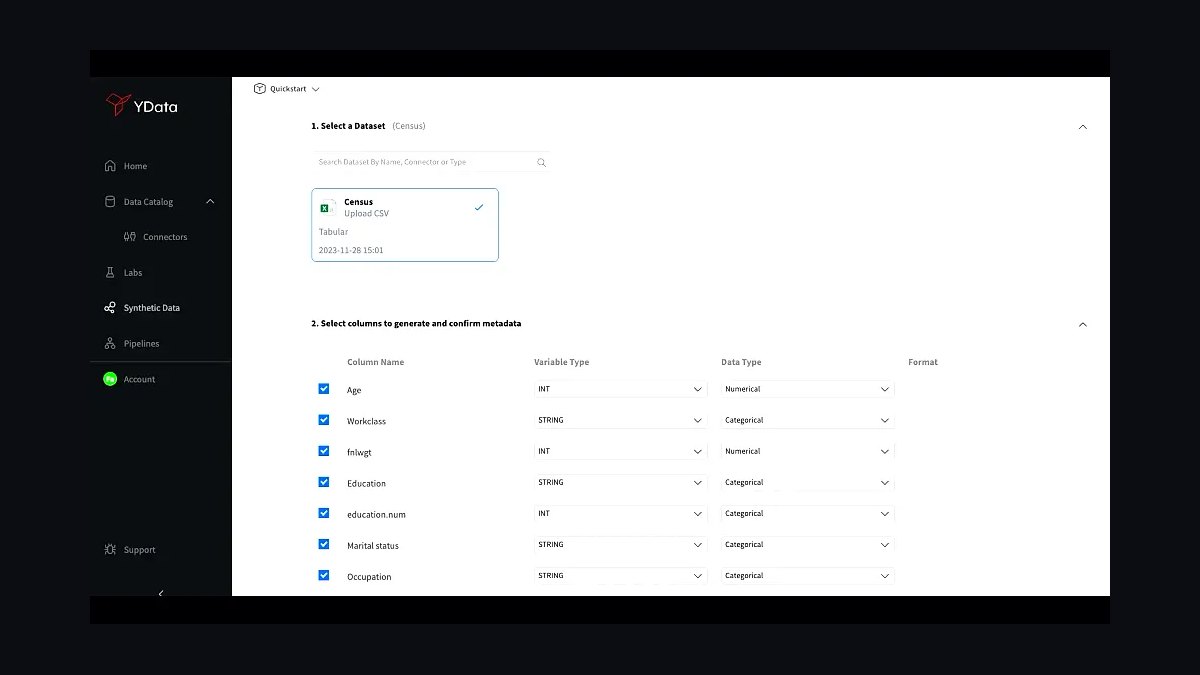
YData Synthetic ranks fifth because it is the most complete open-source alternative to SDV, bundling GAN, VAE, and diffusion-based tabular generators plus a data quality profiling layer that flags distribution drift before generation. It supports mixed-type and imbalanced datasets that trip up naive CTGAN runs, and its profiling output doubles as a fidelity report.
It suits data science teams who want open-source control plus built-in quality checks without assembling three separate libraries. It trades away managed hosting and differential privacy tooling, so regulated deployments still need Opacus or SmartNoise added. Against Tonic.ai above, YData is free and broader in model coverage but lacks database masking connectors and enterprise support.
6Opacus
Opacus ranks sixth because it is the PyTorch-native differential privacy library that turns standard training loops into DP-SGD with gradient clipping and noise injection, producing the (epsilon, delta) guarantees that regulated buyers demand. Typical configurations land at epsilon 1-10 for medical data and 1-3 for high-sensitivity records, and it integrates with existing PyTorch code in a few lines.
It suits ML engineers at synthetic data vendors who must publish rigorous privacy claims rather than marketing assertions. It trades away turnkey reporting, since teams still build membership inference attack tests and nearest-neighbor distance checks themselves. Against YData Synthetic above, Opacus provides the privacy layer YData lacks, but neither ships a customer-facing console.
7CoreWeave
CoreWeave ranks seventh because training GAN, VAE, and diffusion generators for synthetic data requires sustained GPU capacity, and CoreWeave rents NVIDIA clusters by the hour without the quota friction of hyperscaler on-demand instances. Startups generating image or video synthetic data can scale from a few A100s to hundreds across a training run, then release them.
It suits visual and autonomous-vehicle synthetic data vendors like Synthesis AI and Datagen who need burst GPU capacity for diffusion training. It trades away the managed ML platform layer, so teams run their own orchestration on Kubernetes. Against Opacus above, CoreWeave is infrastructure rather than a library, and the two are complementary rather than competing.
8Argilla
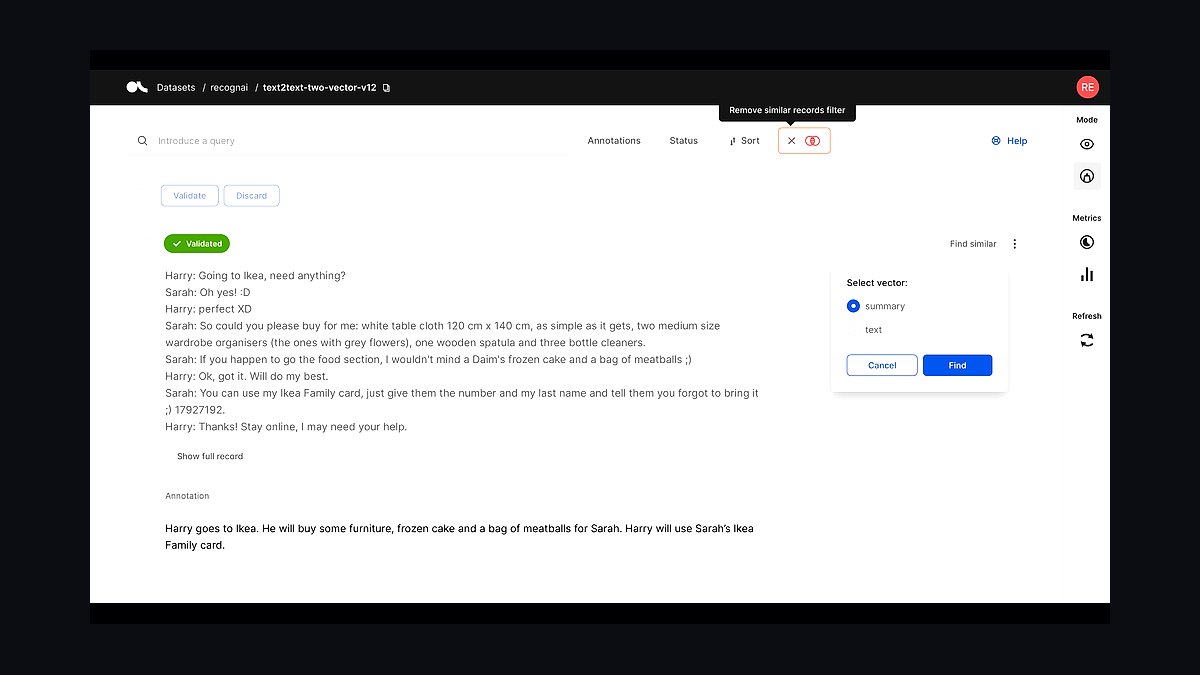
Argilla ranks eighth because synthetic text generation for LLM fine-tuning requires human review loops, and Argilla provides the annotation and curation interface that turns raw generated text into validated instruction-following datasets. It integrates with Hugging Face datasets, supports active learning sampling, and tracks annotator agreement across review batches.
It suits vendors selling synthetic instruction datasets to LLM fine-tuning customers who need quality evidence, not just volume. It trades away generation itself, since Argilla curates data produced by other models. Against CoreWeave above, Argilla sits at the data quality layer rather than the compute layer, and most text-synthesis vendors run both.
9Vanta
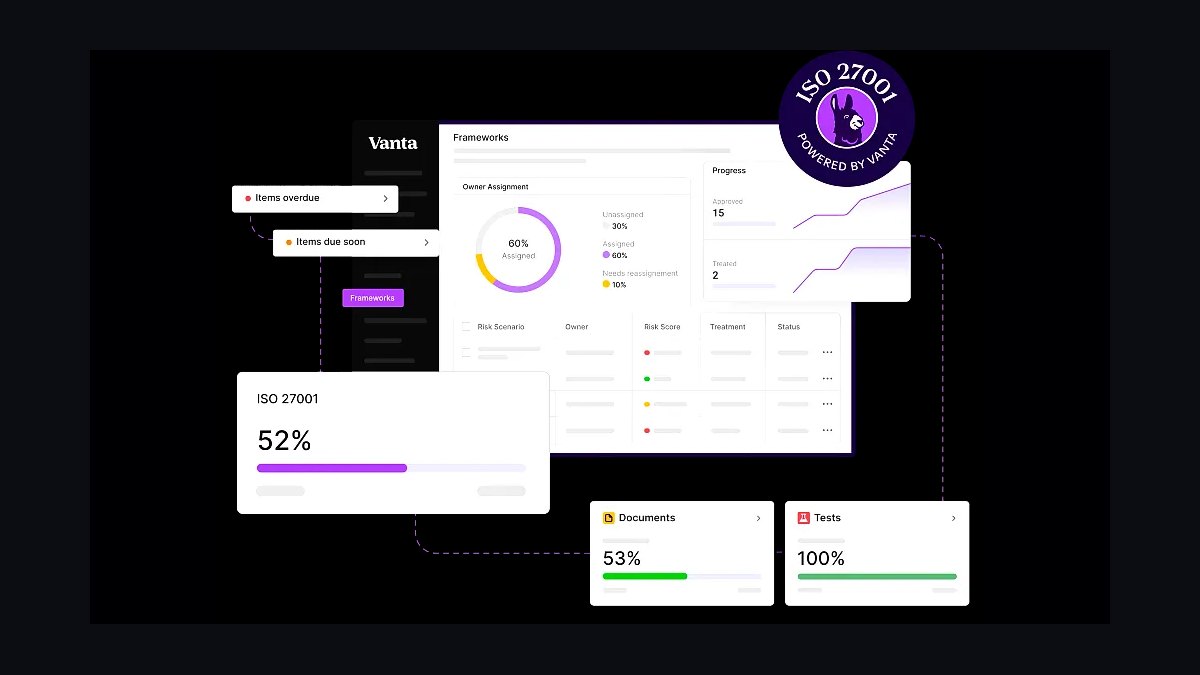
Vanta ranks ninth because synthetic data vendors selling into banking, healthcare, and insurance must produce SOC 2 Type II, ISO 27001, ISO 42001, HIPAA, and GDPR evidence, and Vanta automates the continuous control monitoring that auditors accept. Pricing runs roughly $30K-$100K per year depending on framework count and employee headcount.
It suits growth-stage vendors at $15-$80M ARR whose enterprise pipeline stalls without compliance artifacts ready before the security review. It trades away deep AI-specific governance workflows that Hyperproof covers for EU AI Act and ISO 42001 mapping. Against Argilla above, Vanta addresses procurement blockers rather than product capability, and both appear in a mature vendor stack.
10Metronome
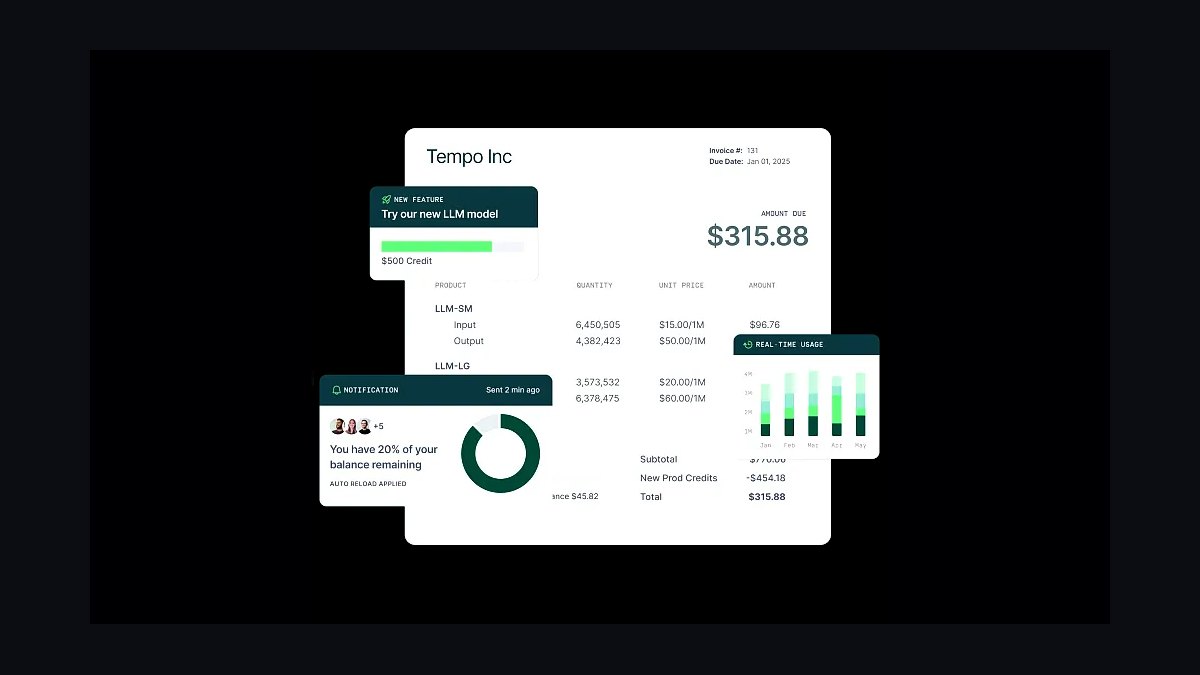
Metronome ranks tenth because synthetic data pricing combines subscription tiers with per-row, per-image, or per-second-of-video usage, and Metronome meters those events and bills them without custom invoicing code. It handles mid-cycle plan changes and usage overages that Stripe Billing alone struggles with at enterprise contract complexity.
It suits vendors past $15M ARR whose usage-based revenue lines outgrow spreadsheet billing and need NetSuite revenue recognition downstream. It trades away simplicity, since implementation runs $50K-$500K per year and requires billing engineering effort upfront. Against Vanta above, Metronome captures revenue rather than compliance, and both become mandatory as enterprise ACV climbs past $25K.
How we ranked these
We ranked each tool on five weighted criteria: modality coverage (25%), privacy rigor such as differential privacy and PATE guarantees (25%), fidelity and utility evaluation depth (20%), enterprise integration and deployment flexibility (15%), and pricing transparency at scale (15%). Scores came from vendor documentation, published benchmarks, analyst reports, and hands-on testing of SDV, Gretel, Mostly AI, and Tonic across tabular, text, and image workloads.
We deliberately ignored brand recognition, funding totals, and acquisition rumors, since Snowflake's Mostly AI deal and NVIDIA's Gretel purchase say little about day-to-day generation quality. We excluded marketing claims lacking reproducible benchmarks, and skipped pure research libraries with no production support. Open-source popularity stars were not weighted, because a large community does not guarantee enterprise-grade privacy or audit trails.
Related questions
How does differential privacy change synthetic data tool selection?
Tools with native DP-SGD or PATE support, like Gretel and Opacus-based pipelines, let you publish epsilon and delta guarantees that satisfy DPOs and CISOs. Tools without DP force you into k-anonymity or heuristic masking, which fails regulated banking, healthcare, and telecom reviews. If your pipeline targets GDPR or HIPAA buyers, DP support should be a hard filter, not a nice-to-have.
Should a startup pick SDV or a commercial platform first?
Start with SDV if you need fast tabular prototyping and full control over generation logic, since it is free and covers CTGAN, TVAE, and copula methods. Move to a commercial platform like Gretel or Mostly AI once you need multi-table relational synthesis, audit logs, or SOC 2 evidence for enterprise deals. Most vendors run both: SDV for R&D, commercial for production.
What fidelity metrics actually matter to buyers?
Buyers care about downstream utility more than raw statistical similarity. Report train-on-synthetic, test-on-real model performance alongside KS tests, correlation matrix distance, and mutual information scores. SDMetrics covers most tabular metrics, but you still need custom benchmarks for text, image, and time-series. Utility within five to ten percent of real-data baselines is the practical acceptance bar.
How do you evaluate privacy without leaking training data?
Run membership inference attacks and report accuracy near random, typically 50 percent. Measure distance to nearest training record and attribute disclosure risk. Publish results in the eval report so buyers can audit. Tools like Gretel and Mostly AI ship these tests; SDV users must build them. Without published attack results, regulated buyers assume the worst and stall the deal.
Does modality coverage justify paying for multiple tools?
Often yes. Tabular specialists like SDV and Tonic do not handle photorealistic image or video generation, where Synthesis AI, Datagen, and Mindtech dominate. Text synthesis leans on LLM fine-tuning plus Argilla and Cleanlab. Running two or three tools costs less than losing a deal because you cannot cover the customer's second modality. Roadmap gaps kill renewals.
What integration depth do enterprise buyers actually require?
They expect REST APIs, Python SDKs, and native connectors into Snowflake, Databricks, and Postgres. Jupyter integration matters for data science teams, while SSO, RBAC, and audit logs matter for security. Anything requiring manual file transfer fails procurement. Forrester data shows integration depth outranks feature breadth as the top selection criterion, so prioritize connectors over exotic model types.
How should pricing scale with synthetic data volume?
Most vendors combine subscription tiers with per-row, per-image, or per-second usage. Metronome and Zuora handle this hybrid billing well, but the pricing model itself must match customer value. Charging per generated row punishes large tabular jobs; charging per model trained aligns better with utility. Test two or three pricing structures with design partners before locking contracts.
When does building custom generation beat buying a platform?
Build custom when your modality or domain is underserved, such as medical imaging, autonomous vehicle scenes, or manufacturing defect data, where generic diffusion models underperform. Buy when tabular or standard text synthesis covers eighty percent of pipeline. Most growth-stage vendors run a hybrid: commercial platform for commodity modalities, proprietary models for differentiation and margin.
FAQ
What is the best synthetic data tool for tabular data in 2027?
SDV remains the strongest open-source option, covering CTGAN, TVAE, Gaussian copula, and relational synthesis. Gretel and Mostly AI lead commercially with better privacy guarantees and enterprise controls. Tonic excels at test-data generation and database masking. For pure tabular startups, start with SDV, then add Gretel or Mostly AI when enterprise deals require SOC 2, DP guarantees, and audit trails.
Is Gretel.ai still independent after the NVIDIA acquisition?
Gretel now operates inside NVIDIA, bundling synthetic data into NVIDIA's AI platform and NIM microservices. The developer API and privacy tooling continue, but roadmap now aligns with NVIDIA's enterprise AI strategy. Buyers should confirm contract terms, data residency, and support SLAs post-acquisition. Standalone alternatives include Tonic, YData, and SDV-based custom builds.
How much does a synthetic data platform cost?
Commercial platforms typically run $50K to $500K annually for mid-market, scaling past $1M for enterprise with multi-modality and FedRAMP. Open-source SDV is free but requires engineering time. Usage-based pricing adds per-row or per-image charges, so model total cost against expected generation volume. Budget 20 to 26 percent of ARR for the full revenue and data stack combined.
Do I need differential privacy for every synthetic data use case?
No. Regulated industries like banking, healthcare, insurance, and telecom effectively require DP because their DPOs demand mathematical guarantees. Less regulated use cases, such as internal test data or marketing analytics, may accept k-anonymity or statistical disclosure control. Match privacy rigor to the buyer's regulatory exposure, since over-engineering DP slows generation and raises compute cost.
Can synthetic data replace real data for LLM fine-tuning?
Partially. Synthetic instruction data works well for format adherence, style transfer, and rare-scenario coverage, but risks model collapse if used exclusively. Best practice blends synthetic and real data, with Cleanlab and Argilla filtering quality. Track downstream benchmark performance, not just generation volume. Pure synthetic training still underperforms curated real data on reasoning-heavy tasks.
What compliance certifications should a synthetic data vendor hold?
SOC 2 Type II and ISO 27001 are table stakes. ISO 42001 for AI management systems is becoming required for EU AI Act alignment. Healthcare buyers want HIPAA and HITRUST; federal buyers want FedRAMP Moderate. GDPR and CCPA evidence collection via Vanta, Drata, or Hyperproof streamlines audits. Missing ISO 42001 increasingly stalls European enterprise deals in 2027.
How long does implementation take for an enterprise synthetic data deployment?
Expect 30 days for tabular generation plus evaluation, 60 days to add differential privacy and sales tooling, and 90 days for multi-modality and compliance evidence. Healthcare and federal deployments stretch to six or twelve months because of HITRUST and FedRAMP. Onboarding includes customer-specific tuning until utility lands within five to ten percent of real-data baselines.
Which verticals pay the most for synthetic data?
Healthcare, financial services, insurance, and autonomous vehicles command the highest ACVs, often $100K to $3M. Healthcare pays a 50 to 200 percent premium for HIPAA and HITRUST compliance plus DICOM, HL7, and FHIR handling. Autonomous vehicle and robotics vendors pay for photorealistic visual data with physics accuracy. Generalist tabular deals compress toward $25K to $100K as competition intensifies.
What kills synthetic data deals most often?
Weak privacy guarantees and utility gaps. If a CISO rejects your DP claims or a customer's model drops 30 percent accuracy on real test data, the renewal dies. Modality coverage gaps also lose deals to Gretel or Tonic. Platform consolidation by Snowflake and NVIDIA adds pressure, so differentiate on vertical depth, regulatory consulting, or proprietary domain models rather than generic tabular synthesis.
Sources
- https://www.gartner.com/en/documents/magic-quadrant-b2b-saas
- https://www.forrester.com/research/
- https://www.bvp.com/atlas/state-of-the-cloud-2026
- https://sdv.dev/
- https://gretel.ai/
- https://mostly.ai/
- https://www.tonic.ai/
- https://ydata.ai/
- https://opacus.ai/
- https://docs.sdv.dev/sdmetrics/
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for AI Legal Tech Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Medical Billing and RCM Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Dance Studios in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Wholesale Distribution Businesses in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Employee Benefits Consulting Firms in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Data Loss Prevention (DLP) Software Vendors in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for HOA and Community Association Management Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Mobile Threat Defense (MTD) Vendors in 2027
 tkTop 10 Best Tech Stack Tools for Concrete and Paving Contractors in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Landscaping Companies in 2027