


Top 10 Best Tech Stack Tools for AI Video Generation Companies in 2027
Quality
Certified
The 10 best tech stack tools for ai video generation companies are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1OpenAI Sora
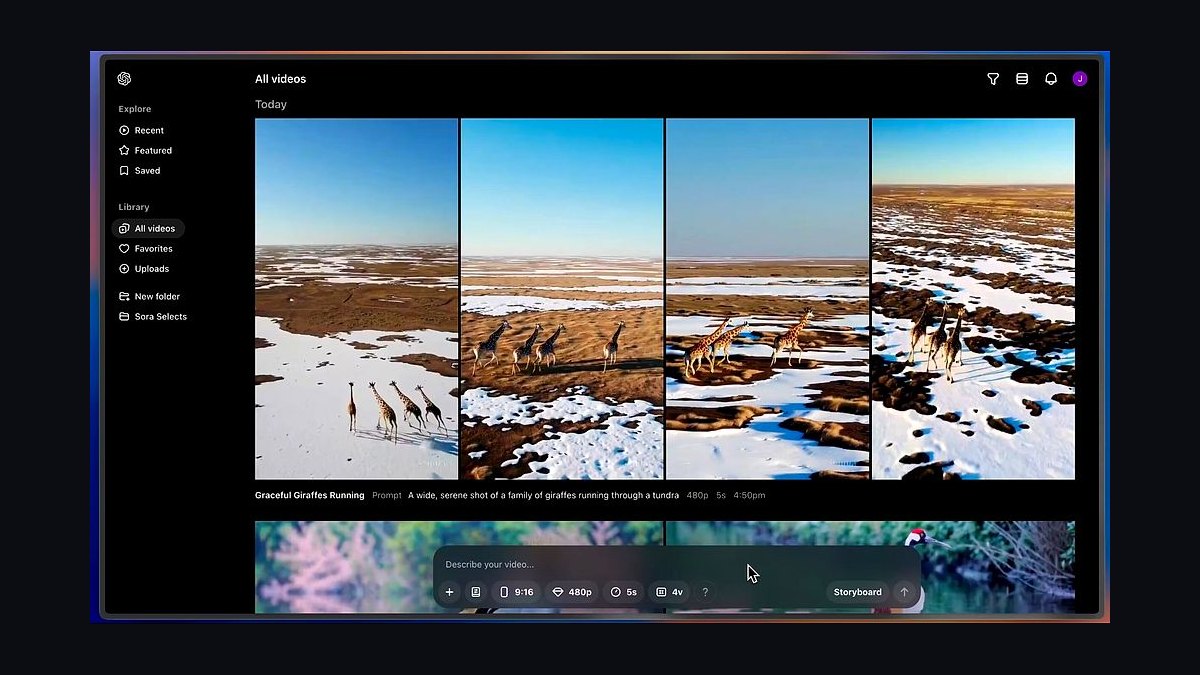
OpenAI Sora ranks first because it sets the quality and integration benchmark for AI video generation in 2027. Sora Turbo delivers text-to-video and image-to-video at frontier quality, and its ChatGPT integration puts generation in front of hundreds of millions of users. Training runs at thousands-of-GPU scale, with per-release compute budgets reported in the $30M-$300M+ range.
It suits enterprises and creators who want best-in-class output with minimal infrastructure work, and who accept API pricing and limited fine-grained camera control. Compared with Google Veo 3 directly below, Sora trades deeper Google-ecosystem integration for stronger consumer reach and a simpler product surface. Teams needing shot-level editing depth typically pair it with Runway.
2Google Veo 3
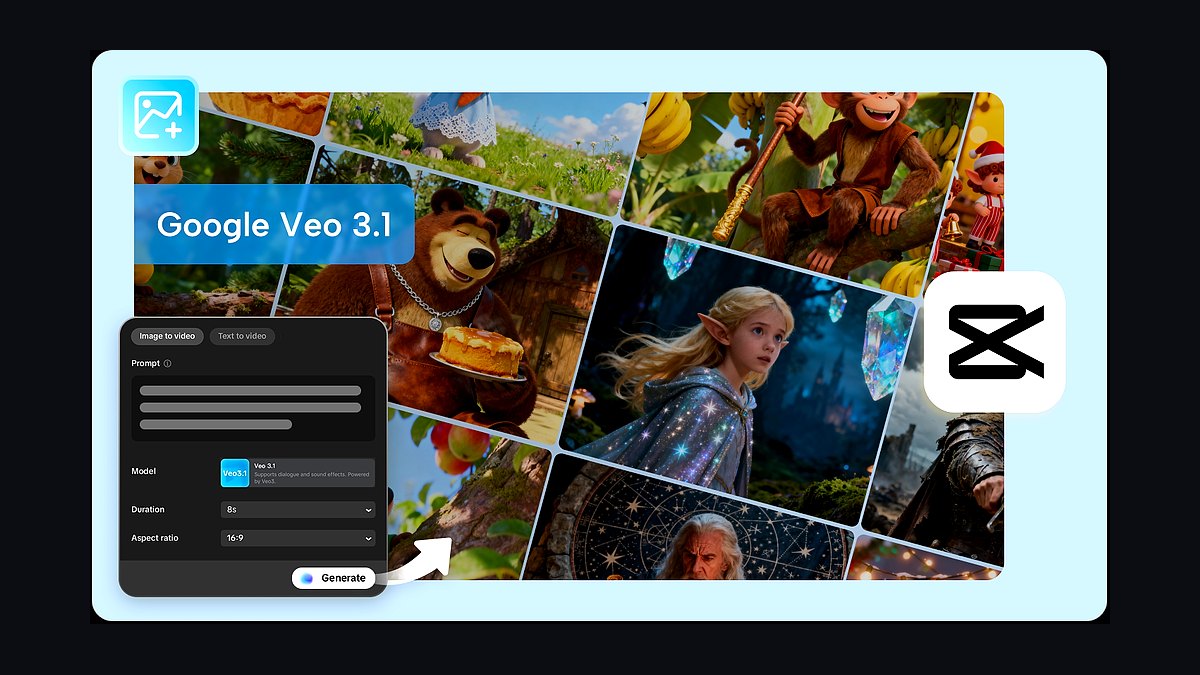
Google Veo 3 ranks second because it pairs frontier video quality with native audio generation and deep Google Cloud distribution. Veo 3 uses flow-matching architecture and ships through Vertex AI, giving enterprises the multi-region serving and IAM controls they already run. Native synchronized audio removes a separate dubbing or sound-generation step from most marketing workflows.
It is built for Google-committed enterprises and agencies that need audio and video in one call, and it trades away some creator-oriented editing tools that Runway provides. Against OpenAI Sora directly above, Veo 3 wins on ecosystem integration and audio, while Sora wins on consumer reach. Most large vendors evaluate both before committing.
3Runway Gen-4
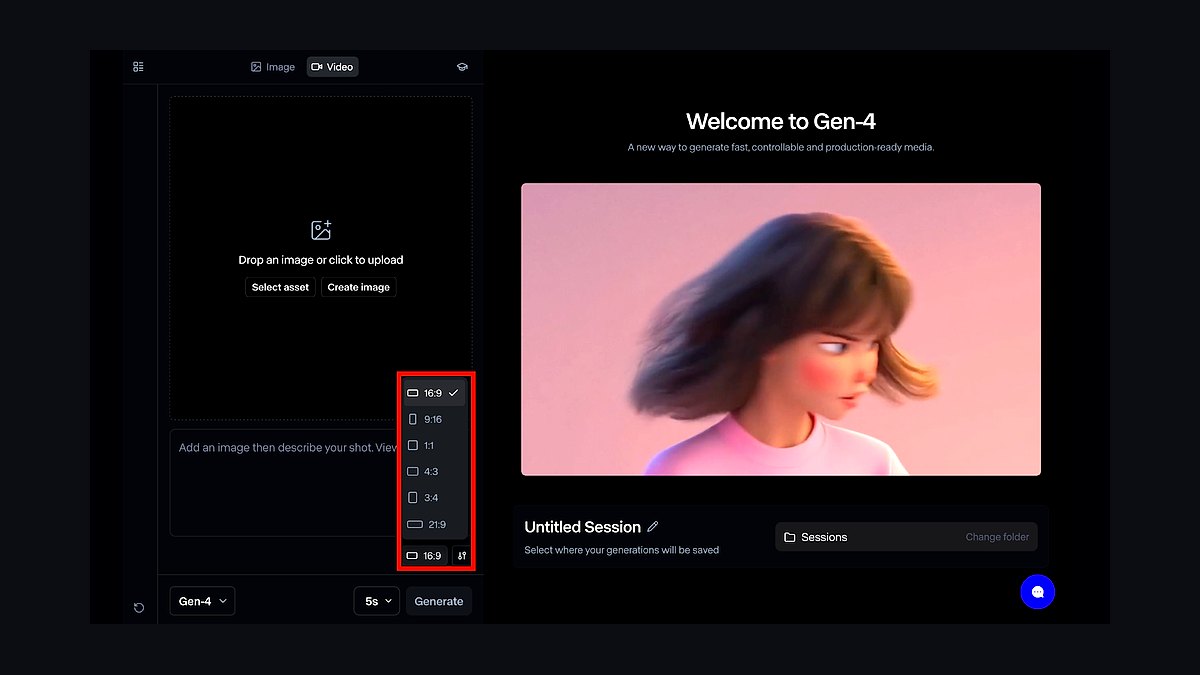
Runway Gen-4 ranks third because it leads on multi-modal control depth, the primary enterprise differentiator for video generation. Runway pairs Gen-4 with the Aleph editing model, enabling video-to-video editing, inpainting, outpainting, and camera control (zoom, pan, tilt, dolly) that generic text-to-video tools lack. Runway has raised at a $1B+ valuation on this creator-plus-enterprise positioning.
It is aimed at filmmakers, VFX teams, and creative professionals who need shot-level control rather than one-shot generation, and it trades away some raw photorealistic quality versus Sora and Veo 3. Compared with Google Veo 3 directly above, Runway gives up native audio and cloud distribution but wins decisively on editing workflow. Growth-stage vendors often benchmark their control features against it.
4Kuaishou Kling
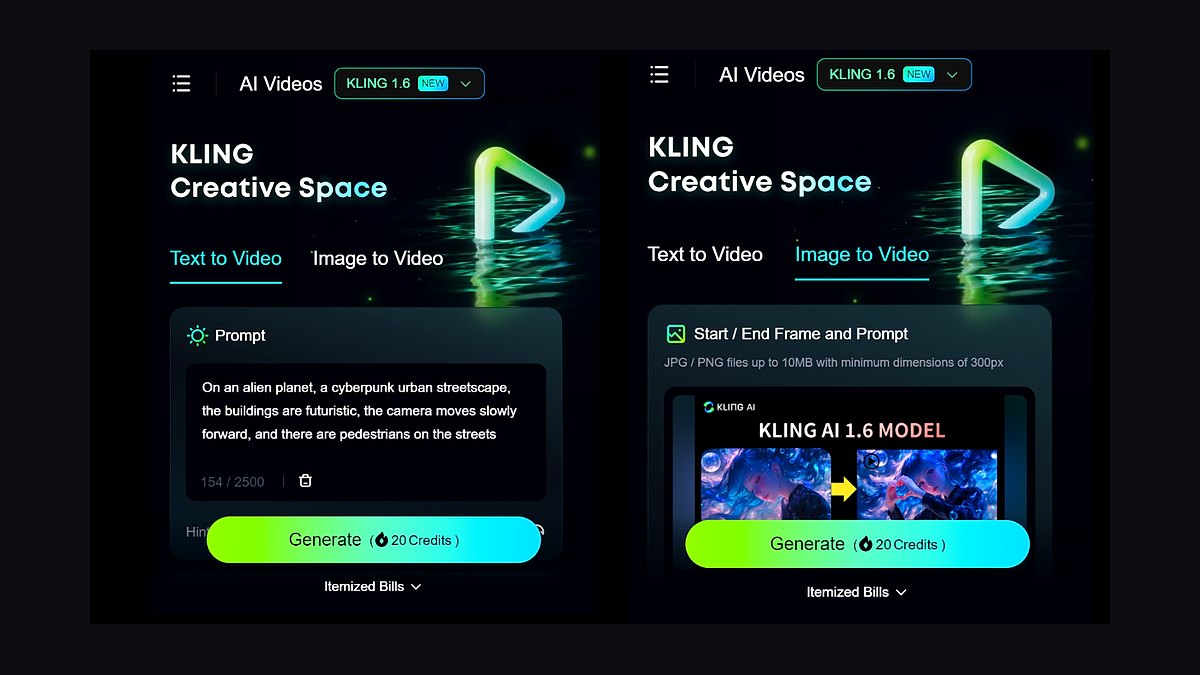
Kuaishou Kling ranks fourth because it delivers frontier-competitive video quality at aggressive API pricing, pressuring Western vendor margins. Kling 1.6 and 2.0 handle text-to-video, image-to-video, and motion control, and Kuaishou operates within China's GPU supply chain, often using Huawei Ascend silicon rather than NVIDIA. That supply independence gives Kling a structural cost advantage on inference.
It suits cost-sensitive platforms and global API resellers, and it trades away Western compliance certifications like SOC 2 Type II and C2PA participation that enterprise buyers increasingly require. Against Runway Gen-4 directly above, Kling wins on price and loses on editing depth and provenance tooling. Vendors serving EU customers should verify Article 50 disclosure support before shipping.
5Pika 2.2
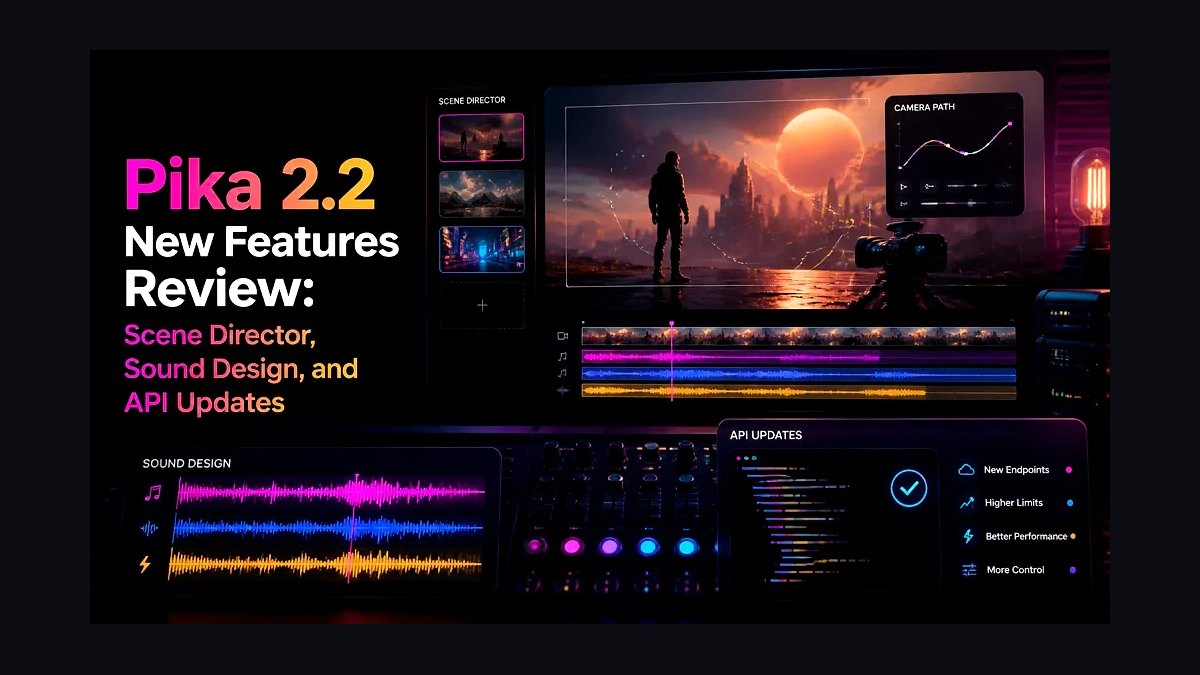
Pika 2.2 ranks fifth because it built a viral creator UX around fast, stylized video generation with integrated sound. Pika reached an $800M valuation on the strength of consumer-grade onboarding and social-first output formats, and version 2.2 adds scene modification and character reference features that earlier releases lacked. Generation latency is tuned for iterative creator workflows rather than batch enterprise jobs.
It is aimed at individual creators, social teams, and marketing groups that value speed and shareability, and it trades away the deep camera and editing controls that Runway Gen-4 offers. Compared with Kuaishou Kling directly above, Pika wins on user experience and brand recognition in Western markets but loses on inference cost. Enterprise buyers typically treat it as a departmental tool, not core infrastructure.
6Luma Dream Machine
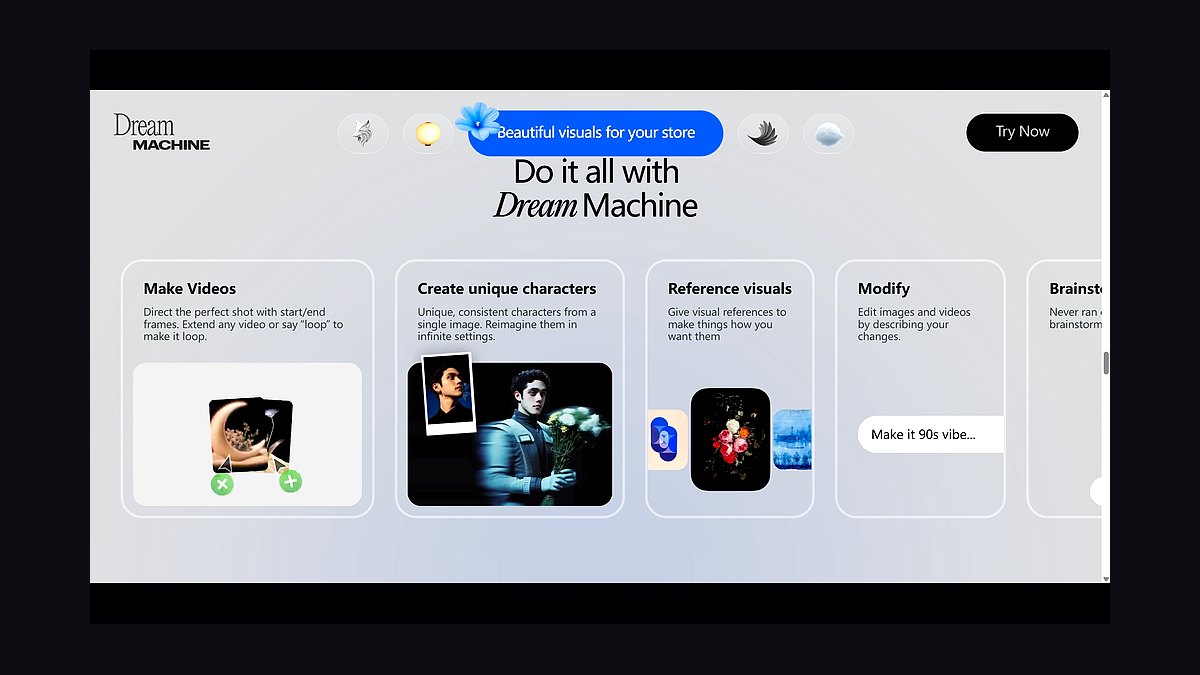
Luma Dream Machine ranks sixth because it leads on generation speed and image-to-video conditioning, with Ray 2 improving motion coherence. Luma has raised over $500M and optimized its serving stack for fast turnaround, making it a common choice for interactive and real-time-adjacent applications. Image-to-video start-frame conditioning is a core strength rather than an add-on.
It suits product teams embedding video generation into interactive experiences, and it trades away the avatar and lip-sync capabilities that Synthesia and HeyGen provide. Against Pika 2.2 directly above, Luma wins on speed and image conditioning while Pika wins on creator-facing polish and sound. Teams needing batch API throughput should benchmark both on identical prompts.
7Synthesia
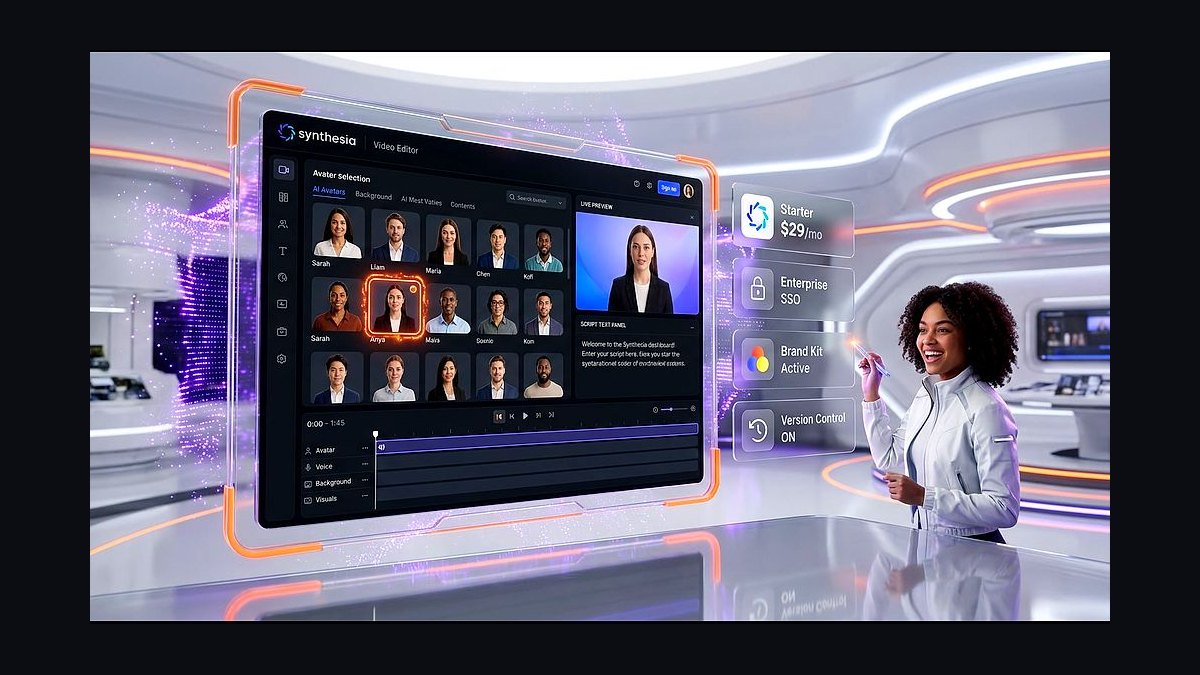
Synthesia ranks seventh because it owns the AI avatar video category for corporate learning and enterprise communications. Synthesia has reached a $1B+ valuation with an avatar library, voice cloning, and multilingual lip-sync built for scripted presenter video rather than open-ended diffusion. Corporate learning, marketing video, and international localization are its core use cases.
It is built for L&D, HR, and enterprise communications teams that need consistent branded presenters, and it trades away the cinematic motion and camera control that Runway Gen-4 delivers. Compared with Luma Dream Machine directly above, Synthesia wins on enterprise compliance and scripted reliability but loses on creative flexibility. It is a different category from text-to-video vendors, not a substitute.
8HeyGen
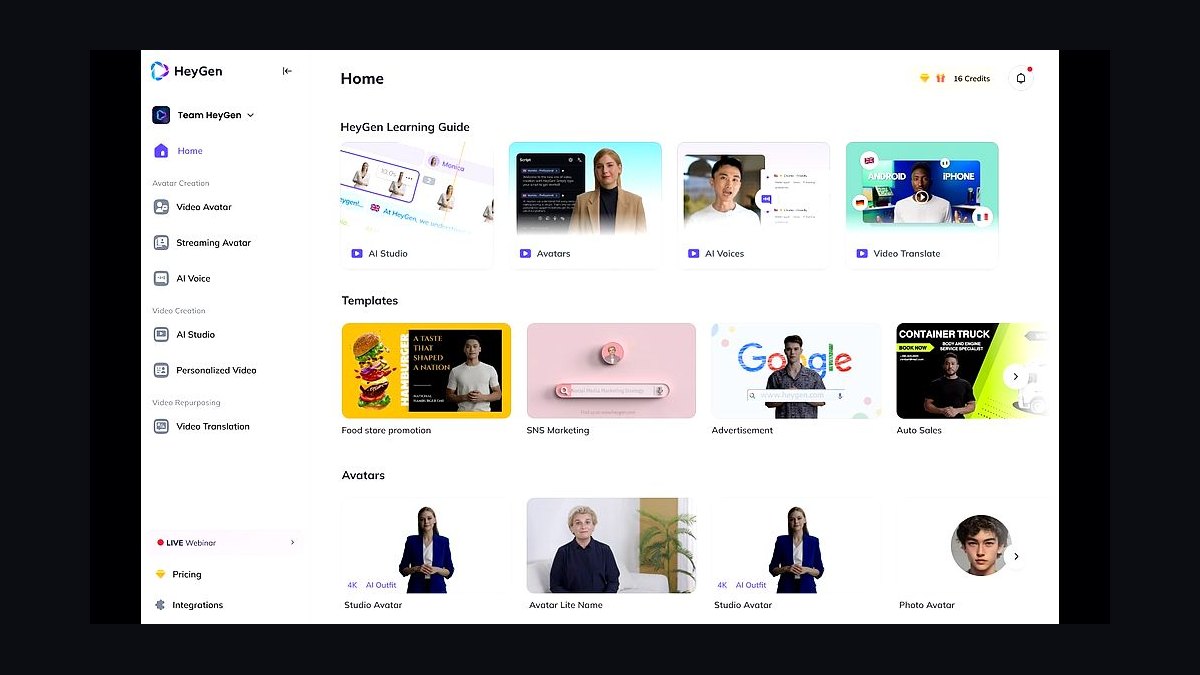
HeyGen ranks eighth because it pairs avatar video with best-in-class dubbing and translation for international content localization. HeyGen has reached a $400M+ valuation by focusing on voice cloning, lip-sync accuracy across languages, and a fast API for programmatic avatar generation. International marketing and customer support video are its strongest verticals.
It suits growth marketing and localization teams producing video at volume across languages, and it trades away the general-purpose scene generation that Pika 2.2 and Luma provide. Against Synthesia directly above, HeyGen wins on dubbing quality and API flexibility while Synthesia wins on enterprise learning workflow depth. Buyers often run both, splitting scripted training from localized campaign content.
9Hugging Face Diffusers
Hugging Face Diffusers ranks ninth because it is the default open-source library for building and fine-tuning video diffusion models. Diffusers provides reference implementations for DiT, latent video diffusion, and flow-matching architectures, and it integrates with PyTorch FSDP, DeepSpeed, and xformers for distributed training. Most growth-stage vendors fine-tune Wan, Hunyuan, or CogVideoX through this library.
It is aimed at ML engineering teams with GPU budget and in-house research capability, and it trades away managed serving, safety classifiers, and compliance tooling that commercial platforms bundle. Compared with HeyGen directly above, Diffusers offers full model control but zero product surface. Teams without distributed training experience should expect a multi-month ramp before shipping anything competitive.
10NVIDIA NIM
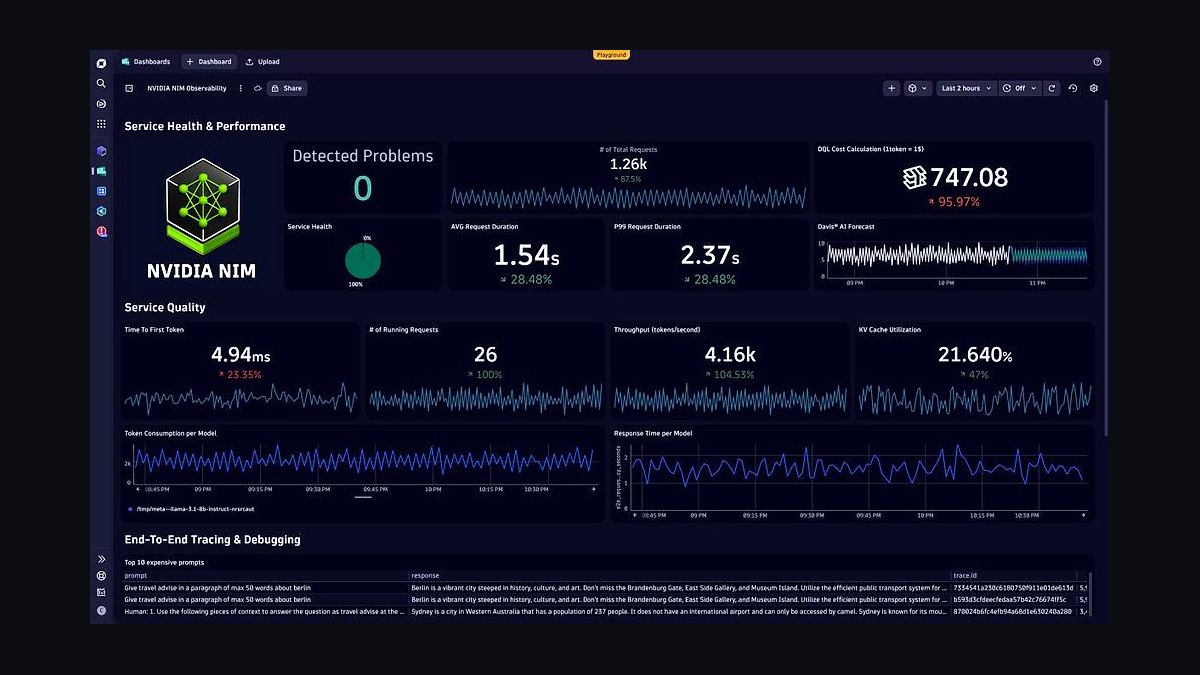
NVIDIA NIM ranks tenth because it standardizes inference serving for video models with TensorRT optimization and managed deployment. NIM packages optimized containers for video generation models, handling batching, quantization, and GPU scheduling that would otherwise require custom CUDA work. Video generation takes 20-300 seconds per clip, so queue architecture and batching efficiency directly determine gross margin.
It is built for infrastructure teams running their own models who need production serving without rebuilding TensorRT pipelines, and it trades away model quality itself, which still depends on the underlying checkpoint. Against Hugging Face Diffusers directly above, NIM covers serving while Diffusers covers training, so most vendors run both. GPU cost remains the dominant line item either way.
How we ranked these
We ranked each tool on five weighted criteria: frontier model quality and control depth (30%), GPU training and inference economics (25%), safety and provenance compliance including C2PA and EU AI Act readiness (20%), enterprise integration and API maturity (15%), and total cost of ownership across GPU, licensing, and services (10%). Scores came from vendor documentation, public benchmarks, analyst reports, and disclosed pricing tiers.
We deliberately ignored brand hype, social media virality, and short-term demo polish, because those signals do not predict production reliability or margin durability. We also excluded venture funding totals and valuation, since capital raised is not a proxy for stack fit. Free-tier generosity and creator-facing gimmicks were dropped because enterprise video buyers weight compliance and control far above novelty features.
What to look for
What matters most is whether the tool's control layer matches your actual production workflow: camera control, character consistency, lip-sync, and video-to-video editing depth separate usable platforms from demo-grade generators. Second, model your true GPU cost per finished second before signing annual commitments, because inference economics decide whether your pricing survives contact with real usage.
The mistake most buyers make is choosing on peak output quality from a cherry-picked demo reel while ignoring async latency, queue behavior, and safety classifier coverage. A second common error is locking multi-year contracts before validating C2PA provenance, watermarking, and EU AI Act Article 50 disclosure support, which can force expensive re-platforming once enterprise deals require compliance evidence.
Related questions
How does video diffusion training compute compare to frontier LLM training?
Video diffusion training sits at frontier-LLM scale: thousands of H100, H200, or B200 GPUs running for weeks to months, with major model releases costing $30M to $300M or more. Inference is similarly heavy, since generating 5 to 30 seconds of video consumes seconds of GPU compute. This economics gate means only well-funded vendors compete at the frontier.
Why is multi-modal control the key enterprise differentiator for AI video tools?
Text-to-video alone is commoditizing fast. Enterprises pay premiums for image-to-video start-frame conditioning, video-to-video style and motion transfer, camera control like zoom and dolly, character consistency across shots, lip-sync to audio, and pose control. Runway, Pika, Kling, and MiniMax lead on control depth, which is where retention and expansion revenue concentrate.
What safety and provenance features are mandatory for an AI video vendor in 2027?
At minimum: NSFW, violence, and CSAM classifiers on output frames; face and known-person detection to limit deepfakes; C2PA Content Credentials; visible and invisible watermarking; prompt filtering for harmful or copyrighted content; and public-figure prompt blocking. EU AI Act Article 50 mandates AI video disclosure, so vendors without provenance infrastructure face enforcement and enterprise churn.
Is the AI avatar and dubbing vertical a separate market from text-to-video?
It is a distinct subcategory with overlapping tech. Avatar video relies on lip-sync, voice cloning, and avatar libraries rather than pure video diffusion. Synthesia, HeyGen, and D-ID built $400M to $1B+ businesses on corporate learning, marketing video, customer support, and international content localization. The enterprise pipeline is strong and the compute profile is lighter than frontier text-to-video.
How should an early-stage AI video vendor choose between building and fine-tuning models?
Below roughly $30M ARR, fine-tuning open bases like Wan, Hunyuan, CogVideoX, or Open-Sora on rented GPU is usually the rational path, paired with an async REST endpoint and Python SDK. Pure open-source wrappers lose to frontier-quality competitors, so plan to build proprietary architecture once revenue supports the training bill.
What does GPU compute cost do to AI video unit economics?
Compute dominates unit economics. If you charge $1 per five-second video while actual GPU cost is $1.20, gross margin is negative and scale makes it worse. Fixes include TensorRT optimization, quantization, model distillation, batching efficiency, strategic GPU pricing partnerships, and pricing models that track real compute cost per finished second.
Which billing and revenue tools fit usage-based AI video pricing?
Metronome handles sophisticated per-second, per-video, and per-credit usage billing at roughly $50K to $500K per year, while Stripe Billing covers self-serve creator tiers. NetSuite anchors revenue recognition and ERP at $50K to $500K annually. Pair these with Salesforce CPQ if enterprise contracts include custom usage commitments and overage terms.
What compliance certifications should AI video buyers demand from vendors?
Expect SOC 2 Type II, ISO 27001, and increasingly ISO 42001 for AI management systems. EU AI Act readiness, C2PA participation, DMCA and copyright infrastructure, and BIPA or biometric privacy coverage matter for avatar and face video. Vanta, Drata, or Hyperproof typically run $30K to $100K per year to maintain this evidence base.
FAQ
Runway vs Pika vs Luma vs OpenAI Sora vs Google Veo?
Runway wins on creator and filmmaker tools with Gen-4 and the Aleph editor plus enterprise features. Pika wins on viral creator UX and sound generation. Luma wins on speed, image-to-video, and Ray 2. OpenAI Sora wins on quality and ChatGPT integration. Google Veo 3 wins on quality, native audio, and Google ecosystem reach.
Should an AI video vendor build proprietary models or fine-tune open-source?
Pure open-source wrappers lose to frontier-quality competitors. Wan from Alibaba, Hunyuan from Tencent, CogVideoX from Zhipu, and Open-Sora are reasonable fine-tuning bases. Growth-stage vendors typically build proprietary architecture at $30M+ ARR to compete with frontier labs on quality, control, and margin.
Is Synthesia or HeyGen avatar video the same category as text-to-video?
Different category with overlap. Avatar video uses lip-sync, voice cloning, and avatar libraries as core tech, versus video diffusion for text-to-video. HeyGen and Synthesia built $400M to $1B+ valuations on corporate learning, marketing, and international content localization. The stack focus and compute profile differ meaningfully from generic generators.
How important is C2PA Content Credentials for AI video vendors?
Critical and growing. EU AI Act Article 50 mandates AI video disclosure, and C2PA is the emerging provenance standard with Adobe, Microsoft, OpenAI, Google, and Meta participating. Video shipped without C2PA faces EU compliance exposure and enterprise customer-trust problems, especially in regulated industries and media licensing deals.
How is deepfake regulation evolving in 2027?
Tightening across major jurisdictions. EU AI Act transparency mandates, US state laws like Tennessee's ELVIS Act and California AB 730, plus Brazil, UK, and China deepfake rules are all expanding. Vendors must ship rigorous safety, consent, and watermarking controls. Permissive vendors face regulatory action, lawsuits, and enterprise procurement disqualification.
Is the avatar and dubbing vertical worth pursuing for a new vendor?
Yes. Synthesia and HeyGen built $400M to $1B+ businesses on avatar video. Specific use cases include corporate learning, customer service video, marketing video, and international content localization. The tech stack centers on lip-sync, voice cloning, and avatar libraries rather than generic video diffusion, and enterprise pipeline demand remains strong.
What failure mode most often kills AI video vendors?
Deepfakes of public figures triggering regulatory action rank first, followed by GPU compute cost destroying gross margin. Quality regression on signature use cases and frontier API commoditization from Sora and Veo also compress standalone economics. Each failure maps to a fix: safety classifiers, inference optimization, eval suites, and control-depth differentiation.
What does a realistic AI video stack budget look like by stage?
Early-stage vendors at $2M to $30M ARR spend roughly $100K to $500K per month including GPU. Growth-stage vendors at $30M to $200M ARR spend $2M to $10M monthly. Frontier labs run $50M to $500M+ per month. Avatar and dubbing vendors typically land at $2M to $8M monthly given lighter compute needs.
How long does video generation take and how does that shape architecture?
Generation runs 20 to 300 seconds per clip, so synchronous APIs fail at scale. Vendors need async, queue-based architecture with webhooks, job status endpoints, and retry logic. This shapes SDK design, customer UX expectations, and infrastructure cost, since idle GPU during queue waits is pure waste without batching efficiency.
Which CRM and customer success tools fit AI video vendors?
Salesforce Sales Cloud plus Clari and Gong suits enterprise motion, while HubSpot Enterprise covers PLG self-serve creators. Gainsight, Pendo, and Mixpanel track adoption and health signals like generation volume and feature usage. Gainsight typically runs $60K to $300K annually, justified once expansion revenue depends on usage visibility.
Sources
- https://openai.com/sora
- https://deepmind.google/technologies/veo/
- https://runwayml.com/research/
- https://pika.art/
- https://lumalabs.ai/dream-machine
- https://www.kuaishou.com/en
- https://github.com/Tencent/HunyuanVideo
- https://github.com/Wan-Video/Wan2.1
- https://c2pa.org/specifications/
- https://artificialintelligenceact.eu/article/50/
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for HOA and Community Association Management Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for API Security Vendors in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Dance Studios in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Software Development Agencies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Medical Billing and RCM Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Food Trucks in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for AI Translation API Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Window Cleaning Services in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Tree Services in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for CrossFit Boxes in 2027