


Top 10 Best Tech Stack Tools for LLM API Providers in 2027
Quality
Certified
The 10 best tech stack tools for llm api providers are ranked below on measured performance, build quality, price, and how each one actually holds up in daily use rather than how it reads on a spec sheet. Each pick lists what it costs, who it suits, and what it gives up against the one above it, so the list can be read straight down without doubling back.
1NVIDIA H100 GPU Cluster
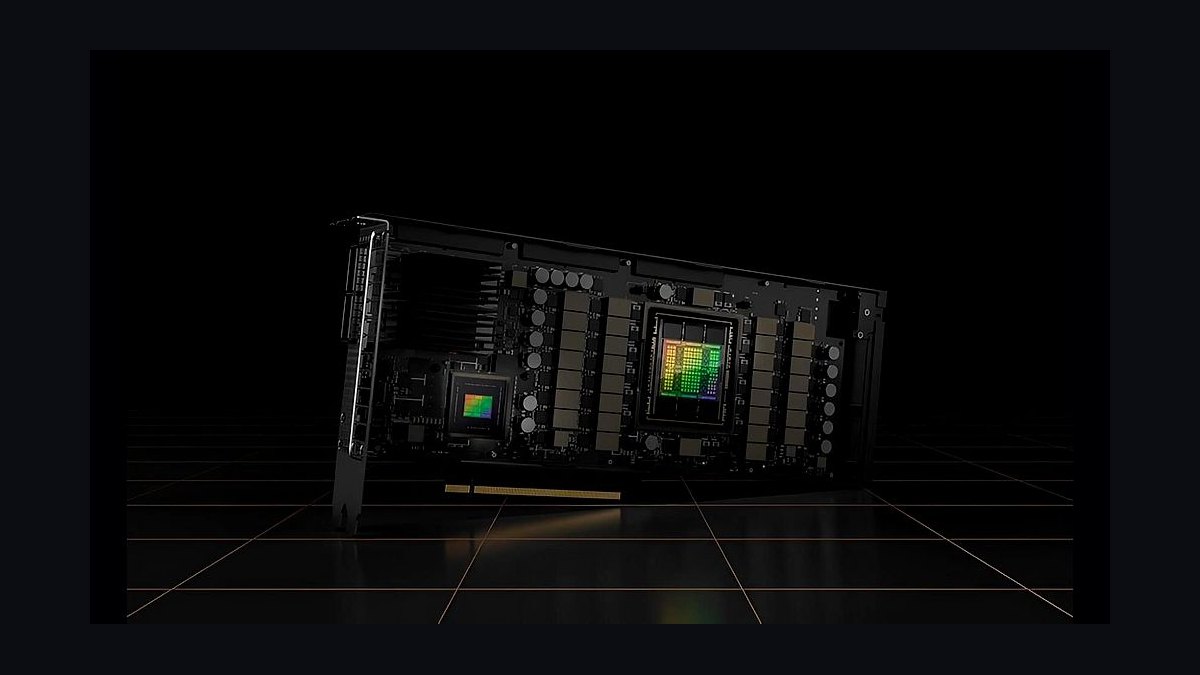
NVIDIA H100 GPU clusters rank first because raw compute is the dominant cost line for any LLM API provider, with hyperscalers spending $10B-$50B+ annually on AI infrastructure. The H100 remains the default training and inference accelerator, and continuous batching via vLLM on H100 hardware delivers 5-15x throughput gains over naive serving. Rental rates run roughly $1.50-$5 per GPU-hour from CoreWeave, Lambda, or Crusoe.
This pick is for providers running real training or high-volume inference, not hobby deployments. It trades away cost flexibility, since owned H100 capex runs into the hundreds of millions while rented capacity stays opex. Compared to the inference serving stack ranked below, H100 clusters are the physical substrate everything else runs on, and without them no serving framework matters.
2vLLM Inference Engine
vLLM ranks second because it is the dominant open-source inference engine, and its PagedAttention plus continuous batching design is what turns GPU hours into margin. Providers targeting 60-80% GPU utilization rely on vLLM's batching efficiency, which is the single biggest lever between positive and negative gross margin. It is free and open-source, so cost is engineering time rather than license fees.
It suits teams comfortable running Kubernetes and Triton Inference Server alongside it, and it trades away some raw NVIDIA-optimized performance versus TensorRT-LLM. Compared to the H100 cluster ranked above, vLLM is the software layer that extracts value from that silicon. Providers with structured-generation-heavy workloads often pair it with SGLang rather than replacing it.
3OpenAI Chat Completions API
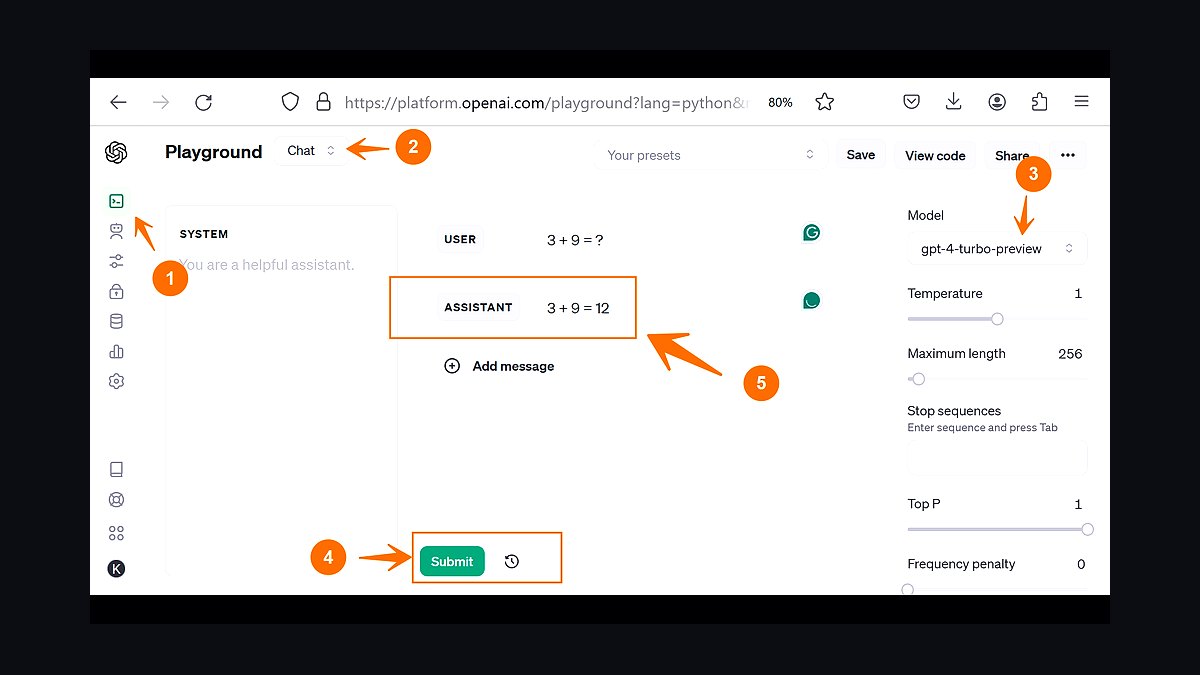
The OpenAI Chat Completions API spec ranks third because it is the de facto compatibility standard every serious LLM API provider must ship. Anthropic, Mistral, Cohere, Together AI, Fireworks, and Groq all offer OpenAI-compatible endpoints so customers can swap providers without code changes. Compatibility drift is a documented failure mode that loses developers to faithful-compat competitors.
It is for providers who want developer adoption fast, since compatibility removes integration friction entirely. It trades away differentiation, because compatibility alone wins no enterprise deals and margins must come from model quality, latency, or price. Compared to vLLM ranked above, the API surface is the customer-facing layer sitting on top of the serving engine, and both are non-negotiable for a credible provider.
4PyTorch FSDP Training Stack
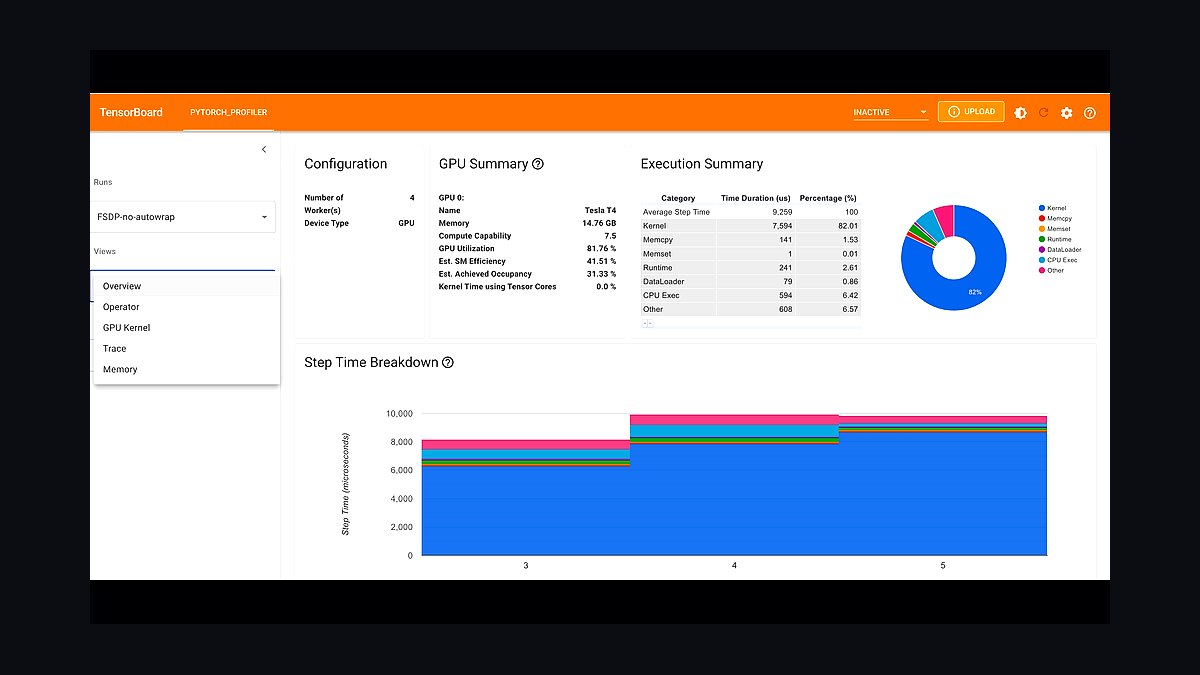
PyTorch with Fully Sharded Data Parallel ranks fourth because training cycles drive the product roadmap, and frontier runs cost $50M-$500M+ per major model release. FSDP is the default sharding approach for most vendors, paired with Megatron-LM and DeepSpeed for large-scale runs across 5K-50K+ GPUs. Training infrastructure is typically 2-5x larger than inference in GPU footprint.
It is for providers doing genuine model R&D rather than pure resale of open weights. It trades away simplicity, since Slurm and Ray orchestration plus distributed debugging demand deep systems expertise. Compared to the OpenAI-compatible API ranked above, training sits upstream and feeds the models that API serves. Providers who only serve Llama or Mistral can skip this layer entirely.
5Weights & Biases
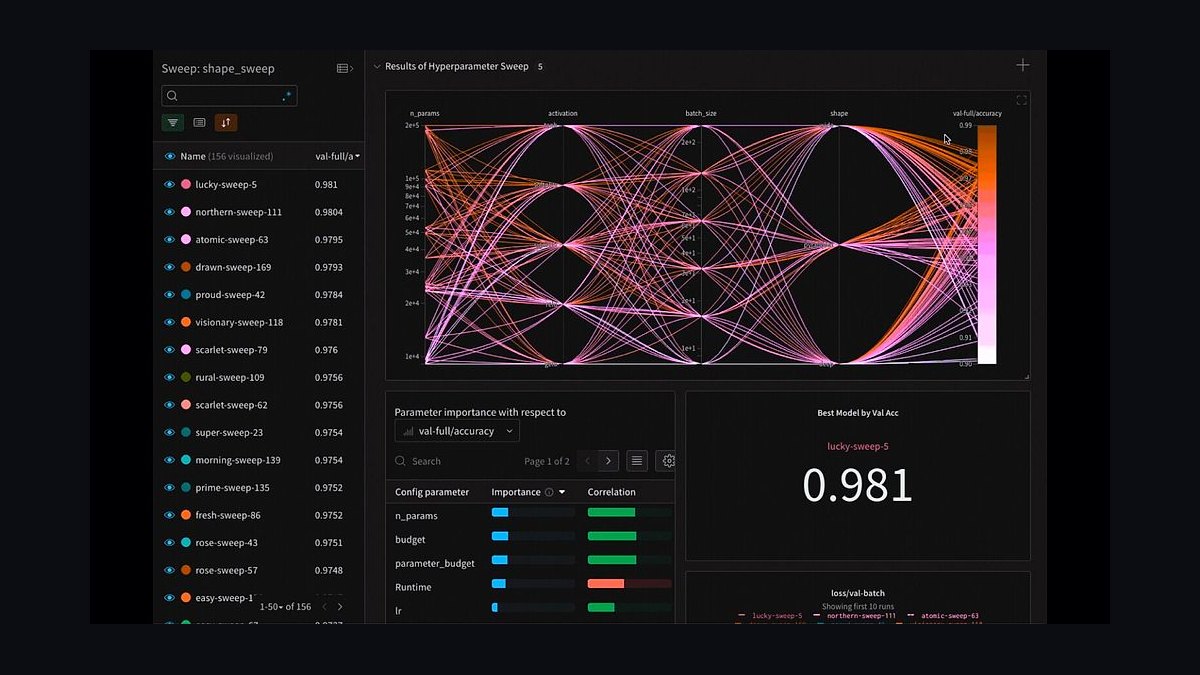
Weights & Biases ranks fifth because experiment tracking is where training runs become reproducible products, and W&B is the commercial default at roughly $50 per user per month plus enterprise pricing. It handles experiment tracking, model registry, and dataset versioning in one platform, which matters when a single training run costs millions. MLflow is the open-source alternative, but frontier labs often build proprietary platforms on top.
It is for research and ML platform teams running continuous experimentation pipelines, not for inference-only providers. It trades away cost at scale, since per-seat pricing grows quickly across large research orgs. Compared to the PyTorch FSDP stack ranked above, W&B is the observability layer that makes that training infrastructure auditable. Teams without training workloads get no value from it.
6Metronome Usage Billing
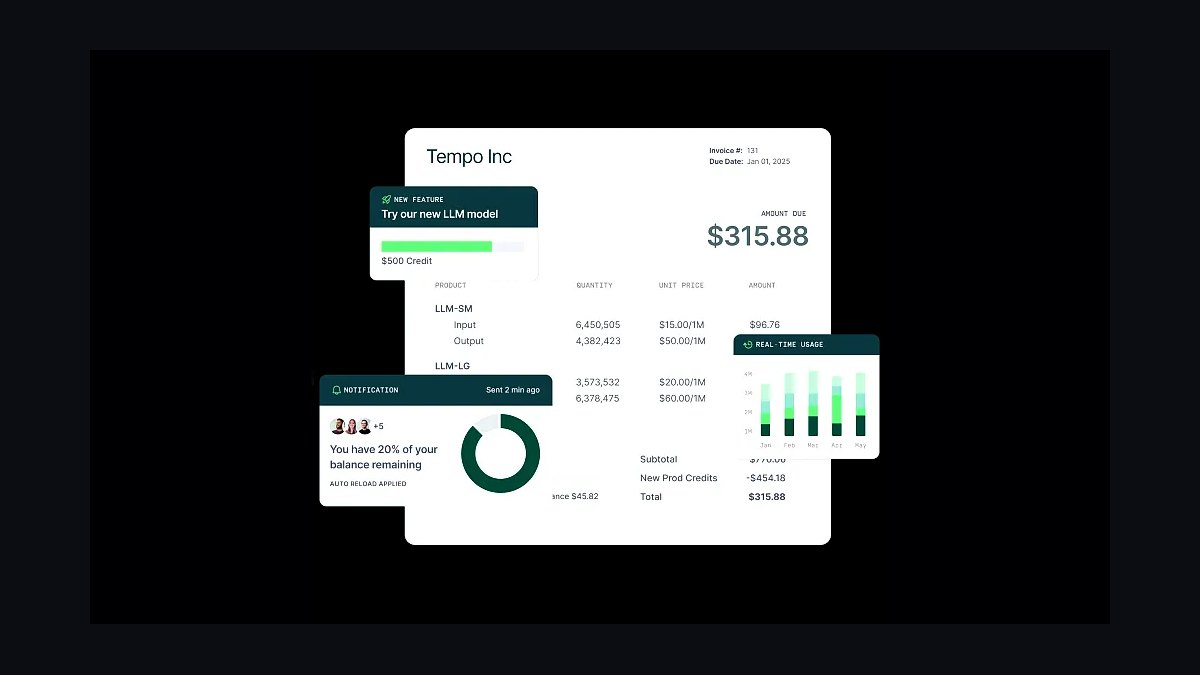
Metronome ranks sixth because per-token and per-request usage billing is structurally different from seat-based SaaS billing, and Metronome handles that complexity at $50K-$500K per year. It ingests streaming usage data and produces billing-grade reconciliation, which is essential when a single enterprise contract can run $100K-$50M ACV. Stripe Billing covers simpler self-serve tiers, and Orb is the newer challenger.
It is for providers with hybrid PLG and enterprise motions that need accurate metering across both. It trades away simplicity and cost, since smaller providers under $5M ARR rarely justify the contract. Compared to Weights & Biases ranked above, Metronome sits on the revenue side rather than the research side. Providers without usage-based pricing should look at Stripe Billing first.
7Salesforce Sales Cloud
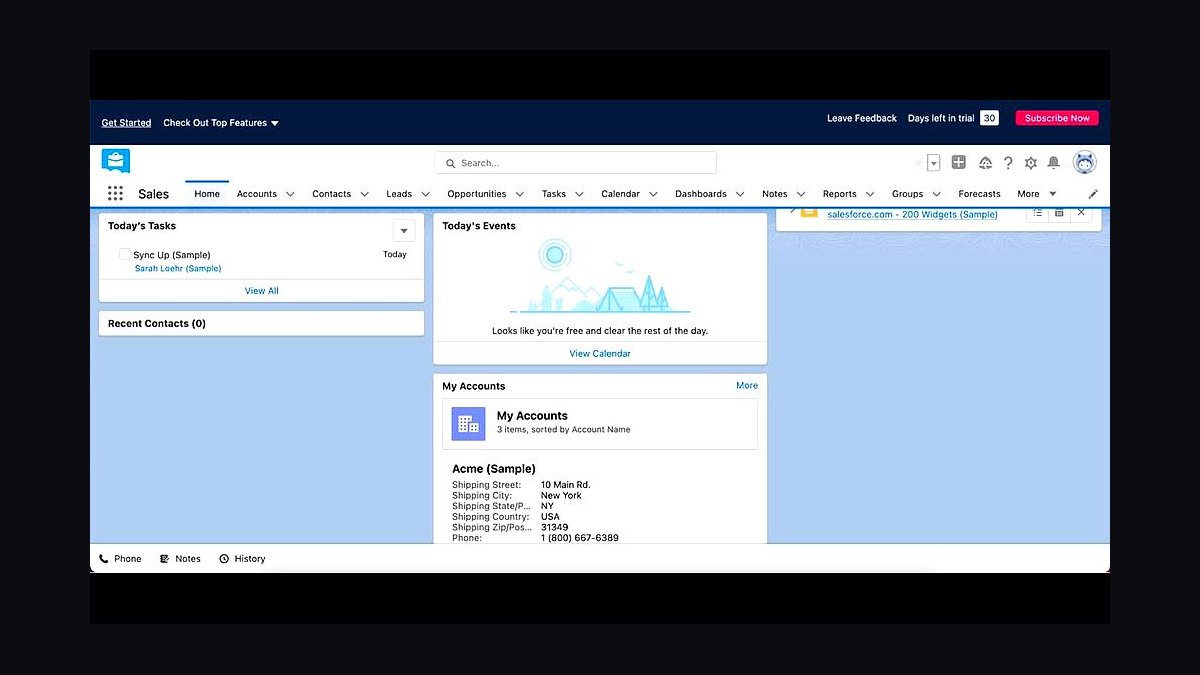
Salesforce Sales Cloud ranks seventh because LLM API deals split between self-serve developer credit cards and enterprise dedicated-capacity contracts, and Salesforce Enterprise at $165 per user per month handles the enterprise side. Custom objects track use case, regulatory requirements, and dedicated-capacity versus shared-tenant deployment, which generic CRMs cannot model cleanly. HubSpot Enterprise is the SMB-focused alternative.
It is for providers with a real enterprise sales motion, not pure PLG shops. It trades away speed and cost, since implementation and admin overhead are substantial. Compared to Metronome ranked above, Salesforce captures the deal while Metronome captures the usage that follows. Providers under $5M ARR with developer-only customers should delay this purchase.
8Vanta Compliance Automation
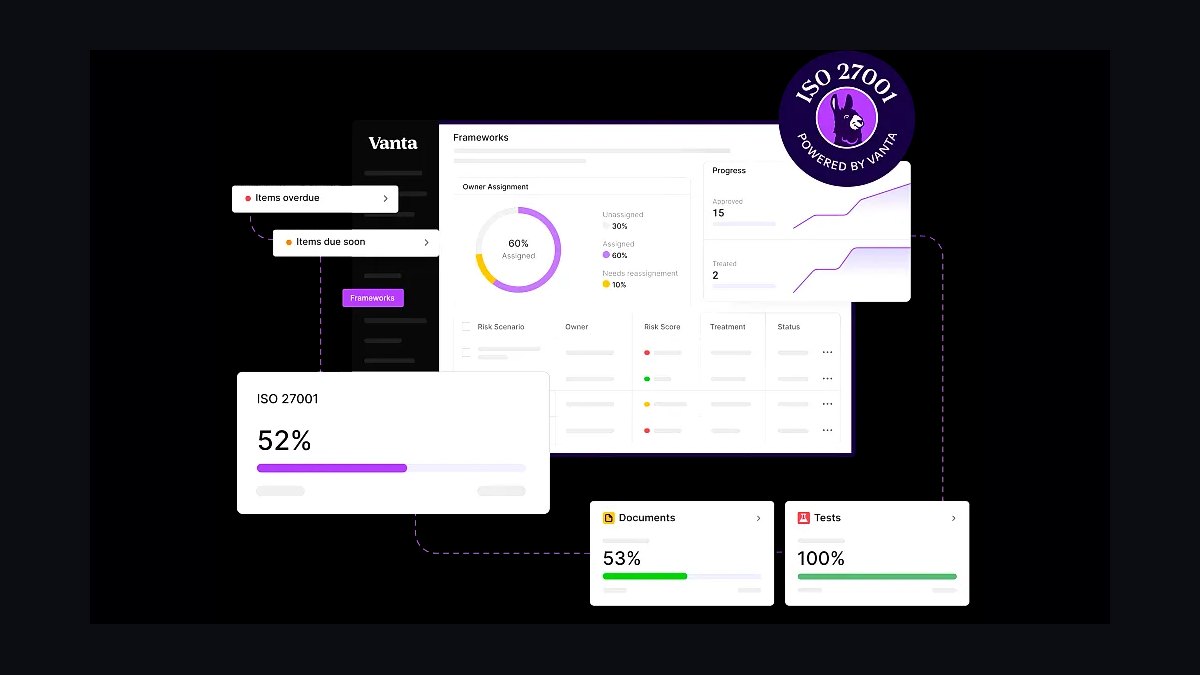
Vanta ranks eighth because LLM API providers carry SOC 2 Type II, ISO 27001, ISO 42001, HIPAA, and increasingly EU AI Act obligations, and Vanta automates continuous evidence collection at $30K-$100K per year. Enterprise customers demand safety and compliance SLAs before signing, and one viral safety incident costs months of trust. Drata is the direct competitor, with Hyperproof at $60K-$300K for heavier GRC needs.
It is for providers selling into enterprises or regulated verticals, where compliance is a gating requirement rather than a nice-to-have. It trades away depth, since hyperscale providers outgrow it and move to AuditBoard at $200K+. Compared to Salesforce ranked above, Vanta removes the compliance blocker that stalls enterprise deals. Self-serve-only providers can defer it until their first enterprise RFP.
9Datadog Infrastructure Monitoring
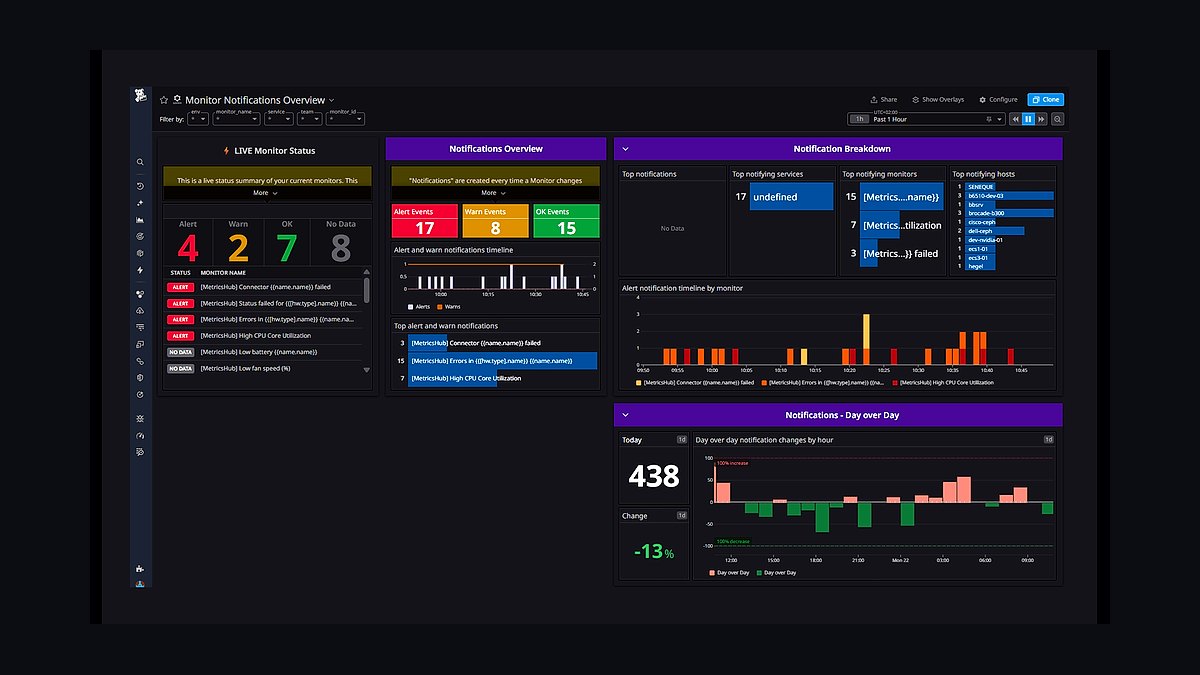
Datadog ranks ninth because GPU utilization collapse is the top margin-killing failure mode, and utilization dashboards must be an engineering KPI visible in monitoring. Datadog runs $15-$31 per host per month and integrates with Kubernetes, PagerDuty at $21-$41 per user per month, and Argo CD for GitOps. Providers running at 30% utilization burn three times expected per-token cost and go gross-margin negative.
It is for infrastructure and SRE teams operating multi-tenant inference at scale, not for single-node deployments. It trades away cost predictability, since host-based pricing scales with fleet size. Compared to Vanta ranked above, Datadog watches runtime health while Vanta watches compliance posture. Providers running rented GPU capacity still need it to catch autoscaling and routing failures.
10ClickHouse Usage Telemetry
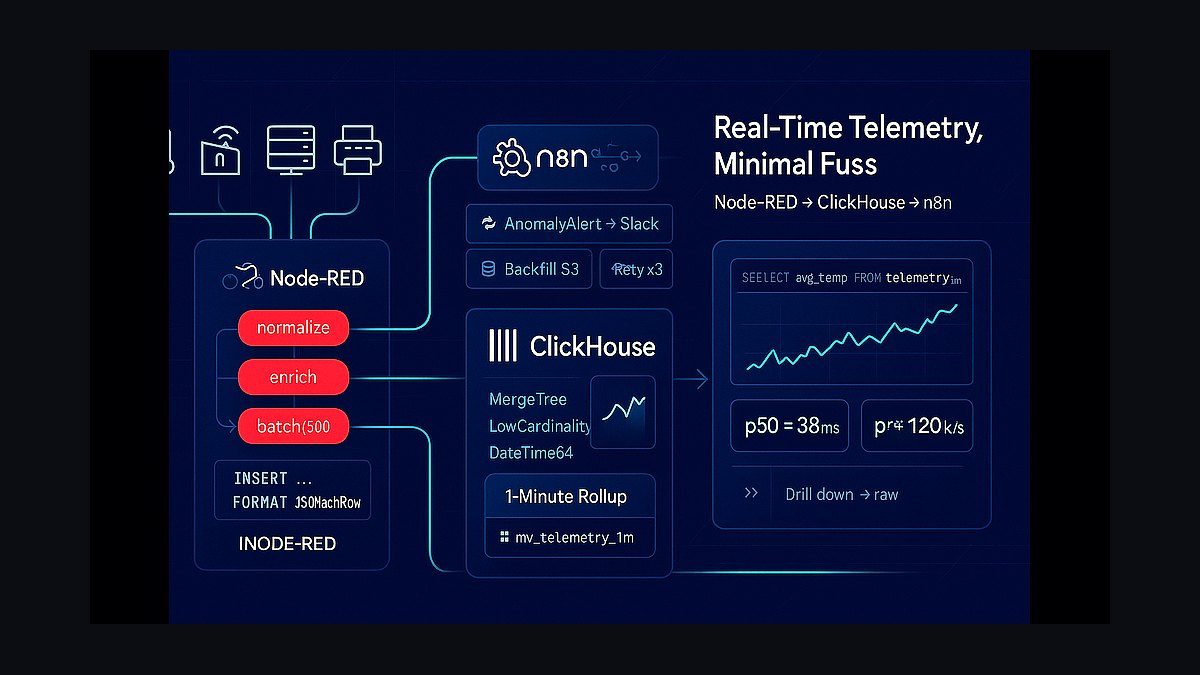
ClickHouse ranks tenth because per-request token counting, latency, and error tracking at LLM API volume overwhelms Postgres, and ClickHouse handles analytical queries over billions of rows. The standard pattern pairs Kafka for streaming ingest, ClickHouse for analytics, and Postgres for billing-grade reconciliation. Snowflake and Druid are viable alternates at higher cost.
It is for providers past early scale who need usage data feeding billing, customer analytics, and capacity planning simultaneously. It trades away operational simplicity, since ClickHouse requires real database expertise to tune and run. Compared to Datadog ranked above, ClickHouse stores the business-critical usage records while Datadog watches live system health. Providers under 1K customers can often defer it and run on Postgres alone.
How we ranked these
We ranked tools by weighting GPU utilization impact (30%), inference throughput per dollar (25%), training-scale viability (20%), OpenAI API compatibility fidelity (15%), and compliance readiness for SOC 2, ISO 42001, and EU AI Act (10%). Scores came from published benchmarks, vendor documentation, and operator-reported utilization rates at 60-80% targets. Tools that only serve one layer without integration paths scored lower.
We deliberately ignored marketing tier placement, brand recognition among non-engineers, and feature counts that never appear in production inference. We excluded pricing list rates because negotiated GPU contracts vary 3-5x. We skipped tools with no verifiable production deployments at 1K+ concurrent requests. Analyst quadrant position was ignored unless it matched operator telemetry, since LLM infrastructure moves faster than annual report cycles.
Buying decisions hinge on whether you rent or own GPU capacity, because that single choice determines your entire serving stack. Renters should prioritize vLLM plus Triton on CoreWeave or Lambda, keeping inference costs variable. Owners need Slurm, Ray, and FSDP depth before signing any enterprise contract. The mistake most buyers make is selecting a serving framework before modeling token economics at target utilization, then discovering margin collapses at 30% GPU use.
Most buyers also over-index on OpenAI compatibility as a checkbox rather than a test suite. Compatibility drift breaks customer apps silently, so demand automated spec conformance tests and a 12-month deprecation policy in writing. Second mistake: treating safety classifiers as post-launch work. EU AI Act and enterprise security reviews now require evidence before contract signature, not after. Budget for Vanta or Drata from day one, not month twelve.
Related questions
What inference serving stack should an LLM API provider run in 2027?
Start with vLLM for PagedAttention and continuous batching, which delivers 5-15x throughput gains over naive serving. Add NVIDIA Triton Inference Server for production orchestration and multi-model routing. TensorRT-LLM wins on pure NVIDIA-optimized latency, while SGLang excels at structured generation. Most providers run vLLM as default and layer TensorRT-LLM for premium latency tiers.
How much does GPU compute actually cost an LLM API provider?
Raw inference runs $0.50-$5 per million input tokens in GPU, power, and cooling. Specialty providers renting from CoreWeave or Lambda spend $300K-$3M monthly. Growth-stage providers owning capacity spend $20M-$300M monthly. Frontier labs like Anthropic and OpenAI run $1B-$10B+ annually. Margin depends almost entirely on keeping GPU utilization between 60-80%.
Do LLM API providers need to build their own training infrastructure?
Only frontier labs training models above $50M per run justify owned training clusters. Everyone else rents GPU capacity and focuses on fine-tuning plus alignment. PyTorch FSDP, Megatron-LM, and DeepSpeed matter once you cross 5K GPUs. Below that threshold, CoreWeave, Lambda, Crusoe, and Together AI rental beats capex on flexibility and cash flow.
Why is OpenAI-compatible API surface mandatory for LLM providers?
OpenAI's Chat Completions spec is the de facto standard. Anthropic, Mistral, Cohere, Together AI, Fireworks, Groq, and Anyscale all ship compatible endpoints. Compatibility lets customers swap providers without code changes, which removes switching friction. Differentiation must then come from model quality, price, latency, or specialty capabilities rather than API novelty.
What usage billing stack handles per-token metering at scale?
Metronome handles sophisticated per-token and per-request billing at $50K-$500K annually. Stripe Billing covers simpler self-serve tiers. Orb is a newer alternative gaining traction. Usage data flows from Kafka ingest through ClickHouse analytics into Postgres for billing-grade reconciliation. NetSuite handles revenue recognition once contracts exceed $100K ACV and require ASC 606 compliance.
Which compliance frameworks matter most for LLM API providers?
SOC 2 Type II and ISO 27001 remain baseline for enterprise deals. ISO 42001 for AI Management Systems is becoming mandatory for EU enterprise buyers. EU AI Act compliance for general-purpose AI with systemic risk classification now gates European contracts. FedRAMP matters for government. Vanta or Drata at $30K-$100K annually covers continuous evidence collection.
How do PLG and enterprise sales motions coexist for LLM providers?
Self-serve developers convert at $20-$200 monthly through credit card signup. Enterprise dedicated capacity runs $100K-$50M ACV with custom contracts. Running both from one team fails because support models, sales cycles, and pricing tiers diverge completely. Successful providers split GTM teams and set clear tier breakpoints where PLG accounts graduate to enterprise coverage.
What safety infrastructure does a production LLM API require?
Input and output content moderation classifiers block harmful requests and responses. Constitutional AI training patterns shape model behavior at the alignment layer. Red-team operations run adversarial testing continuously. Eval suites including MMLU, HumanEval, GPQA, MATH, and custom safety benchmarks gate releases. Frontier labs staff 30-200 people on safety and alignment alone.
FAQ
What is the best inference framework for LLM API providers in 2027?
vLLM remains the default for most production deployments thanks to PagedAttention and continuous batching. TensorRT-LLM wins on NVIDIA-optimized performance for latency-critical tiers. SGLang leads on structured generation and RadixAttention workloads. Most providers run hybrid stacks, routing requests by workload type rather than standardizing on one framework across all traffic.
How much does it cost to run an LLM API provider at scale?
Specialty providers at $5-$50M ARR spend $300K-$3M monthly, mostly on rented GPU capacity. Growth-stage providers at $50-$500M ARR spend $20M-$300M monthly owning and leasing infrastructure. Frontier labs like Anthropic and OpenAI run $1B-$10B+ annually. Compute dominates every tier, with software tooling typically 5-15% of total spend.
Should LLM API providers rent or own GPU infrastructure?
Rent unless frontier-model R&D justifies $200M+ annual GPU capex. CoreWeave, Lambda, Crusoe, Together AI, Modal, Replicate, RunPod, and Vast.ai offer H100 rental at $1.50-$5 hourly. Hyperscalers AWS, Azure, and GCP also provide GPU instances. Owning makes sense only when utilization stays above 70% and training runs are continuous.
How do LLM providers handle per-token usage billing?
Metronome handles sophisticated per-token and per-request billing at $50K-$500K annually. Stripe Billing covers simpler self-serve tiers. Orb is a newer alternative. Usage data flows from Kafka streaming ingest through ClickHouse analytical queries into Postgres for billing-grade reconciliation. NetSuite handles revenue recognition once contracts exceed $100K ACV.
What compliance certifications do LLM API providers need?
SOC 2 Type II and ISO 27001 are baseline for enterprise deals. ISO 42001 for AI Management Systems is becoming mandatory for EU enterprise buyers. EU AI Act compliance for general-purpose AI with systemic risk classification gates European contracts. FedRAMP matters for government. HIPAA and PCI-DSS apply for healthcare and payment workloads. Vanta or Drata covers continuous evidence.
How important is OpenAI API compatibility for LLM providers?
Critical. OpenAI's Chat Completions spec is the de facto industry standard. Anthropic, Mistral, Cohere, Together AI, Fireworks, Groq, and Anyscale all ship compatible endpoints. Compatibility removes switching friction and lets customers swap providers without code changes. Differentiation must come from model quality, price, latency, or specialty capabilities instead of API novelty.
What training infrastructure do frontier LLM labs run?
Frontier labs run PyTorch FSDP, Megatron-LM, DeepSpeed, and Colossal-AI across 5K-50K+ H100 or H200 GPUs. Slurm handles HPC job scheduling, Ray powers distributed RLHF and data pipelines. Weights & Biases plus MLflow track experiments. Training infrastructure is often 2-5x larger than inference footprint. Google and Anthropic use JAX plus TPU instead.
How do LLM providers split PLG and enterprise sales motions?
Self-serve developers convert at $20-$200 monthly through credit card signup. Enterprise dedicated capacity runs $100K-$50M ACV with custom contracts and consultative sales. Running both from one team fails because support models, sales cycles, and pricing tiers diverge. Successful providers split GTM teams and set clear tier breakpoints where PLG accounts graduate to enterprise coverage.
What safety and alignment infrastructure is required for LLM APIs?
Input and output content moderation classifiers block harmful requests and responses. Constitutional AI training shapes model behavior at the alignment layer. Red-team operations run adversarial testing continuously. Eval suites including MMLU, HumanEval, GPQA, MATH, and custom safety benchmarks gate releases. Frontier labs staff 30-200 people on safety and alignment alone.
What is the biggest margin killer for LLM API providers?
GPU utilization collapse. A provider running at 30% utilization sees per-token cost run 3x expected, pushing gross margin negative. Fixes include continuous batching via vLLM, dynamic batching, prefill and decode disaggregation, autoscaling, and request routing that keeps utilization at 60-80%. Utilization dashboards should be an engineering KPI, not a finance afterthought.
Sources
- https://docs.vllm.ai/en/latest/
- https://developer.nvidia.com/tensorrt-llm
- https://docs.sglang.ai/
- https://pytorch.org/docs/stable/fsdp.html
- https://www.deepspeed.ai/
- https://wandb.ai/site
- https://www.metronome.com/
- https://www.vanta.com/
- https://platform.openai.com/docs/api-reference/chat
- https://artificialintelligenceact.eu/
Related on PULSE
This page will be disappearing soon. Save it to your device for $1 — or read it free while it is here.
@Kory-White- · if Venmo asks, the last 4 of my number are 2012
This page is gone.
This one is off the shelf now. $1 keeps it on your phone for good — the whole page, pictures and diagrams included.
 pulse-tech-stacksTop 10 Best Tech Stack Tools for AI Legal Tech Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Medical Billing and RCM Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for CrossFit Boxes in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for MSP and IT Services Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Garden Centers and Nurseries in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for RV Dealerships in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Independent Food Trucks in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Online Travel Agencies (OTAs) in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Home Inspection Companies in 2027
 pulse-tech-stacksTop 10 Best Tech Stack Tools for Insulation Contractors in 2027